Llama 4 didn't dethrone Qwen3 or DeepSeek — but its MoE design and huge context make it worth understanding. What Scout and Maverick actually are, the memory trap that catches everyone, and what you really need to run it.
Let me save you the first disappointment so we can get to the interesting part: Llama 4 did not land as the local-AI king everyone expected. On the coding and reasoning benchmarks that the community actually cares about, the released Scout model underwhelmed against Qwen3 and DeepSeek, and Meta took real heat when it turned out the version topping the LMArena leaderboard was a chat-tuned variant that wasn't the same as the weights you could download. So no, I'm not going to tell you Llama 4 is the best model you can run at home — it usually isn't. What I will tell you is why it's still genuinely worth understanding: its mixture-of-experts design and enormous context window make it one of the most interesting models to run on the unified-memory hardware that's reshaping local AI. That's the real story, and it's the one nobody sells you.
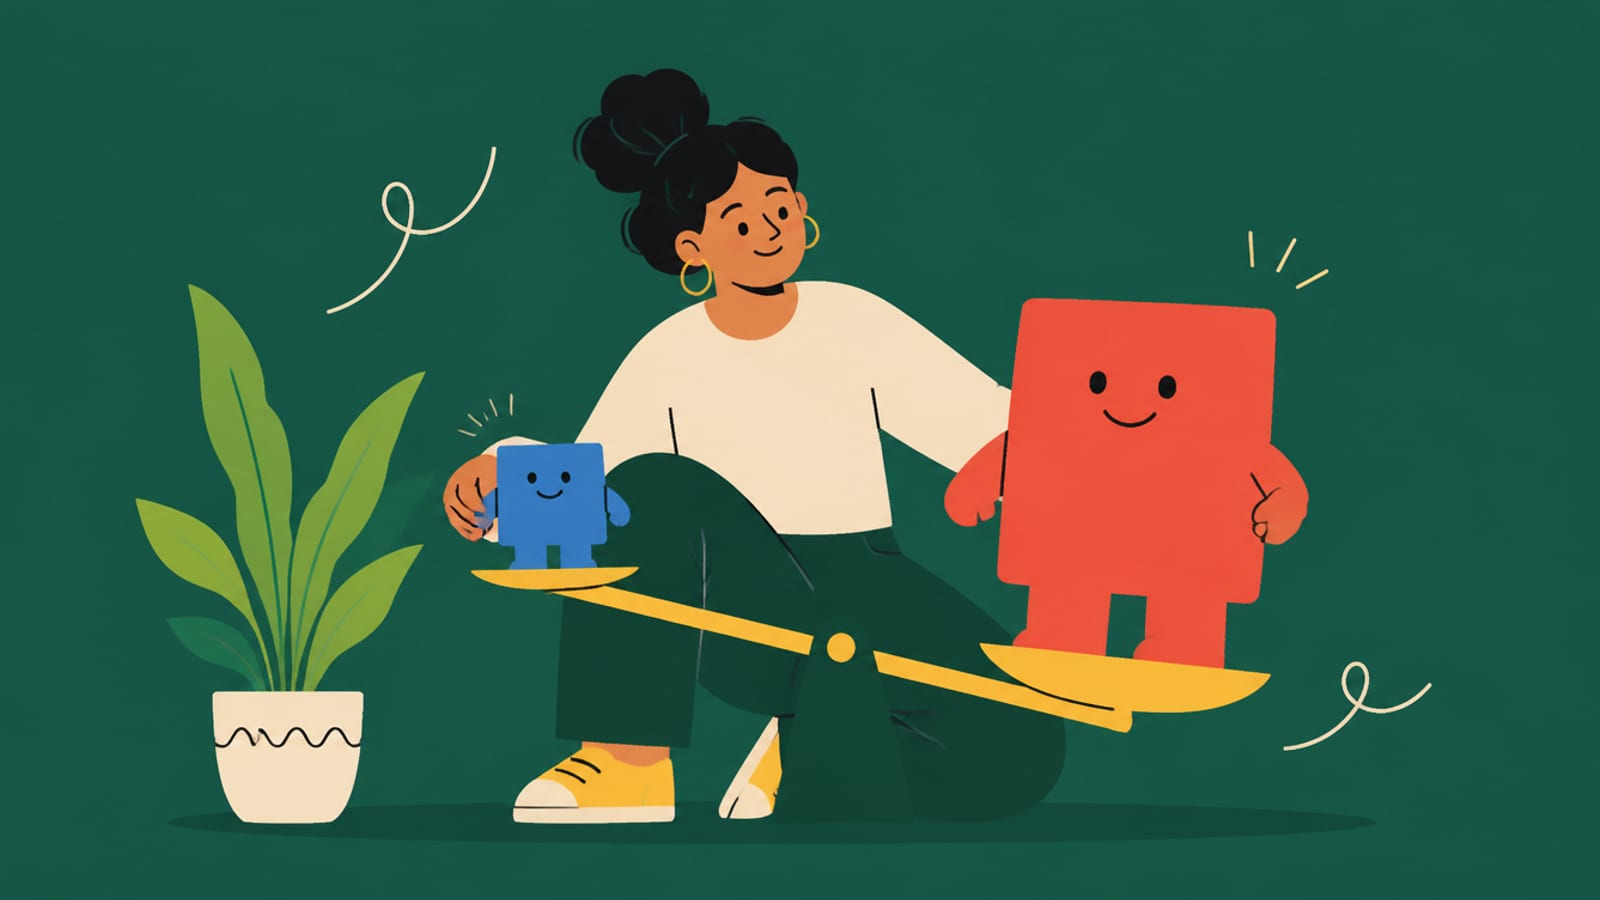
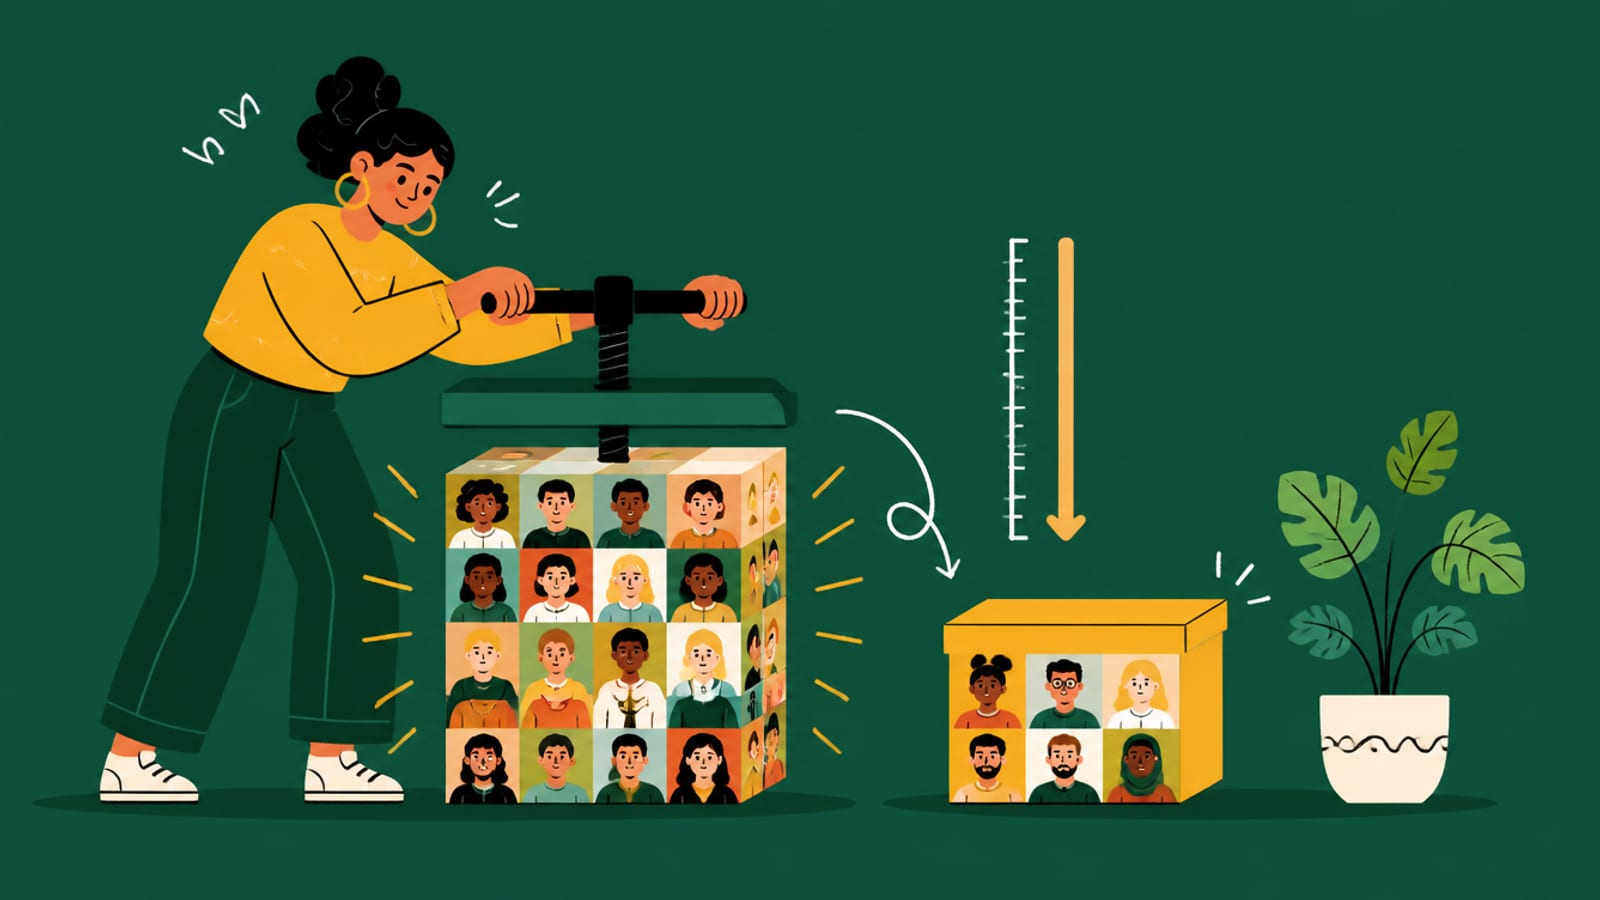
Llama 4 is a mixture-of-experts model — the whole herd has to fit in memory even though only part runs per token. Illustration by Aliteq. · Illustration by Aliteq / generated with Higgsfield
What Llama 4 actually is
Llama 4 is Meta's first natively multimodal, mixture-of-experts (MoE) family. Instead of one dense network where every parameter fires on every token, an MoE model has many "expert" sub-networks and a router that activates only a few per token. Scout has 16 experts and activates 17B of its 109B parameters per token; Maverick has 128 experts and activates 17B of its 400B. The payoff is that inference is as cheap as a 17B model even though the model "knows" far more — you get big-model breadth at small-model compute cost, per token.
Llama 4 Scout vs Maverick (per Meta's model card)
Total parameters
Scout
109B
Maverick
400B
Active per token
Scout
17B
Maverick
17B
Experts
Scout
16
Maverick
128
Context window
Scout
Up to 10M tokens
Maverick
Up to 1M tokens
Multimodal
Scout
Text + image in
Maverick
Text + image in
Local reality
Scout
Runnable at home (quantized)
Maverick
Data-center / heavy multi-GPU
Scout
Maverick
Total parameters
109B
400B
Active per token
17B
17B
Experts
16
128
Context window
Up to 10M tokens
Up to 1M tokens
Multimodal
Text + image in
Text + image in
Local reality
Runnable at home (quantized)
Data-center / heavy multi-GPU
For running at home, Scout is the one that matters — Maverick's 400B total puts it firmly in data-center or serious multi-GPU territory. So the rest of this cluster focuses on Scout, with Maverick as the reference point for "when you'd step up."
What you actually need to run Scout
Here's the honest memory ladder for Llama 4 Scout, from "serious workstation" down to "I just want to poke at it." Full-precision is a non-starter at home (~218GB); quantization is the whole game.
Llama 4 Scout memory footprint by quantization (109B total)
FP16 (unquantized)~218 GB
data-center only
Q8 (8-bit)~109 GB
multi-GPU or 128GB unified memory
Q4_K_M (~4-bit)~62 GB
a 64–80GB card or 96–128GB unified memory
~1.78-bit dynamic~33 GB
fits a 32GB card; or 24GB w/ CPU offload, ~20 tok/s
Two honest notes on that chart. First, MoE loads everything, so even the quality-usable Q4_K_M quant is ~62GB — which means no single consumer GPU holds a good Scout quant; you need a 64GB+ card, a big unified-memory machine, or you drop to an aggressive low-bit quant. That's why unified memory keeps coming up. Second, remember to leave headroom for the KV cache, which grows with context — Llama 4's long context is the whole point, but at 128k tokens the cache alone can want ~24GB on top of the weights.
Scout is runnable at home — but plan memory around its full 109B (quantized), not the 17B active figure. · Illustration by Aliteq / generated with Higgsfield
The map: pick your path
Which hardware to buy for Scout — the honest GPU and memory picks, from a single big card to unified memory: best GPU for Llama 4 Scout.
Scout, yes — but only at aggressive low-bit quantization on a single consumer card, because MoE loads all 109B. A quality Q4_K_M quant is ~62GB (needs a 64GB+ card or unified memory); a ~1.78-bit dynamic quant (~33GB) fits a 32GB card, or a 24GB card with CPU expert-offload at ~20 tok/s. Maverick (400B) isn't a realistic home model.
Is Llama 4 better than Qwen3 or DeepSeek?
Honestly, usually not for local coding and reasoning — those models generally outperform Scout at similar effort, and Meta drew criticism for an LMArena-tuned variant that flattered Llama 4's ranking. Llama 4's genuine advantages are its very long context window and native multimodal input, not raw benchmark wins.
Why does a 17B-active model need so much memory?
Because it's mixture-of-experts: only 17B parameters compute per token, but the router can call any expert at any step, so all 109B (Scout) must be loaded in memory. Compute is cheap per token; memory is not. This is the #1 thing people get wrong.
What's the best hardware for it?
For Scout specifically, a large-unified-memory machine (Strix Halo, Mac Studio) or a single high-VRAM card is the sweet spot, because it can hold the whole MoE. See the hardware spoke for exact picks.
Llama 4 is one model in a fast-moving field. For the broader hardware picture — which GPU actually matters for any local model — start with my colleague's VRAM-first best-GPU guide.