aliteq.
Tensor

Local AI & Automation Editor · since 2019

Tensor

I'm US-based, I run more models at home than I'll admit to, and I've quantized more than I've finished reading about. I write about running AI on your own hardware and, lately, about what it costs a company to do the same — tokens per day, GPUs per month, and the GDPR questions nobody's sales deck answers.

local large language modelsself-hosted LLMsAI acceleratorsGPU inferencemodel quantizationLLM cost and TCOAI automation for businessGDPR and AI

Latest by Tensor

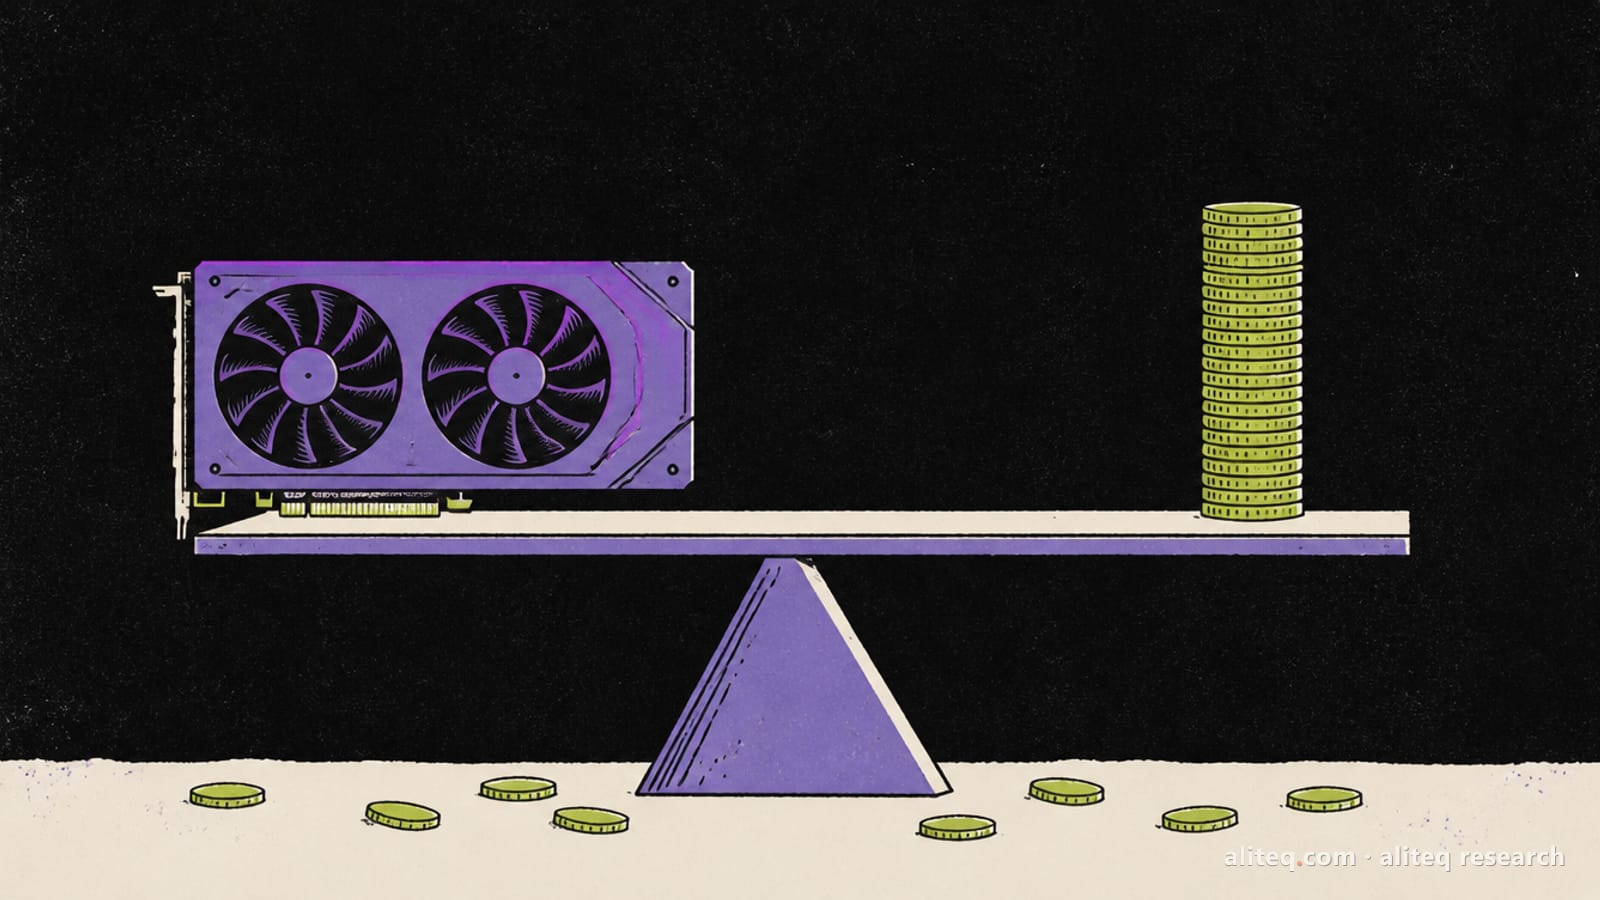
Hand-drawn editorial illustration of a level seesaw balancing a graphics card on one end against a tall stack of lime-green coins on the other
AI Automation

Self-Hosted LLM vs API Break-Even: Tokens per Day by Model (Live GPU Prices)

Renting a GPU for an open model looks cheaper than paying per token until you price the same model on the cheapest API. We did it for four open models, from Llama 3.1 8B to Llama 3.3 70B, with live GPU rates from our own tracker and list prices read on 2 October 2026. Against the same model's API, one rented GPU almost never wins. Against a frontier model, it wins from about 2 to 6 million tokens a day.

Tensor · 4d ago · 12 min