The GitHub request to keep MoE experts in RAM is still open after 15 months. But since Ollama 0.30, llama.cpp's own fit step can park them there for you, as long as you leave num_gpu alone. Plus what Ollama's Qwen3.8 Flash Next tags need, and why Reddit can tell when you're running Ollama.
Some links on this page are referral links: we may earn a commission, at no cost to you.
Share
You read about --n-cpu-moe, the llama.cpp flag that parks a mixture-of-experts model's bulky expert weights in system RAM. Then you went looking for the same switch in Ollama. It isn't there. Not in the Modelfile docs, not in the API options, not in the environment variables. What Ollama does instead, since version 0.30, is let llama.cpp's own fit step park the experts in RAM for you, as long as you leave num_gpu unset.
That part of the story is true. The rest of it changed in May 2026, and most of the advice floating around hasn't caught up. This guide is built from Ollama's and llama.cpp's source, read on October 4, 2026 and re-checked on 1 November, and it quotes the exact lines it leans on.
Can Ollama keep MoE experts on the CPU?
Not on request. Ollama has no option that says "put the experts of the first N layers in RAM". The feature request is still open, and Ollama's documented knobs don't include it. What Ollama does have, since version 0.30, is llama.cpp underneath, and llama.cpp's automatic placement already knows what an expert is.
Here are the options Ollama accepts when it loads a model, read in its api/types.go: num_ctx, num_batch, num_gpu, main_gpu, use_mmap, num_thread and draft_num_predict. That's the whole list. None of them mentions experts. The same list feeds Modelfile PARAMETER lines, so there's no hidden Modelfile key either.
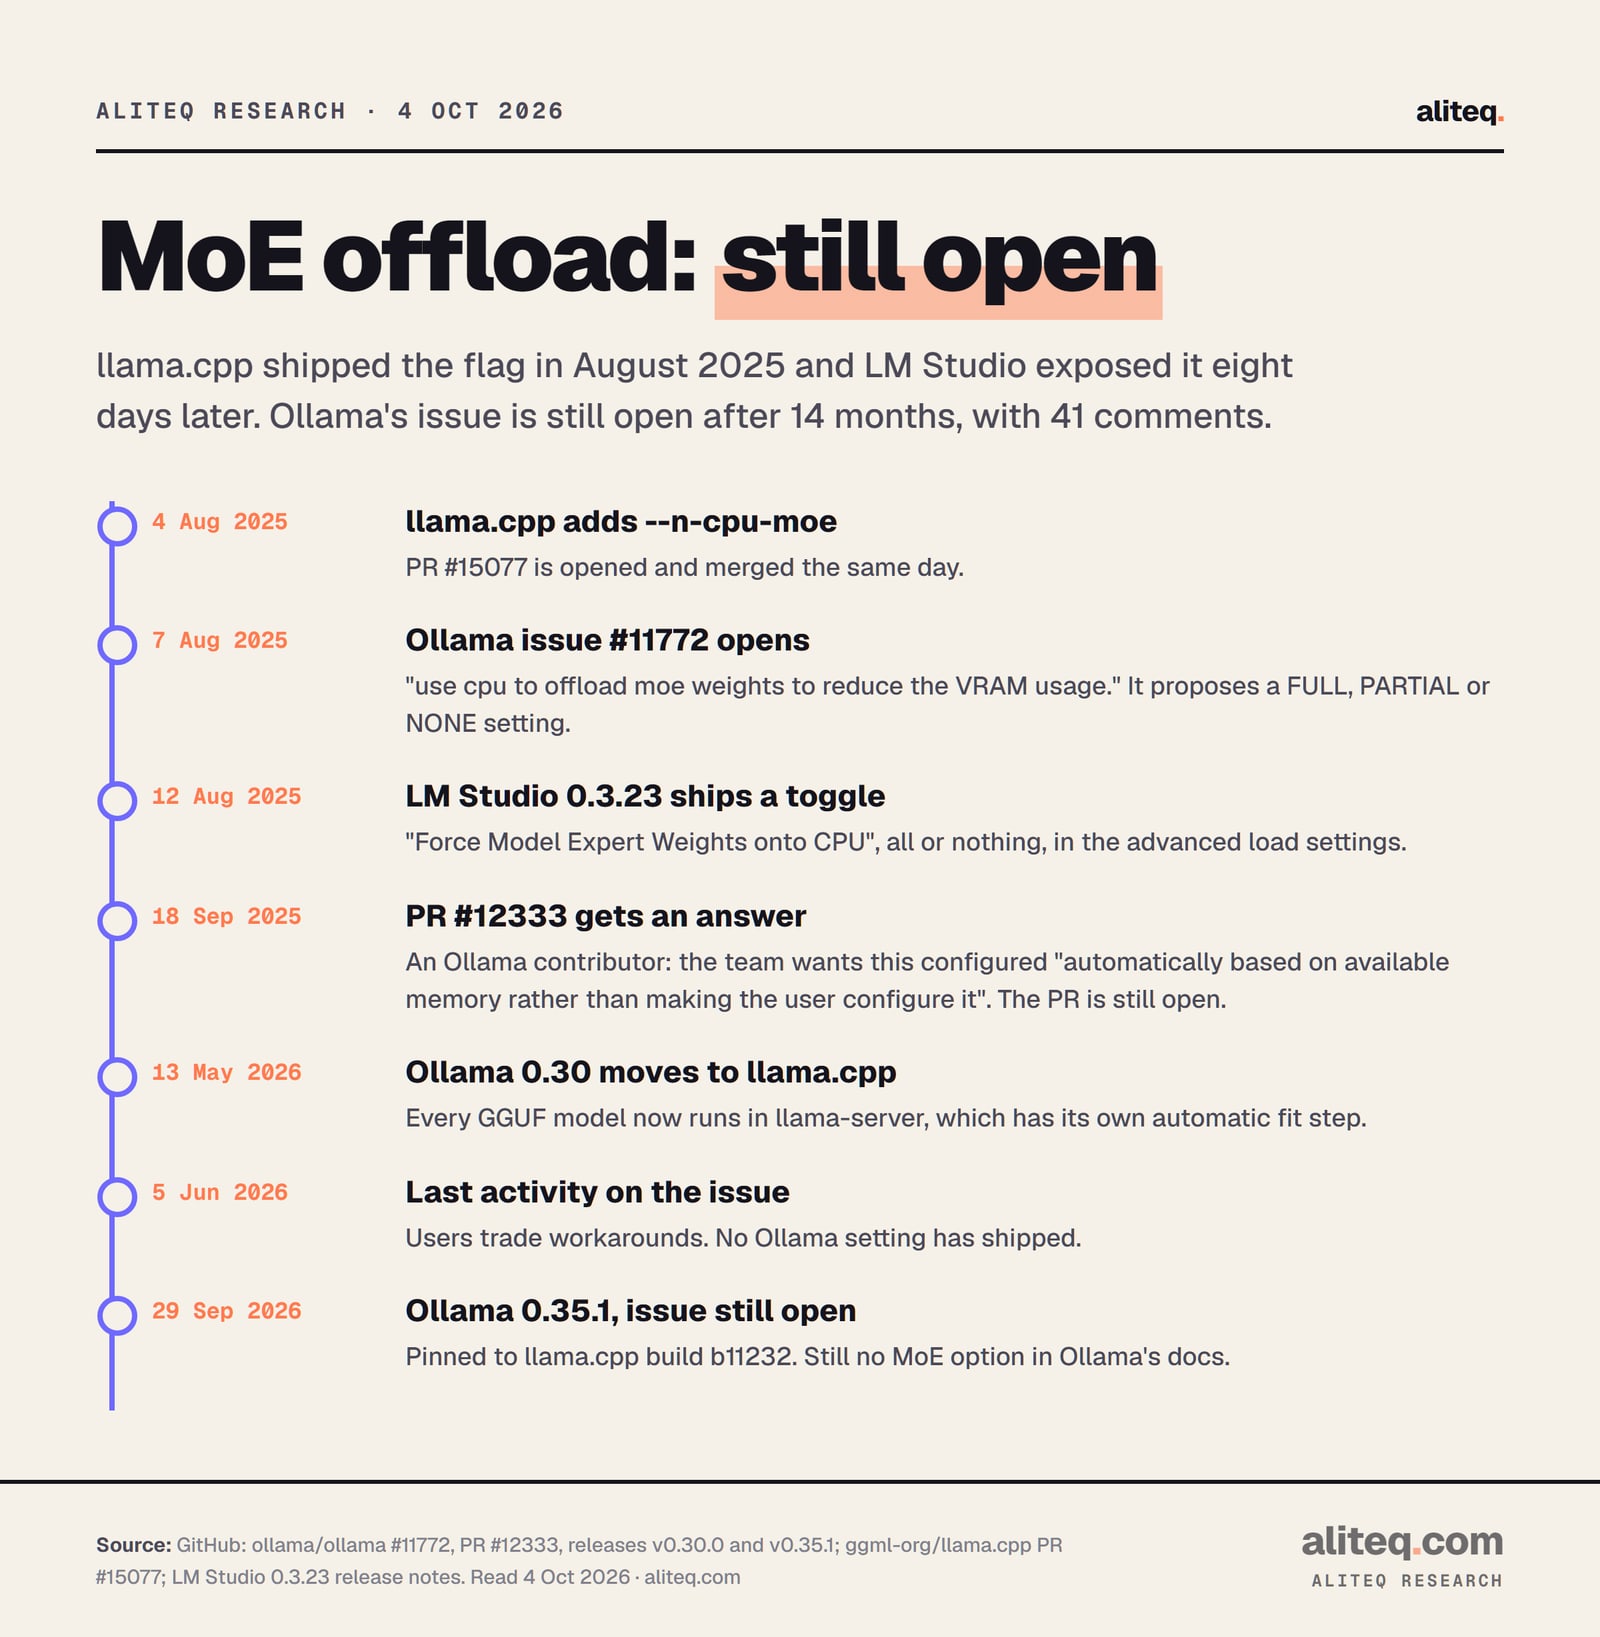
Compare that with the two other tools most people run. llama.cpp has had --n-cpu-moe since August 4, 2025 (PR #15077). LM Studio added a "Force Model Expert Weights onto CPU" toggle in version 0.3.23, eight days later. If you want the mechanics of the flag itself, our explainer on what --n-cpu-moe actually does covers it.
Where the GitHub request stands
Issue #11772 is open, labeled "feature request", with about 43 comments on November 1, 2026. It was opened on August 7, 2025, and its latest comment was posted on October 25, 2026. No setting has shipped. The one clear statement of intent from the Ollama side came on a related pull request in September 2025.
The issue's title is "use cpu to offload moe weights to reduce the VRAM usage." Its first post proposed a strategy setting with three values: FULL, PARTIAL and NONE. Most of the comments are votes, user benchmarks and patches.
A contributor did write a pull request, #12333, "feat: add support for MoE offloading", opened September 18, 2025. It is still open. The reply it got the same day, from Ollama contributor jessegross, explains why:
"Thank you but we want to be able to configure this automatically based on available memory rather than making the user configure it, similar to how the rest of Ollama works."
jessegross on ollama/ollama PR #12333, Sep 18, 2025
The same reply said they were "generally" not adding new features to the old llama engine. Keep that sentence in mind. Ollama later replaced that engine, and the replacement does configure this automatically.
Dates from GitHub and the LM Studio release notes, read Oct 4, 2026. · aliteq research
What Ollama does with an MoE model today
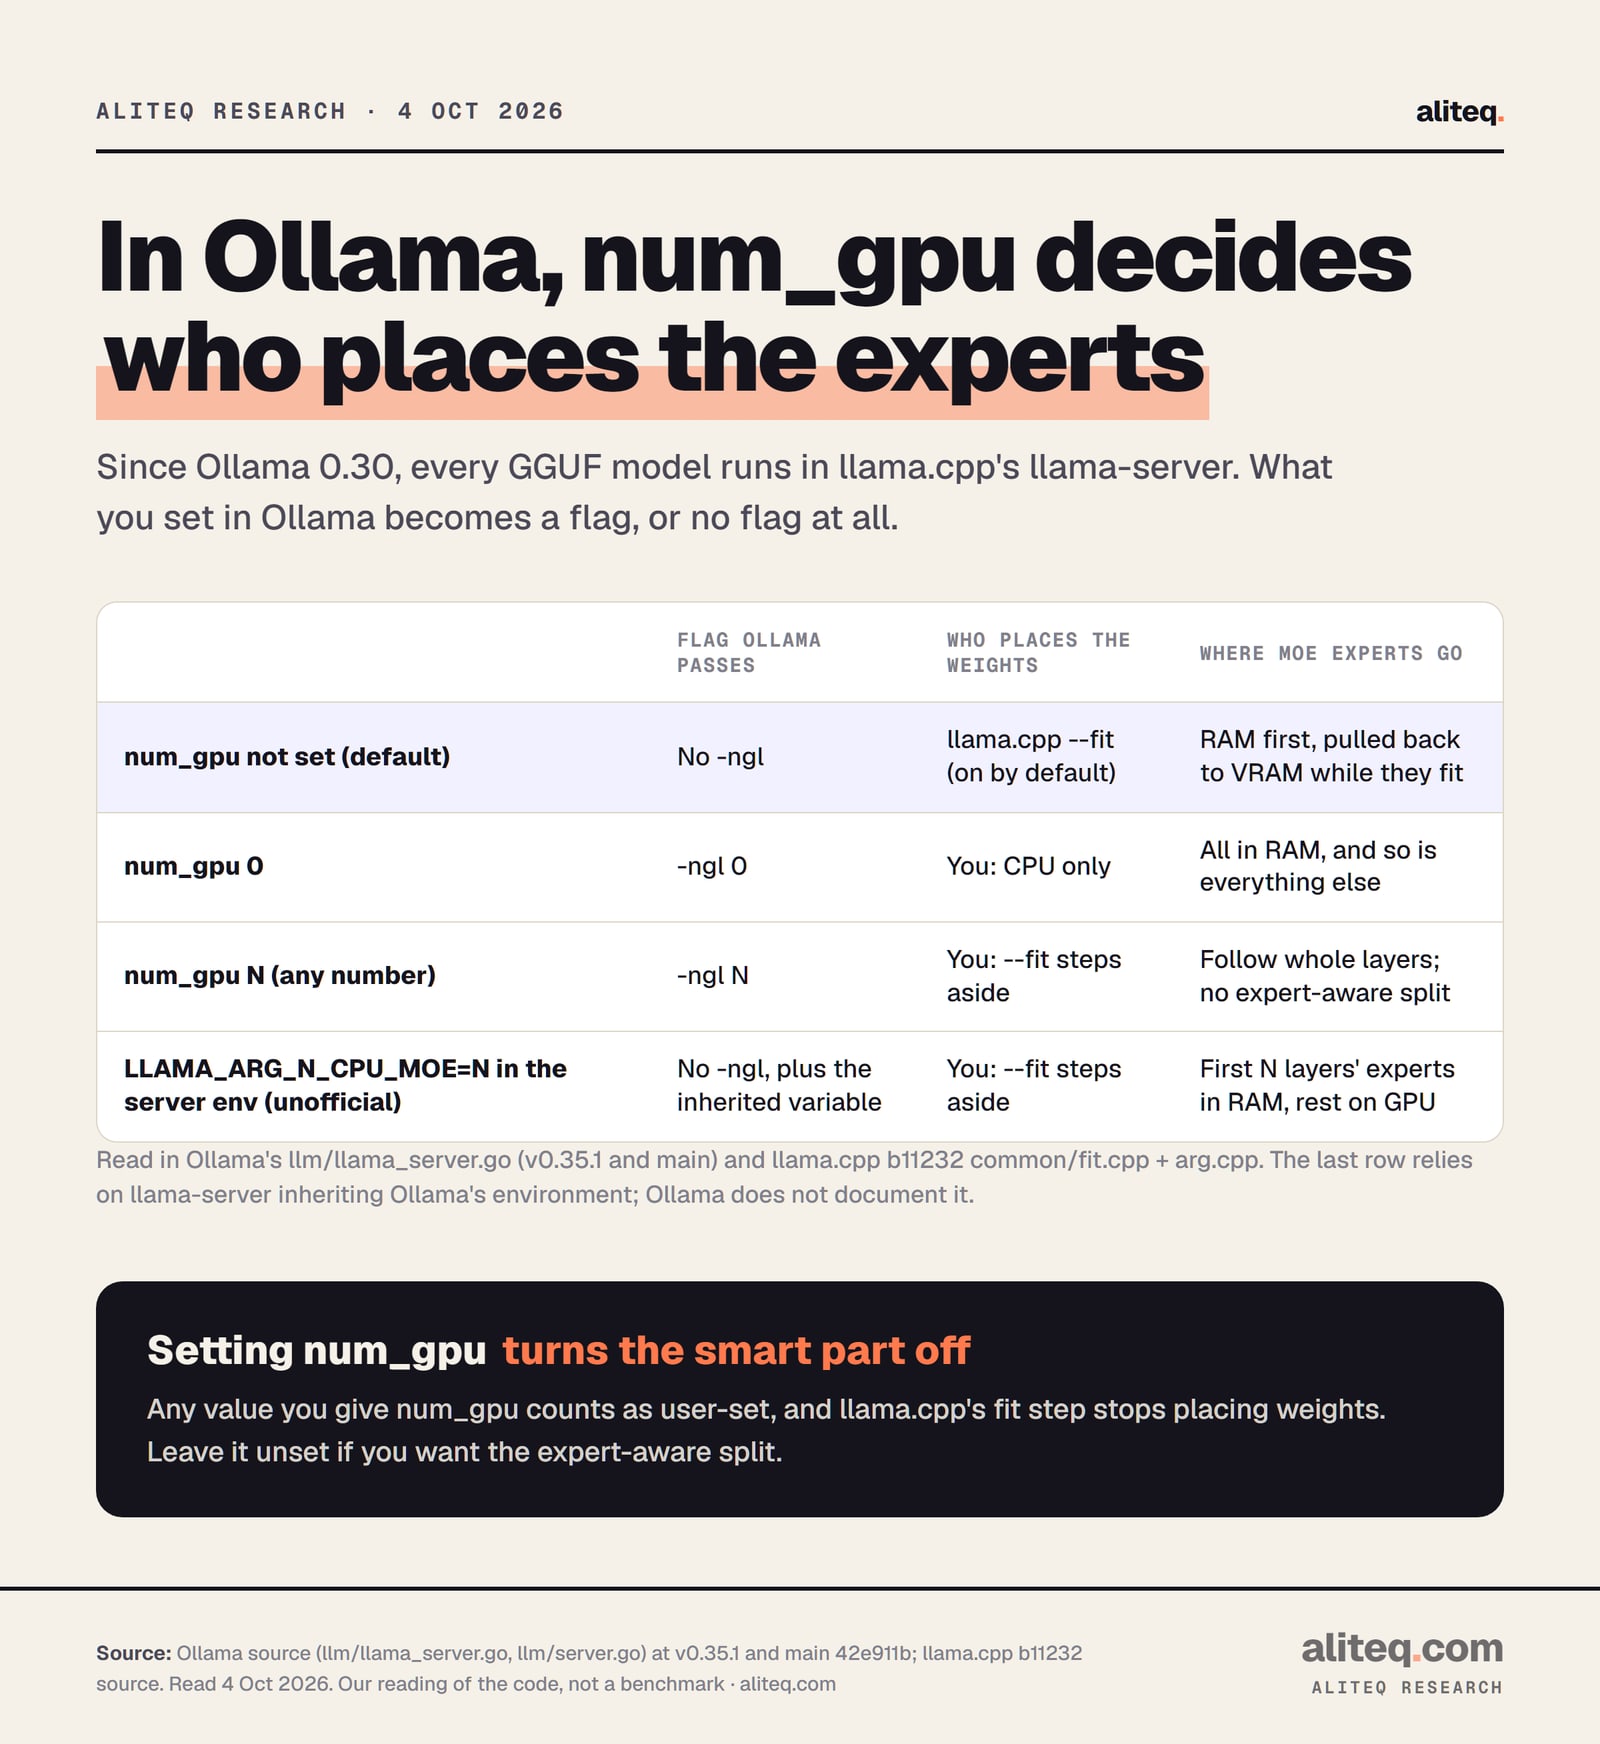
Since 0.30, Ollama starts llama.cpp's llama-server for every GGUF model and passes it a short list of flags. Whether it passes a GPU layer count depends only on num_gpu. With num_gpu unset, it passes none, and llama.cpp's fit step, which is on by default, decides where every tensor goes.
The 0.30 release note (May 13, 2026) put it simply: "Ollama 0.30 is now available, with improved compatibility and performance using llama.cpp." The source is blunter. A comment in llm/server.go reads: "All GGUF models are served via the upstream llama-server subprocess."
Then llm/llama_server.go translates num_gpu into a llama.cpp flag. On main (1 November) the comment still reads "NumGPU == -1 (default): don't pass -ngl, let llama-server auto-detect". This is the table that matters:
What Ollama's num_gpu becomes in llama-server (Ollama v0.35.1, read Oct 4, 2026)
num_gpu not set (default)
Flag Ollama passes
None ("let llama-server auto-detect")
Who places the weights
llama.cpp's fit step, on by default
num_gpu 0
Flag Ollama passes
-ngl 0
Who places the weights
You: CPU only
num_gpu N (any positive number)
Flag Ollama passes
-ngl N
Who places the weights
You: N whole layers in VRAM
Flag Ollama passes
Who places the weights
num_gpu not set (default)
None ("let llama-server auto-detect")
llama.cpp's fit step, on by default
num_gpu 0
-ngl 0
You: CPU only
num_gpu N (any positive number)
-ngl N
You: N whole layers in VRAM
Now the llama.cpp side, read in common/fit.cpp at build b11232, the build Ollama 0.35.1 pins. The fit step only touches settings you didn't set. For an MoE model that doesn't fit, it first measures memory "with all MoE tensors moved to system memory". It fills the GPU with the small, always-used parts. Then it moves expert weights back onto the GPU, front to back, until the card is full.
That is --n-cpu-moe, chosen for you. It's also roughly what the September 2025 reply asked for: placement "based on available memory rather than making the user configure it". Whether Ollama's team sees it that way isn't on record. The issue is still open, and nobody on it says so.
One Ollama detail matters here. Ollama always passes the context size (-c) itself. The fit step leaves a user-set context alone. So it can't shrink your context to make room. It can only move weights. A big context means more experts in RAM.
Our reading of Ollama's and llama.cpp's source, Oct 4, 2026. Not a benchmark. · aliteq research
The trap: setting num_gpu turns the smart part off
If you set num_gpu to any number, llama.cpp's fit step treats the layer count as yours and stops placing weights. You then get a plain split by whole layers: attention and experts move together. That is the old way of running a too-big model, and it's exactly what the expert-aware split was built to beat.
The line in fit.cpp is unambiguous. If the GPU layer count differs from the default, it stops with "n_gpu_layers already set by user ... abort". The log then shows "failed to fit params to free device memory".
That's why the folk advice "raise num_gpu until it fits" deserves a second look on Ollama 0.30 and later. On the older engine it was the only lever you had. On the current one, it switches off the placement that knows about experts. Our --n-cpu-moe explainer explains why attention belongs on the GPU and experts in RAM, and not the other way round.
So, if you set num_gpu in a Modelfile or an API call for an MoE model, try removing it first. Then compare.
How to check what Ollama actually did
Two places tell you. ollama ps shows the overall split between CPU and GPU memory. The Ollama server log carries llama-server's own startup lines, because Ollama runs it with verbose logging on purpose. Look there for the layer count and for any "failed to fit" warning.
Run ollama ps. The PROCESSOR column reads like "48%/52% CPU/GPU" when a model sits partly in system memory, per Ollama's FAQ. For an MoE model with experts in RAM, a split here is expected, not a failure.
Open the server log. Ollama starts llama-server with --log-verbosity 4, with a source comment saying it keeps "startup memory/offload lines visible". Look for "offloaded N/M layers to GPU".
Look for "failed to fit params to free device memory". It means something you set (num_gpu, or an override) took placement away from the fit step.
Shrink num_ctx if experts crowd out. Ollama's default context is 4K, 32K or 256K depending on your VRAM. A smaller window leaves more VRAM for experts.
A word of caution about ollama ps. Issue #15237 (April 2026) reported Gemma 4 showing "100% GPU" while actually running on the CPU. That bug was closed as completed on April 7, 2026. Release 0.30.11 also fixed ollama ps double-counting memory-mapped weights on partial offload. On a current version the column should be honest, but the log is the ground truth.
"I can already tell you're running ollama"
Ollama's defaults make it easy to start and easy to misjudge a model. In an r/LocalLLM thread on 30 October (456 votes), a small software house said Qwen3.8 27B at 128K context on an RTX 3090 with 32GB of RAM was "practically unusable for coding". The top reply, with 629 votes, was "I can already tell you're running ollama". The next asked for the quant, temperature, harness and engine settings. Other replies said the model works well even at Q4 once it is configured properly, and that small models need smaller, explicit tasks.
The lesson carries straight over to MoE offload. Before you blame the model, check the things Ollama picks for you:
Context. Ollama sets num_ctx from your VRAM (4K, 32K or 256K). Too small and long prompts get cut; too large and the cache pushes experts off the card.
Quant. A bare model tag pulls Ollama's default quant. Check which one you got with ollama show, and pick an explicit tag if it matters.
Sampling. Use the model card's recommended temperature and top_p, top_k values, not whatever the harness sends.
Placement. Run ollama ps and read the server log, as above. A num_gpu value left over in a Modelfile switches off the expert-aware split.
Qwen3.8 Flash Next in Ollama
Ollama's library has it, as qwen3.8-flash-next, described as an "experimental preview of the architecture that will underpin Qwen4". Its model card lists 125B parameters with 6B activated, 512 experts per layer and a separate 51B n-gram embedding. On November 1, 2026 the library page listed six tags, none marked cloud, all with a 256K context window and text plus image input:
Ollama's qwen3.8-flash-next tags (read Nov 1, 2026)
125b-a6b-q4_K_M
Size
120GB
Format
GGUF, llama.cpp engine
125b-a6b-q8_0
Size
189GB
Format
GGUF
125b-a6b-bf16
Size
355GB
Format
GGUF
125b-a6b-nvfp4
Size
105GB
Format
MLX (Apple Silicon)
125b-mlx
Size
105GB
Format
MLX (Apple Silicon)
125b-a6b-mlx-bf16
Size
360GB
Format
MLX (Apple Silicon)
Size
Format
125b-a6b-q4_K_M
120GB
GGUF, llama.cpp engine
125b-a6b-q8_0
189GB
GGUF
125b-a6b-bf16
355GB
GGUF
125b-a6b-nvfp4
105GB
MLX (Apple Silicon)
125b-mlx
105GB
MLX (Apple Silicon)
125b-a6b-mlx-bf16
360GB
MLX (Apple Silicon)
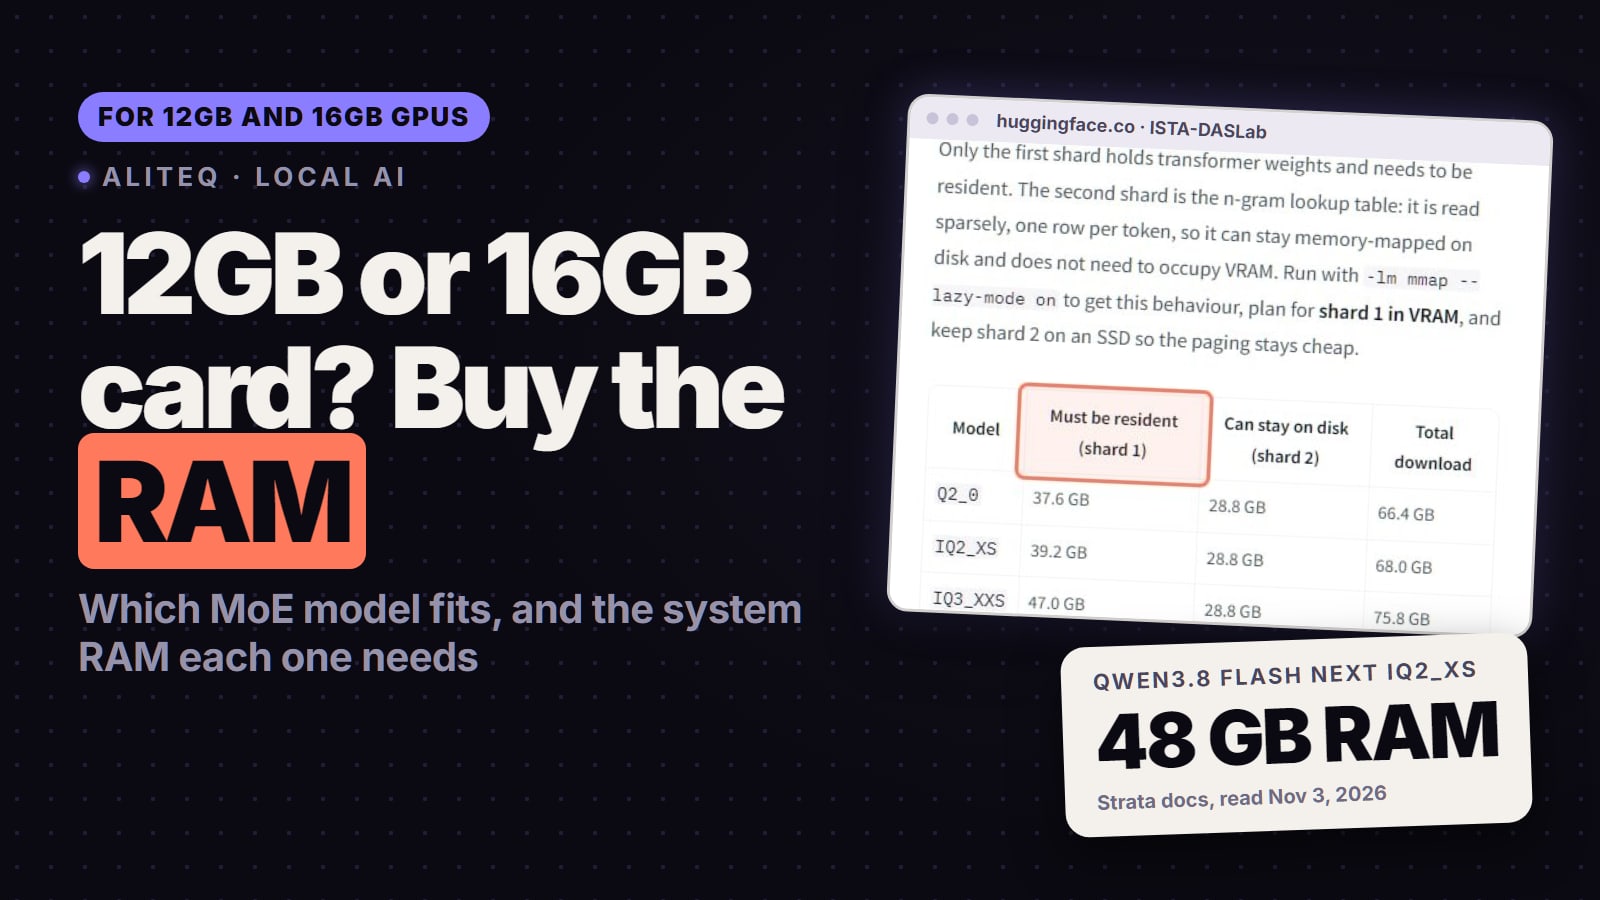
The catch for small-GPU owners: the smallest GGUF tag is 120GB. On a 12GB or 16GB card, almost all of that has to sit in system RAM, so plan on a 128GB kit for the q4_K_M tag. The 2-bit and 3-bit builds people run on 8GB and 12GB cards (68GB to 84GB in the ISTA-DASLab repo) are not Ollama library tags. Hugging Face pages offer ollama run hf.co/... commands for GGUF repos, and ISTA-DASLab's card says its files "run unmodified in llama.cpp, Ollama, and LM Studio"; that is the publisher's claim, not tested here. Ollama's docs also don't say whether it keeps Flash Next's 28.8GB n-gram table on disk the way llama.cpp's --lazy-mode on can, so budget RAM for the whole file.
No 128GB of RAM at home? The q4_K_M tag fits whole in the 141GB of one H200, so nothing has to be offloaded at all. On Vast.ai an H200 started at $3.75 an hour on Nov 17, 2026, and our live cloud GPU price table shows today's rate next to every other card.
Workaround 1: the inherited environment variable (unofficial)
Ollama launches llama-server with a copy of its own environment. llama.cpp reads LLAMA_ARG_N_CPU_MOE as the environment form of --n-cpu-moe. Put the two together and a variable set on the Ollama server reaches the engine. It works only because of how the code is written today, and Ollama documents none of it.
The source facts: Ollama's SetupLlamaServerCommandEnv starts from os.Environ(), the server's full environment. In llama.cpp b11232, --n-cpu-moe is tied to LLAMA_ARG_N_CPU_MOE and --cpu-moe to LLAMA_ARG_CPU_MOE. Ollama does document two llama.cpp variables of the same family, LLAMA_ARG_FIT and LLAMA_ARG_FIT_TARGET, in ollama serve help. The MoE ones aren't on that list. One user on issue #11772 reported using LLAMA_ARG_CPU_MOE this way in June 2026. It has not been tested for this guide.
If you try it, set the variable where Ollama's FAQ says server variables go: launchctl setenv for the Mac app, systemctl edit ollama.service with an Environment= line on Linux, or your user environment variables on Windows. Then restart Ollama.
Workaround 2: use llama.cpp or LM Studio for this model
If you want a per-model expert count that you control, use the tools that expose one. llama.cpp gives you --n-cpu-moe directly. LM Studio gives you a per-layer slider in a desktop app (an all-or-nothing toggle before 0.4.0). Keep Ollama for the models that fit, and run the big MoE one where you can set the number.
llama.cpp.llama-server -m model.gguf --n-cpu-moe N is the exact control the Ollama issue asks for. It also speaks the OpenAI API format, so most apps that talk to Ollama can point at it instead. The --n-cpu-moe explainer covers the flags and the -ot patterns. The gpt-oss-20b on an 8GB or 12GB card walkthrough applies it to one popular model.
LM Studio. Since 0.3.23, its advanced load settings include the expert setting, now a slider called "Number of layers for which to force MoE weights onto CPU" (our LM Studio guide). Its release notes describe it as "the same underlying technology as llama.cpp's --n-cpu-moe" and add a fair warning: "If you can offload the entire model to GPU memory, you're better off sticking with placing expert weights onto the GPU as well". Settings can be saved per model. If you're choosing between the two apps, our Ollama vs LM Studio comparison covers the rest of the trade.
Or skip offload with a bigger card
Offload exists because the model doesn't fit your card. Medium MoE models such as gpt-oss-20b fit whole on a 24GB RTX 4090, and then Ollama's default placement is simply "all on the GPU". Renting one for an evening is a cheap way to see how much faster the model runs without experts in RAM before you buy anything; renting vs buying a GPU for AI does the long-run math.
The image that ran with an earlier version of this guide.
Not as an Ollama setting. Its load options are num_ctx, num_batch, num_gpu, main_gpu, use_mmap, num_thread and draft_num_predict, and none controls experts. Issue #11772 asking for it has been open since August 7, 2025. Since Ollama 0.30, though, llama.cpp's automatic fit step can put experts in RAM when num_gpu is left unset.
Is there an OLLAMA_MOE_OFFLOAD environment variable?
No. OLLAMA_MOE_OFFLOAD with FULL, PARTIAL or NONE was a proposal in the first post of issue #11772. It was never added. Ollama's documented server variables include LLAMA_ARG_FIT and LLAMA_ARG_FIT_TARGET, but no MoE variable.
Does Ollama have Qwen3.8 Flash Next?
Yes, as qwen3.8-flash-next. On November 1, 2026 its smallest GGUF tag was 125b-a6b-q4_K_M at 120GB, with MLX tags at 105GB for Apple Silicon. On a 12GB or 16GB card that means well over 100GB of system RAM; the smaller 2-bit and 3-bit builds live on Hugging Face, and llama.cpp gives more control over them.
Should I set num_gpu for a big MoE model in Ollama?
On Ollama 0.30 or later, try leaving it unset first. Any num_gpu value makes llama.cpp's fit step stand aside, and you get a split by whole layers instead of the expert-aware one. num_gpu 0 forces the whole model onto the CPU.
Does the LLAMA_ARG_N_CPU_MOE trick work in Ollama?
The source suggests it can. Ollama hands its environment to llama-server, and llama.cpp reads that variable as --n-cpu-moe. Ollama doesn't document it, it applies to every model on that server, and it has not been tested for this guide. Treat it as unsupported.
Why does ollama ps show a CPU/GPU split for my MoE model?
Because part of the model sits in system memory. For an MoE model on a small card that's expected: the experts that don't fit live in RAM. Check the server log for the layer count and for any "failed to fit" warning to see who made the split.
Does any of this apply to older Ollama versions?
No. Before 0.30, Ollama ran its own engine, and the llama.cpp fit behavior described here wasn't in the path. Update to a current release, or use llama.cpp or LM Studio for MoE offload.