Both are free and run the same open models. Pick LM Studio to browse and tune models in an app, Ollama for a model your other tools call. Checked Nov 1, 2026.
If you've decided to run AI on your own computer, two names come up first: Ollama and LM Studio. Older comparisons call Ollama "the command-line one". That stopped being true in July 2025, when Ollama shipped a desktop app for macOS and Windows. We re-read both projects' docs and release notes on November 1, 2026 for this version.
What is the difference between Ollama and LM Studio?
The difference is the center of gravity, not the AI. LM Studio is a desktop app first: you search models, download them, pick settings and chat. Ollama is a local service first: it runs in the background, keeps a library of models, and any app on your machine can ask it for an answer. Both have a chat window and an API.
Ollama vs LM Studio, head to head (Nov 1, 2026)
LM Studio
the model workbench
vs
Ollama
the model service
Desktop app (Mac, Windows, Linux)
Interface
Desktop app (Mac, Windows) + CLI
Search and download from Hugging Face
Finding models
Curated ollama.com library, or import a GGUF
Every load setting exposed
Tuning
Sensible defaults, change in settings or env vars
OpenAI-compatible endpoints, SDKs
API
Own API + OpenAI-compatible
lms CLI, llmster headless
Scripting and servers
ollama CLI, runs as a service, ollama launch
Free app, closed source, personal and internal business use
Cost and licence
Free, MIT open source
Studio wins 2wins 2 Ollama
LM Studio: the model workbench
LM Studio is the better place to start if you like to see what you're doing. Its docs list the core jobs: download and run models such as gpt-oss, Llama and Qwen, chat, search and download from Hugging Face, connect MCP servers, and serve models on OpenAI-compatible endpoints on your machine or your network. It runs GGUF models with llama.cpp on Mac, Windows and Linux, and Apple's MLX on Apple Silicon Macs.
The part people underrate is the settings panel. LM Studio exposes the llama.cpp load options per model, including a switch that keeps mixture-of-experts weights in system RAM. That is the same idea as llama.cpp's `--cpu-moe` and `--n-cpu-moe` flags, and it's how a mixture-of-experts model on a 12GB or 16GB card becomes usable. The lms command line tool ships with the app, and llmster is a headless version for servers with no screen.
One thing to read before you use it at work: LM Studio is free but not open source. Its app terms (version of August 23, 2026) grant a licence "solely for Your personal and / or internal business purposes".
Same models, same engines. The choice is workflow: tune it yourself (LM Studio) or plug it into other tools (Ollama). · Unsplash
Ollama: the model service
Ollama is the better pick when the model is a part, not the product. Running one is a single line, ollama run gemma4, and its API on port 11434 is the default in many open-source tools. ollama launch connects it to coding tools: the README lists Claude Code, Codex, Copilot CLI, DeepSeek Harness, Droid and OpenCode (for example ollama launch claude).
Under the hood it runs llama.cpp plus its own MLX engine on Apple Silicon. Since v0.40.0 (September 25, 2026), "model architectures supported by the MLX runtime will automatically run on MLX" on Apple Silicon. The latest release on 1 November is v0.40.13 (28 October).
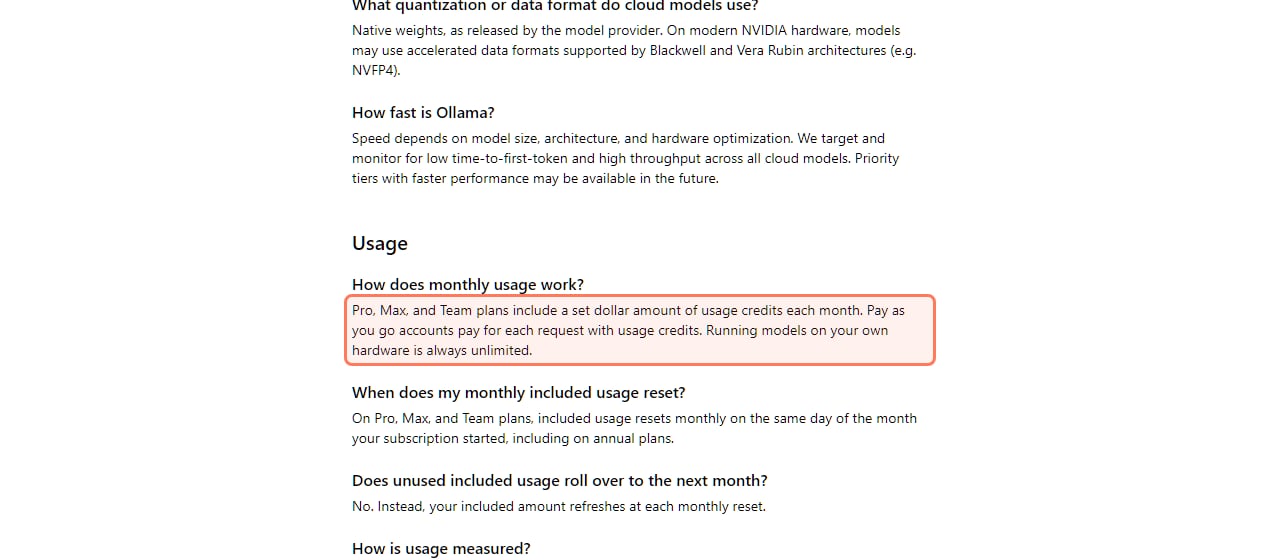
Ollama also runs paid cloud models. Its pricing page (read 1 November) lists pay-per-token and subscription plans for those, no free cloud tier, and says "Running models on your own hardware is always unlimited." Users on r/ollama report an email saying free accounts switch to pay-as-you-go for cloud models from 9 November. Everything on this page is about local models, which stay free. If you want local models in your editor, see how to use Ollama with Claude Code.
Ollama's pricing page, read Nov 1, 2026: cloud use is paid, local use is unlimited.
Is Ollama or LM Studio faster?
Neither is reliably faster. On a PC both run llama.cpp on the same GGUF file, so on identical settings the speed is close. Real gaps come from defaults: how much of the model sits on the GPU, and how big the context window is. Neither project publishes a head-to-head benchmark, and we didn't run one, so we don't print a winner.
Where the differences come from, per the docs:
Context length. Ollama sets its default context by VRAM: 4k tokens under 24 GiB, 32k at 24 to 48 GiB, 256k at 48 GiB or more. In LM Studio, context length is a per-model load setting. Compare at the same context or the numbers mean nothing.
GPU offload. If part of the model spills to system RAM, speed drops sharply. ollama ps shows the split in its PROCESSOR column. In LM Studio, GPU offload is a per-model load setting.
Engine on a Mac. MLX vs GGUF on the same Mac is a bigger difference than Ollama vs LM Studio.
Engine version. Both ship llama.cpp updates on their own schedule, so a fix can land in one before the other.
To measure on your own machine, run ollama run <model> --verbose. After each answer it prints an "eval rate" in tokens per second. Then run the same model file, quantization, context and prompt in LM Studio.
Ollama or LM Studio on a Mac?
Both work well on Apple Silicon, and both run MLX models, so pick on workflow. LM Studio needs an M-series Mac on macOS 14 or newer; its docs say "Intel-based Macs are currently not supported." Ollama also needs macOS 14 (Sonoma) and runs on Intel Macs, but CPU only.
Is either one safe to leave running?
On your own computer, yes, with defaults left alone. Ollama binds to 127.0.0.1:11434 unless you change OLLAMA_HOST, so only your own machine can reach it. LM Studio's docs say it "does not require authentication for API requests" by default; since 0.4.0 you can switch on API tokens in Server Settings.
The risk starts when you open either one to a network. Ollama's API has no login of its own, and this year's most serious Ollama flaw, CVE-2026-7482 (NVD score 9.1, fixed in v0.17.1), was reachable through exactly those unauthenticated endpoints. Keep Ollama updated, and if other devices need it, put it behind a proxy that asks for a key. Our full four-way comparison has the details for anyone setting this up for a team.
Can you use Ollama and LM Studio together?
Yes. Ollama listens on port 11434 and LM Studio on port 1234, so both can run at once. A common split is LM Studio for trying and tuning new models, Ollama as the always-on backend your other apps call. Each keeps its own model store, so the cost is disk space if you download a model twice. If you have a GGUF file, you can load that one file into both:
# LM Studio: copy a GGUF into its library (without --copy, the file is moved)
lms import /path/to/model.gguf --copy

# Ollama: point a Modelfile at the same GGUF, then build it
echo "FROM /path/to/model.gguf" > Modelfile
ollama create my-model -f Modelfile
If you want to browse and tune models, use LM Studio; if you want a model that other tools call, use Ollama. A beginner who wants a private assistant will be happy in either, but LM Studio's built-in model search makes the first week easier. A developer wiring AI into a project will find more tools that expect Ollama. Whichever you choose, pick a model sized to your hardware.
The image that ran with an earlier version of this guide.
Quick answers
Is Ollama or LM Studio better for beginners?
LM Studio, by a small margin. Both have a desktop app, but LM Studio's built-in Hugging Face search and load settings make it easier to find a model that fits your hardware. Ollama's app is simpler, with fewer choices, which some beginners prefer. Neither needs a terminal.
Is Ollama faster than LM Studio?
Not reliably. Both run llama.cpp for GGUF models and both have an MLX engine on Apple Silicon, so speed on the same model, quantization and context is close. Most "twice as fast" results come from different context sizes or GPU offload. Measure with ollama run --verbose, then run the same prompt in LM Studio.
Is LM Studio free for work?
The app is free but not open source. Its terms, version of August 23, 2026, license it for personal and internal business purposes. If you plan to build a product or a paid service on it, read the current terms first. Ollama is MIT-licensed open source.
Can LM Studio use my Ollama models?
Not directly. Each app keeps its own model library. If you have the original GGUF file, import it into LM Studio with lms import and into Ollama with a Modelfile that says FROM followed by the file path, then ollama create.
Ollama or LM Studio for Mac?
Both are good on Apple Silicon and both run MLX models; Ollama has used MLX by default there since v0.40.0. LM Studio requires an M-series Mac on macOS 14 or newer. Ollama also requires macOS 14 and runs on Intel Macs, but CPU only.
Is Ollama safe?
On one computer with default settings, it only listens on 127.0.0.1, so other devices can't reach it. Its API has no login, so don't expose it to a network without a proxy that checks a key, and keep it updated. CVE-2026-7482, fixed in v0.17.1, leaked memory through those open endpoints.
Ollama or LM Studio: tune or plug in. Pick the one that matches how you want to work, size a model to your card, and get going. New to this entirely? Start with the beginner's guide, then browse the best free models.