Moving MoE experts into system RAM can make a model five times faster, or noticeably slower. Both are true. With Qwen3.8 Flash Next now running on 8GB and 12GB cards, here is what the flag moves, where your RAM becomes the limit, and which speed tricks quietly change the answers.
Some links on this page are referral links: we may earn a commission, at no cost to you.
Share
There's a result that circulates in local-LLM threads and sounds like nonsense: someone moves more of their model off the GPU and onto the CPU, and it gets nearly five times faster. Not five percent. Five times. Every instinct says that's backwards: system RAM is slower than VRAM, so shifting work to it should hurt.
The measurement is real. It traces to a merged llama.cpp pull request with the full llama-bench output attached. But the explanation people give for it is usually wrong, and acting on the folklore version makes a setup slower, not faster. In October the same confusion moved to a much bigger model, Qwen3.8 Flash Next, which people now run on 8GB and 12GB cards by pushing most of it into RAM and onto the SSD.
What the flag actually does
--n-cpu-moe N does one specific, narrow thing. For layers 0 through N-1, it overrides the buffer type for tensors matching this pattern:
\.ffn_(up|down|gate|gate_up)_(ch|)exps
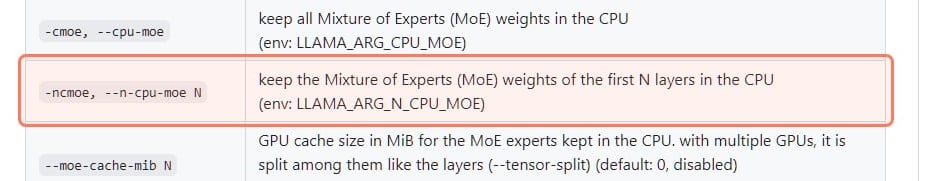
llama.cpp's own documentation for the flag, captured Nov 1, 2026.
Those are the routed expert weights: the big stacks of per-expert feed-forward matrices that make an MoE model large. Nothing else moves. Attention weights stay where -ngl put them. So does the KV cache, the router that picks which experts to use (ffn_gate_inp), any shared experts (_shexp), the layer norms and the embeddings.
You can see the shape of it in our model catalogue. On Qwen3-30B-A3B, the routed experts account for roughly 95% of the parameters, while only about 3.3B are active for any given token. Qwen3.8 Flash Next takes this to an extreme: its model card lists 125B parameters with 6B activated, and 512 experts per layer with 10 routed plus 1 shared active. Each token touches 10 of 512 routed experts, about 2%.
--cpu-moe vs --n-cpu-moe vs -ot
All three flags do the same kind of thing: they tell llama.cpp to keep certain weight tensors in system RAM. They differ only in how much you control. --cpu-moe moves every MoE expert weight. --n-cpu-moe N moves them for the first N layers only. -ot lets you write the pattern yourself.
The MoE offload flags in llama.cpp (help text read Nov 1, 2026)
--cpu-moe (short: -cmoe)
Official help text
keep all Mixture of Experts (MoE) weights in the CPU
What it does
Every layer's routed experts
Environment variable
LLAMA_ARG_CPU_MOE
--n-cpu-moe N (short: -ncmoe)
Official help text
keep the Mixture of Experts (MoE) weights of the first N layers in the CPU
What it does
Layers 0 to N-1 only
Environment variable
LLAMA_ARG_N_CPU_MOE
-ot / --override-tensor
Official help text
override tensor buffer type
What it does
Any tensor whose name matches your regex
Environment variable
LLAMA_ARG_OVERRIDE_TENSOR
--moe-cache-mib N
Official help text
GPU cache size in MiB for the MoE experts kept in the CPU (default 0, disabled)
What it does
Nothing moves; a VRAM cache for RAM-resident experts
Environment variable
LLAMA_ARG_MOE_CACHE_MIB
Official help text
What it does
Environment variable
--cpu-moe (short: -cmoe)
keep all Mixture of Experts (MoE) weights in the CPU
Every layer's routed experts
LLAMA_ARG_CPU_MOE
--n-cpu-moe N (short: -ncmoe)
keep the Mixture of Experts (MoE) weights of the first N layers in the CPU
Layers 0 to N-1 only
LLAMA_ARG_N_CPU_MOE
-ot / --override-tensor
override tensor buffer type
Any tensor whose name matches your regex
LLAMA_ARG_OVERRIDE_TENSOR
--moe-cache-mib N
GPU cache size in MiB for the MoE experts kept in the CPU (default 0, disabled)
Nothing moves; a VRAM cache for RAM-resident experts
LLAMA_ARG_MOE_CACHE_MIB
Under the hood, the first two are shortcuts for the third. --cpu-moe adds one override with the pattern shown above. --n-cpu-moe 3 adds three overrides, one per layer, of the form blk\.0\.ffn_(up|down|gate|gate_up)_(ch|)exps, then blk\.1… and blk\.2…. So these two commands do the same thing:
Which one should you use? Use --n-cpu-moe almost always. It has one knob, and that knob maps straight onto the V-shaped curve below. Use --cpu-moe when the model is far too big for your card and you want the simplest possible start; that is the same as setting --n-cpu-moe to the layer count. Reach for -ot only when you need a pattern the shortcuts can't express, like pinning specific layers to a second GPU. The text after the = must be a buffer type your build knows. If it isn't, llama.cpp prints the list of available buffer types and stops.
The README now also lists --moe-cache-mib N, which reserves a slice of VRAM as a cache "for the MoE experts kept in the CPU". It is off by default. It is llama.cpp's own answer to "keep the hot experts on the GPU": the experts still live in RAM, and the cache holds some of them in VRAM. llama.cpp's docs do not say how it picks what to cache, so treat it as something to measure, not a default. Unlike the expert-biasing tricks covered further down, a cache only changes where a weight is read from, not which experts the model uses.
Two more flags matter once experts are in RAM. The KV cache can be stored at lower precision with -ctk / -ctv (the README lists types including q8_0, q5_0, q5_1, q4_0 and iq4_nl), which frees VRAM for more expert layers; a smaller cache type is a quality trade, so q8_0 is the cautious start. -fa, --flash-attn [on|off|auto] defaults to auto.
If you searched for the phrase "number of layers for which to force MoE weights onto CPU", that is this same N. It counts layers from the start of the model, not experts. N = 0 moves nothing. N equal to the model's layer count is the same as --cpu-moe. That phrase is LM Studio's label for its slider; our LM Studio MoE offload guide covers the app side, and our Ollama MoE guide explains why Ollama has no such setting.
Normally, more offload is slower
This is the part the folklore skips. When the model already fits on your GPU, increasing --n-cpu-moe degrades throughput steadily and predictably. A llama.cpp contributor published a clean sweep of it while working on CUDA graph support for this path:
Token generation as offload increases (tg128), model fits comfortably
GLM-4.5-Air 106B IQ4_XS
ncmoe 8
60.84 t/s
ncmoe 16
48.25 t/s
ncmoe 32
32.84 t/s
ncmoe 64
25.08 t/s
gpt-oss 120B MXFP4
ncmoe 8
95.96 t/s
ncmoe 16
70.42 t/s
ncmoe 32
44.80 t/s
ncmoe 64
40.87 t/s
ncmoe 8
ncmoe 16
ncmoe 32
ncmoe 64
GLM-4.5-Air 106B IQ4_XS
60.84 t/s
48.25 t/s
32.84 t/s
25.08 t/s
gpt-oss 120B MXFP4
95.96 t/s
70.42 t/s
44.80 t/s
40.87 t/s
Monotonic decline, both models. Every layer you push to the CPU is a layer whose expert weights are now read from system RAM instead of out of VRAM. That's the behaviour physics predicts, and it's what you should expect by default.
If more offload is making you faster, something is already wrong. The speedup is a symptom, not a feature.
Qwen3-30B-A3B-Instruct-2507 Q3_K_M (13.70 GiB) on a 12 GB RTX 5070, Windows
-ngl 99 alone
Generation (tg128)
11.09 t/s
Prefill (pp512)
378.46 t/s
-ngl 99 --n-cpu-moe 12
Generation (tg128)
54.04 t/s
Prefill (pp512)
1,253.62 t/s
Change
Generation (tg128)
4.87×
Prefill (pp512)
3.31×
Generation (tg128)
Prefill (pp512)
-ngl 99 alone
11.09 t/s
378.46 t/s
-ngl 99 --n-cpu-moe 12
54.04 t/s
1,253.62 t/s
Change
4.87×
3.31×
Look at the model size against the card. 13.70 GiB does not fit in 12 GB. That's the entire story.
On Windows, NVIDIA's driver has a feature called System Memory Fallback. When a CUDA allocation won't fit in VRAM, rather than failing it silently backs the allocation with host RAM and pages it over PCIe on demand. Your model "loads". It runs. It runs terribly, because the driver is now shuttling weights across the bus with no idea which ones matter.
The 11 t/s baseline isn't GPU inference. It's a driver frantically paging. When you then set --n-cpu-moe 12, you're not adding a penalty: you're taking control of a decision the driver was already making badly. You tell it exactly which tensors live in host memory, everything else fits properly in VRAM, and the thrashing stops. Hence 54 t/s.
The actual shape: a V, not a slope
Put both findings together and the real curve has three regions.
Too little offload: the model overcommits VRAM. On Windows you get driver paging and catastrophic throughput. This is the left arm of the V.
The knee: the smallest N where everything genuinely fits in VRAM. This is the fastest configuration, and it's what you're looking for.
Too much offload: every extra layer sends more expert weight through slow RAM for no benefit. Slow, steady decline. The right arm.
Which reframes the tuning problem completely. You're not looking for "how much can I offload"; you're looking for the least you can get away with. Start at zero, increase until it fits without overcommitting, stop. Every step past that costs you.
Your RAM, not the flag, sets the speed
Once expert weights live in host memory, their read speed is your memory bandwidth. That is the part people underestimate. When a user on r/ollama asked why a 27B model on a 24GB card with 64GB of RAM was "so much slower than I imagined", the top advice was to keep the model fully in VRAM, because system RAM is 10 to 20 times slower. In a 1 November r/LocalLLaMA thread where offloaded experts on two Radeon AI PRO R9700 cards hung on long tasks, a reply made the same point: once you offload, system-RAM bandwidth and the CPU become the bottleneck.
A rough way to see the ceiling, our arithmetic: each new token reads the chosen experts from wherever they live. For Qwen3.8 Flash Next at IQ2_XS, Strata's model notes put the expert weights at 35.5 GB, and the router picks 10 of 512 per layer, so a token reads about 10 / 512 × 35.5 ≈ 0.7 GB of expert data if every expert sat in RAM. Dual-channel DDR4-3200 moves about 51 GB/s in theory (3,200 MT/s × 8 bytes × 2 channels), which caps that case near 70 tokens per second before attention, the CPU's own compute or anything else costs a millisecond. Real numbers land well below such ceilings. Every expert layer you keep on the GPU lowers the RAM read, which is why the knee of the V matters.
Two more consequences:
Dual-channel desktop DDR5 is a different machine from quad-channel or server memory. The same --n-cpu-moe value behaves very differently across them. Any specific speed someone quotes you is a number from their motherboard, not yours.
Prompt processing suffers differently from generation. A critic in the r/LocalLLaMA thread about Flash Next on an 8GB card noted that around 70 tokens per second of prompt processing means minutes before the first token in an agent harness that sends long prompts. If you use coding agents, measure prefill, not only generation.
Qwen3.8 Flash Next: the new headline example
Qwen3.8 Flash Next is why this flag is everywhere again. Per its model card and config.json (read November 1, 2026), it has 48 layers, 512 experts per layer (10 routed plus 1 shared active), hybrid attention with full attention on every fourth layer, a native context of 262,144 tokens, and something new: a 51B-parameter n-gram embedding that the card says is "more amenable to offloading than Mixture-of-Experts (MoE)". Its licence is qwen-community-1.0, a custom licence rather than Apache.
That gives you two piles to move off the card, not one:
The experts go to RAM. Same as any MoE model: --n-cpu-moe N, --cpu-moe, or let --fit place them.
The n-gram table can stay on disk. In the ISTA-DASLab GGUF repo it is a separate 28.8 GB second shard, read one row per token. llama.cpp's --lazy-mode on reads such tensors "from disk on demand instead of keeping them resident (requires mmap)".
Attention, the shared expert and the KV cache stay on the GPU. Only 12 of the 48 layers keep a full KV cache, so long context is cheap for a model this size.
The ISTA-DASLab card's own example command uses -lm mmap --lazy-mode on -ngl 99 and says this "removes 28.8 GB from the resident footprint". Both flags are in llama.cpp's README: -lm, --load-mode (values auto, none, mmap, mlock, mmap+mlock, dio; default auto) and -lzm, --lazy-mode (on, auto, off; auto turns it on only for tensors larger than 4 GiB). A minimal start on a current build, letting --fit place the experts:
# Qwen3.8 Flash Next, ISTA-DASLab IQ2_XS: --fit places experts, n-gram table read from disk
llama-server -m IQ2_XS/Qwen3.8-Flash-Next-GSQ-RCO-IQ2_XS-00001-of-00002.gguf \
  -c 32768 -lm mmap --lazy-mode on
What people report on small cards (their numbers, not ours):
8GB VRAM, 32GB RAM, Q2, Strata: up to 900 tokens/s prompt processing and 30 tokens/s generation, per the most-upvoted October post (910 votes). Strata splits the model across VRAM, RAM and SSD. The poster found it better than any Qwen 3.6 35B-A3B fine-tune or Qwen 3.8 27B they tried.
RTX 3060 12GB, 16GB DDR4, IQ2_XS (the 68 GB GSQ-RCO build), Betelgeuse engine: 22 tokens/s sustained, "without dropping a single expert", per its author.
8GB GPU, 24GB RAM, about 3.5 bits per weight (Flash-Next Coder), llama.cpp, 262K context: most experts in RAM and the n-gram table on disk, per this thread.
Two tips from that last thread are worth knowing, and both are the thread's claims, not documented behaviour. A commenter reported about 50% faster prompt processing with --load-mode none instead of mmap. none is a documented value ("no special loading mode"), but the README also says lazy mode "requires mmap", so that trade presumably keeps the 28.8 GB n-gram table in RAM: only worth it if you have the RAM to spare. The author also said CUDA struggled at 8GB and suggested trying a Vulkan build if loading fails. llama.cpp's server README does not cover that case, so treat it as one user's workaround.
Three reasons this may not apply to you
You're probably on a build that fixes this automatically. llama.cpp's --fit is on by default (-fit, --fit [on|off], "default: 'on'" in the README). It auto-sizes offload to what will actually fit, which largely prevents anyone from landing in the overcommit regime in the first place. This advice increasingly matters for older builds, manually forced configurations, and non-CUDA backends. The next section shows how --fit and --n-cpu-moe interact.
On Linux you'd probably have seen an error instead. Stock CUDA on Linux doesn't do the silent host-memory fallback unless you opt in with GGML_CUDA_ENABLE_UNIFIED_MEMORY=1. Without it, an overcommitted model usually just fails to allocate and tells you so. A loud failure beats a quiet 5× slowdown.
Your model may simply fit. A dense model or a small MoE that fits whole on the card gains nothing from this flag. For 16GB cards, r/LocalLLaMA's October ranking thread put the dense Qwen3.8 27B first; see our 16GB guide for what fits without offload.
How to pick N on a current llama.cpp build
On a current build, try no MoE flag at all first. The default --fit on already does a version of --n-cpu-moe for you. If you then add --n-cpu-moe yourself, --fit stops placing weights and your N is final. So a manual value only helps when it beats the automatic one.
Here is what the fit code does, read in common/fit.cpp on October 4, 2026. It only adjusts settings you did not set yourself. It aims to leave a safety margin of 1,024 MiB free on each GPU (change it with --fit-target). It may shrink the context first, but never below 4,096 tokens (change it with --fit-ctx); both defaults match the README on 1 November. For a MoE model it then fills the GPU with the small, hot tensors first, with all expert weights in RAM. After that it moves expert weights back onto the GPU while they still fit. That is the knee of the V, found for you.
The catch is in the same file. If you set -ngl, --n-cpu-moe, --cpu-moe or -ot yourself, the fit step logs "failed to fit params to free device memory" and leaves weight placement to you. It can still have trimmed the context before that point. So you have two sane workflows:
Let --fit do it. Run with no offload flags, read the log, and check speed with llama-bench. This is the right default for most people.
Tune by hand. Start at --n-cpu-moe 0 and raise it one step at a time until the model loads with headroom, then stop. llama-bench accepts --n-cpu-moe too, so you can sweep several values in one run (PR #15952).
Never keep raising N once it fits. That is the slow right arm of the V.
A dense model has no expert tensors, so --n-cpu-moe does nothing for it. Since August 27, 2026 (PR #26622) llama.cpp has a sibling for that case: --n-cpu-ffn N (short -ncffn), which the README describes as keeping "the dense FFN weights of the first N layers in the CPU". The gpt-oss-20b on an 8GB or 12GB card walkthrough shows the MoE version on a real model.
Quality: what the speed tricks cost
--n-cpu-moe, --cpu-moe and -ot only change where weights are stored. The router still picks the same experts, so the model computes the same thing, only slower or faster. October's arguments were about two other things that do change answers.
Low quants. The Flash Next packs that fit desktop RAM are 2-bit and 3-bit, and that is contested. In one r/LocalLLM thread the poster called everything up to IQ3 terrible, and a reply said "No model is great below Q4". In another, replies reported a Q3_S Flash Next beating Qwen3.8 27B at FP8. The quantizer's own card reports IQ2_XS and IQ3_XXS scoring close to the BF16 model on AIME25, GPQA-Diamond and LiveCodeBench v6; those are the vendor's benchmarks, not independent ones. Test on your own tasks before you trust a 2-bit build.
Engines that swap or skip experts. Some newer engines add speed options that route tokens toward experts already on the GPU, or skip lower-ranked experts that are not. An engine developer measured two such flags and found both change outputs; a commenter's takeaway was "q8 to q3 is less of a hit than enabling bias & tail skip". llama.cpp's README lists no flag of that kind (read November 1, 2026). If an engine offers one, it should be opt-in, and you should compare answers with it off.
Sampling defaults. In a thread asking why Flash Next disappointed (UD-Q4_K_XL on four RTX 3090s, losing to Qwen3.8 27B at Q8 on a coding task), the top reply said Strata "defaults to greedy decoding instead of Qwen's recommended sampling parameters". Strata's current documentation (DETAILS.md) says requests that leave sampling out get the model card's values and that greedy decoding happens only when you ask for temperature 0, so that complaint likely describes an older version; set sampling explicitly either way. Qwen's card recommends temperature 1.0, top_p 0.95, top_k 20 for thinking mode, and temperature 0.7, top_p 0.80, top_k 20 with presence_penalty 1.5 for instruct mode.
Other offload engines (community projects)
llama.cpp is the stable option. October also brought engines built around Flash Next. All of these are young; pin a version and keep llama.cpp as your fallback.
Strata (GitHub): describes itself as "Qwen3.8-Flash-Next on any consumer hardware", MIT-licensed, version 0.2.9 on its release files (1 November). Its model notes say Flash Next fits when "RAM is at least the experts plus about 10 GB", that reading experts from the SSD when RAM is short "works and is much slower", and that a bigger graphics card "does not lower the RAM needed". Reddit users have reported quality changes between versions and breaking changes.
Lean-QwenFlash: streams experts from an NVMe SSD. Its author reported about 20 tokens/s for a 16GB VRAM plus 8GB RAM setup, with the published numbers measured on an RTX 4090; a top commenter called its KL-divergence quality check "a joke" because the test corpus was tiny.
Betelgeuse: the 12GB RTX 3060 result above, from its author, who said an earlier version that pruned experts was scrapped because it hurt quality.
ik_llama.cpp (GitHub): a "llama.cpp fork with additional SOTA quants and improved performance". Its README lists Qwen-3.8-Flash-Next support and DFlash 2, and supports --cpu-moe and --n-cpu-moe; it warns not to use -rtr for hybrid CPU/GPU inference with experts left on the CPU.
One mainline addition also helps offloaded setups: llama.cpp v0.8.0 (October 28, 2026) lists "probabilistic DFlash2 drafts" for speculative decoding (--spec-type includes draft-dflash). A small drafter proposes tokens and the main model checks them. One r/LocalLLaMA user reported about 17% faster generation on average on an M5 Max (18% on code, 3% slower on prose).
The image that ran with an earlier version of this guide.
Quick answers
What value of --n-cpu-moe should I use?
The smallest one where the model fits in VRAM without overcommitting. Start at 0 and increase until it loads cleanly, then stop, because every further step costs throughput. On a current build, first try no flag at all and let --fit choose.
What is the difference between --cpu-moe and --n-cpu-moe?
--cpu-moe (short -cmoe) keeps every layer's MoE expert weights in system RAM. --n-cpu-moe N (short -ncmoe) does the same for the first N layers only. Setting N to the model's layer count gives the same result as --cpu-moe. Both are shortcuts for an -ot (--override-tensor) rule.
What does ncmoe mean in llama.cpp?
-ncmoe is the short form of --n-cpu-moe, the number of layers whose MoE expert weights stay in CPU memory. Its environment variable is LLAMA_ARG_N_CPU_MOE. llama-bench accepts the same flag with a comma-separated list, so you can compare several values in one run.
How do I run Qwen3.8 Flash Next on a small GPU with llama.cpp?
Use a 2-bit or 3-bit GGUF, keep the experts in RAM (let --fit place them, or set --n-cpu-moe), and keep the 28.8 GB n-gram table on disk with -lm mmap --lazy-mode on, as the ISTA-DASLab card shows. You need enough system RAM for the expert weights; our 12GB and 16GB MoE guide gives the numbers.
Does --n-cpu-moe change the model's answers?
No. It only changes where the expert weights are stored, not which experts the router picks. Flags in some other engines that bias routing toward GPU-resident experts or skip lower-ranked experts do change outputs.
Does --n-cpu-moe help dense (non-MoE) models?
No. It targets routed expert tensors, and a dense model doesn't have any. For dense models use -ngl, or --n-cpu-ffn N (short -ncffn, added August 27, 2026), which keeps the dense FFN weights of the first N layers in RAM.
Why did my throughput get worse after following this advice?
Almost certainly because your model already fitted. You've moved expert weights from VRAM to system RAM for no reason, and RAM bandwidth now limits every token. Reduce the value, or remove the flag and let a recent llama.cpp size it for you.
Does the KV cache move to the CPU too?
No. The flag only overrides tensors matching the routed-expert pattern. The KV cache stays where it was, which matters at long context, because a large KV cache can push you back into overcommit even when the weights fit.
If you want to know whether your model fits before you start guessing at flags, the interactive VRAM calculator and our cost-to-run pages compute the weight and KV-cache requirement per quantisation from each model's own configuration, so you can see which term is pushing you over the edge.