AI
What's the best model to run on a 24GB GPU like a 3090 or 4090? Qwen3.8 27B, and when to pick another
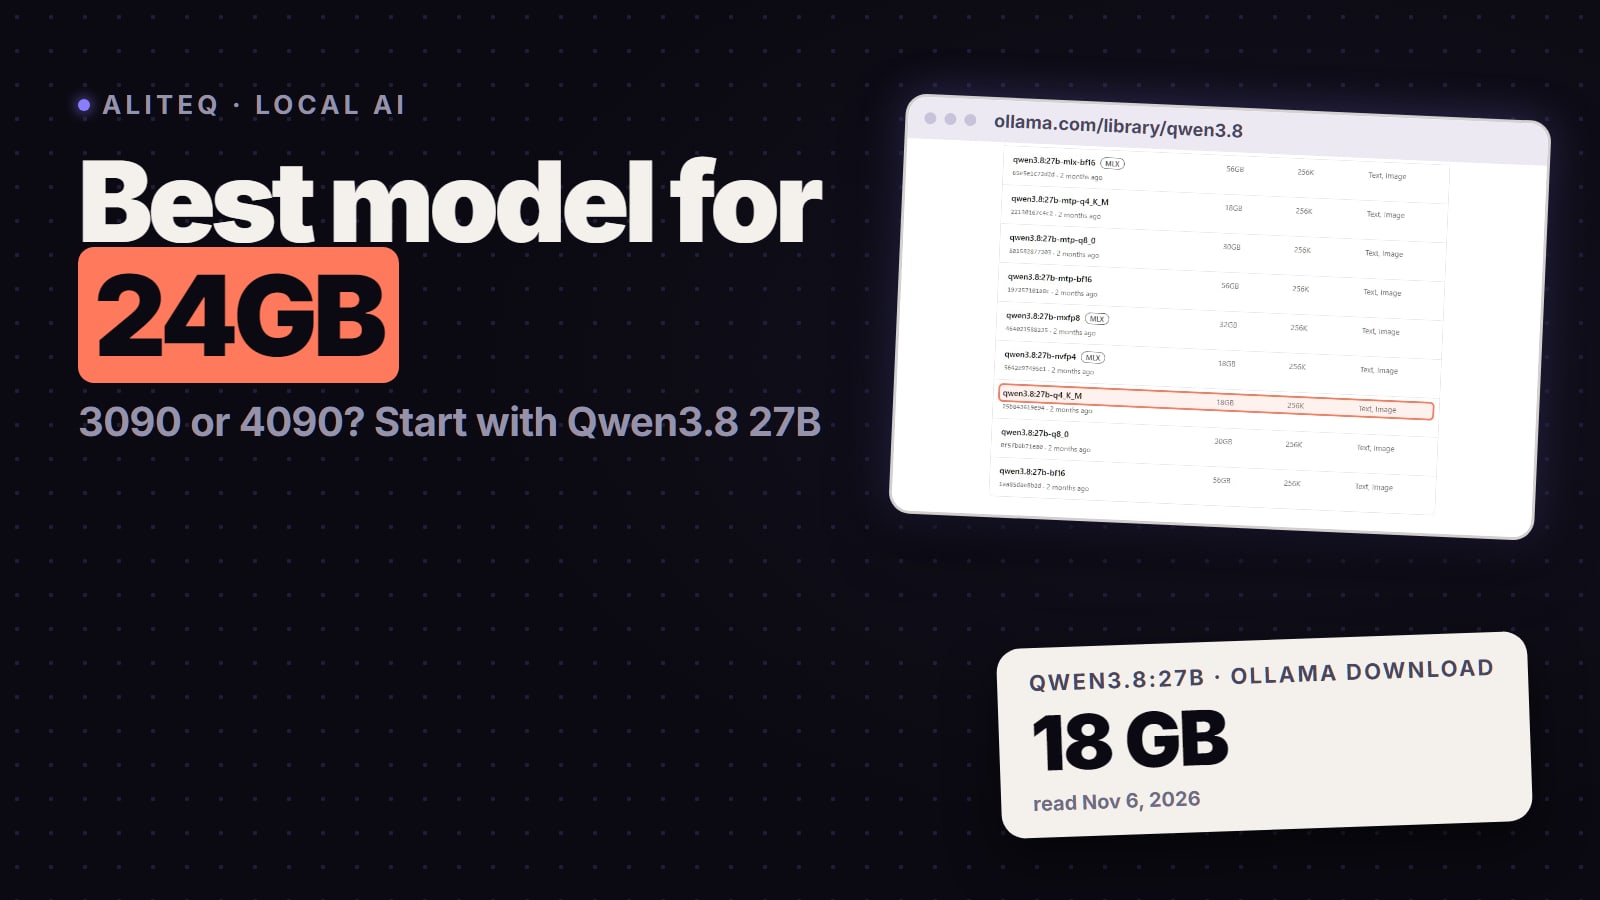
Short answer: Qwen3.8 27B. On our VRAM numbers it fits a 24GB card at Q5_K_M with 32K of context, and Ollama's default download is 18 GB. Gemma 4 and Qwen3.6 MoE models are faster, gpt-oss-20b leaves the most room, and NVIDIA's 24GB Nemotron comes with a runtime catch.
Aliteq Team · · 9 min