For most people in November 2026 that's a used 24GB RTX 3090: it runs 27–32B models and costs far less per GB than an RTX 4090 or 5090. Which card fits each model size and budget, what we could source on the vendors' own pages, and when renting by the hour beats buying.
Some links on this page are referral links: we may earn a commission, at no cost to you.
Share
The best GPU for local AI right now is the cheapest card with enough VRAM for the models you want to run. For most people in November 2026 that's a used RTX 3090: 24GB runs the 27–32B models most home users want, and at a $1,543 lowest eBay average on GPU Poet (checked Nov 12, 2026) it's the cheapest 24GB card with CUDA; a used RX 7900 XTX is a little cheaper ($1,415) if you accept AMD's software. Up to 14B models, a 12GB card is enough. Only buy the 32GB RTX 5090 if you need 30–35B models at long context, and only near its $1,999 list price; it was out of stock on NVIDIA's US marketplace on Nov 1, 2026. If you'd use the card a few hours a week, rent instead: a 24GB RTX 3090 was $0.09 an hour on Vast.ai when our tracker read prices on Nov 3, 2026.
How much VRAM do I need for local AI?
Enough to hold the model you want to run, because a model that doesn't fit in GPU memory spills into system RAM and slows to a crawl. So decide what you want to run before you look at a single price. Our rough map at Q4: 8GB handles small 7–8B models (Llama 3.1 8B, Qwen3 8B, a quantizedgpt-oss-20B with offload); see the best local LLMs for 8GB. 12–16GB runs 14B models, with 16GB leaving room for long context (16GB picks). 24GB runs 27–32B models such as Qwen3.8 27B and Qwen3-32B. 32GB runs the 30–35B class at very long context. A dense 70B at Q4 needs about 40GB, so no single consumer card holds it. For your exact model, quantization and context length, use the VRAM calculator.
7–8B
8GB VRAM
small models, tight quant
up to 14B
12–16GB VRAM
the budget floor
27–32B
24GB VRAM
the tier most people want
30–35B, long context
32GB VRAM
single-card ceiling
Which GPU should I buy at each budget?
Local-AI GPU shortlist: VRAM and the prices we could source (Nov 1–12, 2026)
Used RTX 3060 12GB
VRAM
12GB
Price we could source
$337 eBay low avg (GPU Poet, Nov 12)
Who it's for
Cheapest CUDA start; 7–14B
Intel Arc B580
VRAM
12GB
Price we could source
$249 list (Intel, read Nov 3); hard to find near it
Who it's for
Value only near list price
RTX 5060 Ti 16GB
VRAM
16GB
Price we could source
From $869.99 (NVIDIA store, Nov 1)
Who it's for
14B with long context
RTX 5070 Ti
VRAM
16GB
Price we could source
From $1,299.99 (NVIDIA store, Nov 1)
Who it's for
Faster 16GB; same ceiling
Used RTX 3090
VRAM
24GB
Price we could source
$1,543 eBay low avg (GPU Poet, Nov 12)
Who it's for
Best value for most buyers; 27–32B
Used RTX 4090
VRAM
24GB
Price we could source
$3,133 eBay low avg (GPU Poet, Nov 12)
Who it's for
Same models, about 1.5x faster
RTX 5090
VRAM
32GB
Price we could source
$1,999 list, out of stock (NVIDIA store, Nov 1)
Who it's for
Only if you need 32GB
VRAM
Price we could source
Who it's for
Used RTX 3060 12GB
12GB
$337 eBay low avg (GPU Poet, Nov 12)
Cheapest CUDA start; 7–14B
Intel Arc B580
12GB
$249 list (Intel, read Nov 3); hard to find near it
Value only near list price
RTX 5060 Ti 16GB
16GB
From $869.99 (NVIDIA store, Nov 1)
14B with long context
RTX 5070 Ti
16GB
From $1,299.99 (NVIDIA store, Nov 1)
Faster 16GB; same ceiling
Used RTX 3090
24GB
$1,543 eBay low avg (GPU Poet, Nov 12)
Best value for most buyers; 27–32B
Used RTX 4090
24GB
$3,133 eBay low avg (GPU Poet, Nov 12)
Same models, about 1.5x faster
RTX 5090
32GB
$1,999 list, out of stock (NVIDIA store, Nov 1)
Only if you need 32GB
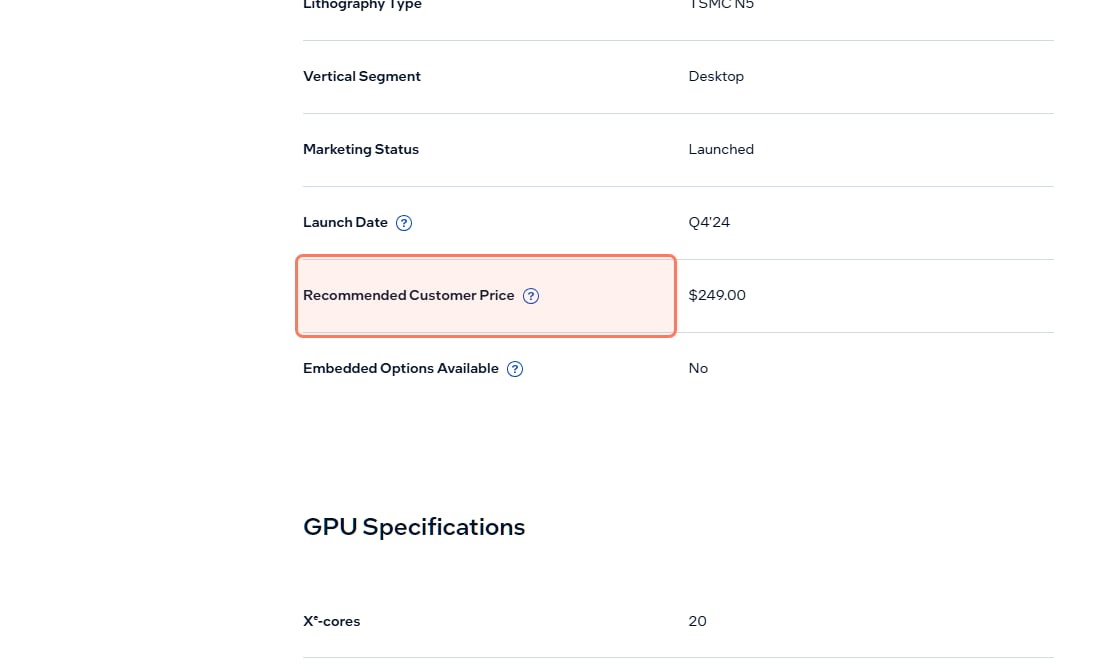
Around $350, models up to 14B: a used RTX 3060 12GB is the safe CUDA pick at about $337 on eBay (GPU Poet, Nov 12, 2026). Intel's Arc B580 has the same 12GB and a $249 recommended price on Intel's own spec page, but it's good value only near that price: the only in-stock B580 in Newegg's search on Nov 1, 2026 was $699.
Intel's own spec page for the Arc B580 (12 GB GDDR6): Recommended Customer Price $249.00. Read November 3, 2026. · Screenshot of intel.com by aliteq
$850–$1,300, a new 16GB card: the RTX 5060 Ti 16GB ($869.99 and up) and RTX 5070 Ti ($1,299.99 and up) on NVIDIA's store on Nov 1 run 14B models with long context. A used 24GB card costs more again (about $1,543 for a 3090 on Nov 12) but runs a whole size class more, so price both before you decide.
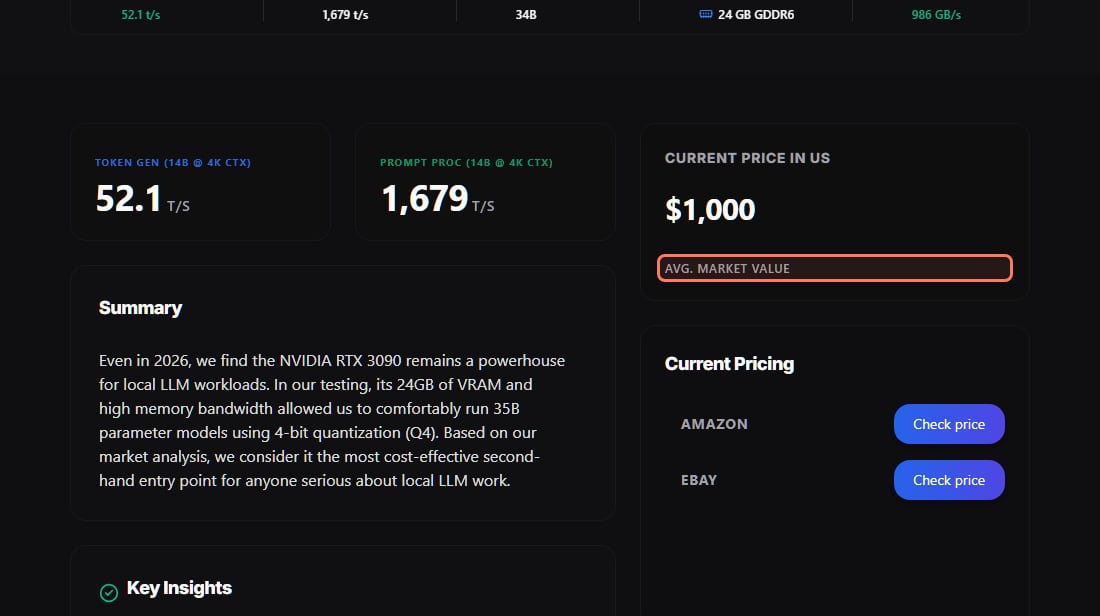
About $1,550, the sweet spot for 24GB: a used RTX 3090. Its 24GB holds 27–32B models at Q4, and hardware-corner.net's 3090 benchmark page gives 52.1 tokens a second generating on a 14B model at 4-bit (Qwen3 14B; the page labels that figure 4K context in one place and 16K in another, and its table lists 70 t/s at 4K). Check the card's condition before you pay; our used RTX 3090 buying guide has the checks.
hardware-corner.net's RTX 3090 page: $1,000 average market value in the US (no date on the figure; the page says its benchmarks were updated March 2026). Read November 3, 2026. On Nov 12, 2026 eBay listings were far higher: GPU Poet's lowest average was $1,543. · Screenshot of hardware-corner.net by aliteq
Cost per GB of VRAM (lower is better), from the prices in the table above
RTX 5060 Ti 16GB~$54/GB
$869.99 ÷ 16GB (NVIDIA store, Nov 1)
RTX 5090 at list price~$62/GB
$1,999 ÷ 32GB, if you can find one
Used RTX 3090 (24GB)~$64/GB
$1,543 ÷ 24GB (GPU Poet eBay low average, Nov 12)
Used RTX 4090 (24GB)~$131/GB
$3,133 ÷ 24GB (GPU Poet eBay low average, Nov 12)
Should I buy a used RTX 3090 or an RTX 4090?
The 3090, unless you need the speed. Both have 24GB, so they run exactly the same models. The difference is speed: hardware-corner.net's relative index puts the 4090 at 151% of the 3090 for token generation, about 1.5x. At $3,133 against $1,543 (GPU Poet's lowest eBay averages, Nov 12, 2026), you pay about twice as much for that. If the gap between the two on the day you buy is much smaller, the 4090 gets more interesting. The full comparison is in RTX 4090 vs RTX 3090 for local AI.
Is the RTX 5090 worth it, and can you buy one?
Only if you need 32GB and find one near list. The RTX 5090 is the only consumer card with 32GB, which buys you the 30–35B class at very long context. It's worth it near its $1,999 list price, but on Nov 1, 2026 NVIDIA's US marketplace showed the Founders Edition at $1,999 and out of stock, with the RTX 5080 and 5070 Founders Editions out of stock too. NVIDIA's GeForce chief Jeff Fisher said in October that production has not been discontinued (PC Gamer, Oct 19, 2026); the January end-of-production dates circulating online are leaks. The full case is in is the RTX 5090 worth it for local AI.
Do I need 64GB of system RAM for local AI?
If you want big mixture-of-experts (MoE) models, yes. MoE models only use a fraction of their weights for each token. Offloading engines keep those active parts on the GPU and the rest in system RAM, so a 24GB card with 64GB of RAM can run models far bigger than 24GB. llama.cpp's MoE offload does this, and newer engines such as Strata, an open-source project started in September 2026, are built around it. One r/ollama user reported about 100 tokens/sec on a 125B MoE with a 3090 and 64GB of RAM; that's one person's report, not our test. If you're buying a 24GB card for big MoE models, budget for the RAM too: see how much RAM you need for local AI.
Should I rent a GPU instead of buying one?
If you'd use it a few hours a week, yes. When our tracker read prices at 12:20 UTC on Nov 3, 2026, a single 24GB RTX 3090 rented on Vast.ai from $0.09 an hour on-demand and a 32GB RTX 5090 from $0.46 an hour; on Runpod the same cards were $0.50 and $1.19 an hour. At $0.09 an hour, the roughly $1,543 a used 3090 costs would rent one for thousands of hours, though you'd pay for storage too and the cheapest offers come and go. Our rent vs buy break-even does the maths, and /cloud-gpu shows today's prices. In one r/LocalLLM thread, a well-upvoted reply made the same point: a $20 cloud subscription is a low bar to clear before buying hardware.
What if I need more than 32GB?
A single gaming card is the wrong answer here. Three routes:
32GB without a 5090. AMD's Radeon AI PRO R9700 is a 32GB RDNA 4 card AMD pitches for local AI inference, and two of them came up often in a recent r/LocalLLM thread on what to buy for up to $5,000. Expect more setup than with CUDA.
Very large models in one box. Unified-memory machines share one big pool between CPU and GPU: an AMD Strix Halo box or an Apple Mac can hold models no gaming card can, at lower speed. We covered how much VRAM Strix Halo really gives you and Mac Studio vs an RTX Pro.
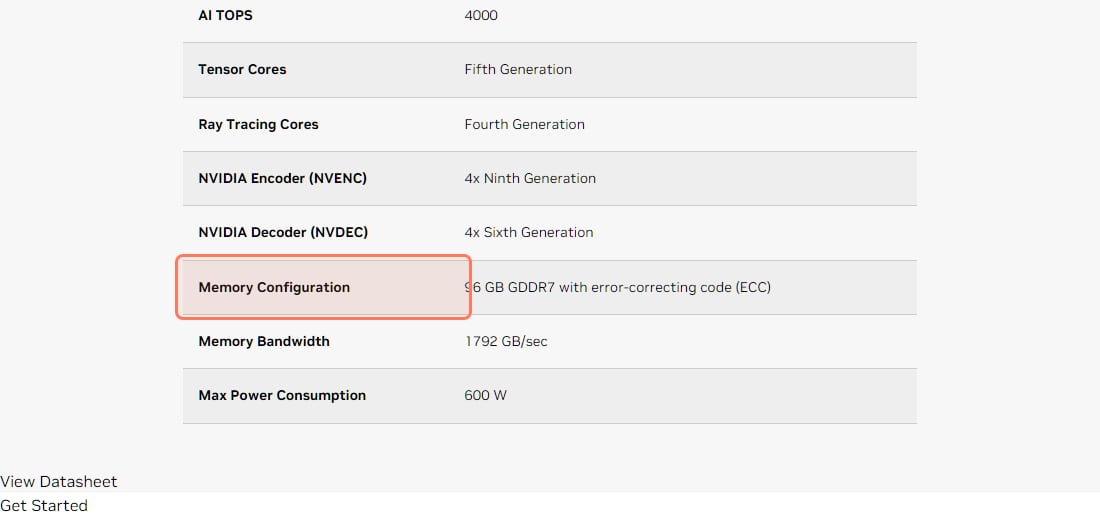
A workstation budget. NVIDIA's RTX PRO 6000 has 96GB of GDDR7 with ECC and a 600W maximum, per NVIDIA's page on Nov 3, 2026. NVIDIA doesn't list a price there. It was the top suggestion in an r/LocalLLaMA thread on a $10–12K agentic-coding build. To try one first, Runpod listed it at $2.49 an hour in our Nov 3 reading.
NVIDIA's own spec table for the RTX PRO 6000 Blackwell: 96 GB GDDR7 with ECC, 600 W. Read November 3, 2026. · Screenshot of nvidia.com by aliteq
Verdict
What we'd buy, November 2026
Size the VRAM to your model first. Up to 14B: a used RTX 3060 12GB, or an Arc B580 near its $249 list. 27–32B: a used RTX 3090, the best value for most buyers; a used 4090 only if the price gap is small or you need the speed. Add 64GB of system RAM for big MoE models. 32GB on one card: an RTX 5090 near $1,999 if one turns up, or an AMD R9700 if you'll accept more setup. Light or occasional use: rent by the hour instead of buying.
Best for: Anyone buying a GPU to run AI models at home
Common questions
What's the best GPU for local AI right now?
The one with enough VRAM for your model at the lowest price. For most buyers in November 2026 that's a used RTX 3090 with 24GB (a $1,543 lowest eBay average on GPU Poet, checked Nov 12, 2026), which runs 27–32B models at Q4. For 7–14B models, a used RTX 3060 12GB is enough. For 30–35B at long context, an RTX 5090 near its $1,999 list price, though it was out of stock on NVIDIA's US store on Nov 1, 2026. If you'd use it only occasionally, rent instead.
How much VRAM do I need to run local LLMs?
At Q4: 8GB for 7–8B models, 12–16GB for 14B, 24GB for 27–32B, 32GB for 30–35B at long context. A dense 70B needs about 40GB, more than any single consumer card. Large MoE models can run on 24GB plus 64GB of system RAM with offloading. The VRAM calculator gives the figure for your exact model and context.
Is a used RTX 3090 still worth it for local AI?
Yes, for most people. It has the same 24GB as an RTX 4090, so it runs the same models, at about two-thirds of the 4090's generation speed in hardware-corner.net's index and about half its used price ($1,543 vs $3,133 lowest eBay averages on GPU Poet, checked Nov 12, 2026). Check the card's condition before you buy.
Is the RTX 5090 discontinued?
NVIDIA says no. Its GeForce senior vice president Jeff Fisher said in October that production has not been discontinued and NVIDIA will keep shipping, while admitting supply is constrained. Claimed January end-of-production dates come from leakers. On Nov 1, 2026 NVIDIA's US store listed the Founders Edition at $1,999, out of stock.
Is NVIDIA or AMD better for local AI?
NVIDIA's CUDA is what most local-AI tools target first, so it needs the least setup. AMD can give more VRAM for the money, including the 32GB Radeon AI PRO R9700, but expect more tinkering with ROCm. Smooth software: NVIDIA. Memory per dollar and you don't mind setup: AMD.
Is it cheaper to rent a GPU than to buy one?
For light use, yes. On Nov 3, 2026 a 24GB RTX 3090 rented on Vast.ai from $0.09 an hour and an RTX 5090 from $0.46 an hour. Buying starts to pay when you'd run the card many hours a week for a long time. Rental prices change hourly; aliteq.com/cloud-gpu shows the current ones.
Will GPU prices drop in 2027?
Nobody can tell you. Reddit has popular posts predicting cheap GPUs next year and equally upvoted replies saying memory contracts are sold out for years; neither side has shown evidence. If a card you need is near its list price, that's a fair price today. If not, rent by the hour while you wait.
Building the rest of the machine? See gaming laptop vs desktop for local AI if you're torn between portable and powerful, and check the VRAM calculator for your exact model and context before you buy anything.