Short answer: Qwen3.8 27B. On our VRAM numbers it fits a 24GB card at Q5_K_M with 32K of context, and Ollama's default download is 18 GB. Gemma 4 and Qwen3.6 MoE models are faster, gpt-oss-20b leaves the most room, and NVIDIA's 24GB Nemotron comes with a runtime catch.
Some links on this page are referral links: we may earn a commission, at no cost to you.
Share
The best model to run on a 24GB GPU like an RTX 3090 or 4090 is Qwen3.8 27B. On our VRAM engine it fits at Q5_K_M with 32K tokens of context in about 21.2 GB, and Ollama's default qwen3.8:27b download is 18 GB (Ollama's tag page, read Nov 6, 2026). Pick something else only for a reason: Gemma 4 26B-A4B or Qwen3.6 35B-A3B when you want faster replies, gpt-oss-20b when you want the most free memory, Gemma 4 31B for a bigger dense vision model. NVIDIA's Nemotron 3.5 Bolt 74B-A9B 24GB was built for this card size, but its documented runtime is a nightly vLLM build, so test it before you rely on it.
best overall
Qwen3.8 27B
Q5_K_M with 32K context, ~21.2 GB
3.8B active
Gemma 4 26B-A4B
Q6_K at 8K, ~20.6 GB
most headroom
gpt-oss-20b
14 GB Ollama download
vision
Gemma 4 31B
Q4_K_M at 8K, ~19.1 GB
What fits a 24GB GPU, model by model?
Six models fit fully on one 24GB card. The first two columns are our VRAM engine's estimates (weights plus KV cache plus runtime overhead); the last is the size of Ollama's own download, which is the weights alone.
Qwen3.8 27B
Fits at 8K context
Q6_K, ~22.5 GB (tight)
Fits at 32K context
Q5_K_M, ~21.2 GB
Ollama download (read Nov 6, 2026)
qwen3.8:27b, 18 GB
Gemma 4 26B-A4B (MoE)
Fits at 8K context
Q6_K, ~20.6 GB
Fits at 32K context
Q6_K, ~21.1 GB
Ollama download (read Nov 6, 2026)
gemma4:26b-a4b-it-q4_K_M, 18 GB
Qwen3.6 35B-A3B (MoE)
Fits at 8K context
Q4_K_M, ~21.2 GB
Fits at 32K context
Q4_K_M, ~21.7 GB (tight)
Ollama download (read Nov 6, 2026)
qwen3.6:35b-a3b-q4_K_M, 24 GB
Gemma 4 31B
Fits at 8K context
Q4_K_M, ~19.1 GB
Fits at 32K context
Q4_K_M, ~20.9 GB
Ollama download (read Nov 6, 2026)
gemma4:31b-it-q4_K_M, 20 GB
gpt-oss-20b
Fits at 8K context
MXFP4 (native)
Fits at 32K context
MXFP4 (native)
Ollama download (read Nov 6, 2026)
gpt-oss:20b, 14 GB
Nemotron 3 Nano 30B-A3B (MoE)
Fits at 8K context
Q5_K_M, ~21.7 GB (tight)
Fits at 32K context
Q5_K_M, ~21.8 GB (tight)
Ollama download (read Nov 6, 2026)
not checked
Fits at 8K context
Fits at 32K context
Ollama download (read Nov 6, 2026)
Qwen3.8 27B
Q6_K, ~22.5 GB (tight)
Q5_K_M, ~21.2 GB
qwen3.8:27b, 18 GB
Gemma 4 26B-A4B (MoE)
Q6_K, ~20.6 GB
Q6_K, ~21.1 GB
gemma4:26b-a4b-it-q4_K_M, 18 GB
Qwen3.6 35B-A3B (MoE)
Q4_K_M, ~21.2 GB
Q4_K_M, ~21.7 GB (tight)
qwen3.6:35b-a3b-q4_K_M, 24 GB
Gemma 4 31B
Q4_K_M, ~19.1 GB
Q4_K_M, ~20.9 GB
gemma4:31b-it-q4_K_M, 20 GB
gpt-oss-20b
MXFP4 (native)
MXFP4 (native)
gpt-oss:20b, 14 GB
Nemotron 3 Nano 30B-A3B (MoE)
Q5_K_M, ~21.7 GB (tight)
Q5_K_M, ~21.8 GB (tight)
not checked
"Tight" means more than 90% of the card is used, so a browser or desktop sharing the GPU can push it over. At 32K, Qwen3.8 27B technically fits at Q6_K too, but at about 24.0 GB there is no margin, so we list Q5_K_M. Qwen3.6 27B has the same layer layout and parameter count, so it fits exactly the same way. Check any other quant and context in our VRAM calculator. For smaller cards, see the 16GB guide or the full VRAM ladder.
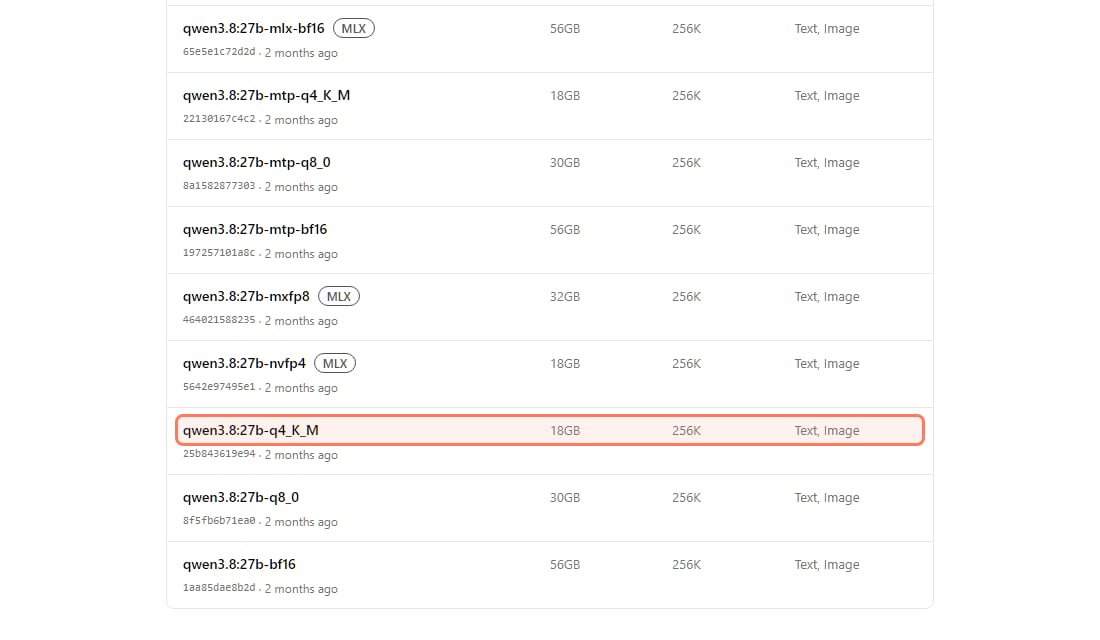
Ollama's qwen3.8 tags, read November 6, 2026. The q4_K_M build (18GB) is the one for a 24GB card; q8_0 (30GB) is not. · Screenshot of ollama.com by aliteq
Which model should I run for coding, fast chat, long documents or images?
Coding, agents and hard questions: Qwen3.8 27B. Per Qwen's model card it is a 27B model with 64 layers, a native vision encoder, a 262,144-token native context (extensible to 1,000,000) and an Apache-2.0 licence. It is dense, so every token reads all 27B weights: accurate rather than instant.
Fast everyday chat: Gemma 4 26B-A4B or Qwen3.6 35B-A3B. Both are mixture-of-experts models. Google's card lists 25.2B total and 3.8B active; Qwen's lists 35B total and 3B activated. Reading only 3B to 4B weights per token, they reply far faster than a dense 27B. On 24GB that's Q6_K for the Gemma and Q4_K_M for the Qwen.
Most free memory and long documents: gpt-oss-20b. OpenAI's card lists 21B parameters with 3.6B active, MXFP4 weights and says it runs within 16GB of memory. On a 24GB card that leaves the most room for context.
A bigger dense model for images: Gemma 4 31B (30.7B parameters, text and image input per Google's card). It fits at Q4_K_M with 8K context (about 19.1 GB) and 32K (about 20.9 GB) and goes tight past about 40K on our numbers.
Memory on a 24GB card, Q4_K_M with 32K context (our VRAM engine; gpt-oss = Ollama download)
gpt-oss-20b~14 GB
14 GB Ollama download, most headroom
Qwen3.8 27B~18.5 GB
comfortable on 24GB
Gemma 4 31B~20.9 GB
fits; tight past ~40K
Qwen3.6 35B-A3B~21.7 GB
tight; fast MoE
Why Qwen3.8 27B holds up at long context
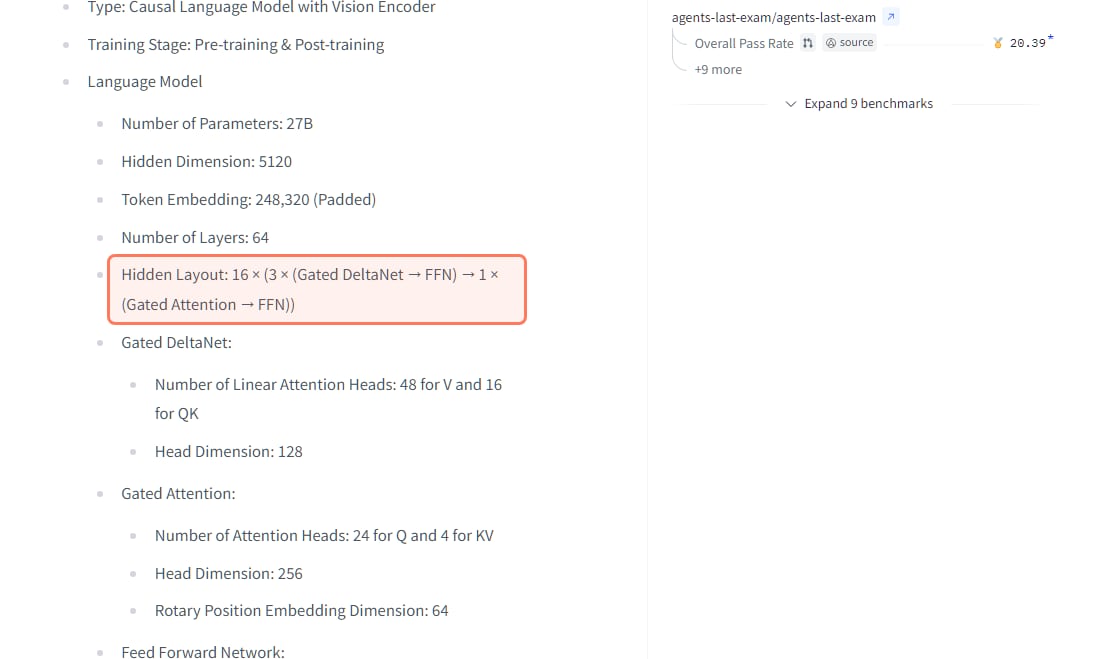
Only 16 of its 64 layers keep a growing KV cache. Qwen's card gives the layout as 16 repeats of three Gated DeltaNet (linear attention) layers and one Gated Attention layer, and linear-attention layers hold a small fixed state instead of a cache that grows with every token. That's why 32K of context costs it so little memory.
Qwen's own model card for Qwen3.8-27B (huggingface.co/Qwen/Qwen3.8-27B), read November 6, 2026. · Screenshot of huggingface.co by aliteq
Ollama's download sizes, read on November 6, 2026, tell you which tags to pull and which to skip. A download is the weights only; the context you set adds more on top.
ollama run qwen3.8:27b: the default tag is the q4_K_M build, 18 GB. Our first pick.
ollama run gemma4:26b-a4b-it-q4_K_M: 18 GB. Note that a bare gemma4 pulls the small e4b model (6.6 to 9.5 GB), not this one.
ollama run gemma4:31b-it-q4_K_M: 20 GB. Keep context modest.
ollama run gpt-oss:20b: 14 GB, the lightest of the four.
Careful with qwen3.6:35b-a3b: Ollama's q4_K_M build is a 24 GB download, the whole card before any context, so Ollama will put part of it in system RAM. It still runs, because it is a mixture-of-experts model, but slower than our 21.7 GB estimate suggests. A smaller GGUF quant in llama.cpp or LM Studio keeps it on the card.
Skip the q8_0 builds of these models on 24GB: Ollama lists qwen3.8:27b-q8_0 at 30 GB, gemma4:26b-a4b-it-q8_0 at 28 GB, gemma4:31b-it-q8_0 at 34 GB and qwen3.6:35b-a3b-q8_0 at 39 GB.
Can a 3090 or 4090 run NVIDIA's Nemotron 3.5 Bolt 24GB model?
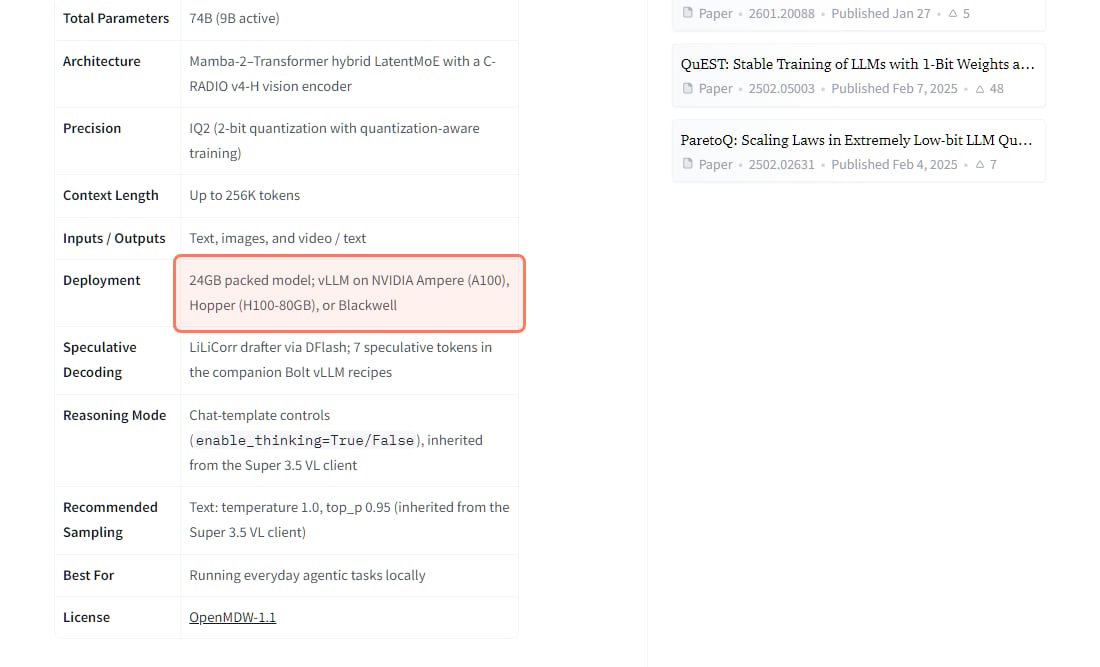
Maybe, but NVIDIA doesn't say so. Per its model card (read Nov 6, 2026), Nemotron 3.5 Bolt 74B-A9B 24GB is a vision-language model with 74B parameters and 9B active per token, compressed from Nemotron 3.5 Super VL 120B-A12B. It gets small with IQ2 weights ("2-bit quantization with quantization-aware training"), and the card says "The router’s architecture search targets a deployment footprint below 24 GB at batch size 1 and 128K context." It supports up to 256K tokens, was released on October 15, 2026 under the OpenMDW-1.1 licence, and the card says it is "ready for commercial or non‑commercial use."
NVIDIA's model card for Nemotron 3.5 Bolt 74B-A9B 24GB, read November 6, 2026. The deployment row names A100, H100 and Blackwell; no GeForce 3090 or 4090. · Screenshot of huggingface.co by aliteq
The catch is the runtime. The card's deployment row reads "24GB packed model; vLLM on NVIDIA Ampere (A100), Hopper (H100-80GB), or Blackwell", while its software section lists only "NVIDIA Blackwell SM120 & SM121", so the card contradicts itself. The quick start uses a nightly vLLM image plus extra kernel packages. Its test hardware includes the GeForce RTX 5090 but not the 3090 or 4090. NVIDIA also publishes a GGUF build, and the card doesn't say whether it works on older GeForce cards. Our VRAM engine doesn't model 2-bit IQ2 quants, so we have no number of our own. On a 3090 (Ampere, like the A100) or a 4090 (Ada, not named at all), treat it as an experiment, not your default.
Should I rent a 24GB GPU before I buy one?
If you don't own the card yet, an hour on a rented one answers "is this model good enough for me?" for very little. On November 6, 2026 at 21:20 UTC our price tracker read an RTX 3090 on Vast.ai from $0.10/hr on-demand (from $0.09/hr spot, which can be interrupted) and an RTX 4090 from $0.27/hr on-demand; Runpod listed the 3090 at $0.50/hr and the 4090 at $0.89/hr on-demand. Prices move hourly; today's, cheapest first, are on our cloud GPU page.
Does system RAM let a 24GB card run bigger models?
Yes, with mixture-of-experts models whose experts mostly sit in system RAM. Several Reddit threads we read on Nov 1, 2026 were about exactly this setup, and it is slower and less predictable than a model that fits on the card.
Qwen3.8 Flash Next. Its model card lists "125B with 6B activated, plus 51B n-gram embedding and 4B MTP" under the qwen-community-1.0 licence (read Nov 6, 2026). At Q4_K_M the whole model is about 102 GB on our numbers, far beyond any single GPU. When we read a r/ollama thread on Nov 1, a user with 24GB of VRAM and 64GB of RAM reported 80 to 100 tokens per second with Flash Next in the Strata engine, and another reply reported about 100 tokens per second on a 3090 with 64GB of DDR4. Single user reports, not benchmarks.
What Strata's docs say. Strata's model notes (read Nov 6, 2026) say "The model fits when RAM is at least the experts plus about 10 GB for the OS and other programs." The smallest original packs are listed at 37.6 GB (Q2_0) to 54.8 GB (IQ3_S) of RAM plus VRAM, so 64GB of RAM covers those; Unsloth's Q4-class downloads start at 94 GB and need more.
DeepSeek V4.1 Flash. Its model card lists 552B backbone parameters (763B in total on the Hub, MIT licence) with 8B active per token during prefill and 16B during decode. A r/LocalLLaMA user reported (read Nov 1) a Q2 build at 41 tokens per second on one 3090, and replies stressed that the machine had 192GB of RAM. On a normal 64GB desktop it doesn't fit.
Both sides, honestly:
The case for it.A popular r/LocalLLM thread argues 24GB to 32GB cards will age well because offloading engines let them run very large MoE models from RAM and NVMe. For a 3090 owner with 64GB of RAM, Flash Next is the biggest upgrade available without buying hardware.
The case against. The packs that fit 64GB are 2-bit to 3-bit, and whether they beat Qwen3.8 27B on the card is argued both ways. Strata is a young 0.x project; users reported greedy sampling by default (Qwen's Qwen3.8-27B card recommends temperature 1.0 in thinking mode and 0.7 otherwise) and breaking changes between versions. Anything read from RAM or SSD slows the model down.
Our take: keep Qwen3.8 27B fully on the card as the predictable default. If you have 64GB of RAM, try Flash Next with llama.cpp's MoE offloading first (how `--n-cpu-moe` works), then Strata if it is clearly faster on your machine. Pin the version and check the sampling settings. More on RAM sizing: how much RAM you need for local AI.
Is a 3090 or a 4090 better for local LLMs?
For what fits, neither: both have 24GB, so they load exactly the same models. The 4090 is the newer, faster card, so it generates more tokens per second; the 3090 is the cheaper way into 24GB, usually bought used (our used RTX 3090 buying guide). The one model this month where the generation might matter is Nemotron 3.5 Bolt, whose documented runtime targets data-centre and Blackwell GPUs.
Two things that quietly change your results
First, the context trap: a model advertising a 256K window will let you set context far beyond what your VRAM holds, which pushes the KV cache into system RAM and collapses the speed. Keep context to what your card holds; the VRAM calculator shows the limit. Second, your inference engine matters as much as your model. Ollama and LM Studio update often, and new architectures like Qwen3.8 need a current build, so update before blaming your card.
Quick answers
What is the best model to run on a 24GB GPU like a 3090 or 4090?
Qwen3.8 27B. On our VRAM engine it fits at Q5_K_M with 32K context in about 21.2 GB, and Ollama's default qwen3.8:27b download is 18 GB (read Nov 6, 2026). For faster replies use Gemma 4 26B-A4B or Qwen3.6 35B-A3B; for the most headroom, gpt-oss-20b.
What is the fastest good model on a 24GB card?
A mixture-of-experts model. Gemma 4 26B-A4B reads 3.8B parameters per token and Qwen3.6 35B-A3B reads 3B, per their model cards, so both reply much faster than the dense Qwen3.8 27B.
Can a 24GB card run Qwen3.8 27B at Q8?
Not fully on the card. Ollama lists qwen3.8:27b-q8_0 at 30 GB (read Nov 6, 2026), more than 24GB before any context. Use the q4_K_M default, or Q5_K_M with 32K context.
Does Qwen3.8 27B need more VRAM than Qwen3.6 27B?
No. Both have 27B parameters and the same layout of 16 full-attention and 48 linear-attention layers, so they fit identically.
Can an RTX 3090 run NVIDIA's Nemotron 3.5 Bolt 24GB model?
Unclear. NVIDIA sized it for 24GB, but its card lists vLLM on A100, H100 or Blackwell, uses a nightly vLLM build, and doesn't mention the 3090 or 4090. A GGUF build exists. Test before you rely on it.
Is a 3090 or a 4090 better for local AI?
They fit the same models because both have 24GB. The 4090 is faster; the 3090 is the cheaper way into 24GB.
Can a 24GB card run Qwen3.8 Flash Next?
With enough system RAM, at a low quant. Strata's docs say RAM must be at least the expert weights plus about 10 GB; its smallest packs are 37.6 to 54.8 GB, which 64GB of RAM covers. Speed depends heavily on your RAM.
The bottom line: on a 24GB 3090 or 4090, keep Qwen3.8 27B on the card for the hardest work, a Gemma 4 or Qwen3.6 MoE for fast chat, gpt-oss-20b when you need headroom and Gemma 4 31B for images. If you have 32GB to work with, our best local LLM for 32GB VRAM guide shows how an RTX 5090 runs these same models at higher quants with longer context.