Google, Meta, Mistral and OpenAI all ship open models that fit a gaming card, if you pick the right size and know each family's trap. Which one fits 8, 12, 16 and 24GB, the quant to use, the Ollama tag to type, and what changes on a Mac, from our VRAM engine and the model cards.
Some links on this page are referral links: we may earn a commission, at no cost to you.
Share
Which Gemma, Llama, Mistral or gpt-oss model fits your GPU? Pick by VRAM. On our VRAM engine at Q4_K_M with 16K context, an 8GB card runs Gemma 4 E4B (about 6 GB) or Llama 3.1 8B (about 7 GB), 12GB runs Gemma 4 12B (about 8 GB) or Phi-4 (about 12 GB, tight), 16GB runs gpt-oss-20b, which OpenAI says runs within 16GB, and 24GB runs Gemma 4 31B (about 20 GB), Mistral Small 24B or gpt-oss-20b with its full 128K context. Each family has one trap, mostly in Ollama's default tags, covered below.
Memory is our VRAM engine's estimate at Q4_K_M (gpt-oss at its own MXFP4) with 16K tokens of context, from each model's best-GPU page on Nov 17, 2026. For other quants and context lengths, run the VRAM calculator.
Gemma 4 E2B
Maker
Google
Memory at Q4_K_M, 16K
about 4 GB
Smallest card that fits
6 to 8GB
Ollama tag
gemma4:e2b
Llama 3.2 3B
Maker
Meta
Memory at Q4_K_M, 16K
about 4 GB
Smallest card that fits
6 to 8GB
Ollama tag
llama3.2:3b
Gemma 4 E4B
Maker
Google
Memory at Q4_K_M, 16K
about 6 GB
Smallest card that fits
8GB
Ollama tag
gemma4 (the default)
Llama 3.1 8B
Maker
Meta
Memory at Q4_K_M, 16K
about 7 GB
Smallest card that fits
8GB, tight
Ollama tag
llama3.1:8b
Gemma 4 12B
Maker
Google
Memory at Q4_K_M, 16K
about 8 GB
Smallest card that fits
12GB
Ollama tag
gemma4:12b
Gemma 3 12B
Maker
Google
Memory at Q4_K_M, 16K
about 9 GB
Smallest card that fits
12GB
Ollama tag
gemma3:12b
Phi-4 14B
Maker
Microsoft
Memory at Q4_K_M, 16K
about 12 GB
Smallest card that fits
12GB tight, 16GB comfortable
Ollama tag
phi4:14b
gpt-oss-20b
Maker
OpenAI
Memory at Q4_K_M, 16K
about 14 GB (MXFP4)
Smallest card that fits
16GB
Ollama tag
gpt-oss:20b (14 GB)
Gemma 4 26B-A4B
Maker
Google
Memory at Q4_K_M, 16K
about 16 GB
Smallest card that fits
24GB, or 16GB with Google's 14.4 GB QAT file
Ollama tag
gemma4:26b
Mistral Small 24B
Maker
Mistral
Memory at Q4_K_M, 16K
about 17 GB (a ~14 GB file)
Smallest card that fits
24GB, 16GB tight
Ollama tag
mistral-small
Gemma 3 27B
Maker
Google
Memory at Q4_K_M, 16K
about 18 GB
Smallest card that fits
24GB
Ollama tag
gemma3:27b
Gemma 4 31B
Maker
Google
Memory at Q4_K_M, 16K
about 20 GB
Smallest card that fits
24GB
Ollama tag
gemma4:31b
Maker
Memory at Q4_K_M, 16K
Smallest card that fits
Ollama tag
Gemma 4 E2B
Google
about 4 GB
6 to 8GB
gemma4:e2b
Llama 3.2 3B
Meta
about 4 GB
6 to 8GB
llama3.2:3b
Gemma 4 E4B
Google
about 6 GB
8GB
gemma4 (the default)
Llama 3.1 8B
Meta
about 7 GB
8GB, tight
llama3.1:8b
Gemma 4 12B
Google
about 8 GB
12GB
gemma4:12b
Gemma 3 12B
Google
about 9 GB
12GB
gemma3:12b
Phi-4 14B
Microsoft
about 12 GB
12GB tight, 16GB comfortable
phi4:14b
gpt-oss-20b
OpenAI
about 14 GB (MXFP4)
16GB
gpt-oss:20b (14 GB)
Gemma 4 26B-A4B
Google
about 16 GB
24GB, or 16GB with Google's 14.4 GB QAT file
gemma4:26b
Mistral Small 24B
Mistral
about 17 GB (a ~14 GB file)
24GB, 16GB tight
mistral-small
Gemma 3 27B
Google
about 18 GB
24GB
gemma3:27b
Gemma 4 31B
Google
about 20 GB
24GB
gemma4:31b
Llama's bigger models aren't on this list for a reason: Llama 3.3 70B needs about 46 GB and Llama 4 Scout about 63 GB, which is giant-model territory.
Which one should you run on your GPU?
8GB, Gemma 4 E4B or a small Llama
Gemma 4 E4B fits at Q6_K with 8K context in about 7.0 GB on our engine, with a little more room than the 8B-class models, and it's what Ollama's bare gemma4 tag pulls. Llama 3.1 8B needs about 7 GB at Q4_K_M with 16K context, so it fits but leaves little headroom. Gemma 3 4B is the lighter option and runs on 8GB laptops too. gpt-oss-20b doesn't fit 8GB on its own, but the llama.cpp guide shows about 42 tokens a second on an 8GB RTX 4060 Laptop GPU with --n-cpu-moe keeping part of the model in system RAM. More 8GB picks in the best local LLM for 8GB of VRAM.
12GB, Gemma 4 12B or Phi-4
Gemma 4 12B is the pick: about 7.7 GB at Q4_K_M with 8K context, and Q6_K with 32K context (about 10.4 GB) still fits a 12GB card like the RTX 3060 12GB. Its sliding-window layers keep long chats cheap. Phi-4 (Microsoft, MIT licence) needs about 12 GB at Q4_K_M, a tight fit, and it shows its late-2024 age with a 16K context. Mistral Nemo 12B, run as ollama run mistral-nemo, is the Mistral option for this tier. See the best local LLM for 12GB.
16GB, gpt-oss-20b
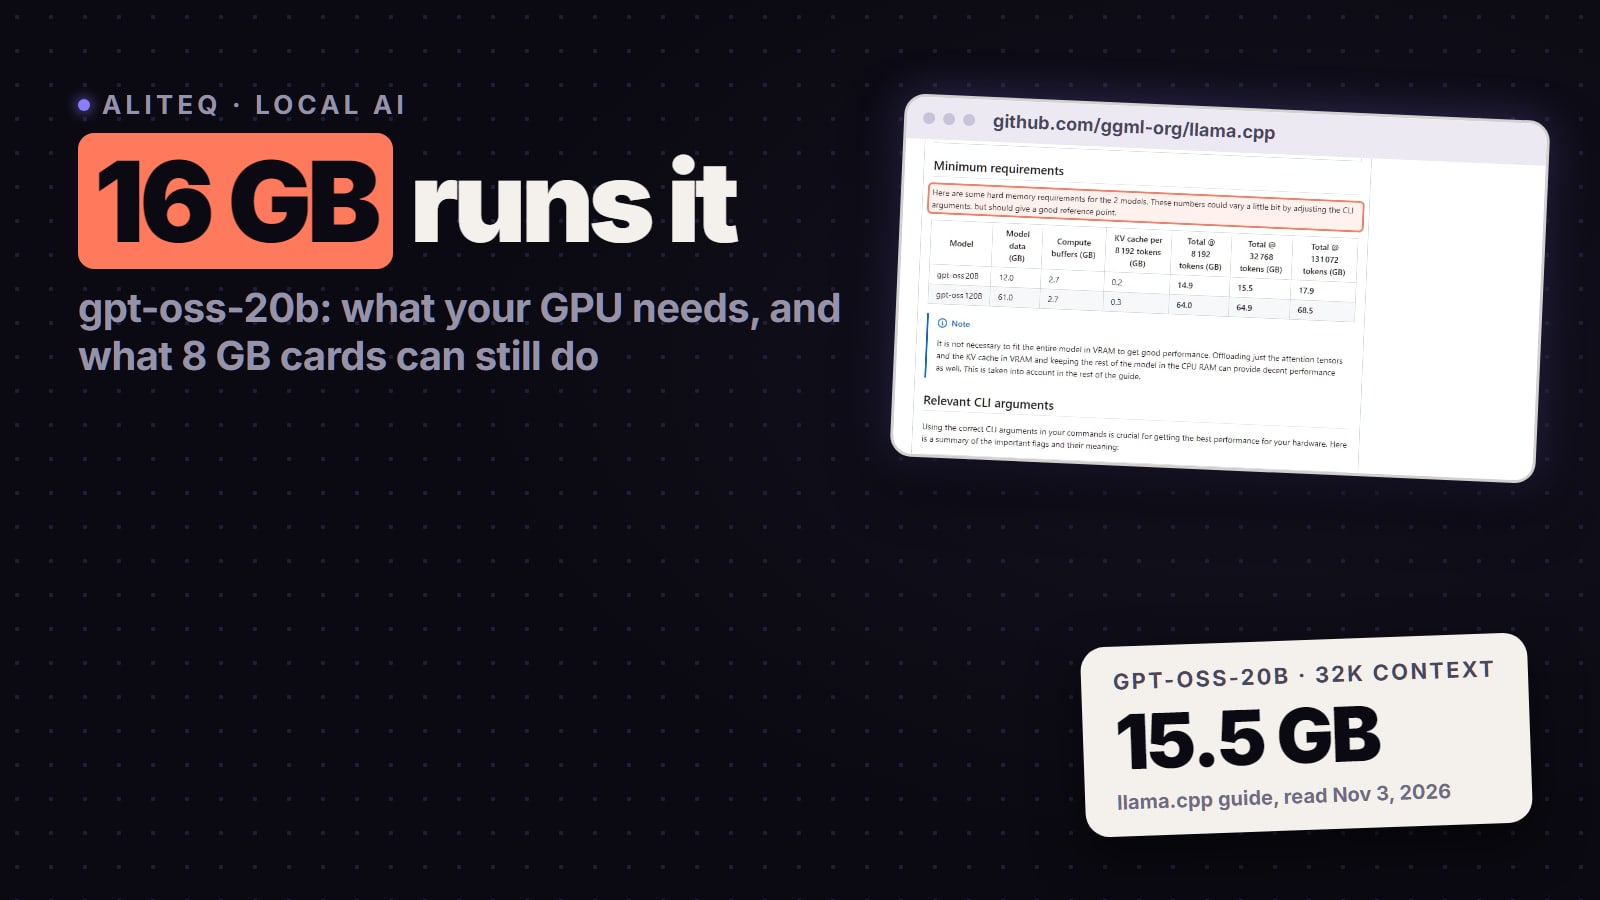
This is the tier gpt-oss-20b was made for. OpenAI's model card says MXFP4 makes it "run within 16GB of memory", and the llama.cpp guide lists 14.9 GB at 8K context, 15.5 GB at 32K and 17.9 GB at the full 128K. Ollama's gpt-oss:20b is a 14 GB download. It ships in OpenAI's own 4-bit format, so there's no point hunting for an 8-bit build. On an RTX 5060 Ti 16GB the alternatives are Gemma 4 12B at Q8_0 (about 12.7 GB) or Gemma 4 26B-A4B using Google's 14.4 GB QAT Q4_0 file. See can you run gpt-oss-20b on your GPU and the best local LLM for 16GB.
24GB, Gemma 4 31B, Gemma 4 26B-A4B or Mistral Small 24B
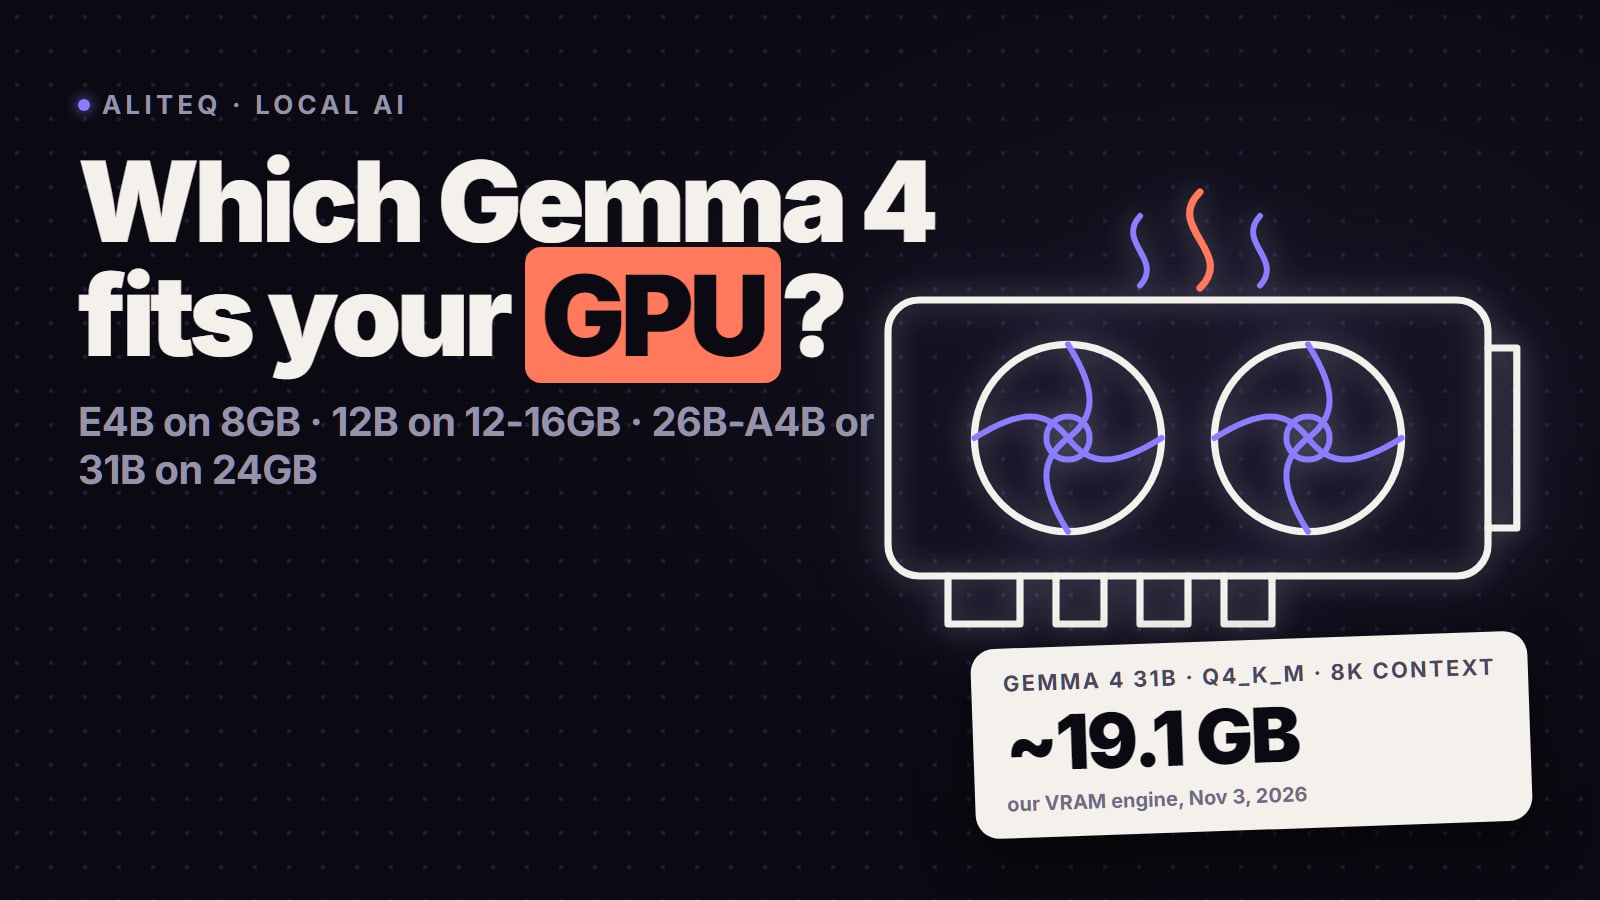
Gemma 4 31B at Q4_K_M, about 19.1 GB with 8K context, the strongest Gemma that fits.
Gemma 4 26B-A4B at Q6_K, a mixture-of-experts model with about 3.8B active parameters, so it answers faster than the 31B.
Mistral Small 24B (v3.2), a dense 24B model with a ~14 GB Q4_K_M file. Community benchmarks compiled by Markaicode put an RTX 4090 at about 38 tokens a second in llama.cpp at Q4_K_M. Q8 needs about 25 GB, so it doesn't fit.
gpt-oss-20b with its full 128K context, 17.9 GB per the llama.cpp guide.
Gemma 3 27B, about 18 GB at Q4, if you're already set up on Gemma 3.
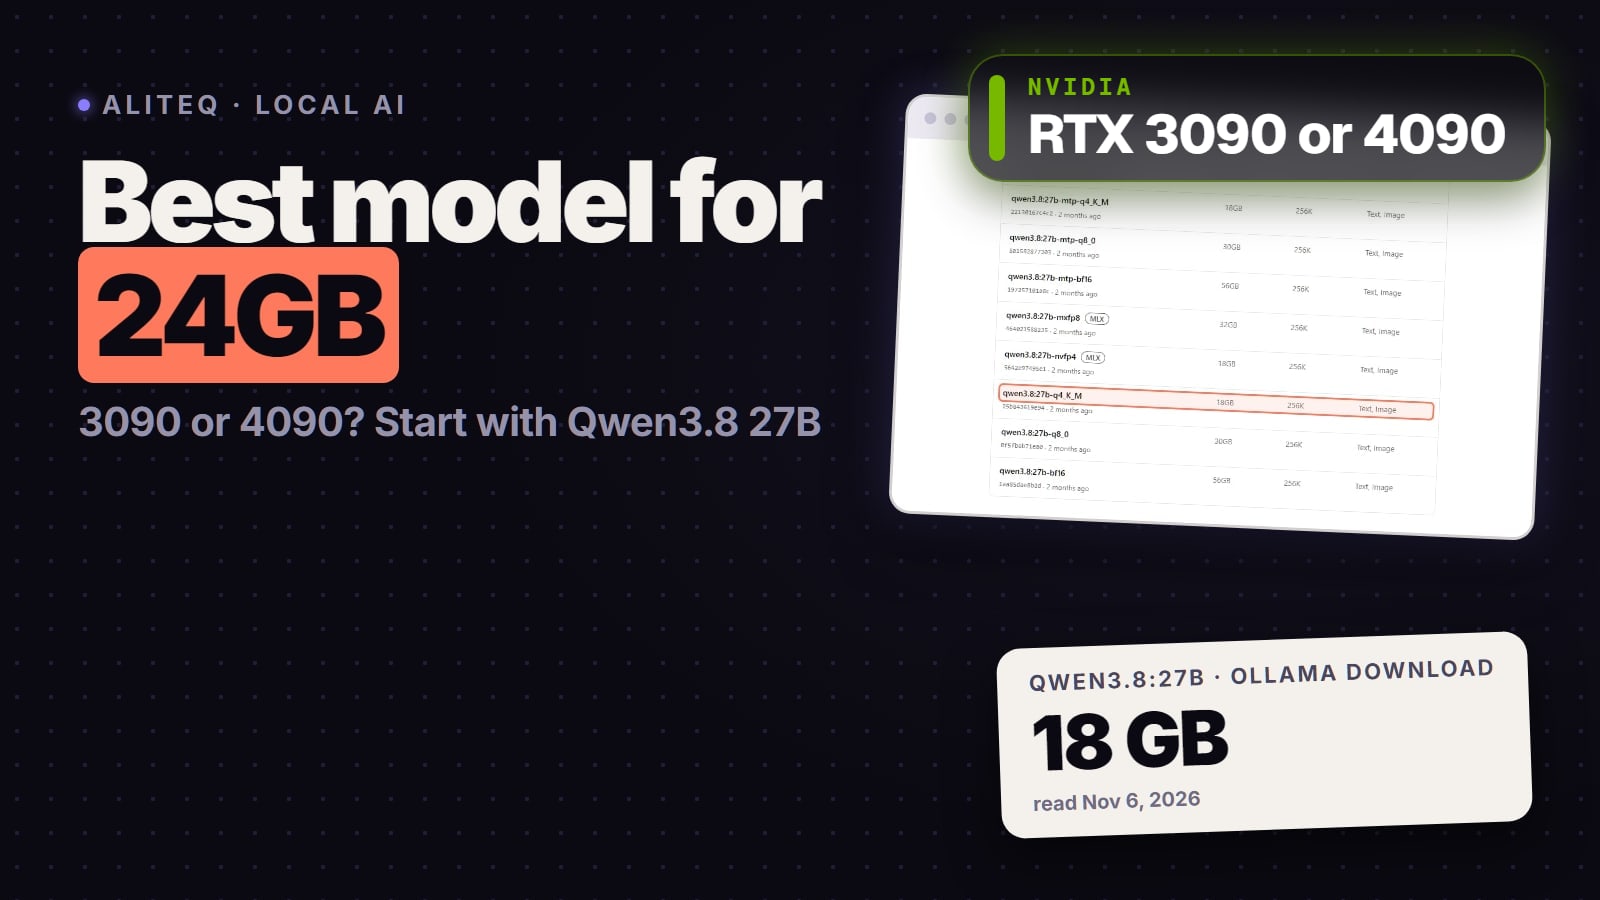
For text and code only, Qwen3.8 27B is the other strong 24GB choice; we compare all of them in the best model for a 24GB card.
On a Mac
A Mac's GPU shares one pool of memory with macOS. The llama.cpp guide says gpt-oss-20b "can run efficiently on Macs with at least 16GB RAM", but a 16GB Mac needs --n-cpu-moe 12 and leaves only 1 to 2 GiB for everything else at 8K to 32K context. A 24GB Mac fits it fully. For the runtime, LM Studio is the app, Ollama the one-command option, mlx-lm the Python route and llama.cpp the one with every setting. See gpt-oss-20b on a 16GB Mac mini and MLX or llama.cpp on a Mac.
Each family's trap, and how to avoid it
Gemma 4 in Ollama. The bare gemma4 tag is the small E4B. Type gemma4:12b, gemma4:26b or gemma4:31b for the bigger ones. Audio input works only on E2B, E4B and 12B, and not through Ollama.
Short default context. Ollama's docs say cards under 24 GiB get a 4K context by default. For documents or code, raise it with /set parameter num_ctx 32768 inside a session, then check ollama ps.
gpt-oss quants. It ships in MXFP4, so smaller GGUF quants don't shrink it much. Fit it by context length instead.
Mistral sizes.ollama run mistral is the 7B, mistral-nemo the 12B and mistral-small the 24B. Several Mistral models are Apache 2.0, so commercial use is allowed. See how to run Mistral locally.
Phi-4's context. It's 16K and full attention, so long chats cost more memory than on newer models. See Phi-4 locally.
Should you rent a 24GB card first?
If you're on 8 to 16GB and wondering whether Gemma 4 31B or Mistral Small 24B is worth an upgrade, an hour on a rented 24GB card answers it. On our price feed (Nov 17, 2026) a 24GB RTX 3090 started at $0.12 an hour on Vast.ai and an RTX 4090 at $0.27; Runpod listed them at $0.50 and $0.89. Prices move hourly; today's are on our cloud GPU page, and rent vs buy shows when owning wins.
Gemma, Llama, Mistral and gpt-oss locally, quick answers
What is the best open model for a 16GB GPU?
gpt-oss-20b. OpenAI's card says it runs within 16GB of memory, the llama.cpp guide lists 15.5 GB at 32K context, and Ollama's gpt-oss:20b is a 14 GB download. Gemma 4 12B at Q8_0 is the dense alternative.
Which Gemma 4 size fits my GPU?
E4B on 8GB, 12B on 12GB at Q4 or 16GB at Q8, 26B-A4B on 24GB (16GB only with Google's 14.4 GB QAT file), and 31B on 24GB at Q4_K_M, about 19.1 GB with 8K context. All five sizes are Apache-2.0.
Can I run gpt-oss-20b on an 8GB GPU?
Yes, slower. llama.cpp's --n-cpu-moe setting keeps part of the model in system RAM; a community result in the llama.cpp guide shows about 42 tokens a second on an 8GB RTX 4060 Laptop GPU.
How much VRAM does Mistral Small 24B need?
Its Q4_K_M file is about 14 GB, and our engine puts it at about 17 GB with 16K context, so a 24GB card is the comfortable fit and 16GB is tight. Q8 needs about 25 GB.
Which Llama runs on an 8GB GPU?
Llama 3.1 8B at Q4_K_M, about 7 GB with 16K context on our engine, or Llama 3.2 3B at about 4 GB. Llama 3.3 70B and Llama 4 need 46 GB or more.
Why does Ollama give me the wrong Gemma or a short context?
The bare gemma4 tag pulls the small E4B, so name the size, for example gemma4:31b. And Ollama's docs say cards under 24 GiB get a 4K context by default; raise num_ctx for long documents or code.