Buy the Mac Studio for the fastest replies, the DGX Spark for CUDA, long prompts and image work, and a Strix Halo mini PC for the cheapest 128GB. Prices read Nov 3, 2026, what Tom's Hardware measured on all three, and who should rent before buying.
Some links on this page are referral links: we may earn a commission, at no cost to you.
Share
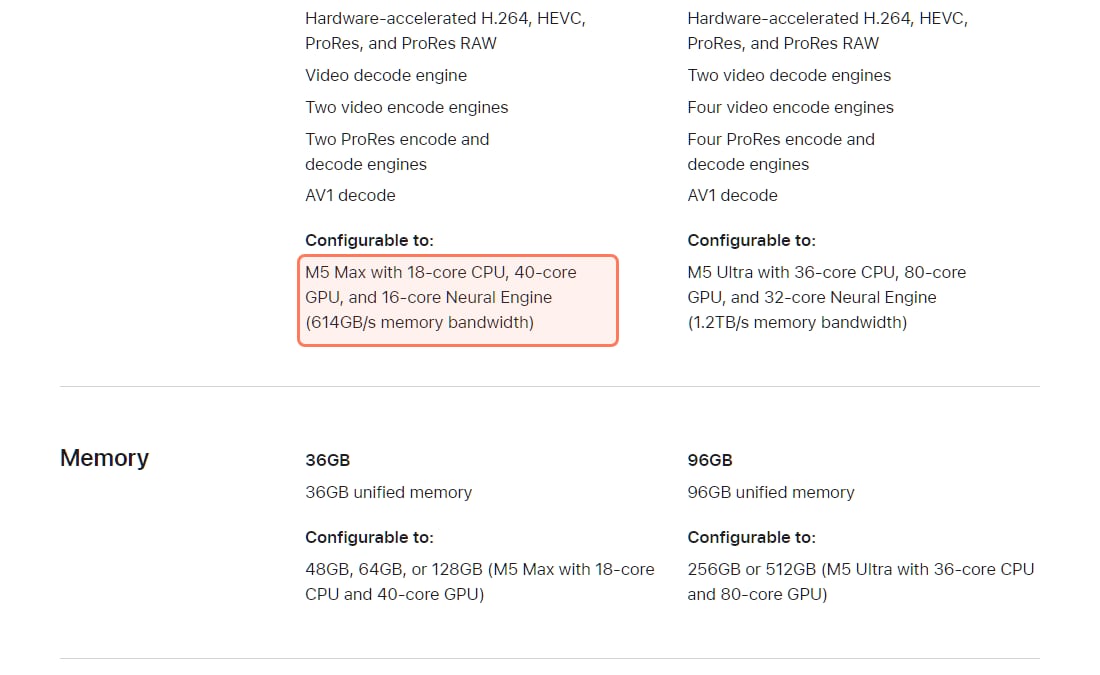
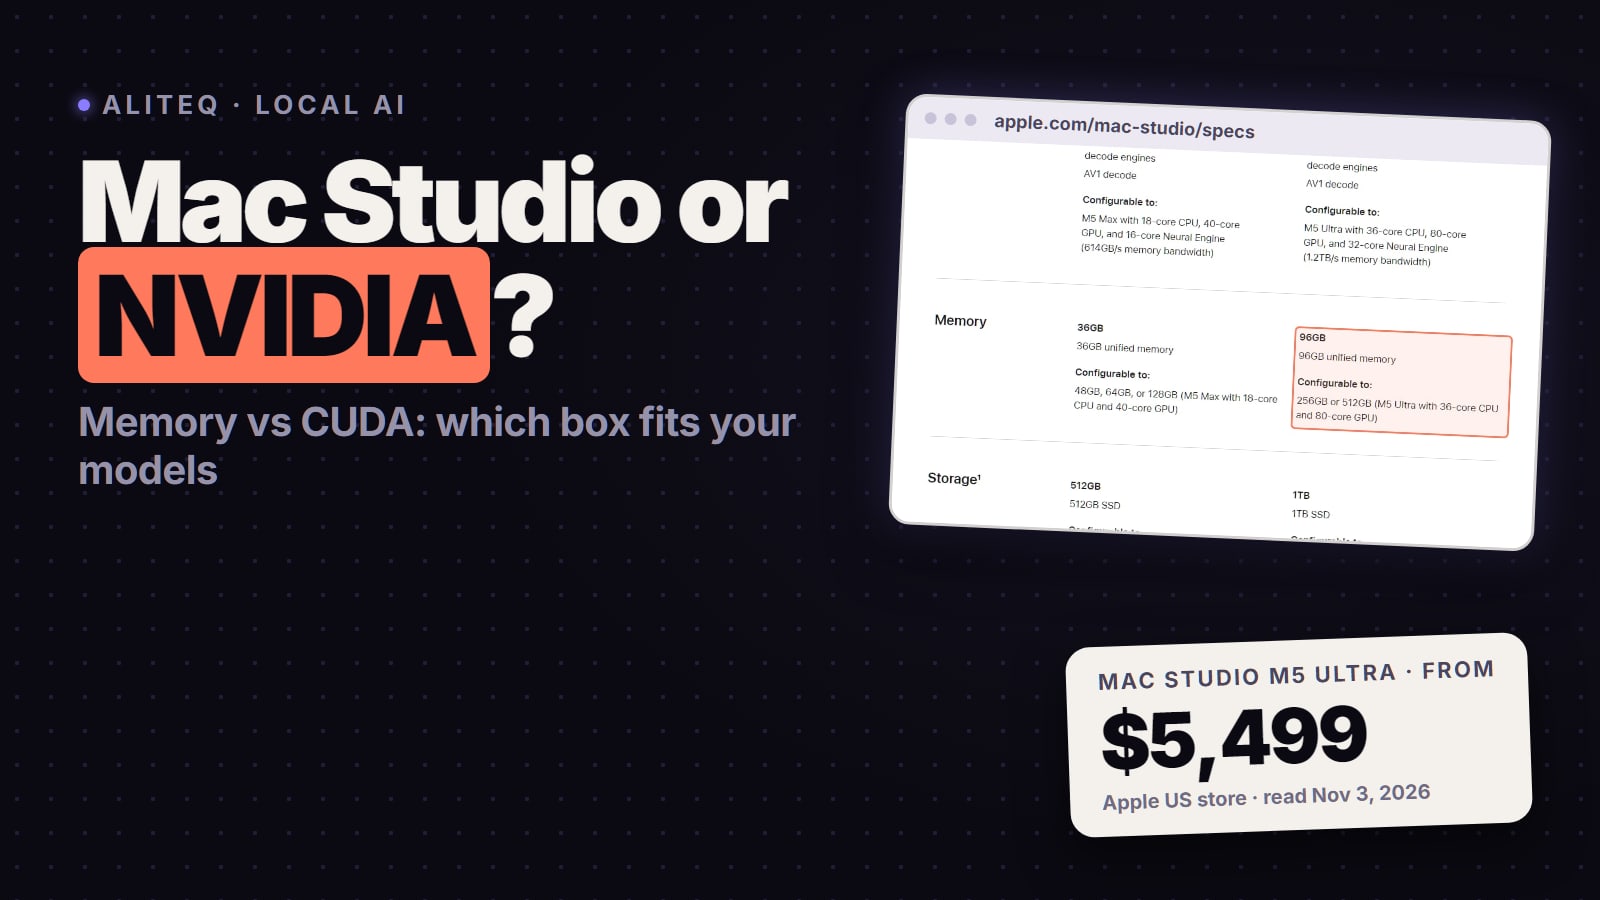
Short answer: buy the Mac Studio if you want the fastest replies from big local models, the DGX Spark if you need NVIDIA's CUDA stack, fast prompt processing or image and video generation, and a Strix Halo mini PC if you want 128GB of memory for the least money. The deciding number for reply speed is memory bandwidth: 614 GB/s on the 40-core M5 Max Mac Studio, 273 GB/s on the DGX Spark and 256 GB/s on Strix Halo, per Apple's, NVIDIA's and AMD's own spec pages read November 3, 2026.
Which one should you buy?
Pick by the job you'll give it most, not by one spec. Here's how the three split, from vendor specs and the benchmarks below.
Fast chat and coding replies from 30B to 120B models
Buy
Mac Studio, M5 Max 128GB
Why
614 GB/s, about 2.2x the Spark's bandwidth
CUDA, fine-tuning, agents with long prompts
Buy
DGX Spark 128GB
Why
Fastest prompt processing of the three in Tom's tests; same software as NVIDIA servers
Image and video generation (ComfyUI, Flux)
Buy
DGX Spark
Why
Tom's measured GB10 well ahead of the M4 Max; FP8 workflows failed on the Mac
The most memory per dollar, x86, Windows or games
Buy
Strix Halo mini PC, 128GB
Why
$3,449 (Framework DIY) to $3,499.99 (GMKtec sale), up to 96GB for the GPU
200B+ models, or 70B dense at chat speed
Buy
Mac Studio M5 Ultra
Why
1.2 TB/s and 256GB or 512GB options
A model that fits in 24 to 32GB
Buy
A GPU PC
Why
A desktop graphics card has several times this bandwidth; see the best GPU for local AI
Buy
Why
Fast chat and coding replies from 30B to 120B models
Mac Studio, M5 Max 128GB
614 GB/s, about 2.2x the Spark's bandwidth
CUDA, fine-tuning, agents with long prompts
DGX Spark 128GB
Fastest prompt processing of the three in Tom's tests; same software as NVIDIA servers
Image and video generation (ComfyUI, Flux)
DGX Spark
Tom's measured GB10 well ahead of the M4 Max; FP8 workflows failed on the Mac
The most memory per dollar, x86, Windows or games
Strix Halo mini PC, 128GB
$3,449 (Framework DIY) to $3,499.99 (GMKtec sale), up to 96GB for the GPU
200B+ models, or 70B dense at chat speed
Mac Studio M5 Ultra
1.2 TB/s and 256GB or 512GB options
A model that fits in 24 to 32GB
A GPU PC
A desktop graphics card has several times this bandwidth; see the best GPU for local AI
How much does each one cost?
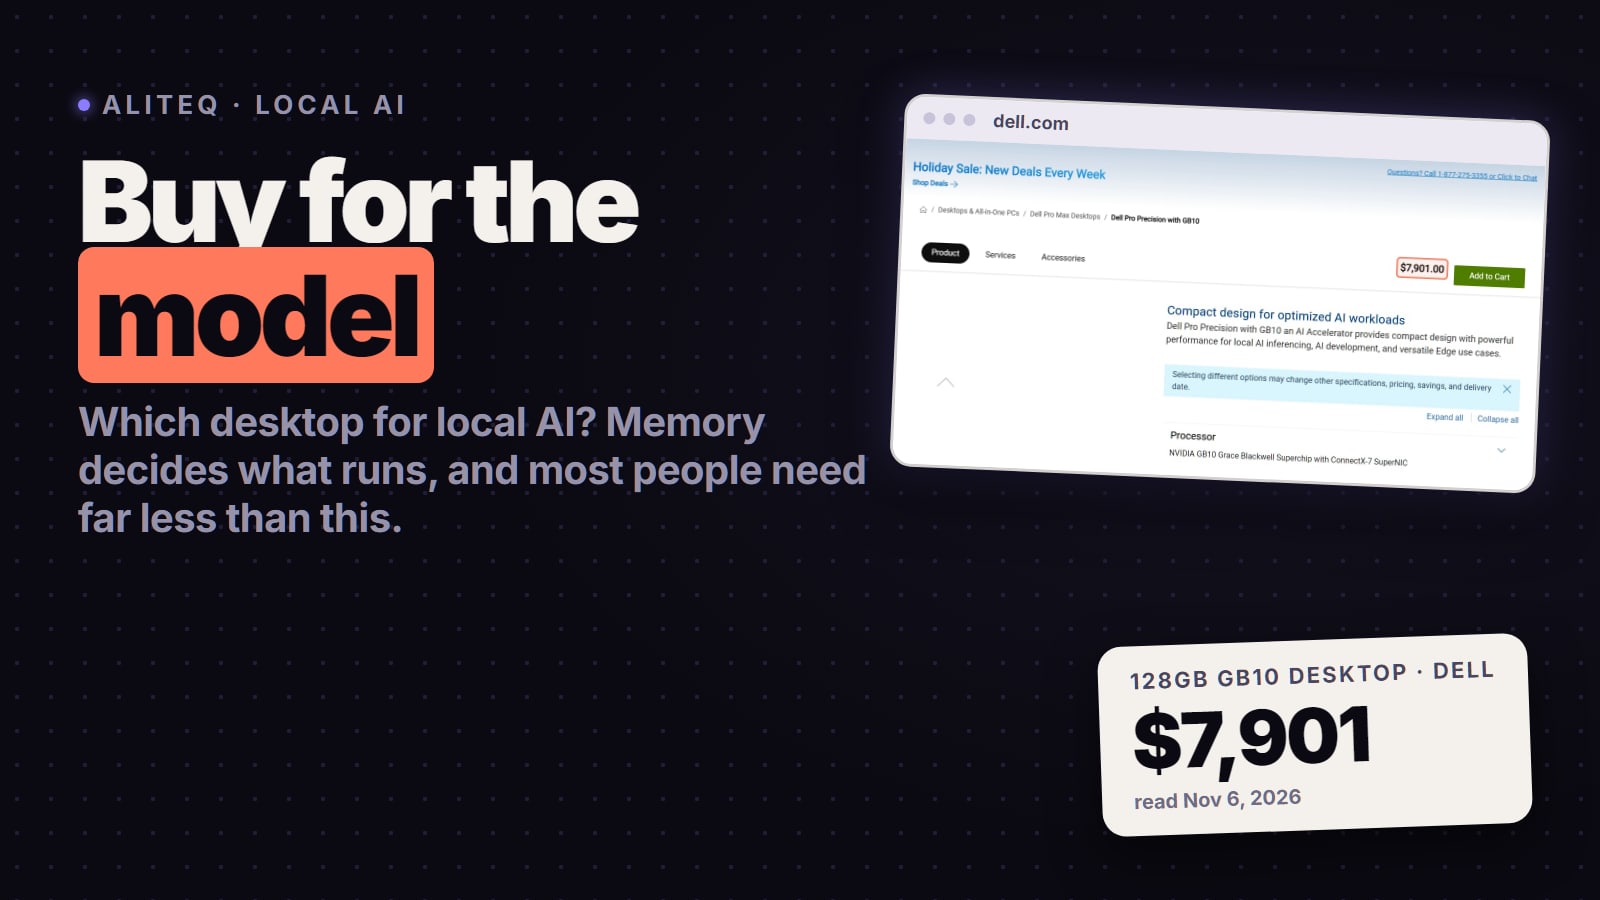
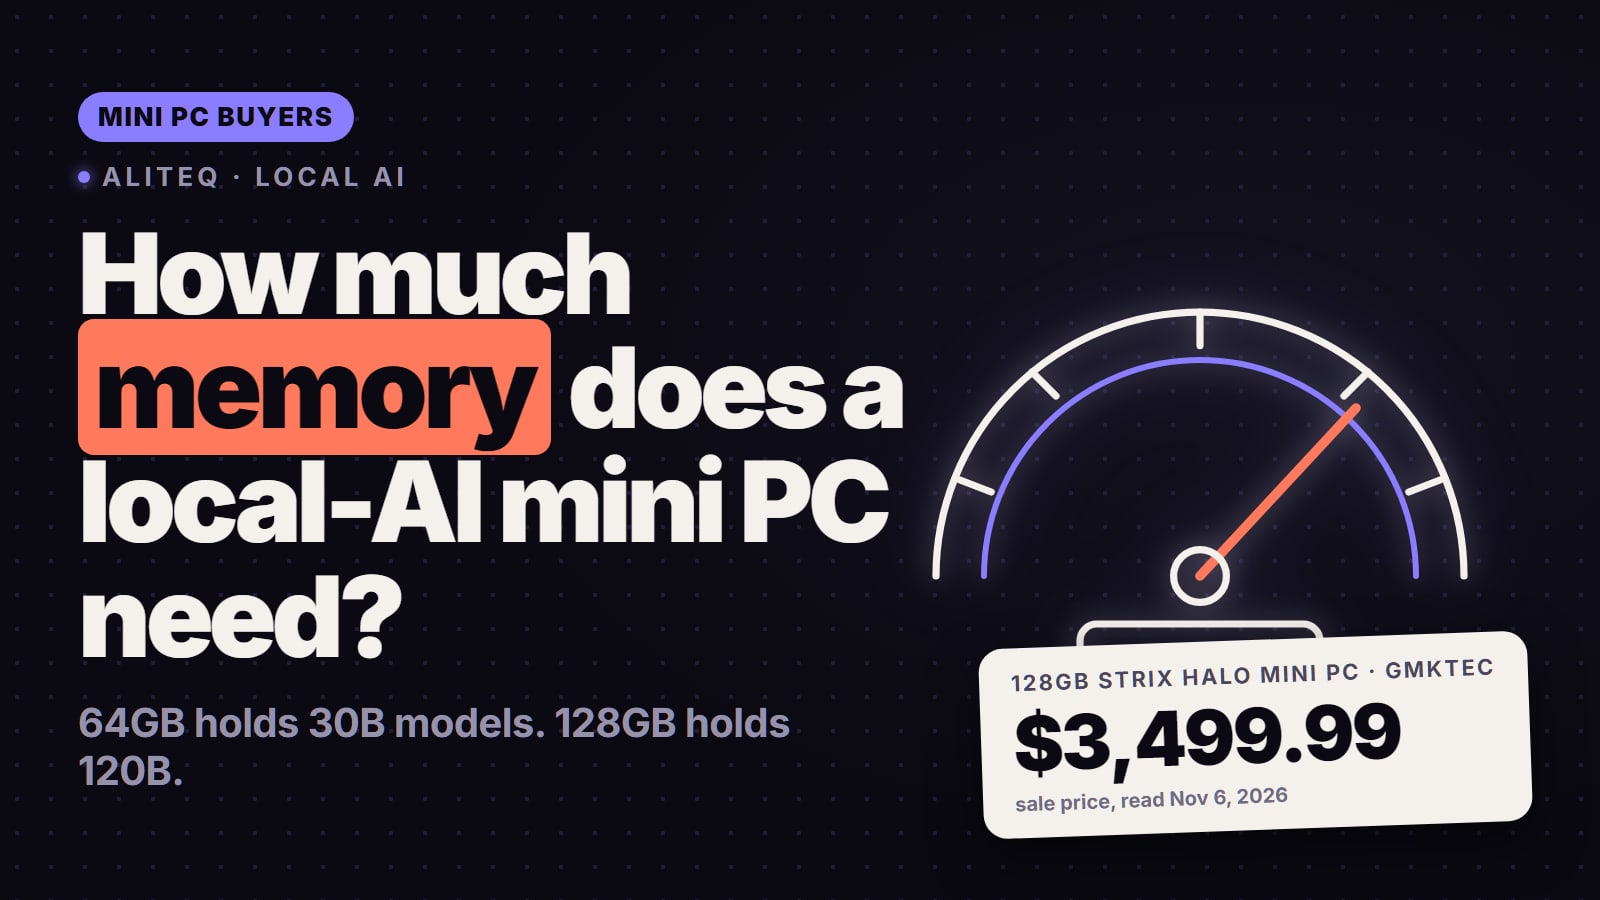
A 128GB Strix Halo box costs about $3,450 to $3,500, a 128GB DGX Spark about $4,700 to $7,000 depending on where you buy, and a 128GB Mac Studio $5,399. Memory prices have been moving all year, so each price below carries the date we read it.
Mac Studio, M5 Max 32-core GPU, 36GB
Price
$2,499
Where and when
Apple Store, read Nov 3, 2026 (entry model, 460 GB/s)
Mac Studio, M5 Max 40-core GPU, 64GB, 1TB
Price
$3,799
Where and when
Apple configurator, read Nov 3, 2026
Mac Studio, M5 Max 40-core GPU, 128GB, 1TB
Price
$5,399
Where and when
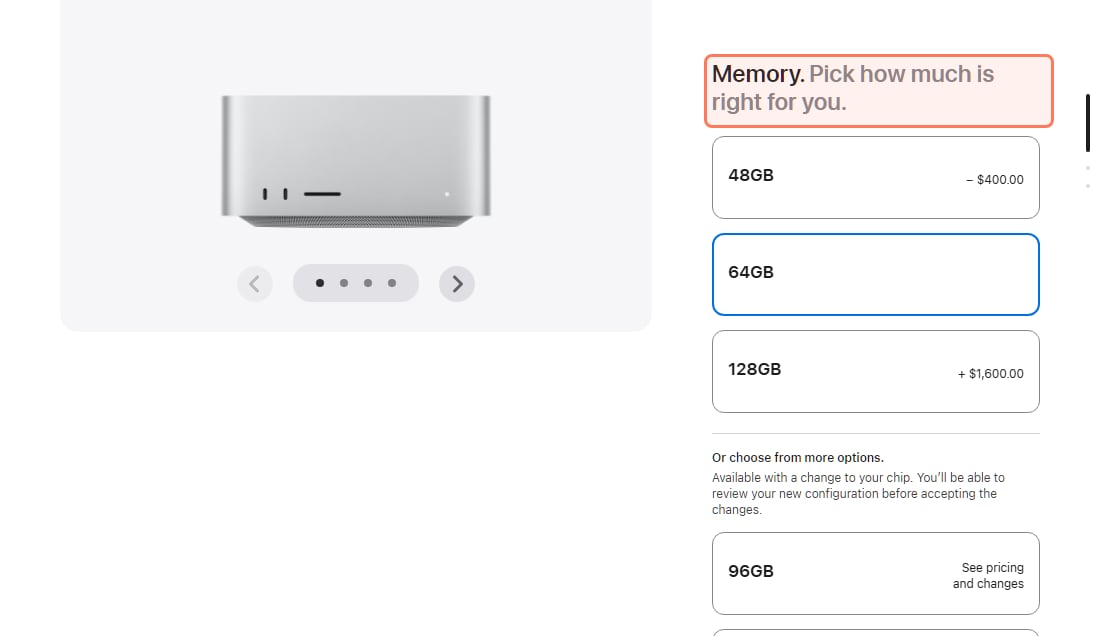
Apple configurator: $3,799 plus $1,600 for 128GB, read Nov 3, 2026
Mac Studio, M5 Ultra, 96GB, 1TB
Price
$5,499
Where and when
Apple Store, read Nov 3, 2026; 256GB adds $4,000, the 80-core chip adds $1,300; 512GB is offered only with the 80-core chip
DGX Spark 64GB (partner systems)
Price
from $4,999
Where and when
NVIDIA blog, on sale from Acer, ASUS, Dell, Gigabyte, HP and MSI since Oct 23, 2026
DGX Spark 128GB (Founders Edition)
Price
$4,699 MSRP; about $7,000 reported in October
Where and when
NVIDIA's last announced MSRP (Feb 25, 2026); HotHardware reported $6,995 on Oct 2, 2026
Framework Desktop DIY, Ryzen AI Max+ 395
Price
$3,449
Where and when
Framework configurator, read Nov 3, 2026; DIY price before storage and OS (64GB: $1,959)
GMKtec EVO-X2, Ryzen AI Max+ 395, 1TB
Price
$3,499.99 sale ($3,999.99 regular)
Where and when
GMKtec store, read Nov 3, 2026 (64GB: $2,199.99 sale)
Price
Where and when
Mac Studio, M5 Max 32-core GPU, 36GB
$2,499
Apple Store, read Nov 3, 2026 (entry model, 460 GB/s)
Mac Studio, M5 Max 40-core GPU, 64GB, 1TB
$3,799
Apple configurator, read Nov 3, 2026
Mac Studio, M5 Max 40-core GPU, 128GB, 1TB
$5,399
Apple configurator: $3,799 plus $1,600 for 128GB, read Nov 3, 2026
Mac Studio, M5 Ultra, 96GB, 1TB
$5,499
Apple Store, read Nov 3, 2026; 256GB adds $4,000, the 80-core chip adds $1,300; 512GB is offered only with the 80-core chip
DGX Spark 64GB (partner systems)
from $4,999
NVIDIA blog, on sale from Acer, ASUS, Dell, Gigabyte, HP and MSI since Oct 23, 2026
DGX Spark 128GB (Founders Edition)
$4,699 MSRP; about $7,000 reported in October
NVIDIA's last announced MSRP (Feb 25, 2026); HotHardware reported $6,995 on Oct 2, 2026
Framework Desktop DIY, Ryzen AI Max+ 395
$3,449
Framework configurator, read Nov 3, 2026; DIY price before storage and OS (64GB: $1,959)
GMKtec EVO-X2, Ryzen AI Max+ 395, 1TB
$3,499.99 sale ($3,999.99 regular)
GMKtec store, read Nov 3, 2026 (64GB: $2,199.99 sale)
Apple's configurator for the 40-core M5 Max Mac Studio ($3,799 with 64GB and 1TB): 128GB adds $1,600. Read November 3, 2026. · Screenshot of apple.com by aliteq
We could not load NVIDIA's own store on November 3, so we can't confirm today's 128GB Spark price there. The two dated figures we have point in different directions: NVIDIA's developer forum post of February 25, 2026 says the Founders Edition MSRP "has been adjusted from $3,999 to $4,699 due to memory supply constraints", and HotHardware reported on October 2 that the 128GB model's price "has increased significantly to $6,995". Check the price at checkout, and look at partner GB10 boxes (Dell Pro Max, ASUS Ascent GX10, HP ZGX Nano and others): it's the same chip.
Which one writes replies fastest?
The Mac Studio, by a wide margin. Writing a reply (decode) means reading the model's active weights from memory for every token, so speed follows memory bandwidth. Tom's Hardware put it plainly in its July 30 test: "the speed of the entire decode process basically becomes dependent on how fast those model weights can be streamed in from GPU memory."
Memory and bandwidth, from each maker's spec page (read Nov 3, 2026)
Mac Studio, M5 Ultra
Memory bandwidth
1.2 TB/s
Memory options
96GB, 256GB or 512GB
Mac Studio, M5 Max 40-core GPU
Memory bandwidth
614 GB/s
Memory options
48GB, 64GB or 128GB
Mac Studio, M5 Max 32-core GPU
Memory bandwidth
460 GB/s
Memory options
36GB
NVIDIA DGX Spark (GB10)
Memory bandwidth
273 GB/s
Memory options
64GB or 128GB LPDDR5X
AMD Ryzen AI Max+ 395 (Strix Halo)
Memory bandwidth
about 256 GB/s
Memory options
up to 128GB LPDDR5x-8000
Memory bandwidth
Memory options
Mac Studio, M5 Ultra
1.2 TB/s
96GB, 256GB or 512GB
Mac Studio, M5 Max 40-core GPU
614 GB/s
48GB, 64GB or 128GB
Mac Studio, M5 Max 32-core GPU
460 GB/s
36GB
NVIDIA DGX Spark (GB10)
273 GB/s
64GB or 128GB LPDDR5X
AMD Ryzen AI Max+ 395 (Strix Halo)
about 256 GB/s
up to 128GB LPDDR5x-8000
The Strix Halo figure is arithmetic: AMD lists 256-bit LPDDR5x-8000, which works out to 256 GB/s. Tom's Hardware also describes the M4 Max as having "double the memory bandwidth of GB10 and Strix Halo on paper". (An earlier version of this page said 273 GB/s for Strix Halo; that is GB10's number.)
Apple's Mac Studio spec page lists 614GB/s for the 40-core M5 Max and 1.2TB/s for the M5 Ultra. Read November 3, 2026. · Screenshot of apple.com by aliteq
What the three-way benchmark measured
Tom's Hardware tested a 128GB M4 Max Mac Studio (546 GB/s, the previous generation) against GB10 and Strix Halo systems with llama.cpp and four-bit Unsloth quantizations. The Mac generated more tokens per second than both at every context depth, but its lead varied a lot by model:
Tokens per second, Mac Studio M4 Max vs the GB10 system (GB10 = 1x)
Qwen 3.6-35B-A3B (MoE)about 1.25x
Tom's Hardware, Jul 30, 2026
gpt-oss-120b (MoE)about 1.5x
average across context depths
Gemma 4 12B (dense)about 1.8x
dense models track bandwidth best
Against Strix Halo, the same Mac was 2.26x faster on Gemma 4 12B and 1.6x faster on gpt-oss-120b. Tom's summed it up: "you might see the M4 Max generate as few as 27% more tokens per second or as many as 82% more TPS than an Nvidia GB10 box." Twice the bandwidth did not mean twice the speed on mixture-of-experts models, which read only part of their weights per token.
The current Mac Studio is faster still. In its September 21 review of the M5 Ultra Mac Studio, Tom's Hardware wrote: "The M5 Ultra's prompt processing speeds are even faster than Nvidia's DGX Spark's, and its tokens-per-second throughput is double that of the M4 Max and almost four times higher than the DGX Spark across the board." Nobody we found has published the same three-way test on the M5 Max yet; its 614 GB/s sits about 12% above the M4 Max's 546 GB/s, so expect it to lead the Spark by at least as much as the M4 Max did.
Which one reads long prompts fastest?
The DGX Spark. Reading your prompt (prefill) is compute-bound, not bandwidth-bound, and GB10 has the most GPU compute of the three. In Tom's tests the M4 Max landed "behind GB10, especially with longer contexts" on Qwen 3.6, and on Gemma 4 12B its prompt speed was "only in line with (or even slightly worse than) Strix Halo."
That matters for agents, coding tools and retrieval, where the prompt is long and the reply short. In Tom's fixed gpt-oss-120b job (a 2,048-token prompt on a 32,768-token context, then 1,024 output tokens), the GB10 finished faster and used less total energy than the Mac Studio, "even though it's outputting fewer tokens per second in the decode stage." The M5 Ultra changes this, per the quote above, but at $5,499 and up it's a different budget. Our DGX Spark review has llama.cpp's own prefill and decode numbers for the Spark.
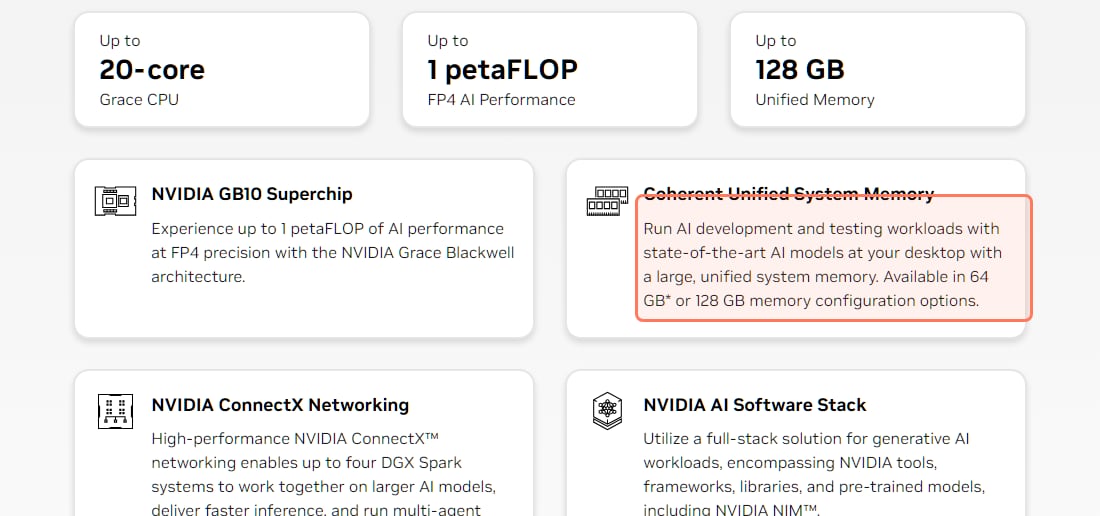
NVIDIA's DGX Spark page now offers 64 GB or 128 GB. The 1 petaFLOP figure is FP4 with sparsity, a prefill number; the spec table lists 273 GB/s. Read November 3, 2026. · Screenshot of nvidia.com by aliteq
Which one is best for image and video generation?
The DGX Spark. Diffusion models are bound by GPU compute, and Tom's measured the M4 Max taking longer than even Strix Halo's Radeon 8060S on its Flux.2 Klein test. The Mac's first run failed outright, from "an apparent lack of GPU support for the FP8 data type that the ComfyUI workflow uses by default," and only ran after switching to the FP16 model. Apple claims the M5 Max is "up to 3.8x faster" at image generation than the M4 Max, which Tom's quotes but couldn't test. If ComfyUI is your main use, CUDA is the safer bet today.
How big a model can each one run?
All three run 120B-class mixture-of-experts models at 4-bit in 128GB. Only the Mac Studio M5 Ultra goes past 128GB in one box.
DGX Spark: NVIDIA lists one 128GB unit for models up to 200B parameters and two linked over ConnectX-7 for up to 400B; its blog says the 64GB version "supports up to 100-billion-parameter models".
Strix Halo: on a 128GB Ryzen AI Max+ 395, AMD's Variable Graphics Memory gives the GPU up to 96GB, and AMD says the GPU "can technically access a total graphics memory size of 112GB". Details in our Strix Halo VRAM guide.
Mac Studio: M5 Max tops out at 128GB; M5 Ultra offers 96GB, 256GB or 512GB per Apple's spec page. macOS keeps some memory for itself, so don't plan on using every gigabyte for the model.
Check your exact model and quantization in our VRAM calculator before you buy; a 70B dense model at 4-bit fits on all three but generates slowly on the 256 to 273 GB/s machines. For gpt-oss-120b specifically, see the gpt-oss-120b hardware guide.
Should you rent one before you buy?
If you're on the fence about the Spark, yes: Vast lists GB10 machines by the hour. On November 3, 2026 at 20:20 UTC our price tracker read the cheapest single GB10 on Vast at $0.28 an hour on demand, so a few evenings of testing your own models costs a few dollars against a $4,999-plus purchase. Prices move hourly; our cloud GPU page has today's.
Apple Silicon and Strix Halo aren't rentable in the same way, so for those the published benchmarks above are what you have. Our rent vs buy guide works through when owning pays off.
What we did not test
We have not run these machines ourselves. Speeds here are Tom's Hardware's measurements (M4 Max, GB10 and Strix Halo in July 2026; M5 Ultra in September 2026), quoted word for word from their pages, and the M5 Max comparison is our inference from Apple's bandwidth figure, labeled as such. Prices are what each vendor's page showed on November 3, 2026, except the 128GB Spark, explained above. No referral fee depends on which machine you pick; the only referral link on this page is the Vast rental card.
Mac Studio vs DGX Spark vs Strix Halo, answered
Is the Mac Studio faster than the DGX Spark for local LLMs?
For generating replies, yes. Tom's Hardware measured an M4 Max Mac Studio at 27% to 82% more tokens per second than a GB10 box, and the current M5 Ultra at almost four times the Spark's throughput. The Spark is faster at reading long prompts than the M4 Max and better at image generation.
Is Strix Halo or the DGX Spark better for local AI?
Their bandwidth is close (about 256 vs 273 GB/s), so reply speeds are in the same range. The Spark has more GPU compute and CUDA, so it wins on prompt processing and image models. Strix Halo costs less (a 128GB Framework Desktop DIY was $3,449 and a 128GB GMKtec EVO-X2 $3,499.99 on sale on Nov 3, 2026), runs Windows and games, and gives the GPU up to 96GB.
What is the cheapest way to get 128GB for local AI?
A Strix Halo mini PC. On November 3, 2026, Framework's 128GB Desktop DIY Edition was $3,449 before storage and OS, and GMKtec showed its 128GB EVO-X2 at $3,499.99 on sale ($3,999.99 regular). A 128GB M5 Max Mac Studio is $5,399.
Is the 64GB DGX Spark worth it?
Only for models under about 100B parameters, which is NVIDIA's own limit for it. It starts at $4,999 from partners, more than a 128GB Strix Halo box. If you need CUDA on a budget it's an option; for memory per dollar it isn't.
Does more memory bandwidth always mean faster local AI?
For writing replies it's the biggest factor, but not a straight line. The M4 Max had double GB10's bandwidth and was only about 25% faster on Qwen 3.6-35B-A3B, against 1.8x faster on the dense Gemma 4 12B. Mixture-of-experts models gain less from bandwidth.
What is NVIDIA GB10?
The Grace Blackwell chip inside the DGX Spark and partner boxes such as the Dell Pro Max with GB10, ASUS Ascent GX10 and HP ZGX Nano. NVIDIA lists up to 1 petaFLOP of FP4 compute (with sparsity), up to 128GB of LPDDR5X and 273 GB/s.
The simple rule: if you'll mostly chat with or code against a big model, the Mac Studio's bandwidth wins. If you'll feed it long prompts, run image models or need CUDA, the Spark is the better tool. If you want the most memory for the least money and can live with slower replies, buy Strix Halo. We'll update this page when a three-way test of the M5 Max or the new Ryzen AI Max+ PRO 495 (Framework lists a 192GB version at $6,799 on pre-order, shipping in December) is published.