One 48 GB card holds Llama 3.3 70B at Q4_K_M (a 42.5 GB file), and on Nov 3, 2026 the cheapest was an RTX A6000 on Vast from about $0.35 an hour on-demand, or an A40 or RTX A6000 on Runpod at $0.59. When you need an 80 GB card instead, what an evening really costs, and when a per-token API is cheaper than any GPU.
Some links on this page are referral links: we may earn a commission, at no cost to you.
Share
Rent one 48 GB GPU. Llama 3.3 70B at Q4_K_M is a 42.52 GB file, so a single RTX A6000 or A40 holds it with about 8K tokens of context. On Nov 3, 2026 the cheapest RTX A6000 on Vast rented from about $0.35 an hour on-demand, and Runpod charged $0.59 an hour for an A40 or RTX A6000. An evening of four hours is about $1.40 on Vast or $2.36 on Runpod, plus storage. You need an 80 GB card (an A100, from $0.87 an hour on Vast and $1.79 on Runpod that day) only for long context or 8-bit weights.
Which GPU do I need to run Llama 70B in the cloud?
One card with at least 48 GB of VRAM, for the usual 4-bit file. The model is 70.6 billion parameters (70,553,706,496 on Meta's Hugging Face page), and its size on the GPU depends on the quantization you load. Here are the real file sizes from the most-downloaded GGUF set and the card each one needs once you add room for the chat.
Llama 3.3 70B: file size, card, and the cheapest price that day (read Nov 3, 2026, 20:20 UTC)
IQ4_XS (4-bit, smaller)
Weights
37.90 GB
Card it needs
48 GB, or a 45 GB Vast listing
Vast on-demand
from $0.35/hr (RTX A6000)
Runpod Secure Cloud
$0.59/hr (A40 or RTX A6000)
Q4_K_M (4-bit, the default)
Weights
42.52 GB
Card it needs
48 GB (RTX A6000, A40)
Vast on-demand
from $0.35/hr (RTX A6000)
Runpod Secure Cloud
$0.59/hr (A40 or RTX A6000)
Q4_K_M with 32K context
Weights
42.52 GB + 10.7 GB cache
Card it needs
80 GB (A100)
Vast on-demand
from $0.87/hr (A100X)
Runpod Secure Cloud
$1.79/hr (A100 PCIe or SXM)
Q8_0 (8-bit)
Weights
74.98 GB
Card it needs
80 GB, tight (A100, H100)
Vast on-demand
from $0.87/hr (A100X)
Runpod Secure Cloud
$1.79/hr (A100)
BF16 (full weights)
Weights
about 141 GB
Card it needs
2 x 80 GB
Vast on-demand
not a single-card job
Runpod Secure Cloud
not a single-card job
Weights
Card it needs
Vast on-demand
Runpod Secure Cloud
IQ4_XS (4-bit, smaller)
37.90 GB
48 GB, or a 45 GB Vast listing
from $0.35/hr (RTX A6000)
$0.59/hr (A40 or RTX A6000)
Q4_K_M (4-bit, the default)
42.52 GB
48 GB (RTX A6000, A40)
from $0.35/hr (RTX A6000)
$0.59/hr (A40 or RTX A6000)
Q4_K_M with 32K context
42.52 GB + 10.7 GB cache
80 GB (A100)
from $0.87/hr (A100X)
$1.79/hr (A100 PCIe or SXM)
Q8_0 (8-bit)
74.98 GB
80 GB, tight (A100, H100)
from $0.87/hr (A100X)
$1.79/hr (A100)
BF16 (full weights)
about 141 GB
2 x 80 GB
not a single-card job
not a single-card job
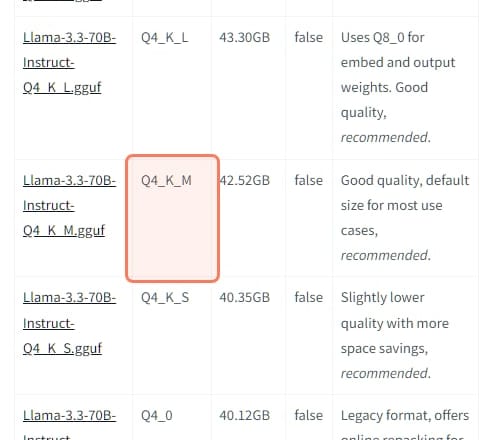
The Q4_K_M file is 42.52 GB on bartowski's Llama 3.3 70B GGUF page, read Nov 3, 2026. · Screenshot of huggingface.co by aliteq
Why 48 GB and not 44: the chat itself takes memory. Llama 3.3 70B's config has 80 layers, 8 key-value heads and a head size of 128, so every token of context costs about 0.33 MB in 16-bit cache. That's about 2.7 GB for 8K tokens and 10.7 GB for 32K. Q4_K_M plus 8K of context is about 45.2 GB before the runtime's own buffers, which is why a 48 GB card fits and a 45 GB one doesn't. Vast's listings in our feed report 45 GB for its A40 and L40S rows; on those, load IQ4_XS (37.90 GB) instead. Our VRAM calculator does this arithmetic for any context length.
What does Llama 70B cost per hour on Vast and Runpod?
From about $0.35 an hour on the cheapest 48 GB card. These are the on-demand single-GPU prices in our hourly read of both providers at 20:20 UTC on Nov 3, 2026:
RTX A6000 (48 GB): Vast from $0.35 an hour (middle listing $0.46, 6 offers; interruptible from $0.30). Runpod $0.59.
A40 (48 GB): Runpod $0.59. Vast's A40 listings show 45 GB, from $0.54 on-demand.
A100 (80 GB): Vast A100X from $0.87 (2 offers). Runpod A100 PCIe or SXM $1.79.
Vast is a marketplace: its docs say "Prices fluctuate based on real-time supply and demand" and billing is by the second, so the cheapest offer moves every hour and there may be only a handful of them. Runpod's figures are its Secure Cloud list prices on runpod.io/pricing that day. The same page's data also carries lower Community Cloud prices (RTX A6000 $0.33, A40 $0.35, A100 PCIe $1.19, read Nov 6, 2026), but Runpod's docs say "Runpod is no longer accepting new hosts for Community Cloud", so don't count on finding one free. Today's numbers for every card are on our live cloud GPU table and on the Llama 3.3 70B cost-to-run page.
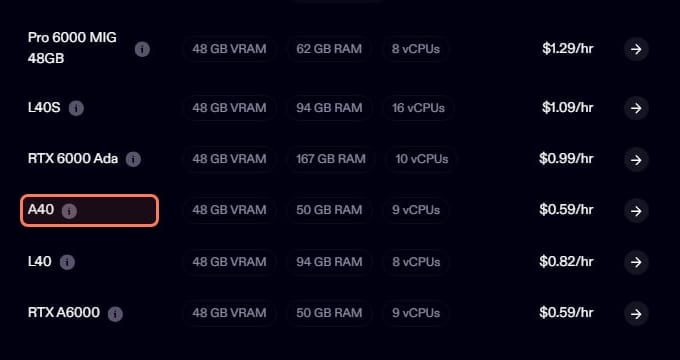
Runpod's 48 GB cards on runpod.io/pricing, read Nov 3, 2026. The A40 and RTX A6000 are the cheapest at $0.59 an hour. · Screenshot of runpod.io by aliteq
How fast is Llama 70B on a rented 48 GB card?
Slow but usable for one person: roughly 12 to 14 tokens a second by our estimate, not a benchmark. Generating text is limited by memory bandwidth, so we divide each card's published bandwidth by the 42.52 GB Q4_K_M file and take 75% of that, the same method our cost-to-run pages use:
A40 (696 GB/s, NVIDIA datasheet): about 12 tokens a second
RTX A6000 (768 GB/s, NVIDIA line card): about 13.5
A100 80GB SXM (2,039 GB/s, NVIDIA): about 36
H100 SXM (3.35 TB/s, NVIDIA): about 59
We haven't rented these cards to time them ourselves. Real speed depends on the runtime, the context length and how many requests you batch. The practical choice: the A6000 is cheapest per hour, while an A100 is about 2.7 times faster for roughly 2.5 times the Vast price, so per token the two land close. Pick the A100 when you're waiting on long answers, or when you need the room.
What does an evening of Llama 70B cost, all in?
About $1.40 to $2.40 for four hours of GPU time, plus a little storage. Four hours on Vast's cheapest RTX A6000 is $1.40 at Nov 3's price, and four hours on Runpod's A40 is $2.36. Two things add to the bill:
Download time. The first part of every new machine is pulling a 42.5 GB file. Keep it on persistent storage so you download it once.
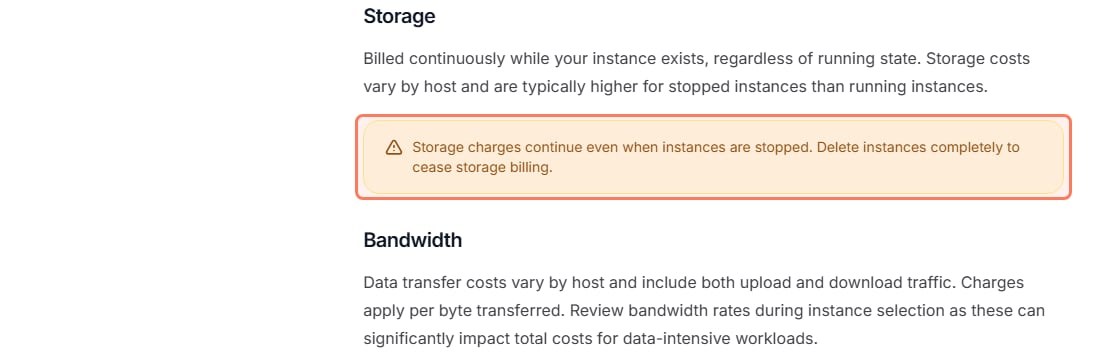
Storage while stopped. Runpod's docs list a pod's volume disk at $0.10 per GB a month while it runs and $0.20 while it's stopped; a network volume is $0.07 per GB a month either way, so 60 GB for the model is about $4.20 a month. Vast's docs warn that storage keeps billing on stopped instances:
Vast's pricing docs (docs.vast.ai/guides/instances/pricing), read Nov 3, 2026. · Screenshot of docs.vast.ai by aliteq
Rented against owned: at $0.35 an hour, 1,000 hours of Llama 70B is $350 of GPU time. Owning a 48 GB setup costs far more than that up front, so renting wins unless you run it most days. Our guide to running a 70B model at home and the rent-or-buy math cover the other side.
Do I need two 24 GB GPUs or an H100?
No to both for most people. Two 24 GB cards add up to 48 GB, which is how people run 70B at home. In the cloud it depends on the provider. On Runpod Secure Cloud, two RTX 3090s at $0.50 each cost $1.00 an hour against $0.59 for one A40, so the single card wins. On Vast, single RTX 3090 offers started at about $0.11 an hour on Nov 3 (21:20 UTC read), so a two-card machine can cost about the same as one A6000, but it has to be a host that offers both cards in one machine, and the model is then split across two GPUs. One 48 GB card is the simpler rental. An H100 is the fastest single card here, but at $2.40 an hour on Vast and $2.89 on Runpod it costs seven to eight times the cheapest A6000. Rent it for big batch jobs where speed matters; the H100 price page and the A100 price page have the details.
Is an API cheaper than renting a GPU for Llama 70B?
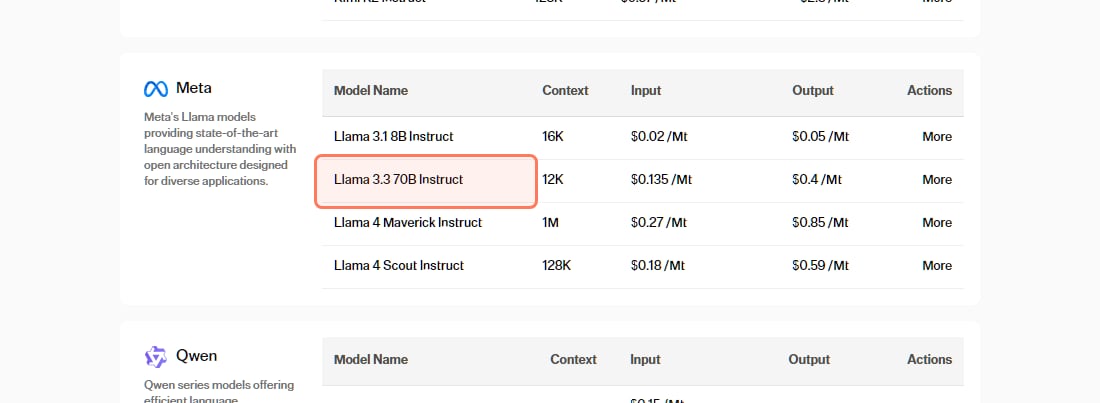
For light chat, yes, by a lot. Novita's pricing page lists Llama 3.3 70B Instruct at $0.135 per 1M input tokens and $0.40 per 1M output tokens (read Nov 3, 2026). A rented RTX A6000 at $0.35 an hour, producing about 13.5 tokens a second for one user, works out to roughly $7 per 1M output tokens. You only beat the API on a rented GPU if you keep it busy with batched requests, or if you need what the API doesn't give you:
Long context. Novita lists a 12K context window for this model; on your own A100 you can run 32K or more.
Privacy. With the API, your prompts run on Novita's servers.
Control. Your own quantization, fine-tunes, system prompt and no rate limits.
Novita's Llama 3.3 70B price on novita.ai/pricing, read Nov 3, 2026. · Screenshot of novita.ai by aliteq
How do I set it up without wasting the first hour?
Pick the card by disk too. Ask for at least 60 GB of disk so the 42.5 GB file and the runtime fit.
Use llama.cpp or Ollama for one user, vLLM for many. Our runtime comparison explains which to pick.
Keep context modest on 48 GB. Around 8K tokens fits with Q4_K_M; for more, use IQ4_XS or move to an 80 GB card.
Stop, then delete. Stopped machines still bill storage on both providers, so delete what you won't reuse this month.
Quick answers
What does it cost per hour to run Llama 70B in the cloud?
From about $0.35 an hour on Nov 3, 2026, for an RTX A6000 (48 GB) on Vast on-demand. Runpod listed the A40 and RTX A6000 at $0.59 an hour. An 80 GB A100 was from $0.87 on Vast and $1.79 on Runpod.
What is the cheapest GPU that runs Llama 70B?
A single 48 GB card such as an RTX A6000 or A40. Llama 3.3 70B at Q4_K_M is a 42.52 GB file, which leaves room for about 8K tokens of context on 48 GB.
How much VRAM does Llama 70B need?
About 45 GB for Q4_K_M with 8K context, about 53 GB with 32K context, and about 78 GB for Q8_0 with 8K context. Full 16-bit weights are about 141 GB, which needs two 80 GB cards.
Is an A100 worth it over an RTX A6000 for Llama 70B?
For long context or 8-bit weights, yes, because you need the 80 GB. For speed alone it's close: by our bandwidth estimate an A100 SXM is about 2.7 times faster, at about 2.5 times the Vast price on Nov 3, 2026.
How fast is Llama 70B on a rented GPU?
By our estimate, not a benchmark: about 12 to 14 tokens a second on an A40 or RTX A6000, about 36 on an A100 80GB SXM, and about 59 on an H100 SXM, for one user at Q4_K_M.
Is an API cheaper than renting a GPU for Llama 70B?
For light chat, yes. Novita lists Llama 3.3 70B at $0.135 per 1M input and $0.40 per 1M output tokens (Nov 3, 2026), against roughly $7 per 1M output tokens on a $0.35-an-hour A6000 used by one person. Rent the GPU for long context, privacy or batch jobs.
Does a stopped cloud GPU still cost money?
Storage does. Vast's docs say storage charges continue on stopped instances, and Runpod charges $0.20 per GB a month for a stopped pod's volume disk. Delete the machine when you won't use it again soon.
For today's prices on every card, see our live cloud GPU table; to check a different quantization or context length, use the VRAM calculator.