On Nov 3, 2026 a 40GB A100 rented from $0.40/hr on Vast.ai and an 80GB one from $0.63/hr (median $1.00), against $1.35 on Hyperstack and $1.79 on Runpod. Where the cheap A100s are, why 80GB costs about twice as much, and the jobs that need it.
Some links on this page are referral links: we may earn a commission, at no cost to you.
Share
The cheapest A100 rental is on Vast.ai's marketplace, and the memory size changes the price. In our read of Vast's offer API at 13:30 UTC on Nov 3, 2026, a 40GB A100 started at $0.40/hour on-demand (median $0.53 across 39 offers) and an 80GB A100 at $0.63/hour (median $1.00 across 25 offers). The cheapest 80GB card from a Vast-verified host was $1.00. Managed 80GB A100s listed at $1.35 on Hyperstack and $1.79 on Runpod Secure Cloud. Pay for 80GB when you run a 70B model, gpt-oss-120b or a 70B fine-tune; for 32B-class models and smaller fine-tunes, 40GB does the job for about half the price. Prices move every hour, so check today's live prices before you rent.
Where is the cheapest A100 rental right now?
The table below is one A100, priced per GPU-hour, read on Nov 3, 2026. The Vast.ai rows come from our own pull of Vast's offer API at 13:30 UTC, split by memory size; every other row is the provider's published on-demand price on its own pricing page, read the same day. "From" is the cheapest listing and "median" the middle one.
A100 rental, $/GPU-hour, read Nov 3, 2026
Vast.ai A100 40GB
From
$0.40
Median
$0.53
What you get
39 offers, SXM4 and PCIe; on-demand, marketplace hosts
Vast.ai A100 80GB
From
$0.63
Median
$1.00
What you get
25 offers; cheapest verified host $1.00
Hyperstack A100 80GB
From
$1.35
Median
-
What you get
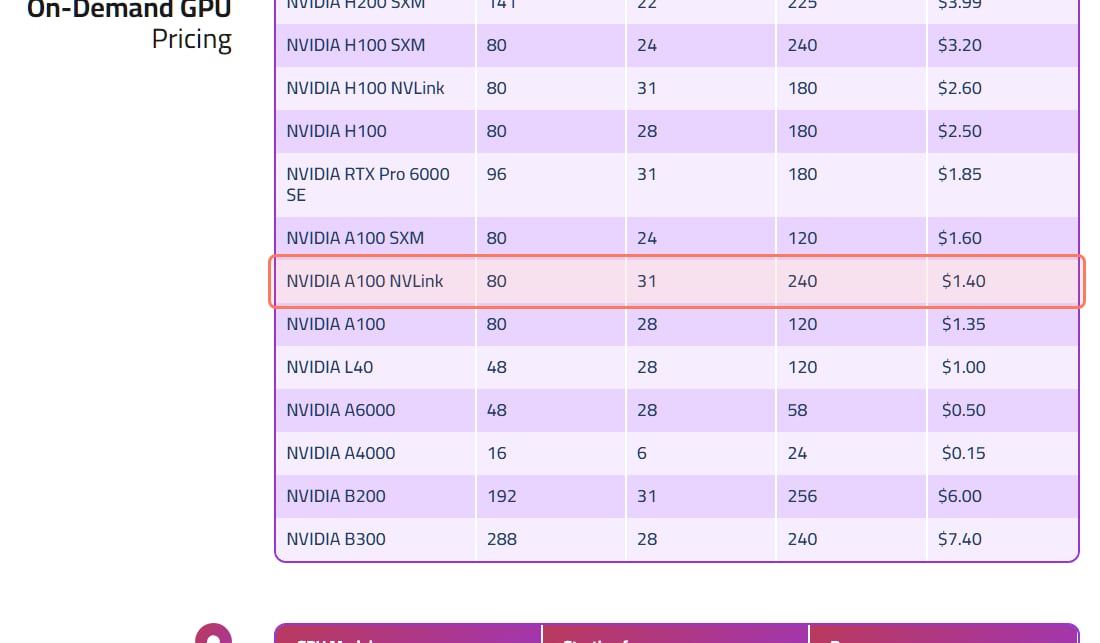
PCIe; NVLink $1.40, SXM $1.60
Runpod Secure Cloud A100 80GB
From
$1.79
Median
-
What you get
PCIe (117 GB RAM) or SXM (125 GB RAM)
Lambda A100 40GB (1 GPU)
From
$1.99
Median
-
What you get
Single-GPU instance, SXM or PCIe
CoreWeave A100 80GB
From
$2.70
Median
-
What you get
8-GPU machine only: $21.60/hr
Lambda A100 80GB
From
$2.79
Median
-
What you get
8-GPU machine only: $22.32/hr
From
Median
What you get
Vast.ai A100 40GB
$0.40
$0.53
39 offers, SXM4 and PCIe; on-demand, marketplace hosts
Vast.ai A100 80GB
$0.63
$1.00
25 offers; cheapest verified host $1.00
Hyperstack A100 80GB
$1.35
-
PCIe; NVLink $1.40, SXM $1.60
Runpod Secure Cloud A100 80GB
$1.79
-
PCIe (117 GB RAM) or SXM (125 GB RAM)
Lambda A100 40GB (1 GPU)
$1.99
-
Single-GPU instance, SXM or PCIe
CoreWeave A100 80GB
$2.70
-
8-GPU machine only: $21.60/hr
Lambda A100 80GB
$2.79
-
8-GPU machine only: $22.32/hr
One A100 80GB, on-demand, $ per GPU-hour (read Nov 3, 2026)
Vast.ai, cheapest offer$0.63
One unverified host
Vast.ai, cheapest verified host$1.00
Also the median of 25 offers
Hyperstack$1.35
Runpod Secure Cloud$1.79
CoreWeave (8-GPU node)$2.70
Lambda (8-GPU node)$2.79
Two things to know about the cheapest number. First, it's a single host: at 13:30 UTC the $0.63 80GB offer was one machine in Germany, not marked verified by Vast, with a 99.4% reliability score. The next cheapest 80GB cards were around $0.85 to $0.87, and the cheapest verified one was $1.00. Second, Vast's A100 listings mix 40GB and 80GB cards under the same name ("A100 SXM4", "A100 PCIE"), so on Vast, filter by GPU memory before you compare prices. Our live cloud-GPU table groups Vast offers by name, so its A100 rows can show a 40GB price.
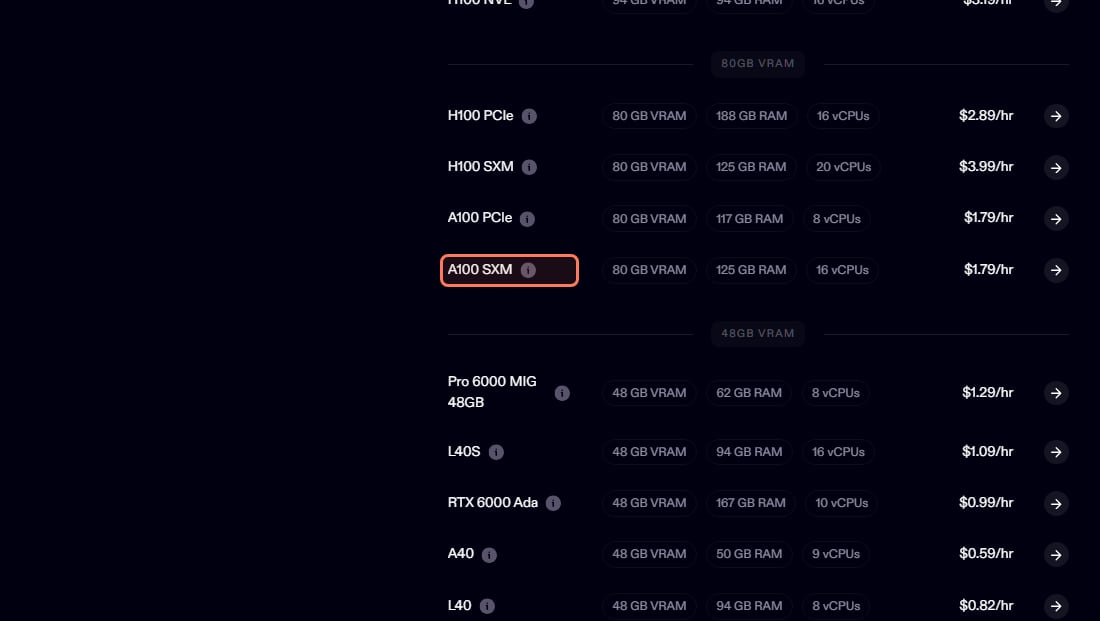
Runpod's own price list, read Nov 3, 2026: both A100 80GB versions at $1.79/hr, against $2.89 for an H100 PCIe. · Screenshot of runpod.io by aliteq
Is the 80GB A100 worth twice the price?
Only if your job doesn't fit in 40GB. On Vast, the 80GB median ($1.00) was almost exactly twice the 40GB median ($0.53) on Nov 3. NVIDIA lists the 80GB A100 with HBM2e memory at 1,935 GB/s (PCIe) or 2,039 GB/s (SXM), so the extra money buys room, not a different chip. The table uses our VRAM engine, the same one behind the VRAM calculator: weights at the stated quantization, plus the KV cache at 16-bit and about 0.8 GB of overhead.
Estimated VRAM vs a 40GB and an 80GB A100 (Aliteq VRAM engine, Nov 3, 2026)
Qwen3 30B-A3B (MoE), Q8_0
8K context
31.7 GB
32K context
34.0 GB
Card you need
40GB is enough
Qwen3 32B, Q8_0
8K context
35.2 GB
32K context
41.2 GB
Card you need
40GB at short context; 80GB at 32K
Llama 3.3 70B, Q4_K_M
8K context
43.1 GB
32K context
50.6 GB
Card you need
80GB
Llama 3.3 70B, Q6_K
8K context
57.2 GB
32K context
64.7 GB
Card you need
80GB
Llama 3.3 70B, Q8_0
8K context
73.1 GB
32K context
80.6 GB
Card you need
80GB at 8K only, tight
Qwen3 32B, 16-bit
8K context
63.8 GB
32K context
69.8 GB
Card you need
80GB
8K context
32K context
Card you need
Qwen3 30B-A3B (MoE), Q8_0
31.7 GB
34.0 GB
40GB is enough
Qwen3 32B, Q8_0
35.2 GB
41.2 GB
40GB at short context; 80GB at 32K
Llama 3.3 70B, Q4_K_M
43.1 GB
50.6 GB
80GB
Llama 3.3 70B, Q6_K
57.2 GB
64.7 GB
80GB
Llama 3.3 70B, Q8_0
73.1 GB
80.6 GB
80GB at 8K only, tight
Qwen3 32B, 16-bit
63.8 GB
69.8 GB
80GB
The other jobs where 80GB pays off, from the makers' own pages:
gpt-oss-120b: OpenAI's model card says its MXFP4 weights let "gpt-oss-120b run on a single 80GB GPU". It does not fit on 40GB. Check the live price for it on cost to run gpt-oss-120b.
Fine-tuning a 70B model: Unsloth's requirements table (which it calls absolute minimums) puts QLoRA (4-bit) on a 70B model at 41 GB, just over a 40GB card, so you need the 80GB one. 16-bit LoRA on a 32B model is 76 GB, which fits 80GB with little room; on a 70B model it's 164 GB, beyond any single A100.
Where 40GB is enough: the same table puts QLoRA at 26 GB for a 32B model and 30 GB for 40B, and 16-bit LoRA at 33 GB for a 14B model. All of those fit a 40GB A100 at about half the 80GB price.
Managed or marketplace: what do you give up for the low price?
Vast.ai is a marketplace of independent hosts: each offer has its own reliability score, location, disk price and bandwidth price, and the cheapest one may be gone in an hour. Hyperstack, Runpod Secure Cloud, Lambda and CoreWeave each publish one fixed price for their own data centers. On Nov 3 the cheapest managed single 80GB A100 was Hyperstack at $1.35; Runpod's $1.79 includes 117 GB of RAM and 8 vCPUs (PCIe) or 125 GB and 16 vCPUs (SXM).
Hyperstack's on-demand price list, read Nov 3, 2026: three 80GB A100 versions from $1.35 to $1.60 an hour. · Screenshot of hyperstack.cloud by aliteq
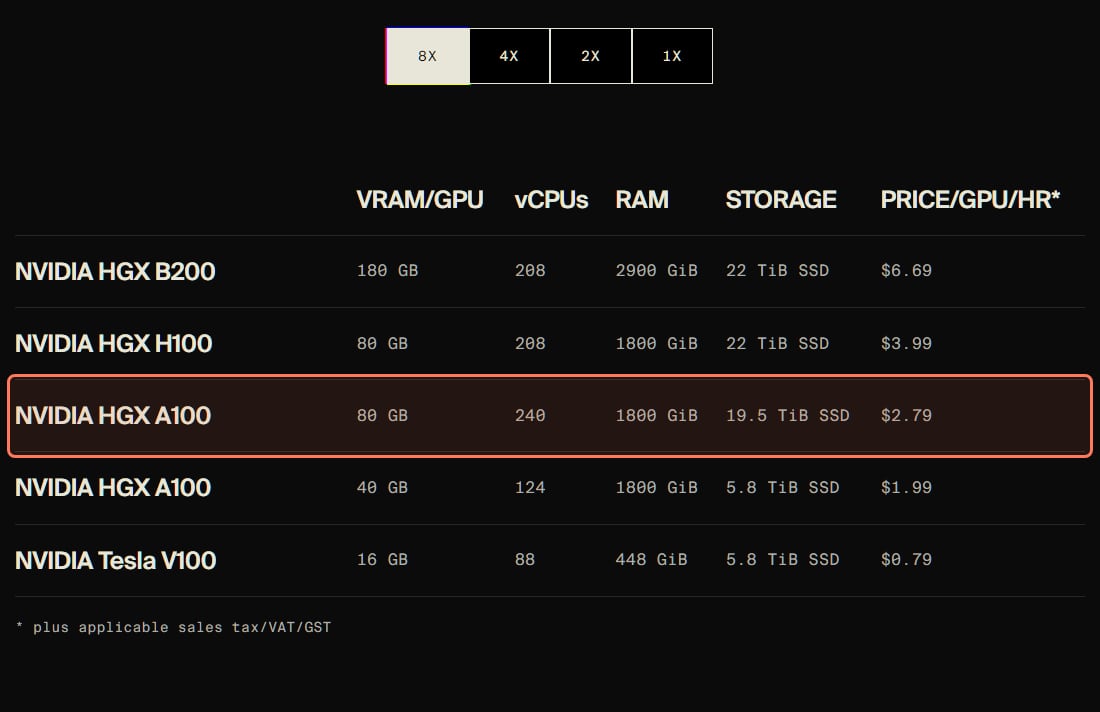
The big clouds aren't built for one-card rentals at this tier. Lambda's single-GPU A100 is the 40GB one at $1.99; its 80GB A100 appears only in the 8-GPU table, at $2.79 per GPU-hour, so about $22.32 an hour for the machine. CoreWeave lists an 8-GPU A100 80GB machine at $21.60 an hour, which works out to $2.70 per GPU. Those make sense for a multi-GPU training run, not for one model.
Lambda's 8-GPU price table, read Nov 3, 2026: the 80GB A100 at $2.79 per GPU-hour, sold as an 8-GPU machine. · Screenshot of lambda.ai by aliteq
Runpod also shows lower Community Cloud prices for the A100 ($1.19 PCIe, $1.39 SXM) in its pricing page's data, but its docs say Runpod is "no longer accepting new hosts for Community Cloud" (existing Community Cloud resources remain available), so a Community A100 may not be there when you look.
Is on-demand or interruptible the better deal for an A100?
Vast's docs describe on-demand as "Fixed pricing, guaranteed resources (high priority)" and interruptible as "Lowest cost, may be paused (low priority)". For 80GB A100s, interruptible bids started at $0.13 an hour on Nov 3 (median $0.56). That's tempting, but an 80GB A100 is usually rented for a long job, a fine-tune or a big model you've spent time loading, and a pause costs you that time. Use interruptible for work that saves checkpoints often; use on-demand for everything else. Hyperstack also lists a spot A100 at $1.08 and reservations from $0.95, if you can commit ahead.
What does an A100 cost for a real job?
Vast's docs say GPU compute is "Charged per second while your instance is running", and Runpod advertises per-second rates too, so you pay for the time the machine is on. At the Nov 3 prices:
A 4-hour session with a 70B model at 4-bit (needs 80GB): about $4.00 on the cheapest verified Vast host, $5.40 on Hyperstack or $7.16 on Runpod Secure Cloud.
A 10-hour QLoRA fine-tune of a 70B model (needs 80GB): about $10 on a verified Vast host, $13.50 on Hyperstack or $17.90 on Runpod.
The same 10 hours for a 32B QLoRA (fits 40GB): about $5.30 at the Vast 40GB median.
Storage and bandwidth come on top. Vast's docs say storage is "Billed continuously while your instance exists, regardless of running state" and add: "Delete instances completely to cease storage billing." Runpod lists volume disk at $0.10/GB a month while running and $0.20/GB a month idle.
Vast's offer list, Nov 1, 2026. Each price is per host, "plus bandwidth", with its own reliability score and verified label.
Should you rent an A100 or an H100?
Both come with 80GB, so they fit the same models; the H100 is the newer, faster chip and costs more. On Nov 3 Runpod Secure Cloud listed the A100 80GB at $1.79 against $2.89 for an H100 PCIe and $3.99 for an H100 SXM, and Vast's H100 SXM offers started at $1.79 (median $2.27, our 13:20 UTC feed). Rent the A100 when memory is what you need and the job isn't time-critical; rent the H100 when finishing faster matters more than the hourly rate. If you need more than 24GB but less than 80GB, 48GB cards are cheaper still: on Vast an RTX A6000 started at $0.35 and an L40S at $0.43 on Nov 3. For training choices, see the best cloud GPU for fine-tuning.
Frequently asked
Where is the cheapest A100 rental?
Vast.ai's marketplace. On November 3, 2026 an A100 40GB started at $0.40 an hour on-demand (median $0.53) and an A100 80GB at $0.63 (median $1.00 across 25 offers; cheapest verified host $1.00). Managed 80GB A100s listed at $1.35 on Hyperstack and $1.79 on Runpod Secure Cloud. Prices change hourly, so check the live table before you rent.
Is the 80GB A100 worth it over the 40GB one?
Only if your job needs more than 40GB. On Vast the 80GB card cost about twice the 40GB one on November 3, 2026. You need 80GB for a 70B model at 4-bit (about 43 GB at 8K context by our estimate), gpt-oss-120b, QLoRA on a 70B model (41 GB per Unsloth) or 16-bit LoRA on a 32B model (76 GB). A 32B model at 8-bit with short context, or QLoRA up to about 40B, fits in 40GB.
How do I find an 80GB A100 on Vast.ai?
Filter by GPU memory. Vast lists 40GB and 80GB cards under the same names (A100 SXM4, A100 PCIE), so a low "A100" price is often the 40GB card. Then pick a verified host with a high reliability score and check the disk and bandwidth price on the offer.
Can an A100 run a 70B model?
The 80GB one can. Llama 3.3 70B at Q4_K_M needs about 43 GB at 8K context and 51 GB at 32K by our estimate, and Q8_0 needs about 73 GB at 8K. The 40GB A100 can't hold it: the 4-bit weights alone are about 40 GB.
A100 or H100 for the cloud?
Both have 80GB and fit the same models; the H100 is faster. On November 3, 2026 Runpod Secure Cloud listed the A100 80GB at $1.79 an hour against $2.89 for an H100 PCIe, so rent the A100 when memory is the need and the H100 when speed is.
Why is Runpod's Community Cloud A100 cheaper?
Runpod's pricing data lists Community Cloud A100s at $1.19 (PCIe) and $1.39 (SXM), but its docs say it is no longer accepting new hosts for Community Cloud; existing Community resources remain available, so a Community A100 may or may not be free when you look. The Secure Cloud price was $1.79 for either version.
Do I pay for a stopped A100 on Vast.ai?
Not for the GPU, but yes for storage. Vast's docs say storage is billed while the instance exists, regardless of running state, and to delete the instance to stop storage billing.
The short version: rent the A100 on Vast.ai when price matters and you'll check the host, filter for 80GB only when the job needs it, and use Runpod or Hyperstack when you want one fixed price. Check your model with the VRAM calculator first, compare every card on our cloud-GPU compare page, and see Runpod vs Vast vs Lambda and the cloud-GPU pricing pillar for the bigger providers.