On Nov 3, 2026 the same H100 rented for $1.79 an hour on Vast.ai and listed at $6.16 a GPU on CoreWeave. Where the cheap H100s are, which ones can be taken back mid-job, and the storage bill that keeps running after you stop.
Some links on this page are referral links: we may earn a commission, at no cost to you.
Share
The cheapest H100 you could rent on Nov 3, 2026 was $1.79 an hour, on-demand, on Vast.ai's marketplace (median $2.40 across 6 offers, our 12:20 UTC read). The cheapest managed H100s were Hyperstack at $2.50 (listed simply as "H100") and Runpod Secure Cloud at $2.89 for an H100 PCIe. The catch: Vast's floor is one host out of a handful and can be gone in an hour, the even cheaper interruptible H100s can be paused or taken back mid-job, and on both Vast and Runpod the storage keeps billing after you stop the instance. Lambda, Nebius and CoreWeave listed $3.29 to $6.16 for the same chip that day. For the price right now, see our live cloud-GPU compare page.
One H100, on-demand, $ per GPU-hour (read Nov 3, 2026)
Vast.ai H100 SXM (cheapest offer)$1.79
Marketplace; median $2.40 across 6 offers
Hyperstack H100$2.50
Runpod Secure H100 PCIe$2.89
Lambda H100 PCIe (1x)$3.29
Runpod Secure H100 SXM$3.99
Lambda H100 SXM (1x)$4.29
Nebius HGX H100$4.50
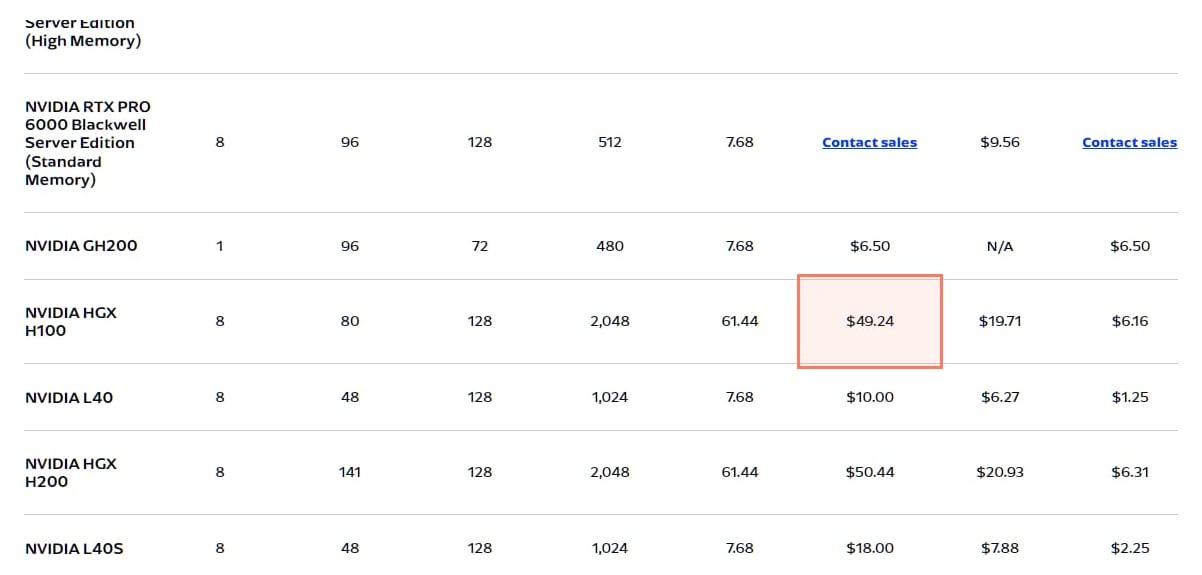
CoreWeave HGX H100 (8-GPU node)$6.16
$49.24 an hour for 8 GPUs
Where is the cheapest H100 to rent right now?
On a marketplace. Vast.ai lets independent hosts list their GPUs, and on Nov 3, 2026 its cheapest on-demand H100 SXM was $1.79 an hour. Every other price below is the provider's own published rate, read the same day; the Vast, Novita and Runpod figures are from our hourly read of their APIs, the same data that feeds /cloud-gpu.
H100 rental, $ per GPU-hour (read Nov 3, 2026)
Vast.ai (SXM)
Rate (from)
$1.79 (median $2.40)
Type
On-demand
The catch
Only 6 offers; the floor comes and goes
Hyperstack (H100)
Rate (from)
$2.50
Type
On-demand
The catch
NVLink $2.60, SXM $3.20
Runpod Secure (PCIe)
Rate (from)
$2.89
Type
On-demand
The catch
Data center hardware; NVL $3.19
Lambda (PCIe, 1x)
Rate (from)
$3.29
Type
On-demand
The catch
Plus sales tax where it applies
Novita (SXM)
Rate (from)
$3.39
Type
On-demand
The catch
Spot from $1.70
Runpod Secure (SXM)
Rate (from)
$3.99
Type
On-demand
The catch
Faster interconnect than PCIe
Lambda (SXM)
Rate (from)
$3.99 to $4.29
Type
On-demand
The catch
$4.29 on 1 GPU, $3.99 per GPU on 8
Nebius (HGX)
Rate (from)
$4.50
Type
On-demand
The catch
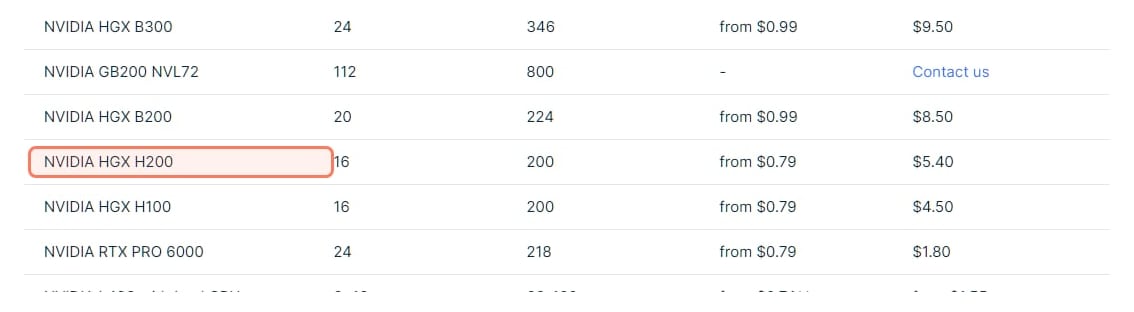
Preemptible from $0.79 (dynamic)
CoreWeave (HGX)
Rate (from)
$6.16
Type
On-demand
The catch
Sold as an 8-GPU node at $49.24/hr
Rate (from)
Type
The catch
Vast.ai (SXM)
$1.79 (median $2.40)
On-demand
Only 6 offers; the floor comes and goes
Hyperstack (H100)
$2.50
On-demand
NVLink $2.60, SXM $3.20
Runpod Secure (PCIe)
$2.89
On-demand
Data center hardware; NVL $3.19
Lambda (PCIe, 1x)
$3.29
On-demand
Plus sales tax where it applies
Novita (SXM)
$3.39
On-demand
Spot from $1.70
Runpod Secure (SXM)
$3.99
On-demand
Faster interconnect than PCIe
Lambda (SXM)
$3.99 to $4.29
On-demand
$4.29 on 1 GPU, $3.99 per GPU on 8
Nebius (HGX)
$4.50
On-demand
Preemptible from $0.79 (dynamic)
CoreWeave (HGX)
$6.16
On-demand
Sold as an 8-GPU node at $49.24/hr
A reliable on-demand H100 from a managed provider cost about $2.50 to $3 an hour on Nov 3, 2026. Anything well above that buys enterprise capacity, multi-GPU nodes and contracts, not a faster chip. If you need 8 GPUs with fast interconnect for a training run, that premium can be worth it; for one card for a few hours, it isn't.
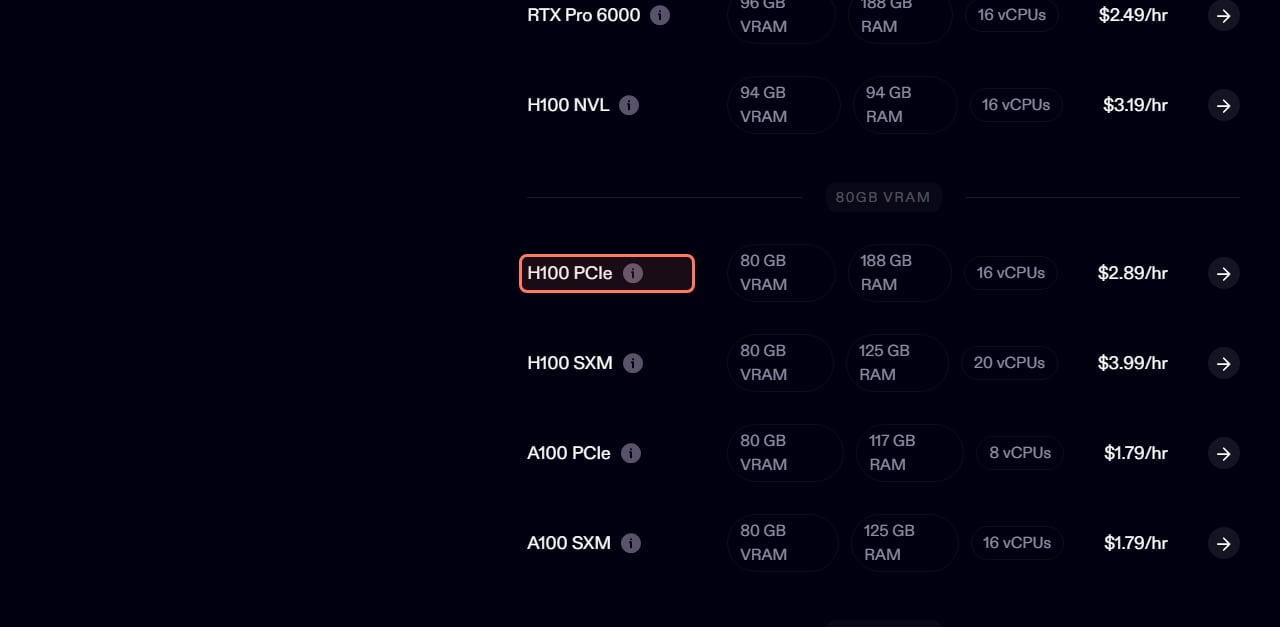
Runpod's own pricing page (runpod.io/pricing), read Nov 3, 2026: H100 PCIe $2.89 an hour, H100 SXM $3.99. · Screenshot of runpod.io by aliteq
Hyperstack's own pricing page, captured Nov 1, 2026; the same prices were listed when we re-read it on Nov 3. · Screenshot of hyperstack.cloud by aliteq
Why is Runpod's H100 sometimes $1.99?
That's the Community Cloud price. Runpod's pricing page lists H100 PCIe at $1.99 on Community Cloud and $2.89 on Secure Cloud (SXM: $2.69 vs $3.99) in its structured data, read Nov 3, 2026. Its docs say "Runpod is no longer accepting new hosts for Community Cloud" and "Existing Community Cloud resources remain available", so the cheap tier is shrinking. Expect to pay the Secure Cloud price.
What is the catch with the cheapest H100s?
There are three, and they apply to the cheapest offers most.
1. Thin supply. Our Nov 3 read found only 6 rentable on-demand H100 SXM offers on Vast. The $1.79 one is a single host; once it's rented, the next price up is what you pay. That's why we show the median ($2.40) next to the floor. Check the host's reliability score before you rent.
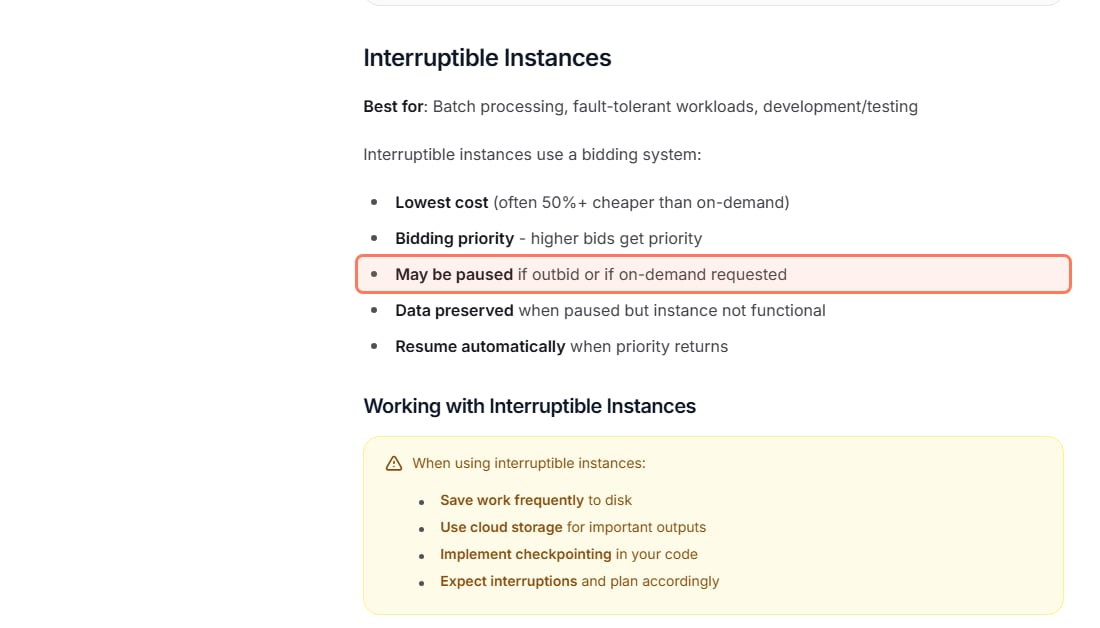
2. Interruptible means it can stop. Vast's interruptible H100s started at $0.89 an hour on Nov 3 (median $2.40), and Nebius lists preemptible H100s "from $0.79" with a note that "Spot prices are dynamic and may increase or decrease based on available capacity". Vast's own docs say an interruptible instance "May be paused if outbid or if on-demand requested". The data stays, but the job stops until your bid wins again.
Vast.ai's docs on interruptible instances (docs.vast.ai), read Nov 3, 2026. · Screenshot of docs.vast.ai by aliteq
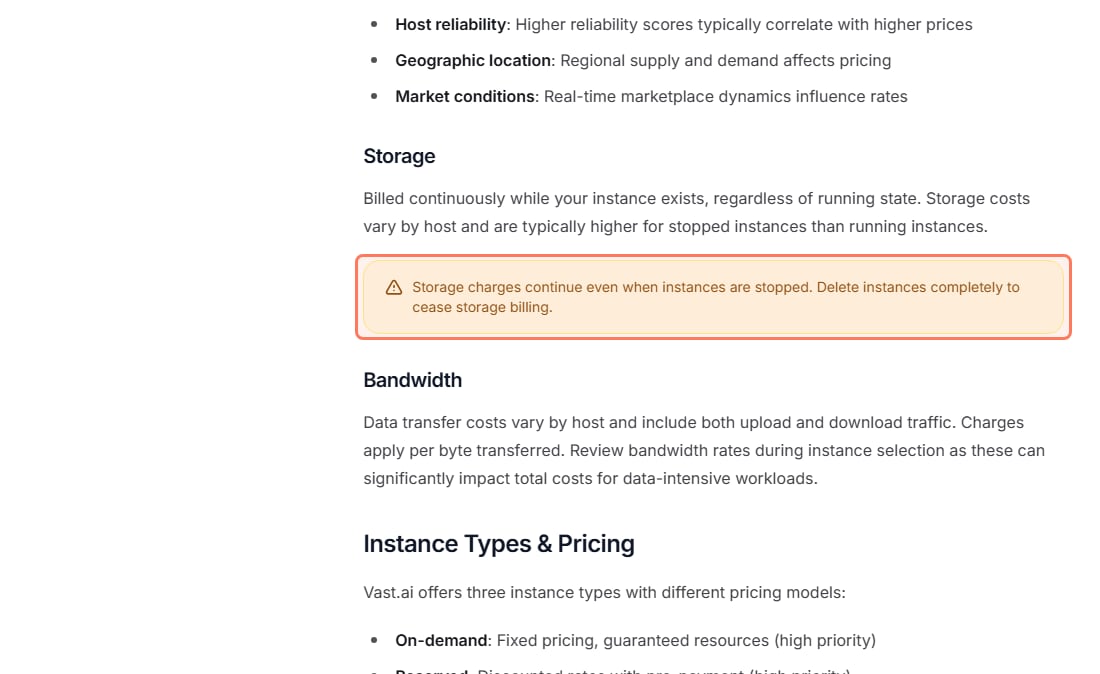
3. Storage bills after you stop. Vast's pricing docs say: "Storage charges continue even when instances are stopped. Delete instances completely to cease storage billing." Runpod's storage docs list volume disk at $0.10 per GB a month while running and $0.20 per GB a month while stopped. A stopped Runpod pod with a 100 GB volume disk is about $20 a month for nothing, by our arithmetic.
Vast.ai's pricing docs (docs.vast.ai), read Nov 3, 2026: stopping isn't deleting. · Screenshot of docs.vast.ai by aliteq
Should you rent an interruptible or an on-demand H100?
Interruptible if the job can restart, on-demand if it can't. Inference, testing a model, or a fine-tune that saves checkpoints every few minutes are fine on an interruptible card; Vast's own advice is to save work often and checkpoint. A long training run, a demo you're showing live, or anything you'd hate to lose belongs on an on-demand instance: Hyperstack at $2.50 or Runpod Secure at $2.89 were the cheapest managed options on Nov 3, 2026, with Vast's on-demand marketplace offers below them if you pick a reliable host.
Hyperstack also lists a reserved H100 from $1.75 an hour and a spot H100 PCIe at $2.00 on its pricing page (read Nov 3, 2026). Reservation means committing up front, so it only pays off if you'll keep the card busy.
Why is CoreWeave's H100 three times Vast's?
They're selling different things. CoreWeave lists an 8-GPU HGX H100 node at $49.24 an hour (about $6.16 per GPU, read Nov 3, 2026); Nebius lists $4.50 per GPU-hour for its HGX H100. Those are data center nodes with fast GPU-to-GPU links, sold to teams that need many GPUs at once and contracted capacity. Vast is a marketplace of independent hosts with variable reliability. The chip is the same H100.
CoreWeave's own pricing page, captured Nov 1, 2026 and re-read Nov 3: an 8x H100 node is $49.24 an hour, $6.16 per GPU. · Screenshot of coreweave.com by aliteq
Nebius's own pricing page, captured Nov 1, 2026; unchanged when re-read Nov 3. · Screenshot of nebius.com by aliteq
For a small team weighing a long multi-node run, a thread on r/mlops about renting 10 H100 nodes is a useful read: the worries there are support response times when a node fails mid-training and invoices that come out higher than the sticker price, not the hourly rate.
What does an H100 cost per job?
An hour only matters next to what you finish in it. An H100's 80GB runs a 70B model quantized, or a smaller model at high throughput. Using the Nov 3, 2026 prices:
Four hours of 70B inference: about $7.16 at Vast's $1.79 floor, $11.56 on Runpod Secure PCIe at $2.89.
A box left running overnight by mistake (10 hours): $17.90 to $28.90. Shut it down, and delete it when you're done.
That's our arithmetic, not a quote; the real bill depends on how long the card sits idle. Not sure you need 80GB? Our VRAM calculator shows whether a cheaper 24GB or 48GB card fits your model, and /cost-to-run matches a model to the cheapest card that runs it.
Frequently asked
Where can I rent an H100 cheapest?
On Nov 3, 2026 the cheapest on-demand H100 was $1.79 an hour on Vast.ai's marketplace (median $2.40 across 6 offers), then Hyperstack at $2.50 and Runpod Secure Cloud at $2.89 for an H100 PCIe. Lambda, Nebius and CoreWeave listed $3.29 to $6.16. Marketplace prices change hourly, so check the live price before you rent.
What is the cheapest H100 at all, including spot?
Interruptible capacity: Nebius lists preemptible H100s from $0.79 an hour (dynamic), and Vast's interruptible H100 SXM offers started at $0.89 on Nov 3, 2026. Vast's docs say an interruptible instance may be paused if outbid or if someone requests it on-demand, so use it only for work you can restart.
Is an interruptible H100 safe to use?
For work you can restart, yes: inference, experiments, and training that saves checkpoints often. Vast keeps your data when an interruptible instance is paused, but the job stops until it resumes. For anything you can't afford to restart, pay for on-demand.
Why does Runpod show an H100 for $1.99?
That's the Community Cloud price for an H100 PCIe ($2.69 for SXM). Runpod's docs say it is no longer accepting new Community Cloud hosts, while existing resources remain available. The Secure Cloud price on Nov 3, 2026 was $2.89 for PCIe and $3.99 for SXM.
Do I pay for a stopped H100?
Not for the GPU, but for the storage, yes. Vast's docs say storage charges continue when instances are stopped until you delete them, and Runpod lists volume disk at $0.20 per GB a month while a pod is stopped. Delete instances you're done with.
H100 PCIe or H100 SXM?
Both have 80GB. SXM has faster GPU-to-GPU links and costs more ($3.99 vs $2.89 on Runpod Secure, Nov 3, 2026). For one GPU running inference, PCIe is the cheaper choice; SXM matters most for multi-GPU training.
How much does it cost to run a 70B model on a rented H100?
At Runpod Secure's $2.89 an hour, four hours of inference on a quantized 70B model is about $11.56; at Vast's $1.79 floor it's about $7.16 (Nov 3, 2026 prices). You pay only while the instance runs, plus storage.