Qwen3-Coder comes in three sizes, not five. The 30B-A3B is a 19 GB download and fits a 24 GB card, Qwen3-Coder-Next (80B) needs about 48 GB, and the 480B flagship is a 290 GB server model. Exact sizes from Ollama and Hugging Face, how much context adds, and what to do on 8 to 16 GB.
Some links on this page are referral links: we may earn a commission, at no cost to you.
Share
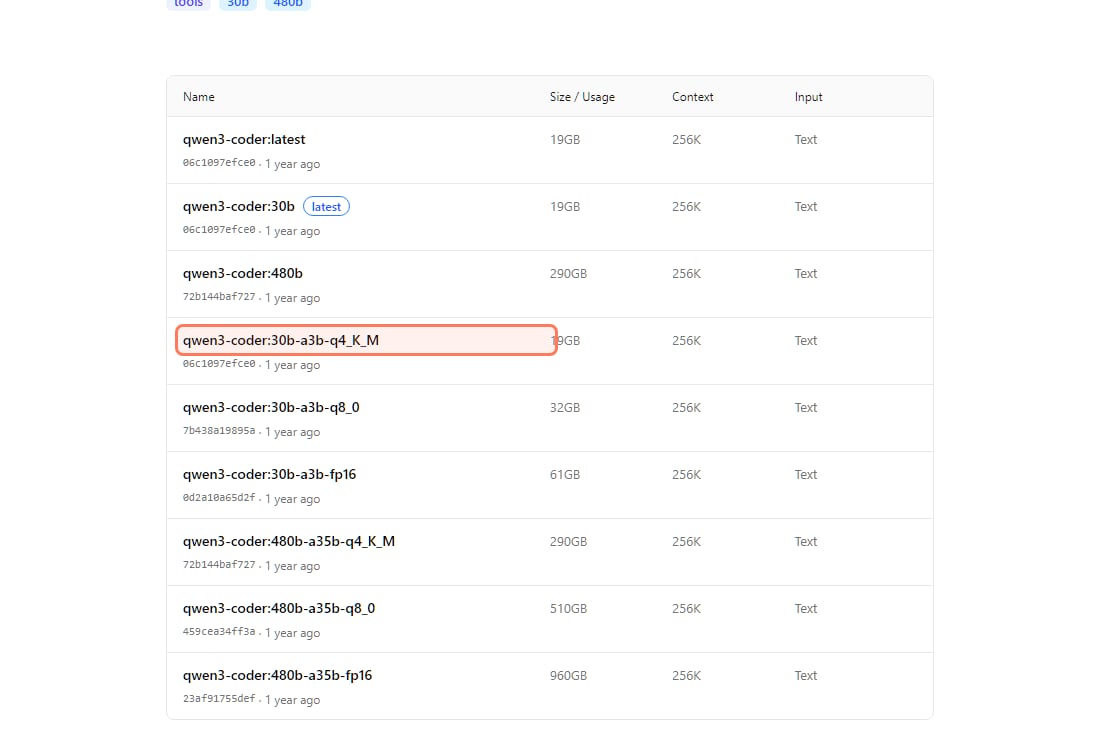
How much VRAM do you need for Qwen3-Coder? It depends on which of the three variants you mean. The 30B-A3B is a 19 GB download at Q4_K_M on Ollama and runs fully on a 24 GB GPU at a 32K context. Qwen3-Coder-Next (80B total, 3B active) is a 52 GB download on Ollama and wants a 48 GB card or a Mac with 64 GB or more of unified memory. The 480B-A35B flagship is 290 GB at Q4_K_M, so it's a multi-GPU server model. Sizes read November 3, 2026 on Ollama's library and Qwen's own Hugging Face pages.
Qwen3-Coder download sizes at 4-bit (Ollama, Nov 3, 2026)
19 GB
Qwen3-Coder 30B-A3B
qwen3-coder:30b-a3b-q4_K_M
52 GB
Qwen3-Coder-Next (80B)
qwen3-coder-next:q4_K_M
290 GB
Qwen3-Coder 480B-A35B
qwen3-coder:480b-a35b-q4_K_M
256K
Native context (K tokens)
All three variants
How much VRAM does each Qwen3-Coder variant need?
Start from the file size, then add room for context. These are the published file sizes for each variant and quantization, read November 3, 2026. The GPU column is our read of those sizes plus a 32K context; check your own card in the VRAM calculator.
Qwen3-Coder-30B-A3B
Total / active params
30.5B / 3.3B
Q4_K_M file
19 GB
Q8_0 file
32 GB
GPU that fits it at 32K context
24 GB (RTX 3090, 4090)
Qwen3-Coder-Next
Total / active params
80B / 3B
Q4_K_M file
52 GB (Ollama), 48.4 GB (Qwen GGUF)
Q8_0 file
85 GB
GPU that fits it at 32K context
48 GB (RTX A6000, 6000 Ada) or 64 GB+ Mac
Qwen3-Coder-480B-A35B
Total / active params
480B / 35B
Q4_K_M file
290 GB
Q8_0 file
510 GB
GPU that fits it at 32K context
Multi-GPU server
Total / active params
Q4_K_M file
Q8_0 file
GPU that fits it at 32K context
Qwen3-Coder-30B-A3B
30.5B / 3.3B
19 GB
32 GB
24 GB (RTX 3090, 4090)
Qwen3-Coder-Next
80B / 3B
52 GB (Ollama), 48.4 GB (Qwen GGUF)
85 GB
48 GB (RTX A6000, 6000 Ada) or 64 GB+ Mac
Qwen3-Coder-480B-A35B
480B / 35B
290 GB
510 GB
Multi-GPU server
Parameter counts are from each model card on Qwen's Hugging Face page. File sizes are Ollama's tag list, except the 48.4 GB figure, which is the sum of the Q4_K_M files in Qwen's own Qwen3-Coder-Next-GGUF repo.
Ollama's own qwen3-coder tag list, read November 3, 2026. The default tag (latest = 30b) is the 19 GB Q4_K_M build. · Screenshot of ollama.com by aliteq
Is there a Qwen3-Coder 8B or 32B?
No. Qwen's Qwen3-Coder repo lists three model families: Qwen3-Coder-Next, Qwen3-Coder-480B-A35B and Qwen3-Coder-30B-A3B, plus their FP8, GGUF and base builds. The 7B, 14B and 32B coding models are Qwen2.5-Coder, the previous generation. If a guide tells you to run "Qwen3-Coder 32B", it's mixing the two up. An earlier version of this page did too; we corrected it on November 3, 2026.
Does Qwen3-Coder-30B-A3B fit on a 24 GB GPU?
Yes, at 4-bit with a sensible context. The Q4_K_M file is 19 GB. On top of that sits the KV cache, which grows with every token of context. From the model's own config.json (48 layers, 4 KV heads, head size 128), that's about 96 KB per token, or roughly 3 GB per 32K tokens.
16K
Weights (Q4_K_M)
17.2 GB
KV cache
1.5 GB
About this much VRAM
19.5 GB
32K
Weights (Q4_K_M)
17.2 GB
KV cache
3.0 GB
About this much VRAM
21 GB
64K
Weights (Q4_K_M)
17.2 GB
KV cache
6.0 GB
About this much VRAM
24 GB
128K
Weights (Q4_K_M)
17.2 GB
KV cache
12 GB
About this much VRAM
30 GB
256K
Weights (Q4_K_M)
17.2 GB
KV cache
24 GB
About this much VRAM
42 GB
Weights (Q4_K_M)
KV cache
About this much VRAM
16K
17.2 GB
1.5 GB
19.5 GB
32K
17.2 GB
3.0 GB
21 GB
64K
17.2 GB
6.0 GB
24 GB
128K
17.2 GB
12 GB
30 GB
256K
17.2 GB
24 GB
42 GB
Weights and the 16K row are from our cost-to-run page for this model, which adds about 0.8 GB of runtime overhead; the longer rows apply the same KV formula. So a 24 GB card holds the 30B at 32K comfortably and tops out around 64K. For the full 256K window you'd need about 42 GB, or a quantized KV cache. Qwen's own model card says: "If you encounter out-of-memory (OOM) issues, consider reducing the context length to a shorter value, such as 32,768."
The 30B-A3B is a mixture-of-experts model: only 3.3B parameters work on each token, which is why it's quick, but all 30.5B still have to sit in memory. That's why the file is 19 GB even though it "thinks" like a much smaller model. Our best GPU for Qwen3-Coder page compares the 24 GB cards.
Watch out: Ollama gives you 4K or 32K context unless you change it
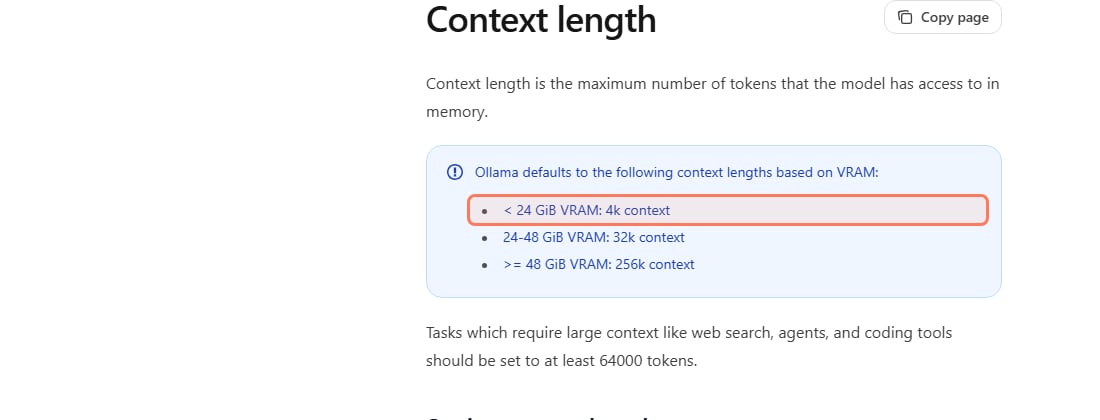
Ollama picks a default context from your VRAM. Its docs list "< 24 GiB VRAM: 4k context", "24-48 GiB VRAM: 32k context" and ">= 48 GiB VRAM: 256k context", and add: "Tasks which require large context like web search, agents, and coding tools should be set to at least 64000 tokens." A coding agent that seems to forget your files after a few turns is often running at 4K.
Ollama's Context length page, read November 3, 2026. Set it with the app's slider or OLLAMA_CONTEXT_LENGTH when you serve. · Screenshot of docs.ollama.com by aliteq
How much VRAM does Qwen3-Coder-Next need?
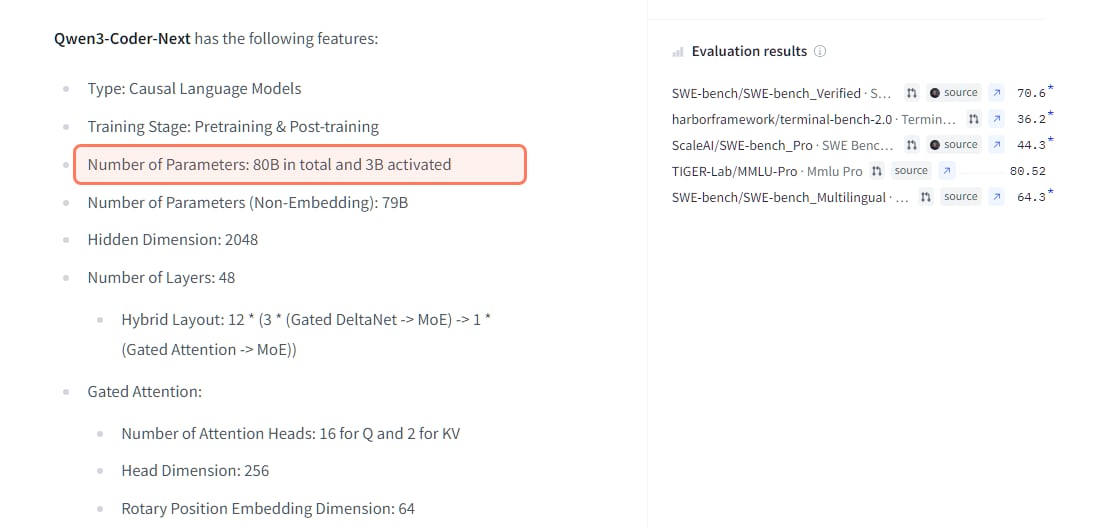
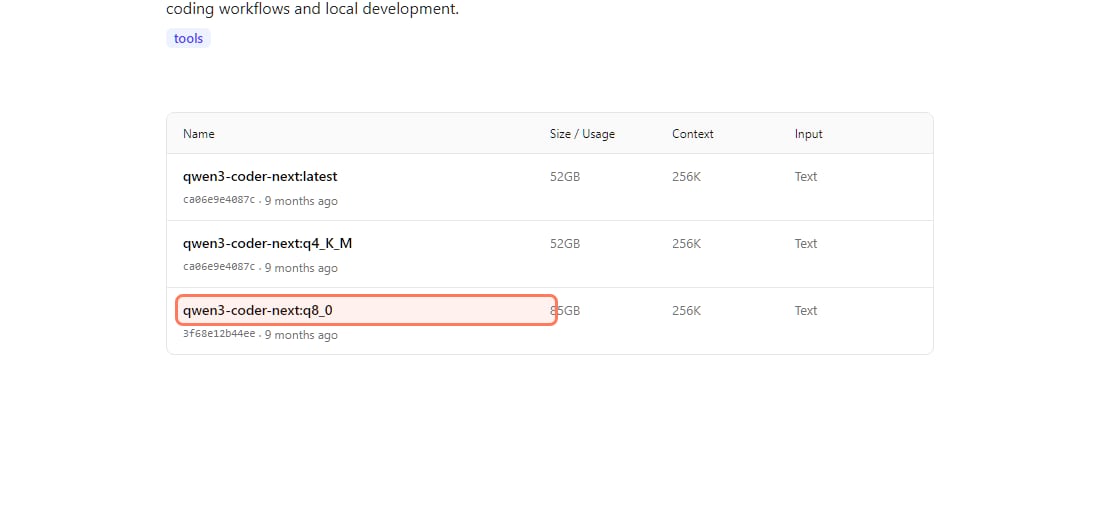
About 48 GB for the 4-bit build. Qwen describes Qwen3-Coder-Next as "an open-weight language model designed specifically for coding agents and local development", with "80B in total and 3B activated" parameters. Ollama's q4_K_M tag is 52 GB and its q8_0 tag is 85 GB; Qwen's own GGUF repo lists 48.4 GB for Q4_K_M and 84.8 GB for Q8_0.
Qwen's Qwen3-Coder-Next model card on Hugging Face, read November 3, 2026. · Screenshot of huggingface.co by aliteq
The good news is context. Only 12 of its 48 layers use full attention (the rest are linear-attention layers with a small fixed state), so its KV cache is about a quarter of the 30B's per token: roughly 0.75 GB per 32K tokens, about 6 GB for the full 256K. So once the 45 to 52 GB of weights fit, the full 256K window adds only about 6 GB more. Two 24 GB cards (48 GB total) are tight: our cost-to-run page for Qwen3-Coder-Next puts the Q4_K_M build at 46.1 GB with just 16K of context.
Ollama's qwen3-coder-next tag list, read November 3, 2026. · Screenshot of ollama.com by aliteq
Can you run Qwen3-Coder-480B at home?
Not on a normal desktop. The Q4_K_M build is 290 GB on Ollama, the Q8_0 is 510 GB and the FP16 is 960 GB. Its KV cache is also the biggest: from its config.json (62 layers, 8 KV heads), about 248 KB per token, or close to 8 GB per 32K tokens. At 4-bit and 32K context that's roughly 300 GB of memory, which means several 80 GB data-center GPUs or a 512 GB Mac Studio-class machine. For most people, the 480B is something you call through an API, not something you host.
Can you run Qwen3-Coder on 8 GB, 12 GB or 16 GB of VRAM?
Not fully on the GPU. The smallest Qwen3-Coder is 19 GB at 4-bit, so on 8 to 16 GB you have three honest options:
Offload the experts to system RAM. Because the 30B-A3B is a mixture-of-experts model, llama.cpp can keep the attention layers on the GPU and put expert weights in system RAM. It runs slower than fully on the GPU, and you need enough RAM for the rest of the 19 GB plus your OS. How it works: --n-cpu-moe explained.
Drop to a smaller quant. Our cost-to-run page shows Q2_K at about 14 GB with 16K context, which squeezes into 16 GB, but with heavy quality loss. See what quantization does.
Should you buy a GPU or rent one to try Qwen3-Coder?
Try first if you're unsure. A 24 GB card is the floor for the 30B and a 48 GB card for Next, and both are cheap to rent by the hour. On November 3, 2026 at 20:20 UTC, our price tracker's lowest listings were an RTX 3090 (24 GB) at $0.067/hr and an RTX A6000 (48 GB) at $0.301/hr, both interruptible (spot) offers on Vast.ai; on-demand was $0.096/hr and $0.349/hr. Listings change by the hour; see today's prices on our cloud GPU page.
If you're buying, a used RTX 3090 is the usual cheapest route to 24 GB. For Qwen3-Coder-Next, compare a 48 GB card against a high-memory Mac on the best GPU for Qwen3-Coder-Next page.
Which Qwen3-Coder should you run?
Match it to your memory:
24 GB GPU (RTX 3090, 4090) or 32 GB (RTX 5090): Qwen3-Coder-30B-A3B at Q4_K_M, context set to 32K to 64K. A 32 GB card fits Q6_K at 16K context per our cost-to-run page.
48 GB GPU or a 64 GB+ Mac (two 24 GB GPUs are tight): Qwen3-Coder-Next at Q4_K_M. Its small KV cache leaves room for long context.
8 to 16 GB: the 30B with expert offload to system RAM, or Qwen2.5-Coder 7B/14B.
480B: use it through an API; it isn't a home model.
It depends on the variant. Per Ollama's library (read Nov 3, 2026), Qwen3-Coder-30B-A3B is 19 GB at Q4_K_M and fits a 24 GB GPU with about 32K of context. Qwen3-Coder-Next (80B total, 3B active) is 52 GB at Q4_K_M on Ollama and needs a 48 GB GPU or a Mac with 64 GB or more. Qwen3-Coder-480B-A35B is 290 GB at Q4_K_M and needs a multi-GPU server. Long context adds VRAM on top of the file size.
Can Qwen3-Coder run on 8 GB or 16 GB of VRAM?
Not fully on the GPU, because the smallest Qwen3-Coder is a 19 GB file at 4-bit. On 16 GB you can run the 30B-A3B by offloading expert weights to system RAM in llama.cpp, which is slower, or use a 2-bit build with heavy quality loss. On 8 GB, Qwen2.5-Coder 7B is the practical choice.
Is there a Qwen3-Coder 32B or 8B?
No. Qwen's Qwen3-Coder repo lists Qwen3-Coder-Next, Qwen3-Coder-480B-A35B and Qwen3-Coder-30B-A3B. The 7B, 14B and 32B coding models are Qwen2.5-Coder, the previous generation.
How much extra VRAM does the 256K context take?
For the 30B-A3B, about 3 GB per 32K tokens, so the full 256K adds roughly 24 GB on top of the 17 GB of weights. Qwen3-Coder-Next uses full attention in only 12 of its 48 layers, so its KV cache is about 0.75 GB per 32K tokens, roughly 6 GB at 256K. Qwen's model card suggests dropping to 32,768 tokens if you run out of memory.
Why does Qwen3-Coder forget my code in Ollama?
Usually the context is too short. Ollama's docs say it defaults to 4K context under 24 GiB of VRAM and 32K between 24 and 48 GiB, and that coding tools should be set to at least 64,000 tokens. Raise it in the app's settings or with OLLAMA_CONTEXT_LENGTH.
Is Qwen3-Coder free to use commercially?
The 30B-A3B, Next and 480B-A35B model pages on Hugging Face all list the Apache 2.0 license (read Nov 3, 2026), which allows commercial use under its terms.