RTX 5090: 32 GB, what it runs and what it costs
Specs checked · Rental prices from 55m ago · Aliteq Team · How we compute this
The short answer
The NVIDIA GeForce RTX 5090 has 32 GB of VRAM and 1792 GB/s of memory bandwidth (2025). At Q4_K_M quality or better with an 8K context it runs 32 of the open models we track; the largest that fits with room to spare is Qwen3.6 35B-A3B (MoE). The cheapest rental right now is $0.200/hr (Vast.ai, interruptible).
- VRAM
- 32 GB
- Bandwidth
- 1792 GB/s
- Board power
- 575 W
- Launched
- 2025
Source: NVIDIA specification · bandwidth not yet confirmed by a second source, so we don't estimate speed from it
Buy it or rent it
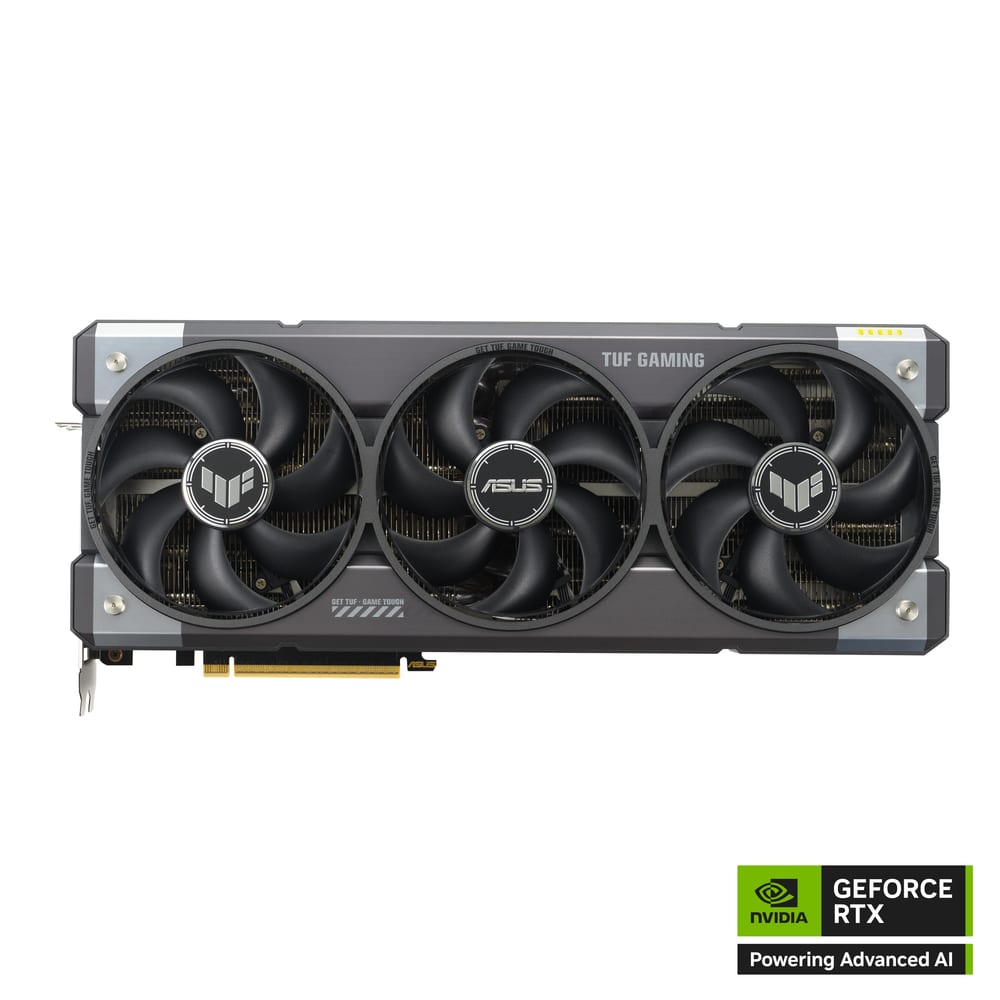
Buy an RTX 5090
GeForce RTX 5090 32GB cards
New, from Amazon. Check the exact model says 32 GB before you buy.
Best for: Top-end gaming and workstation cards; 70B-class models at low-bit quants.
Today's price shows on Amazon · Referral link
| Provider | Type | From, per hour | Rent |
|---|---|---|---|
| Vast.ai | Spot (can be interrupted) | $0.200/hr | Vast.ai |
| Vast.ai | On demand | $0.387/hr | Vast.ai |
| Lium | Spot (can be interrupted) | $0.670/hr | Lium |
| Lium | On demand | $0.700/hr | Lium |
| Runpod | On demand | $1.190/hr | Runpod |
Lowest price per provider in our hourly snapshot (55m ago). Rent buttons are referral links. Every card side by side: cloud GPU prices.
Which AI models run on the RTX 5090
Computed by our VRAM engine for an 8K context: the best quality each model fits at in 32 GB. Speeds are upper-bound estimates from memory bandwidth, not benchmarks.
| Model | Best fit | VRAM used | ~tok/s |
|---|---|---|---|
| Mixtral 8x7B (MoE) | Q5_0 | 32 GB100% · tight | — |
| Qwen3.6 35B-A3B (MoE) | Q6_K | 28 GB89% | — |
| Ornith-1.5 35B-A3B (MoE) | Q6_K | 28 GB89% | — |
| Qwen3.5 35B-A3B (MoE) | Q6_K | 28 GB89% | — |
| DeepSeek R1 Distill 32B | Q6_K | 28 GB87% | — |
| Qwen2.5 Coder 32B | Q6_K | 28 GB87% | — |
| Qwen2.5 32B Instruct | Q6_K | 28 GB87% | — |
| Qwen3 32B | Q6_K | 28 GB87% | — |
| NVIDIA Nemotron 3 Nano 30B-A3B (MoE) | Q6_K | 25 GB78% | — |
| Gemma 4 31B | Q6_K | 25 GB79% | — |
| Qwen3 30B-A3B (MoE) | Q8_0 | 32 GB99% · tight | — |
| Qwen3-Coder 30B-A3B (MoE) | Q8_0 | 32 GB99% · tight | — |
Fits only below Q4 quality: Qwen3-Next 80B-A3B (MoE) (IQ3_XS), Qwen3-Coder-Next 80B-A3B (MoE) (IQ3_XS), DeepSeek R1 Distill 70B (Q2_K).
Too big for 32 GB (rent a bigger card instead): what it costs to run GLM-4.5-Air (MoE), what it costs to run Llama 4 Scout 17B-16E (MoE), what it costs to run gpt-oss 120B (MoE), what it costs to run NVIDIA Nemotron 3 Super 120B-A12B (MoE).
Check a model and context of your own in the VRAM calculator.
AI video on the RTX 5090
Alibaba's Wan 2.2 is an open video model you can run yourself in ComfyUI. With 32 GB the RTX 5090 fits:
- Wan 2.2 14B at 640x640 with fp8 weights (24 GB and up, per Runpod's Wan 2.2 guide)
- Wan 2.2 5B, with ComfyUI's native offloading (8 GB and up, per ComfyUI's Wan 2.2 docs)
What each setup needs, the cheapest card to rent and what one clip costs: cloud GPUs for ComfyUI with Flux and Wan 2.2. Against an app or an API: AI video cost per clip, app vs API vs rented GPU. Rather not run a model yourself? Hosted video models such as Seedance, Veo and Hailuo are compared in Kling AI alternatives, priced per clip.
Our guides on the RTX 5090
- CompareRTX 5080 vs RTX 5090 for Local AI: The 16GB Gap Decides Which Models You Can Run
- CompareTwo RTX 3090s or one RTX 5090 for local LLMs? The answer isn't the one everyone gives
- CompareI ran the math on renting a cloud GPU vs buying an RTX 5090 — the answer surprised me
- What is the best local LLM for a 32GB RTX 5090? Qwen3.6 35B-A3B, and four more that fit
- Two used RTX 3090s or one RTX 5090 for local AI: which should you buy?
- newegg's '$500 off' on this RTX 5090 PC undersells the actual deal by a lot
- Is the RTX PRO 6000 worth it for local AI, versus two RTX 5090s or renting?
- nvidia is selling the RTX 5090 for $1,999 this week — but only if you're in Dallas
- The ROG Astral RTX 5080 OC launched at $1,499.99. Best Buy now asks $2,099.99
- the best 4K gaming GPU in 2026 isn't the RTX 5090 — and the reason is pure math
- Is the RTX 5090 worth it for local AI? Only if you need 32GB and can find one near $1,999
- What's the cheapest way to get 16, 24, 32, 48 or 96GB of VRAM for local AI right now?
Cards to compare it with
- RTX 5000 Ada Generation · 32 GB
- Apple M4 Max (14-core CPU / 32-core GPU) · 36 GB
- RTX 4090 · 24 GB
- RTX 3090 Ti · 24 GB
- AMD Radeon RX 7900 XTX · 24 GB
- RTX 3090 · 24 GB
Every card by VRAM tier: all GPUs for gaming and local AI.