AI
the cheapest way to run GLM in the cloud (by version)
Can't hold GLM locally? Rent it. GLM-4.5-Air needs one 80GB card (~$0.47/hr); GLM-5 needs two H200s (~$5.26/hr). The card maths and live dated prices for each version.
Aliteq Team · · 7 min
40 articles · newest first
Can't hold GLM locally? Rent it. GLM-4.5-Air needs one 80GB card (~$0.47/hr); GLM-5 needs two H200s (~$5.26/hr). The card maths and live dated prices for each version.
Aliteq Team · · 7 min
GLM ties Kimi K3 at the top of the open-weight rankings, but 'run it locally' depends on which GLM — from the 106B Air that fits one card to the 744B GLM-5 that needs a 256GB Mac or the cloud. The honest map, with real numbers.
Aliteq Team · · 8 min
Mistral Small 24B fits a single 24GB card at Q4 (~14GB). VRAM by quant, which GPU, realistic speeds by runtime, and the cheapest way to run it — own or rent.
Aliteq Team · · 7 min
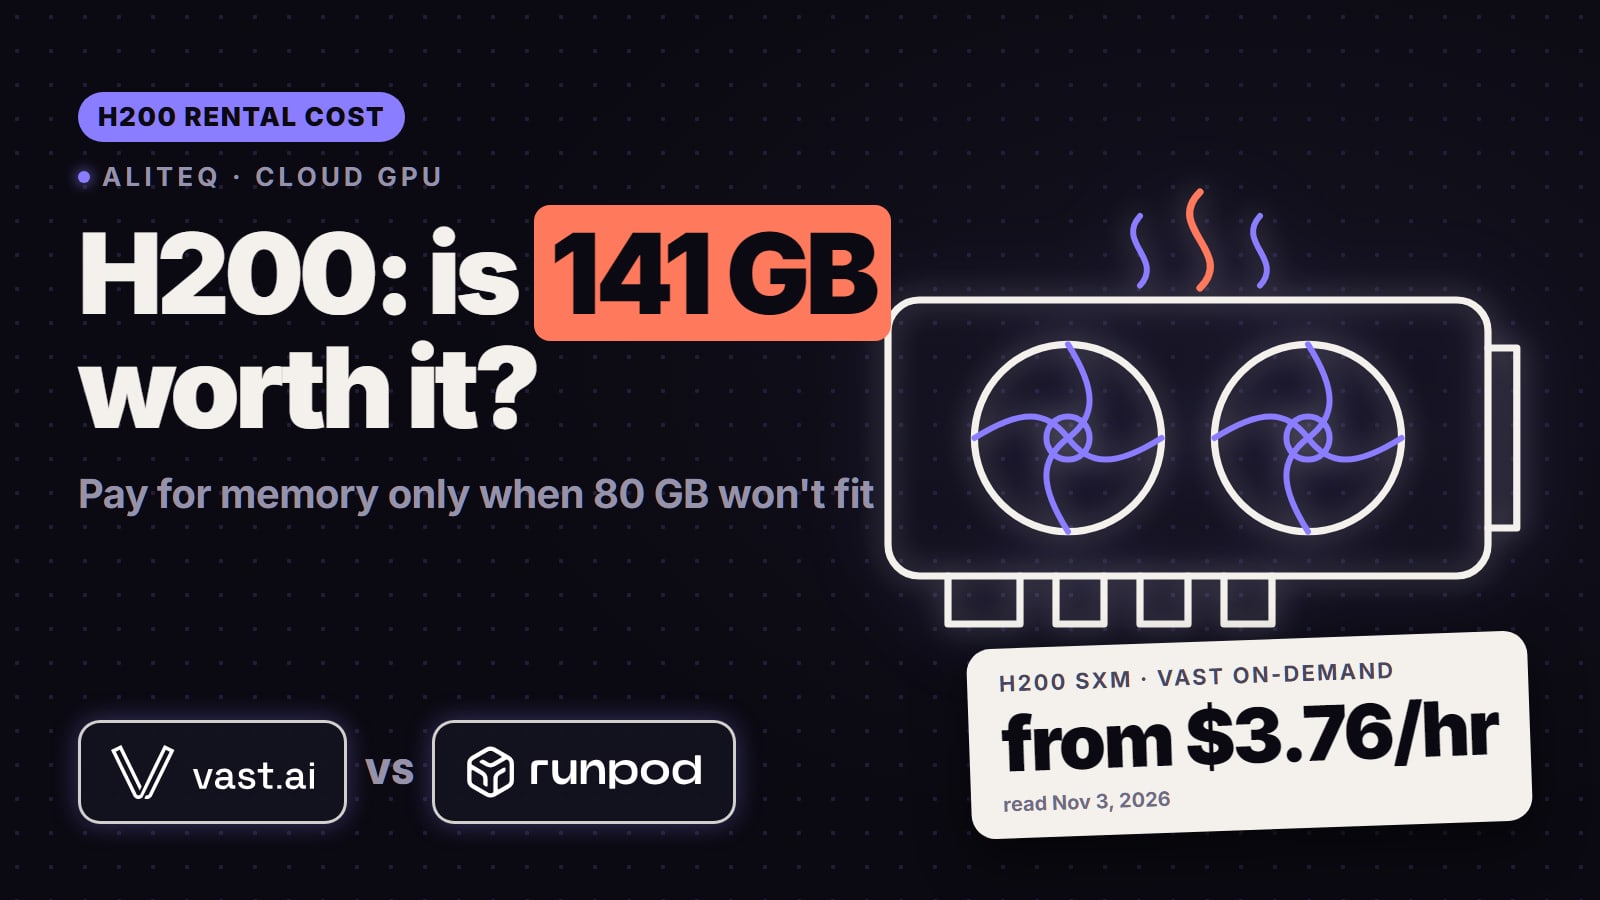
On Nov 3, 2026 a single H200 rented from $3.76 an hour on Vast.ai to $6.31 a GPU on CoreWeave. What each provider charges, the cheaper H200 NVL, and the models that really need 141GB instead of an 80GB H100.
Aliteq Team · · 8 min
On Nov 3, 2026 a 40GB A100 rented from $0.40/hr on Vast.ai and an 80GB one from $0.63/hr (median $1.00), against $1.35 on Hyperstack and $1.79 on Runpod. Where the cheap A100s are, why 80GB costs about twice as much, and the jobs that need it.
Aliteq Team · · 8 min
On Nov 3, 2026 a rented RTX 4090 started at $0.27/hr on Vast.ai (median $0.46) against $0.89/hr on Runpod Secure Cloud. Where the low prices are, the catch behind each one, and which models, image tools and fine-tunes fit in 24GB.
Aliteq Team · · 7 min
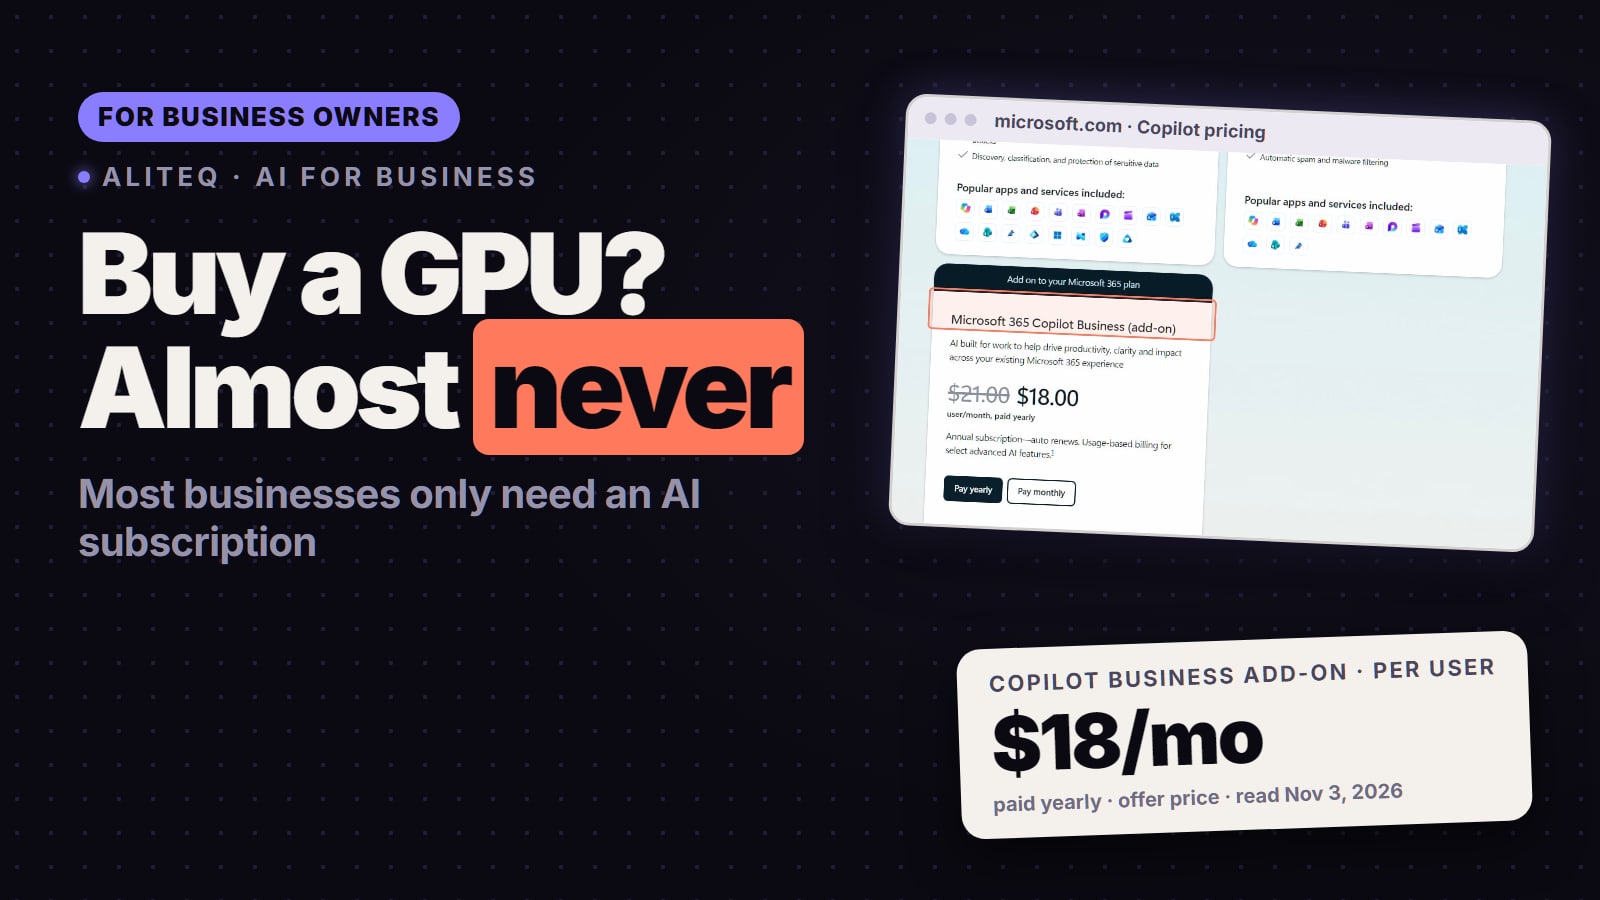
ChatGPT, Claude, Copilot and Gemini all run on the vendor's servers, so a business pays per seat or per use, not for hardware. What each option cost on Nov 3, 2026, what the business plans say about your data, and the few cases where a GPU really comes in.
Aliteq Team · · 7 min
Without a strong graphics card you have three real options: a free app with limits, a paid app at about 14 cents an image on Higgsfield Starter, or a rented 24 GB GPU from 9 cents an hour on Vast. What each costs, checked on the vendors' own pages Nov 3, 2026, and which one fits you.
Aliteq Team · · 7 min
Most AI apps don't need a GPU — they just call an API. Here's when you actually need to rent one, and what 'pod vs serverless' means in plain words.
Aliteq Team · · 6 min
A cloud GPU is a powerful graphics chip you rent over the internet by the hour instead of buying one. Here's what that means, why it exists, and what it costs — in plain words.
Aliteq Team · · 6 min
You don't need a $1,000 graphics card to start using AI yourself. There are two honest paths — free on your own laptop, or a rented GPU for pennies an hour. Here's which is yours.
Aliteq Team · · 6 min
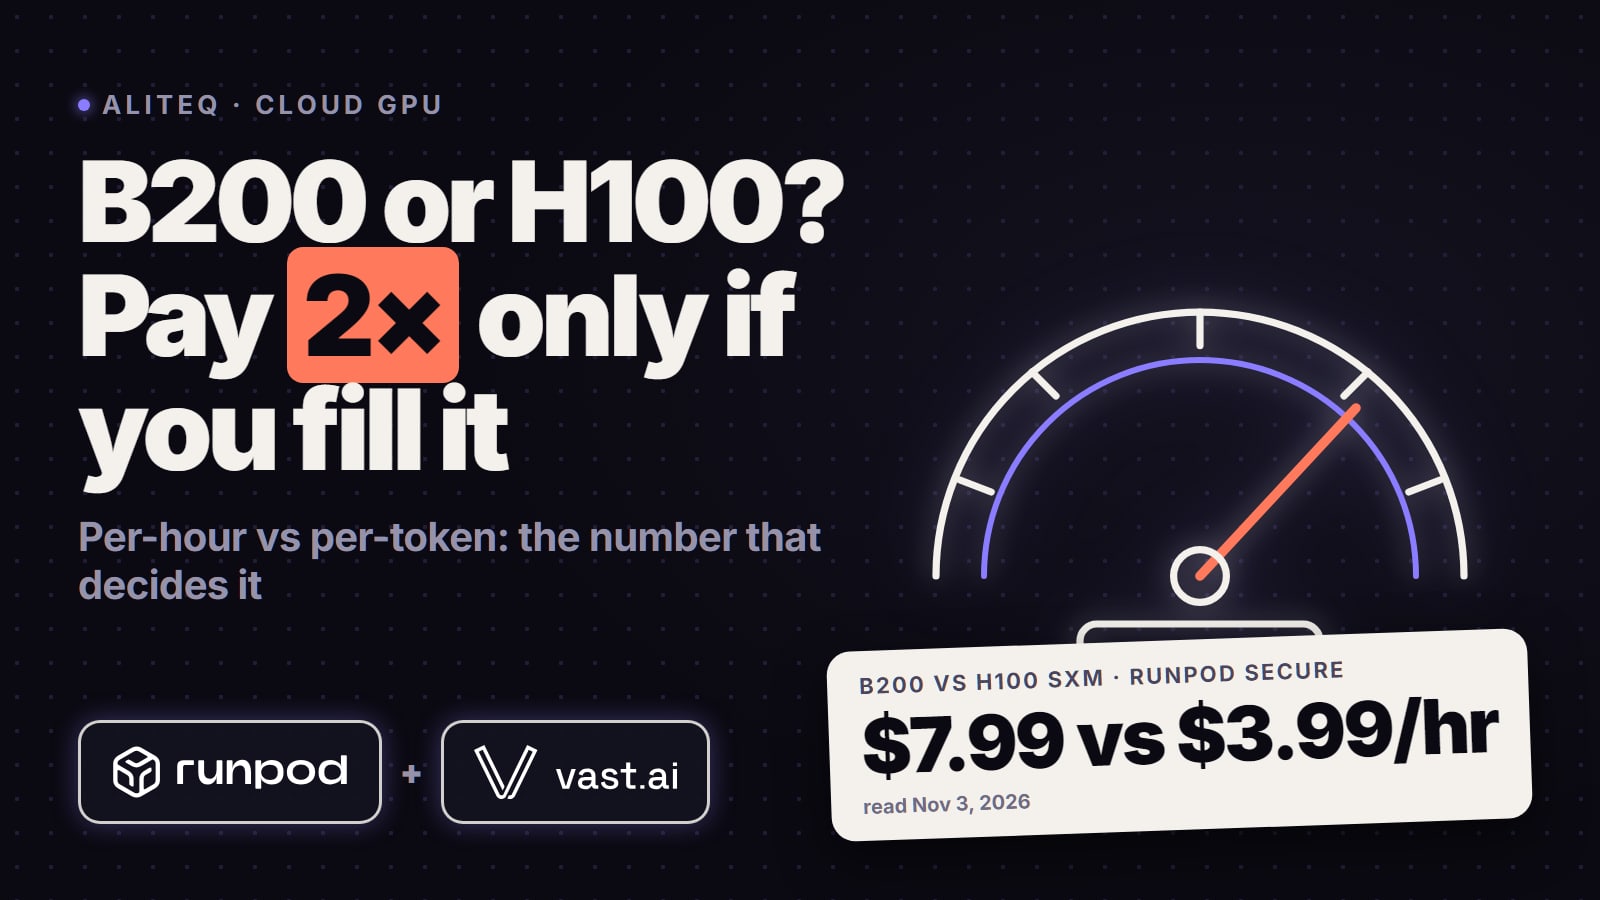
On Nov 3, 2026 a B200 rented for 1.4 to 2 times an H100 at the same managed cloud, and 3.6 times on Vast's marketplace. NVIDIA's own specs put it at about 2.3 times the compute and 2.25 times the memory. How to tell which side of that line your workload is on.
Aliteq Team · · 8 min
A serverless H100 lists at $5.39 an hour against $1.99 to $3.99 for an H100 pod, but serverless bills only the seconds a worker runs. The full rate card side by side, the busy-hours break-even for every tier, and the settings that quietly add to the bill. Read on Runpod's own pages, Nov 3, 2026.
Aliteq Team · · 8 min
Scout fits a single H100 from ~$1.73/hr. Maverick needs 243GB — four H100s or two H200s. Here's the cheapest cloud setup for each, dated to real prices.
Aliteq Team · · 7 min
On Nov 3, 2026 the same H100 rented for $1.79 an hour on Vast.ai and listed at $6.16 a GPU on CoreWeave. Where the cheap H100s are, which ones can be taken back mid-job, and the storage bill that keeps running after you stop.
Aliteq Team · · 7 min
France pledged €109B for AI, hosted a landmark Paris summit, and built a champion in Mistral. The honest look at its 'sovereign AI' strategy — what's genuinely working, and where 'stratospheric growth' is still just a slogan.
Aliteq Team · · 8 min
Samsung pushed its flagship Galaxy AI features down to 2023 phones — a small move with a big lesson: AI is becoming a software add-on to hardware you own. What landed, what runs on-device, and the catch.
Aliteq Team · · 7 min
A French startup barely a year old raised €600M at a $6B valuation — then multiplied it several times over. The honest story of Mistral, Europe's answer to OpenAI, and why its open-model, sovereign-AI bet matters.
Aliteq Team · · 8 min
Claude burned through 650 dead ends to push the Riemann zeta problem forward — real progress, not the proof half the internet is calling it.
Aliteq Team · · 6 min
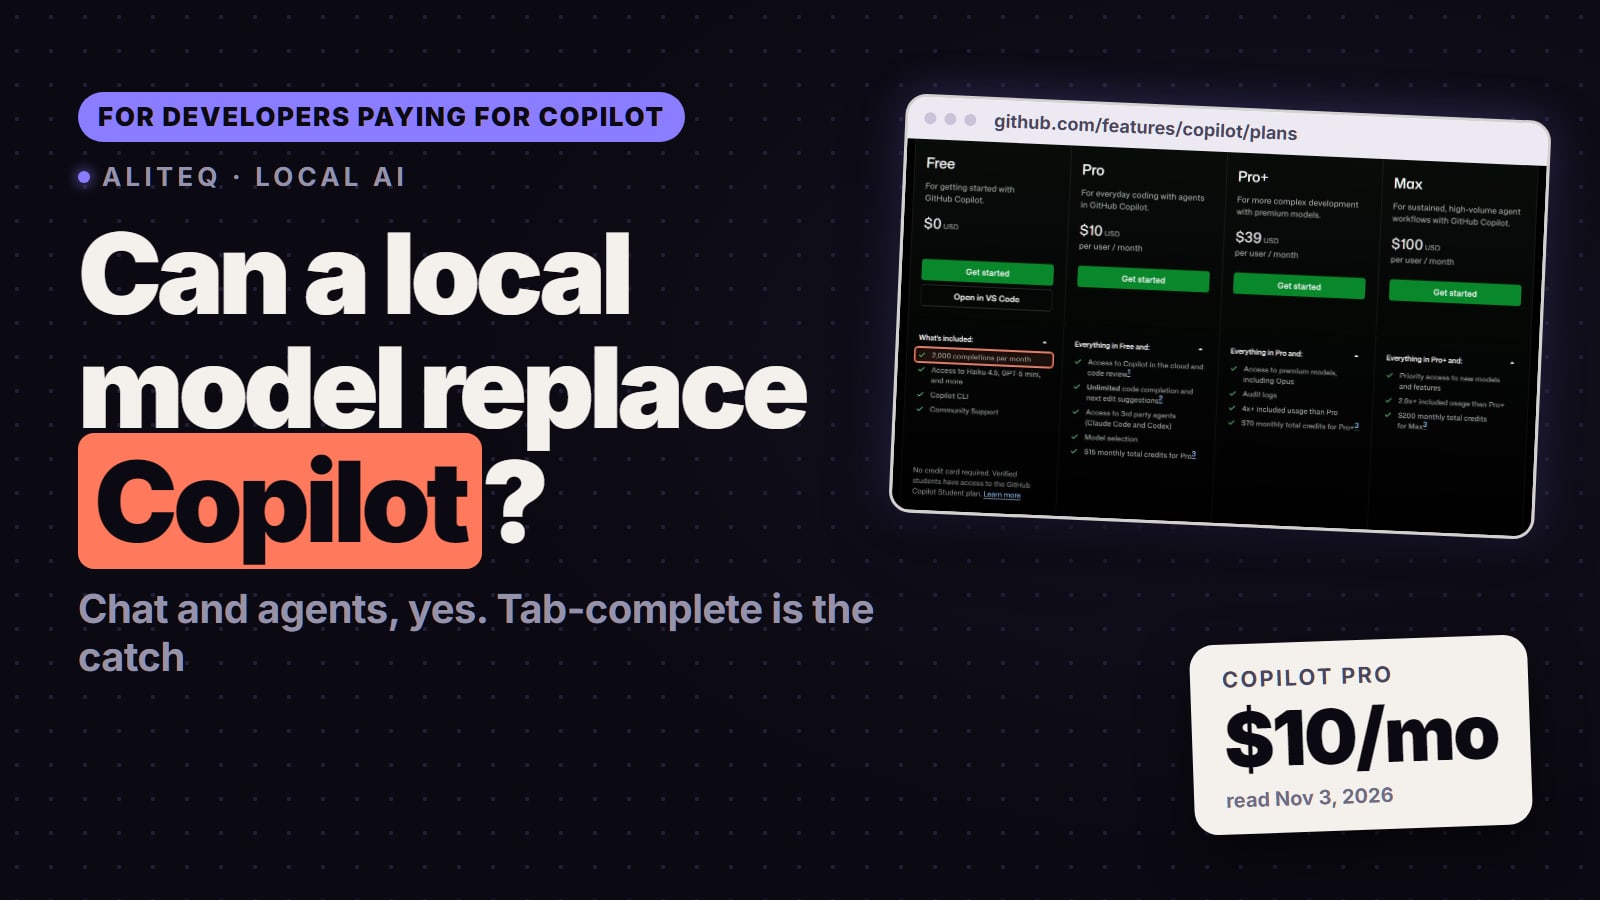
A local Qwen3-Coder can take over Copilot's chat and agent work for $0 a month and keep your code on your machine. Tab autocomplete is the catch. What Copilot costs since its June 2026 billing change, what GPU the local route needs, and who should keep paying.
Aliteq Team · · 9 min
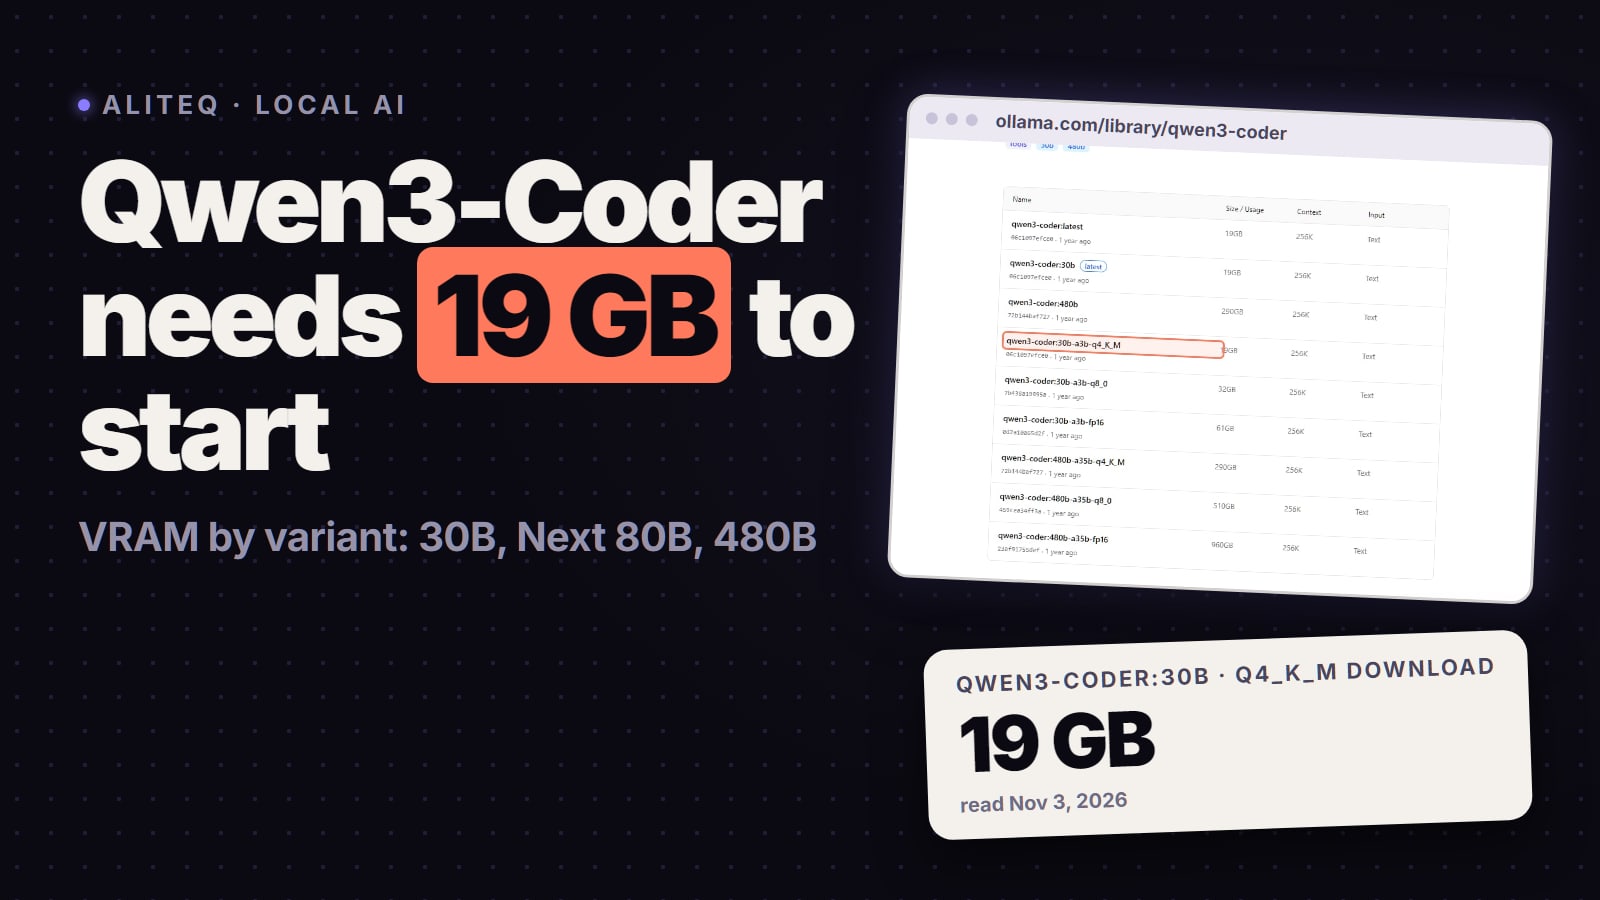
Qwen3-Coder comes in three sizes, not five. The 30B-A3B is a 19 GB download and fits a 24 GB card, Qwen3-Coder-Next (80B) needs about 48 GB, and the 480B flagship is a 290 GB server model. Exact sizes from Ollama and Hugging Face, how much context adds, and what to do on 8 to 16 GB.
Aliteq Team · · 8 min
Three of the best open models, three different strengths. gpt-oss is the cost-effective all-rounder, Qwen3 owns coding, DeepSeek owns hard reasoning. Here's how to pick for your work.
Aliteq Team · · 10 min
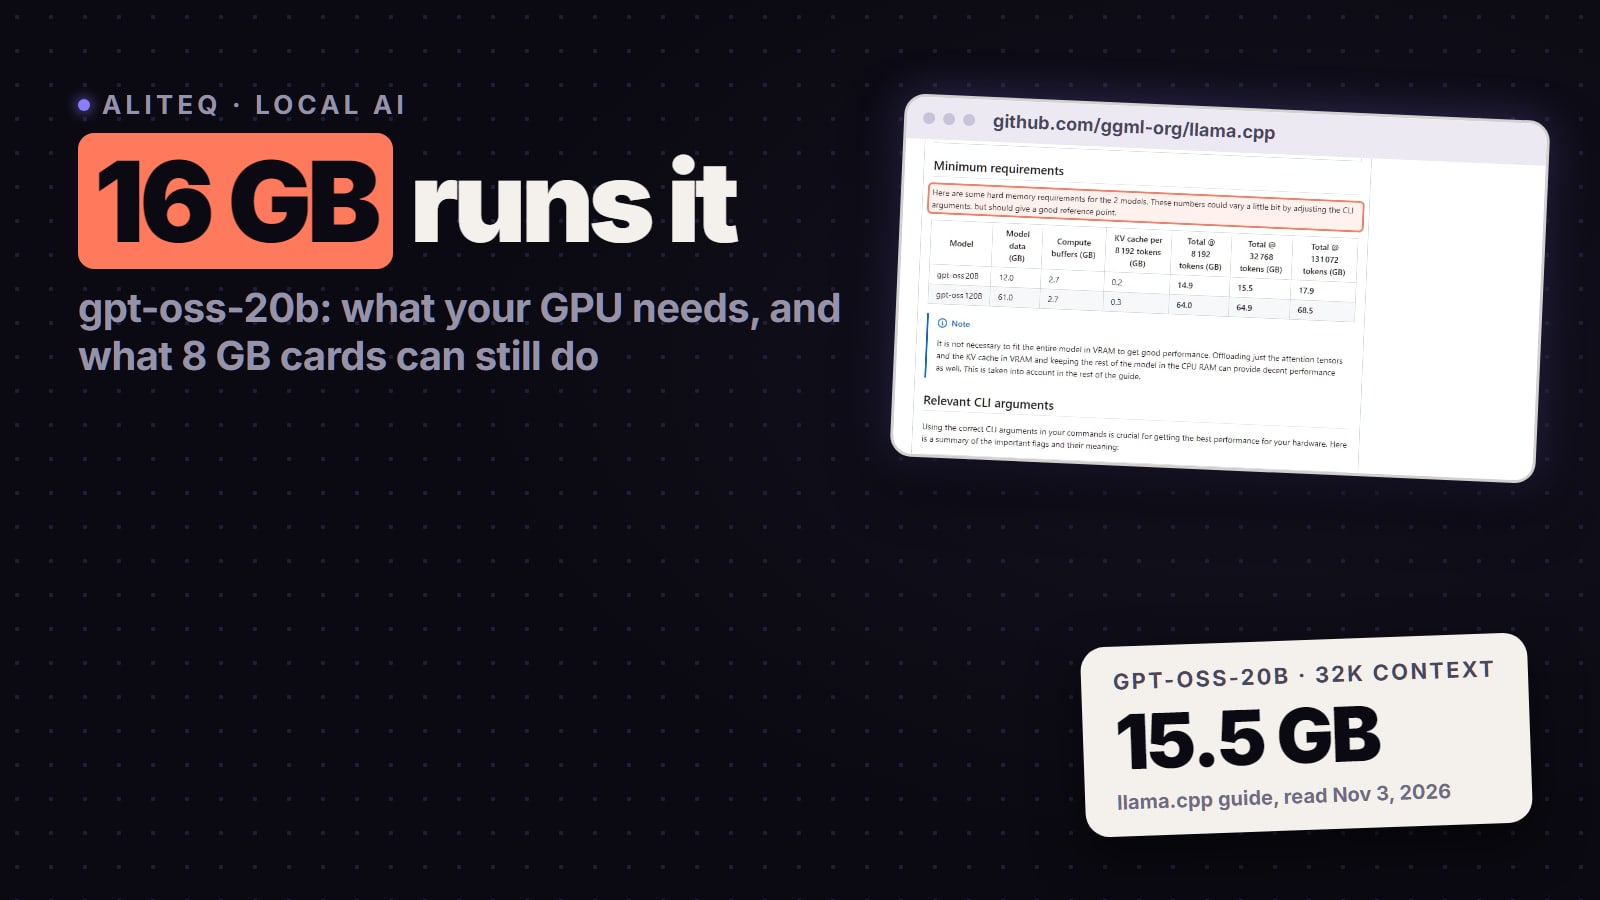
gpt-oss-20b fits fully on any 16 GB graphics card: 14.9 GB at 8K context and 15.5 GB at 32K, per the llama.cpp guide. An 8 GB or 12 GB card still runs it with some layers in system RAM. What your GPU, RAM and Mac need, how fast each card is, and the Ollama setting that quietly cuts your context. Checked Nov 3, 2026.
Aliteq Team · · 9 min
You don't need a discrete graphics card to get GPU-accelerated local AI. A modern AMD Radeon iGPU shares your system RAM as VRAM and runs 7B models faster than a CPU — here's what to expect.
Aliteq Team · · 10 min
Local models pile up fast and each one is gigabytes. Here are the exact Ollama commands to remove one model or all of them, see what you have, stop what's running, update, and move the whole store to another drive.
Aliteq Team · · 8 min
A '30B' model that runs as fast as a 3B one? That's a Mixture-of-Experts model, and it changes the local-AI math. Here's what MoE means and why it matters for what you can run.
Aliteq Team · · 10 min
For math, logic, and step-by-step problems, 'reasoning' models that think out loud beat regular chatbots. Here's the best one to run locally, from an 8GB card to a 24GB rig.
Aliteq Team · · 10 min
Yes, you can run a real language model on a Raspberry Pi 5. It won't be fast, but for a tiny, private, always-on AI it's genuinely fun and useful. Here's how, and what to expect.
Aliteq Team · · 10 min
Embeddings are what let a local AI search your documents. Pick the wrong one and retrieval is bad; pick the right one and RAG just works. Here's the best local embedding model, by need.
Aliteq Team · · 10 min
Running your local AI stack in Docker keeps it isolated, portable, and easy to reset. It's the tidy way to run Ollama and a web UI together. Here's the simple setup.
Aliteq Team · · 10 min
Uncensored local models answer without the refusals and lectures of cloud chatbots. How the two kinds are made, how to run one in Ollama on an 8 GB card, and the rules that still apply after the filter is gone.
Aliteq Team · · 8 min
Point your editor at a model on your own machine and get autocomplete, chat, and even an agent that edits files — free, unlimited, and with your code never leaving your PC. Here's the setup.
Aliteq Team · · 10 min
A local vision model reads images, describes photos, and pulls text out of screenshots — all offline. Some open ones now beat GPT-4o at OCR. Here's how to run one, in one command.
Aliteq Team · · 10 min

For fiction, worldbuilding, and character roleplay, the best models are community fine-tunes that write like a collaborator, not a chatbot — and they run privately on your own machine.
Aliteq Team · · 10 min
Kokoro and Piper narrate on almost any PC; Chatterbox and Kitten-TTS 2 clone voices; Fish Audio Drama 3 now tops the open-weights leaderboard but needs a big GPU. What each one needs, and what its license lets you do.
Aliteq Team · · 10 min
Mistral's models are famously efficient — they punch above their size, so you get a lot on modest hardware. Here's how to run Mistral locally in one command, by size.
Aliteq Team · · 10 min
Point your apps, scripts, and coding tools at a model on your own machine instead of a paid cloud API. It's an OpenAI-compatible endpoint, it's free, and it's one command to start.
Aliteq Team · · 10 min
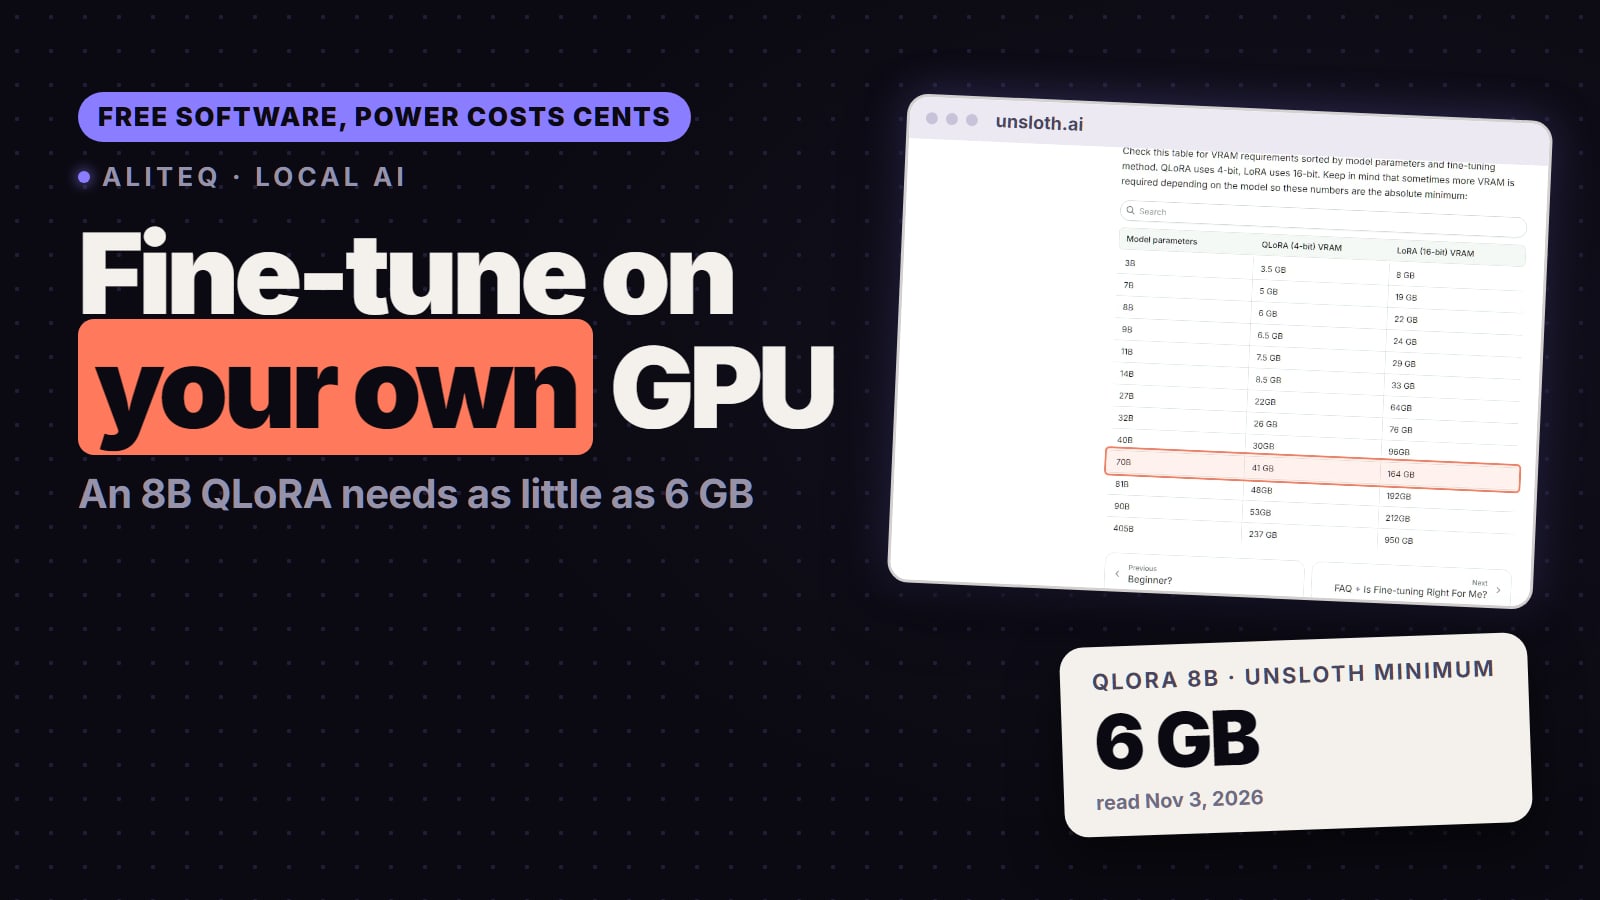
Yes. With QLoRA, an 8B model needs as little as 6 GB of VRAM and a 14B model 8.5 GB (Unsloth's minimums, read Nov 3, 2026), so a 12GB RTX 3060 or a 24GB RTX 4090 can do it. The software is free; the cost is electricity, about 6 to 13 cents an hour for a whole PC at the US average rate. Here is what fits on which card, and when renting is cheaper.
Aliteq Team · · 8 min
Upload your PDFs, notes, and research to a local AI and ask it anything — with none of it leaving your machine. This is local RAG, and you can set it up in about 30 minutes.
Aliteq Team · · 10 min
Quantization is the trick that shrinks giant AI models to fit consumer GPUs, with almost no quality loss. Here's what those Q4/Q5/Q8 labels actually mean — in plain English.
Aliteq Team · · 10 min