A local Qwen3-Coder can take over Copilot's chat and agent work for $0 a month and keep your code on your machine. Tab autocomplete is the catch. What Copilot costs since its June 2026 billing change, what GPU the local route needs, and who should keep paying.
Some links on this page are referral links: we may earn a commission, at no cost to you.
Share
Can a free local model replace GitHub Copilot? Mostly. A local Qwen3-Coder can take over Copilot's chat, edits and agent work for $0 a month, and your code stays on your machine. The catch is tab autocomplete: VS Code's own docs say "Currently, you cannot connect to a local model for inline suggestions", so ghost-text completions need a separate extension and a small completion model. You also need a GPU with enough memory, about 24 GB for the model most people use. Copilot Pro costs $10 a month and Copilot Free costs nothing, so the free tier is the real thing to beat. All prices and specs below were read on the vendors' own pages on Nov 3, 2026.
The numbers behind the decision (vendor pages, Nov 3, 2026)
$10
Copilot Pro per month
Unlimited completions, chat uses credits
2000
Free completions
Copilot Free, per month
19 GB
Local model download
Ollama qwen3-coder:30b
$0
Local model per month
Apache 2.0 licence
Can a free local model replace GitHub Copilot?
For most of what Copilot does, yes. Copilot is really three things now: inline suggestions as you type, a chat panel that explains and edits code, and agents that change several files for you. A local model covers the second and third well, and the first with a little extra setup.
Chat, edits and agents. Qwen3-Coder is built for this. Its model card says it "excels in tool calling capabilities" and lists support for coding tools such as Qwen Code and Cline. VS Code's own docs say local "BYOK models work without signing into a GitHub account and without a Copilot plan", so you can even keep the Copilot Chat panel you know and point it at a local model.
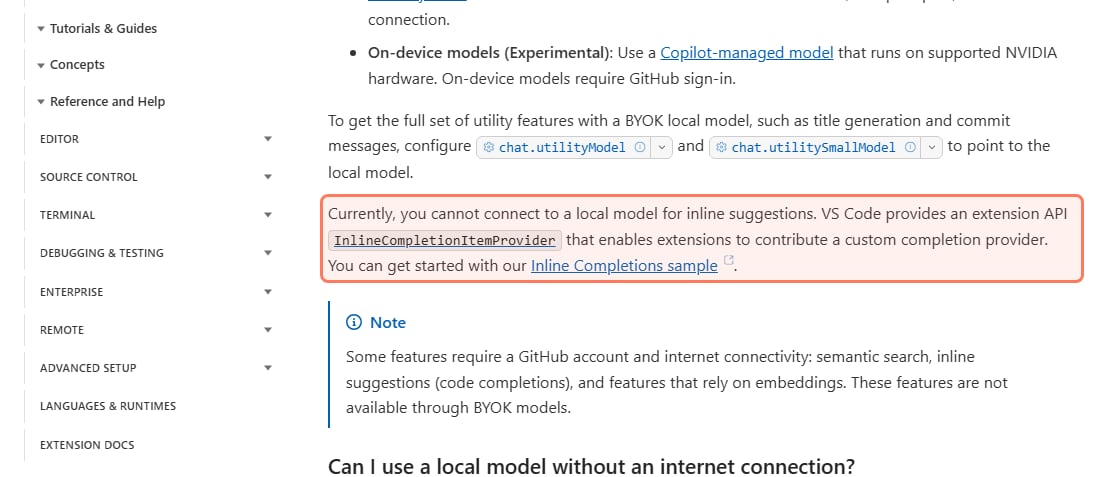
Tab-complete (inline suggestions). This is the part that doesn't carry over. VS Code says you cannot connect a local model for inline suggestions, and notes that inline suggestions need a GitHub account and an internet connection. The free route is an extension such as Continue, whose docs recommend ollama run qwen2.5-coder:1.5b for autocomplete because those models "are trained with a highly specific prompt format". Our VS Code setup guide walks through it.
Quality. Qwen publishes strong scores for its own models (for example 70.6 on SWE-bench Verified for Qwen3-Coder-Next on its model card). Those are the vendor's numbers, not ours, and we haven't benchmarked it against Copilot's models ourselves. Copilot's paid plans give you frontier models; a local 30B model is good, not identical.
The catch, in Microsoft's own words. VS Code docs, AI language models page, read Nov 3, 2026. · Screenshot of code.visualstudio.com by aliteq
What does GitHub Copilot cost now?
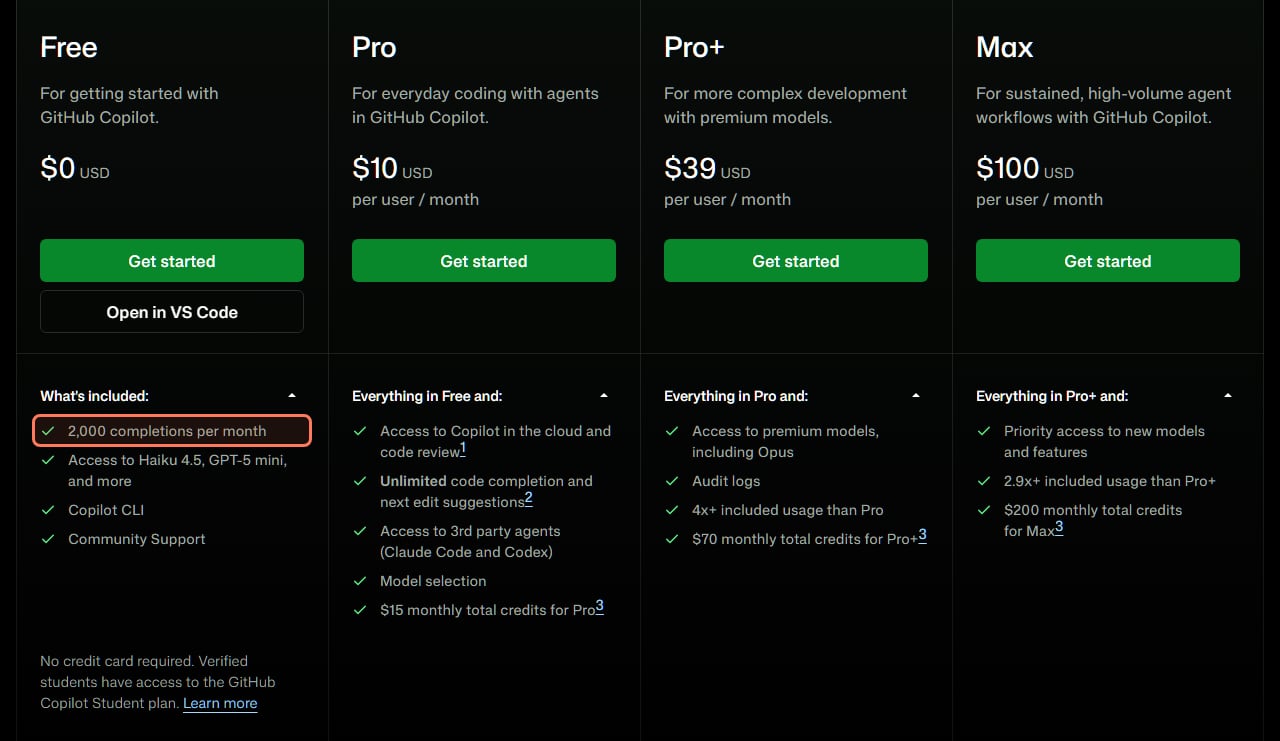
$0 to $100 a month for one person, after a billing change. GitHub moved Copilot to usage-based billing on June 1, 2026: inline completions stay unlimited on every paid plan, but chat and agent work now draws down monthly "GitHub AI Credits", where GitHub says 1 credit = $0.01. Here's what GitHub's plan page and billing docs listed on Nov 3, 2026.
Free
Price
$0
Inline completions
2,000 a month
Chat and agents
An allowance of AI credits, auto model selection only
Pro
Price
$10 per user / month
Inline completions
Unlimited
Chat and agents
1,500 AI credits a month (1,000 base + 500 flex)
Pro+
Price
$39 per user / month
Inline completions
Unlimited
Chat and agents
7,000 AI credits a month (3,900 base + 3,100 flex)
Max
Price
$100 per user / month
Inline completions
Unlimited
Chat and agents
20,000 AI credits a month (10,000 base + 10,000 flex)
Business
Price
$19 per user / month
Inline completions
Unlimited
Chat and agents
Admin-set usage limits
Enterprise
Price
$39 per user / month
Inline completions
Unlimited
Chat and agents
Admin-set usage limits
Price
Inline completions
Chat and agents
Free
$0
2,000 a month
An allowance of AI credits, auto model selection only
Pro
$10 per user / month
Unlimited
1,500 AI credits a month (1,000 base + 500 flex)
Pro+
$39 per user / month
Unlimited
7,000 AI credits a month (3,900 base + 3,100 flex)
Max
$100 per user / month
Unlimited
20,000 AI credits a month (10,000 base + 10,000 flex)
Business
$19 per user / month
Unlimited
Admin-set usage limits
Enterprise
$39 per user / month
Unlimited
Admin-set usage limits
GitHub's FAQ puts it plainly: "You use credits when you chat with Copilot and work with agents. Code completions and next edit suggestions don't use credits." GitHub also says the flex part of each allowance "may change over time". If you run out on a paid plan, GitHub's docs say "you can pay extra to keep working".
GitHub's own Copilot plan table, github.com/features/copilot/plans, read Nov 3, 2026. The Free plan's completion limit is outlined. · Screenshot of github.com by aliteq
What that means for this question: if you mostly use tab-complete and only chat now and then, Copilot Pro's $10 already gives you unlimited completions, and a local setup saves you $10 a month. If you lean on chat and agents all day, those are the parts that burn credits, and also the parts a local model replaces most easily.
Can I use a local model inside Copilot itself?
Yes, for chat. VS Code lets you bring your own model into the Copilot Chat panel, including local ones, and says these "work without signing into a GitHub account and without a Copilot plan". For Ollama, VS Code's docs now say "The built-in Ollama provider is deprecated" and point you to the official Ollama extension instead.
What you don't get that way: inline suggestions, semantic search and features that rely on embeddings. VS Code lists those as needing a GitHub account and internet, "not available through BYOK models". So the practical free stack in Nov 2026 is:
Ollama running qwen3-coder:30b for chat, edits and agent work.
Copilot Chat with a local model, or Continue / Cline, pointed at Ollama.
Continue's autocomplete with a small FIM-trained model such as qwen2.5-coder:1.5b, if you want ghost-text completions without Copilot.
Or keep Copilot Free for its 2,000 monthly completions and do everything else locally. That costs $0, but your typing still goes to GitHub.
Which local model, and what GPU do I need?
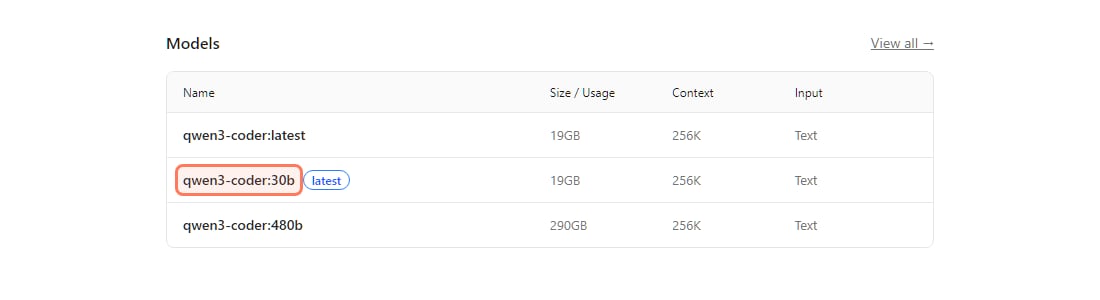
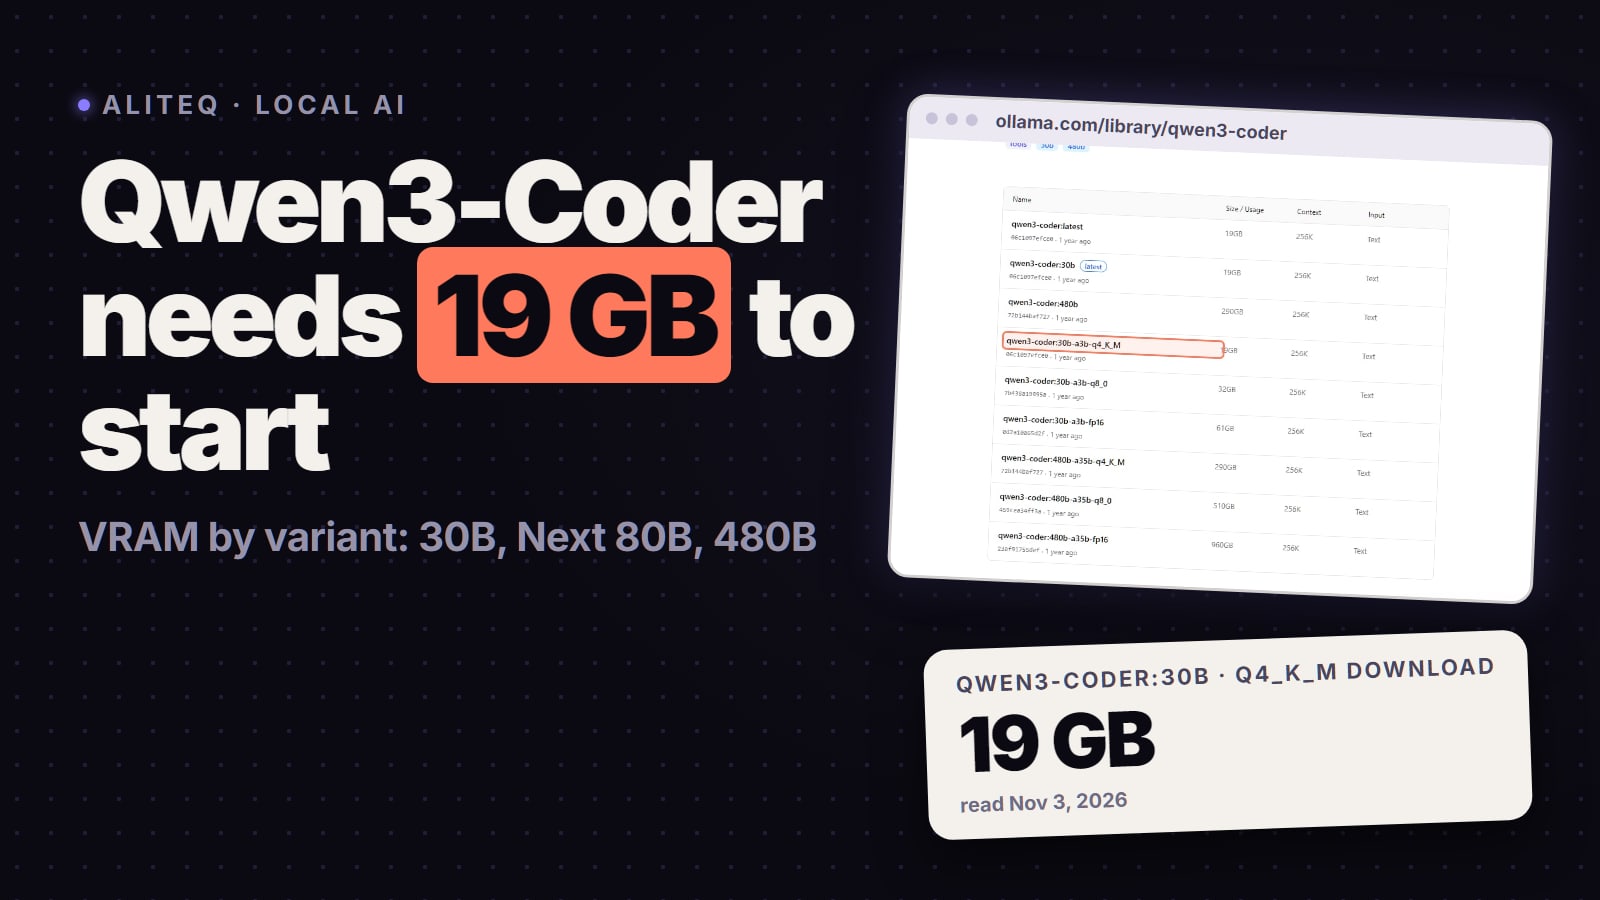
Qwen3-Coder 30B-A3B for most people, on a 24 GB GPU. Its model card lists "30.5B in total and 3.3B activated" parameters, a "Context Length: 262,144 natively" and an Apache 2.0 licence. Ollama's qwen3-coder:30b tag is a 19 GB download.
Ollama's qwen3-coder tags, ollama.com/library/qwen3-coder, read Nov 3, 2026. The 30B model is 19 GB; the 480B one is 290 GB and out of reach for a home PC. · Screenshot of ollama.com by aliteq
Qwen3-Coder 30B-A3B (Ollama `qwen3-coder:30b`)
Download
19 GB
Memory to plan for
A 24 GB GPU, with room left for context
Fits
RTX 3090, RTX 4090, or a Mac with enough unified memory
Same model, smaller quant (Unsloth Q3_K_M)
Download
14.7 GB
Memory to plan for
A 16 GB GPU, lower quality
Fits
16 GB cards, with a shorter context
Qwen3-Coder-Next 80B-A3B (Ollama)
Download
52 GB
Memory to plan for
Unsloth says ">45GB unified memory or RAM/VRAM" for 4-bit
Fits
Big-memory Macs, or a GPU plus system RAM offload
Qwen3-Coder 480B (Ollama)
Download
290 GB
Memory to plan for
Server hardware
Fits
Not a home setup
Download
Memory to plan for
Fits
Qwen3-Coder 30B-A3B (Ollama `qwen3-coder:30b`)
19 GB
A 24 GB GPU, with room left for context
RTX 3090, RTX 4090, or a Mac with enough unified memory
Same model, smaller quant (Unsloth Q3_K_M)
14.7 GB
A 16 GB GPU, lower quality
16 GB cards, with a shorter context
Qwen3-Coder-Next 80B-A3B (Ollama)
52 GB
Unsloth says ">45GB unified memory or RAM/VRAM" for 4-bit
Big-memory Macs, or a GPU plus system RAM offload
Qwen3-Coder 480B (Ollama)
290 GB
Server hardware
Not a home setup
Sizes are from Ollama's and Unsloth's pages, read Nov 3, 2026. A 19 GB model can't sit fully in a 16 GB card, which is why we say 24 GB. Long contexts need more memory on top of the weights; Unsloth's tip if you hit out-of-memory errors is "reducing the context length to a shorter value, such as 32,768". Check your own card in our VRAM calculator, see the best GPU for Qwen3-Coder, or read the used RTX 3090 guide if you're thinking of buying a 24 GB card. Our best local coding models guide covers the alternatives.
Is my code private with GitHub Copilot?
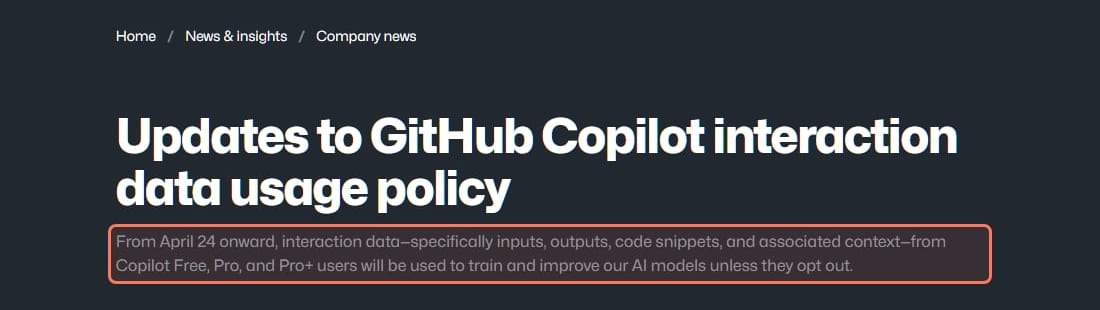
Less private than a local model, and GitHub changed the rules this year. On Mar 25, 2026 GitHub announced: "From April 24 onward, interaction data—specifically inputs, outputs, code snippets, and associated context—from Copilot Free, Pro, and Pro+ users will be used to train and improve our AI models unless they opt out." It adds that "Copilot Business and Copilot Enterprise users are not affected by this update", and that "Copilot does process code from private repositories when you are actively using Copilot."
GitHub's own announcement, github.blog, dated Mar 25, 2026, read Nov 3, 2026. · Screenshot of github.blog by aliteq
You can opt out under Privacy at github.com/settings/copilot. A local model avoids the question: the prompts, your code and the answers never leave your machine. For client work under an NDA, regulated code, or a company that bans sending source to third parties, that alone can settle it.
When does going local actually pay off?
When you already own a 24 GB GPU, or when privacy matters more than polish. The money side is small: Copilot Pro is $10 a month, $120 a year, so buying a GPU just to save that takes years to pay back. Renting is cheaper to test: on Nov 3, 2026 at 20:20 UTC our price tracker read RTX 3090s on Vast from about $0.10 an hour on-demand, so a four-hour test evening would come to well under a dollar at that rate. Prices move hourly; see today's on /cloud-gpu or the Qwen3-Coder cost page. Remember that storage on a stopped instance can still bill.
Go local if you have a 24 GB card (or a big-memory Mac), you want your code to stay on your machine, you work offline, or you use chat and agents heavily enough to hit Copilot's credit limits.
Keep Copilot if you want tab-complete that just works with no setup, you don't have the hardware, you want frontier models for hard problems, or your employer pays for Business or Enterprise (which GitHub says aren't trained on).
Or mix them. Copilot Free's 2,000 completions a month plus a local Qwen3-Coder for chat costs $0, though your completions still go through GitHub.
Local Qwen3-Coder vs GitHub Copilot (Nov 3, 2026)
Qwen3-Coder (local)
Free + private
vs
GitHub Copilot
Zero setup
$0 a month (you supply the GPU)
Cost
$0 Free, $10 Pro, $39 Pro+, $100 Max
Never leaves your machine
Privacy
Free/Pro/Pro+ trained on unless you opt out
Ollama + an extension, ~24 GB GPU
Setup
Sign in and go
Needs Continue + a small model
Tab-complete
Built in, unlimited on paid plans
Works offline
Offline
Needs internet
Strong open 30B model
Model strength
Frontier models on paid plans
(local) wins 3wins 3 Copilot
Quick answers
Can a free local model replace GitHub Copilot?
Mostly. A local Qwen3-Coder handles chat, code edits and agent work well, and VS Code lets local models into Copilot Chat without a Copilot plan. Tab autocomplete is the gap: VS Code says you can't connect a local model for inline suggestions, so you add an extension such as Continue with a small completion model like qwen2.5-coder:1.5b. You also need a GPU with about 24 GB of memory for the 30B model.
How much does GitHub Copilot cost in November 2026?
For individuals, GitHub's plan page lists Free at $0 (2,000 completions a month), Pro at $10, Pro+ at $39 and Max at $100 per user per month. Business is $19 and Enterprise $39 per user per month. Since June 2026, chat and agent work uses monthly AI credits (1 credit = $0.01) while completions stay unlimited on paid plans. Read Nov 3, 2026.
Can I use Ollama with GitHub Copilot?
In Copilot Chat, yes. VS Code supports bring-your-own models, including local ones, and says they work without a GitHub account or Copilot plan. Its built-in Ollama provider is deprecated, so install the official Ollama extension. Inline suggestions can't use a local model.
What GPU do I need to run Qwen3-Coder locally?
Ollama's qwen3-coder:30b is a 19 GB download, so plan on a 24 GB GPU such as an RTX 3090 or 4090, or a Mac with enough unified memory. Smaller quants (about 14.7 GB at Q3_K_M) squeeze onto 16 GB cards with some quality loss. Qwen3-Coder-Next is 52 GB in Ollama and needs a big-memory machine.
Does GitHub Copilot train on my code?
For Copilot Free, Pro and Pro+, GitHub says that from April 24, 2026 it uses interaction data (inputs, outputs, code snippets and context) to train its models unless you opt out at github.com/settings/copilot. Business and Enterprise users are not affected. A local model never sends your code anywhere.
Is local Qwen3-Coder as good as Copilot?
For everyday coding help it's close enough that many developers switch, but it isn't identical. Qwen's own model cards report strong benchmark scores, and Copilot's paid plans give access to frontier models that a 30B local model doesn't match on the hardest problems. Try it on your own code first, on your own GPU or a rented one for an hour.
The short version: a local Qwen3-Coder replaces Copilot's chat and agents for free and keeps your code private; tab-complete needs Continue and a small model; and you need about 24 GB of GPU memory. Check your card in the VRAM calculator, then follow our VS Code setup guide.