The Arc B580's 12GB holds every 8B model and 14B models at 4-bit, and Ollama now runs on it through Vulkan. The catch in November 2026 is the price: about $378 on eBay against a $249 list price, while a used RTX 3060 12GB with CUDA averaged $322.
Some links on this page are referral links: we may earn a commission, at no cost to you.
Share
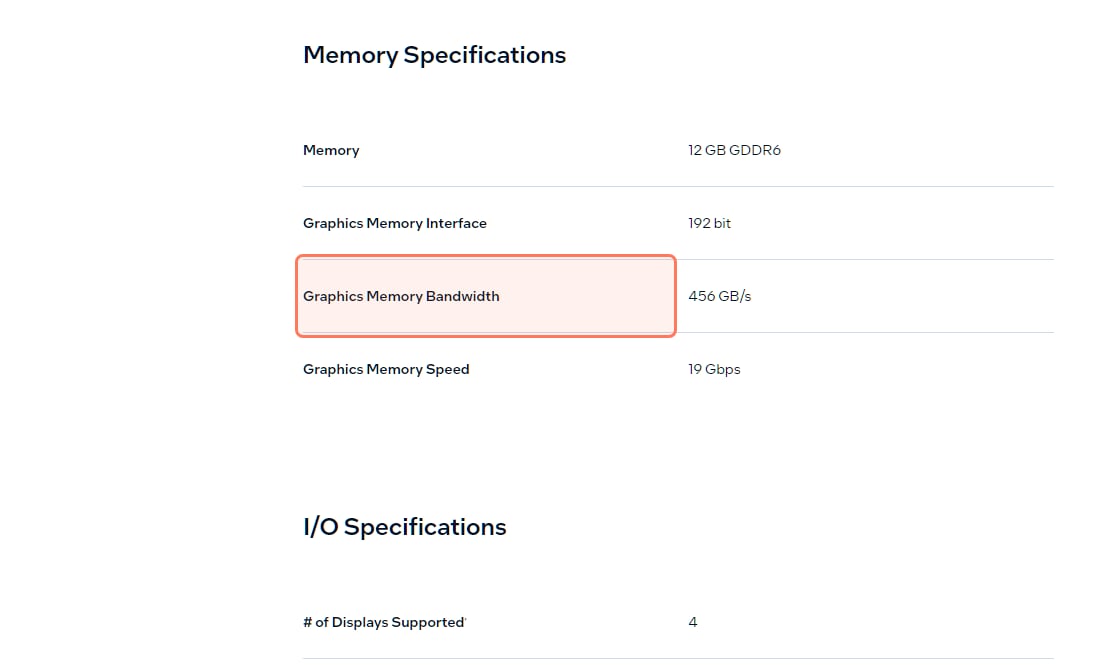
Is the Intel Arc B580 good for local AI? Yes, for 8B to 14B models. Intel lists the card with 12GB of GDDR6 and 456 GB/s of memory bandwidth, which holds every 8B model at high quality and 14B models such as Qwen3 14B at the common Q4_K_M quantization with 8K of context. Ollama's own docs now say its Vulkan support "is enabled by default", so you no longer need an Intel fork to get started. Two things hold it back. Models of 20B and up don't fit whole in 12GB. And on Nov 3, 2026 the card wasn't cheap any more: GPU Poet's November eBay reading put it at $378, against Intel's $249 list price, while a used RTX 3060 12GB with NVIDIA's CUDA averaged $322.
The Arc B580 in four numbers (read Nov 3, 2026)
12GB
GDDR6 VRAM
Intel spec page
456 GB/s
Memory bandwidth
Intel spec page
$249
Intel's recommended price
Intel spec page
$378
November eBay low average
GPU Poet, 3 lowest listings a day
What models fit in the Arc B580's 12GB?
Every model up to about 9B fits with room to spare, 12B to 14B models fit at 4-bit with normal context, and 20B and larger don't fit on the card alone. The numbers below come from our VRAM calculator's engine: model weights at the given quantization, plus the KV cache for 8,192 tokens of context at FP16, plus about 0.8 GB of runtime overhead. They're estimates for llama.cpp-style GGUF files, not measurements on a B580, and the overhead figure is calibrated on NVIDIA cards, so leave a little headroom.
Llama 3.2 3B
Best quant that fits (8K context)
F16
VRAM needed
~7.6 GB
At Q4_K_M
~3.5 GB
Verdict on 12GB
Fits easily
Llama 3.1 8B
Best quant that fits (8K context)
Q8_0
VRAM needed
~9.7 GB
At Q4_K_M
~6.3 GB
Verdict on 12GB
Fits easily
Qwen3 8B
Best quant that fits (8K context)
Q8_0
VRAM needed
~10.0 GB
At Q4_K_M
~6.5 GB
Verdict on 12GB
Fits easily
Gemma 3 12B
Best quant that fits (8K context)
Q6_K
VRAM needed
~10.6 GB
At Q4_K_M
~8.2 GB
Verdict on 12GB
Fits
Qwen3 14B
Best quant that fits (8K context)
Q5_K_M (tight)
VRAM needed
~11.8 GB
At Q4_K_M
~10.4 GB
Verdict on 12GB
Fits at Q4_K_M
Phi-4 14B
Best quant that fits (8K context)
Q5_0 (tight)
VRAM needed
~11.8 GB
At Q4_K_M
~10.6 GB
Verdict on 12GB
Fits at Q4_K_M
gpt-oss-20b
Best quant that fits (8K context)
IQ4_XS (tight)
VRAM needed
~11.5 GB
At Q4_K_M
~13.0 GB
Verdict on 12GB
Not whole; offload part to RAM
Mistral Small 24B
Best quant that fits (8K context)
Q2_K (tight)
VRAM needed
~11.2 GB
At Q4_K_M
~15.3 GB
Verdict on 12GB
No, needs 16GB+
Qwen3 30B-A3B
Best quant that fits (8K context)
none
VRAM needed
n/a
At Q4_K_M
~18.8 GB
Verdict on 12GB
No; MoE offload only
Qwen3 32B
Best quant that fits (8K context)
none
VRAM needed
n/a
At Q4_K_M
~21.3 GB
Verdict on 12GB
No, needs 24GB
Best quant that fits (8K context)
VRAM needed
At Q4_K_M
Verdict on 12GB
Llama 3.2 3B
F16
~7.6 GB
~3.5 GB
Fits easily
Llama 3.1 8B
Q8_0
~9.7 GB
~6.3 GB
Fits easily
Qwen3 8B
Q8_0
~10.0 GB
~6.5 GB
Fits easily
Gemma 3 12B
Q6_K
~10.6 GB
~8.2 GB
Fits
Qwen3 14B
Q5_K_M (tight)
~11.8 GB
~10.4 GB
Fits at Q4_K_M
Phi-4 14B
Q5_0 (tight)
~11.8 GB
~10.6 GB
Fits at Q4_K_M
gpt-oss-20b
IQ4_XS (tight)
~11.5 GB
~13.0 GB
Not whole; offload part to RAM
Mistral Small 24B
Q2_K (tight)
~11.2 GB
~15.3 GB
No, needs 16GB+
Qwen3 30B-A3B
none
n/a
~18.8 GB
No; MoE offload only
Qwen3 32B
none
n/a
~21.3 GB
No, needs 24GB
Ollama's own download sizes agree with the shape of that table: on Nov 3, 2026 its library listed qwen3:8b at 5.2GB, qwen3:14b at 9.3GB, qwen3:30b at 19GB, qwen3:32b at 20GB and gpt-oss:20b at 14GB. Anything bigger than about 11GB on disk won't sit entirely in the B580's memory once context is added.
Two limits worth knowing before you buy:
Context eats the margin on 14B models. At 32K tokens of context, our engine puts Qwen3 14B at Q4_K_M at about 14.1 GB, which no longer fits. On a 12GB card, 14B models are an 8K-to-16K-context proposition. 8B models still fit at 32K (Qwen3 8B at Q4_K_M is about 9.9 GB).
MoE models can run with part of the model in system RAM. gpt-oss-20b and Qwen3 30B-A3B are mixture-of-experts models, so llama.cpp can keep the expert weights in your PC's RAM and the rest on the GPU. It works, but you trade speed for size. How that works: running gpt-oss-20b on an 8GB or 12GB GPU and what `--n-cpu-moe` actually does.
Intel's own Arc B580 spec page, read Nov 3, 2026. The same page lists 20 Xe-cores, 160 XMX engines, 233 peak INT8 TOPS, 190 W total board power and a $249 recommended price. · Screenshot of intel.com by aliteq
Does Ollama work on the Intel Arc B580?
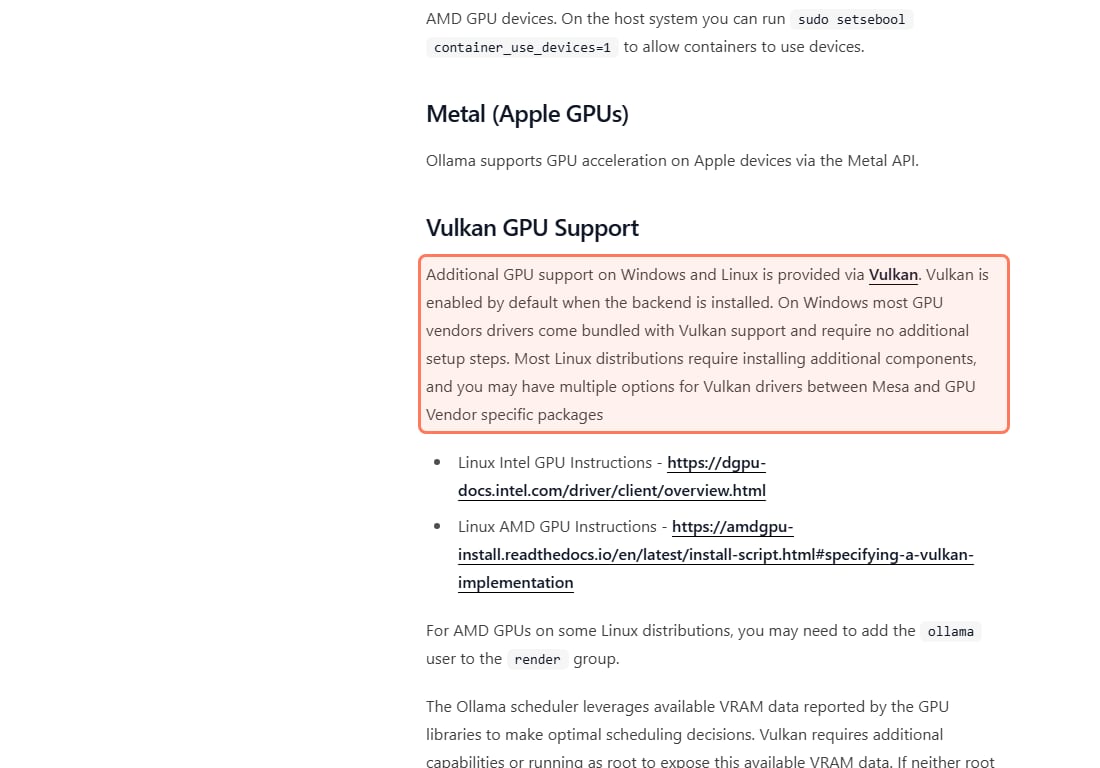
Yes, through Vulkan. Ollama's hardware page says: "Additional GPU support on Windows and Linux is provided via Vulkan. Vulkan is enabled by default when the backend is installed. On Windows most GPU vendors drivers come bundled with Vulkan support and require no additional setup steps." On Linux it adds that "Most Linux distributions require installing additional components", and it links Intel's GPU driver instructions.
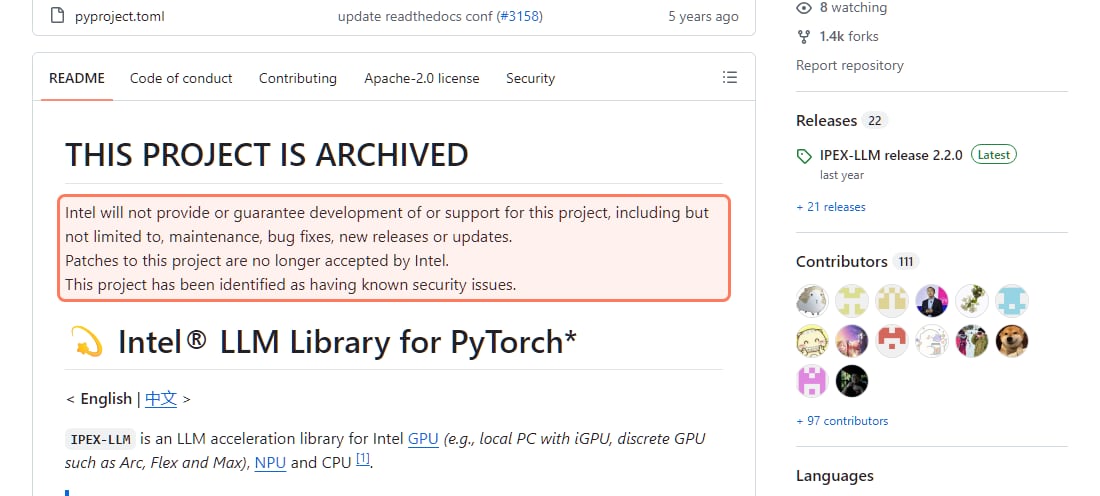
That changes the older advice, which said to install Intel's own patched Ollama from its IPEX-LLM project. Don't build on that path today. Intel archived the IPEX-LLM repository, and its README now opens with "THIS PROJECT IS ARCHIVED" and says: "Intel will not provide or guarantee development of or support for this project, including but not limited to, maintenance, bug fixes, new releases or updates." It also says the project "has been identified as having known security issues." Intel's Extension for PyTorch repository carries the same archived notice.
Ollama's GPU docs, read Nov 3, 2026 (page last modified Oct 27, 2026). Vulkan is how an Arc card runs in stock Ollama. · Screenshot of docs.ollama.com by aliteq
Intel's IPEX-LLM repository, read Nov 3, 2026. Older Arc guides send you here; Intel no longer supports it. · Screenshot of github.com/intel/ipex-llm by aliteq
What else runs on it: llama.cpp, PyTorch and ComfyUI
The supported paths in November 2026 are all upstream projects, not Intel forks:
llama.cpp has two Intel routes. Its SYCL backend docs list "Intel Arc B-Series" as supported with the Arc B580 as the verified model, and the project README lists Vulkan as a GPU backend too.
PyTorch lists "Intel® Arc™ B-Series Graphics (CodeName: Battlemage)" as validated hardware for its Intel GPU (XPU) builds on Windows 11, Ubuntu and WSL2, in the PyTorch 2.15 docs.
ComfyUI, the image-generation tool, has a "Portable for Intel GPUs" download for Windows and tells Arc users to install PyTorch's XPU build with pip.
What you give up is the CUDA default. Most tutorials, Docker images and day-one model releases assume an NVIDIA card, so on Arc you'll more often be the one working out a driver or backend setting. Our longer piece on the B580's software tax covers that setup in detail.
How fast is the Arc B580 for local LLMs?
Usable for chat on 8B to 14B models, but slower than NVIDIA's current cards. Phoronix ran llama.cpp's Vulkan backend on Linux in December 2025 and wrote that "the Arc B580 itself remains much slower than the likes of the RX 9060 XT and RTX 5060 Ti", and that "Even at $249 USD, the Arc B580 was in last place for the performance-per-dollar in this benchmark." A June 2026 Phoronix follow-up found "some significant speed-ups to find with Intel ANV for Llama.cpp on Mesa 26.1, especially around the text generation speed", so a current Linux driver stack matters.
For a ceiling: generating text is limited mostly by memory bandwidth, and our engine's bandwidth formula gives the B580 an upper bound of roughly 70 tokens a second on an 8B model at Q4_K_M and roughly 38 on a 14B model. That is a theoretical ceiling, not a benchmark; real speeds depend on the backend and driver and come in below it.
Is the Arc B580 worth it for local AI in November 2026?
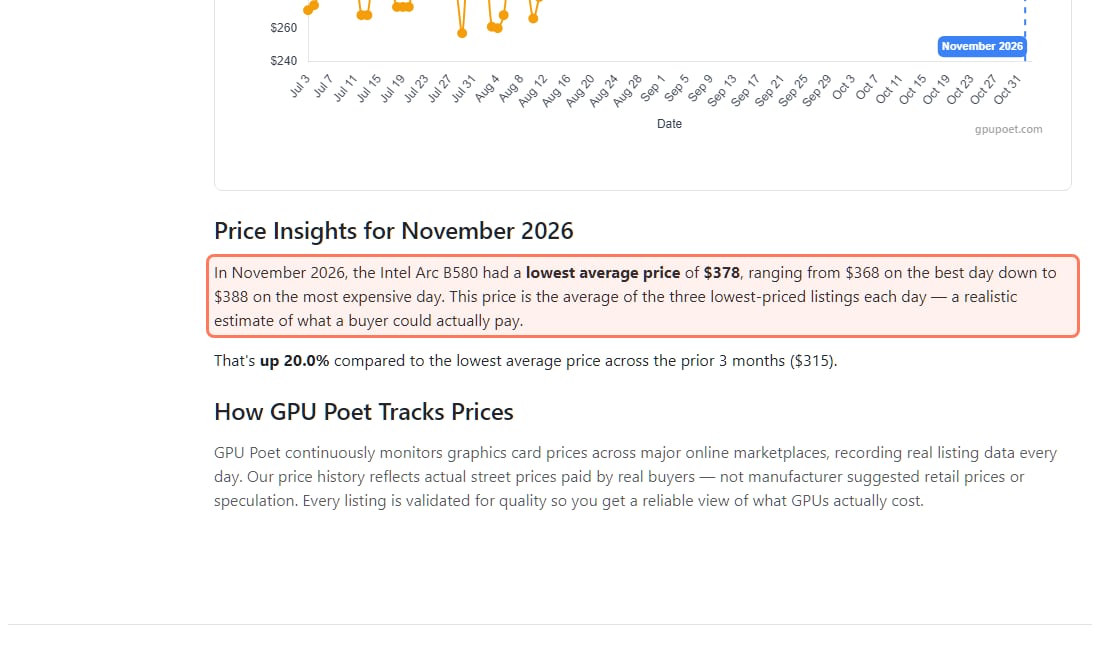
Only near its list price, or if you specifically want a new card. Intel's spec page still lists the B580 at $249, but when we read GPU Poet's tracker of eBay listings on Nov 3, 2026, it put the card's November lowest average at $378, "up 20.0%" on the prior three months ($315). The same tracker put a used NVIDIA RTX 3060 12GB at $322 that day. The monthly figure updates as November goes on, so check the tracker for today's number. Both have 12GB, so both run the same models in the table above; the 3060 adds CUDA, where every local-AI tool works first.
GPU Poet's November 2026 B580 reading (eBay listings, average of the three lowest each day), read Nov 3, 2026. · Screenshot of gpupoet.com by aliteq
Intel Arc B580 (new)
VRAM
12GB GDDR6
Price read Nov 3, 2026
$249 list; $378 eBay low average
Software
Vulkan, SYCL, PyTorch XPU
Pick it if
You find it near list price and want a new card with a warranty
NVIDIA RTX 3060 12GB (used)
VRAM
12GB
Price read Nov 3, 2026
$322 eBay low average
Software
CUDA
Pick it if
You want the same 12GB with the fewest setup surprises
A 16GB card, such as the RTX 5060 Ti 16GB
VRAM
16GB
Price read Nov 3, 2026
Well above both
Software
CUDA
Pick it if
You want gpt-oss-20b or 24B models fully on the GPU
VRAM
Price read Nov 3, 2026
Software
Pick it if
Intel Arc B580 (new)
12GB GDDR6
$249 list; $378 eBay low average
Vulkan, SYCL, PyTorch XPU
You find it near list price and want a new card with a warranty
NVIDIA RTX 3060 12GB (used)
12GB
$322 eBay low average
CUDA
You want the same 12GB with the fewest setup surprises
A 16GB card, such as the RTX 5060 Ti 16GB
16GB
Well above both
CUDA
You want gpt-oss-20b or 24B models fully on the GPU
6/ 10
Verdict
Good card, wrong price right now
The Arc B580 runs 8B to 14B models well in its 12GB, and Ollama now supports it through Vulkan without an Intel fork. But it's slower than NVIDIA's cards in llama.cpp, and at $378 on eBay it costs more than a used RTX 3060 12GB that runs the same models on CUDA.
Best for: Buyers who find it close to Intel's $249 list price, want a new card rather than a used one, and don't mind setting up Vulkan or SYCL.
Intel Arc B580 Limited Edition 12GB
Intel's own Arc B580 with 12GB of GDDR6, per Intel. Compare the listing with Intel's $249 list price and a used RTX 3060 12GB before you buy.
Rent the bigger card for an hour before you buy one. If you want Qwen3 32B or Mistral Small 24B fully on a GPU, you need 16GB to 24GB. On Nov 3, 2026 (20:20 UTC) our price tracker's cheapest single RTX 3090 24GB on Vast.ai was about $0.10 an hour on demand; prices move hourly, so check today's cloud GPU prices.
Arc B580 for local AI: quick answers
Is the Intel Arc B580 good for running LLMs?
Yes, for 8B to 14B models. Its 12GB holds every 8B model at Q8_0 and 14B models like Qwen3 14B at Q4_K_M with 8K of context, per our VRAM engine. It's slower than NVIDIA's current cards in Phoronix's llama.cpp tests, and 20B+ models don't fit whole.
Can the Arc B580 run gpt-oss-20b?
Not entirely on the card. Ollama's gpt-oss:20b download is 14GB, more than the B580's 12GB. llama.cpp can keep part of the mixture-of-experts weights in system RAM and run it that way, at lower speed. A 16GB card runs it fully on the GPU.
Can the Arc B580 run 13B or 14B models?
Yes, at 4-bit. Our engine puts Qwen3 14B at Q4_K_M at about 10.4 GB with 8K context, which fits. At 32K context it grows to about 14.1 GB and doesn't. Keep context to roughly 8K-16K on 14B models.
Do I still need IPEX-LLM to use Ollama on an Arc GPU?
No. Ollama's docs say Vulkan support is enabled by default and needs no extra setup on Windows; Linux needs Intel's GPU drivers installed. Intel has archived IPEX-LLM and says it no longer supports the project, which it also says has known security issues.
Arc B580 or a used RTX 3060 12GB for local AI?
On Nov 3, 2026 prices, the used RTX 3060 12GB: GPU Poet's November eBay low average was $322 for it and $378 for the B580. Both have 12GB and run the same models; the 3060 has CUDA. The B580 makes sense near its $249 list price or if you want a new card.
Is the Arc B580 good for Stable Diffusion or ComfyUI?
It's supported. ComfyUI offers a portable Windows download for Intel GPUs and installs PyTorch's XPU build, and PyTorch lists Arc B-Series as validated hardware. Expect fewer ready-made guides than for NVIDIA cards.
The short version: the Arc B580 is a capable 12GB card for 8B to 14B models, and its software story is better than a year ago because Ollama, llama.cpp and PyTorch support it upstream. In November 2026 its price is the problem, not its memory. Check any model against your own card in the VRAM calculator before you buy.