Gemma 4 12B at Q6_K is the 12GB pick that still leaves room for long chats. Qwen3.8 27B can squeeze in at a 3-bit quant with short context, and bigger MoE models run if your system RAM is large. Here is what fits, on our numbers.
Some links on this page are referral links: we may earn a commission, at no cost to you.
Share
On a 12GB card like the RTX 3060 12GB or RTX 4070, the best all-round local model in November 2026 is Gemma 4 12B at Q6_K: on our VRAM numbers it uses about 10.0 GB with 8K tokens of context and about 10.4 GB with 32K, so it fits comfortably, handles images, and keeps a long chat on the card. Qwen3.5 9B at near-lossless Q8_0 is the other easy fit. The new Qwen3.8 27B does squeeze onto 12GB, but only at IQ3_XS with 8K of context (about 12.0 GB, with no margin), so treat it as a stretch, not a default.
What fits a 12GB card, on our numbers
Gemma 4 12B
Best fit at 8K context
Q6_K, ~10.0 GB
Best fit at 32K context
Q6_K, ~10.4 GB
Notes
The all-rounder; vision input
Qwen3.5 9B
Best fit at 8K context
Q8_0, ~10.6 GB
Best fit at 32K context
Q8_0, ~11.3 GB (tight)
Notes
Q6_K holds 64K in ~10.2 GB
Gemma 4 E4B
Best fit at 8K context
Q8_0, ~8.8 GB
Best fit at 32K context
Q8_0, ~9.2 GB
Notes
Most headroom
Qwen3-14B
Best fit at 8K context
Q4_K_M, ~10.4 GB
Best fit at 32K context
Q2_K only
Notes
Short context only
Phi-4 14B
Best fit at 8K context
Q4_K_M, ~10.6 GB
Best fit at 32K context
does not fit
Notes
Short context only
gpt-oss-20b
Best fit at 8K context
IQ4_XS, ~11.5 GB (tight)
Best fit at 32K context
Q3_K_M, ~11.8 GB (tight)
Notes
Fast MoE, but no room
Qwen3.8 27B
Best fit at 8K context
IQ3_XS, ~12.0 GB (tight)
Best fit at 32K context
does not fit
Notes
Stretch pick
Best fit at 8K context
Best fit at 32K context
Notes
Gemma 4 12B
Q6_K, ~10.0 GB
Q6_K, ~10.4 GB
The all-rounder; vision input
Qwen3.5 9B
Q8_0, ~10.6 GB
Q8_0, ~11.3 GB (tight)
Q6_K holds 64K in ~10.2 GB
Gemma 4 E4B
Q8_0, ~8.8 GB
Q8_0, ~9.2 GB
Most headroom
Qwen3-14B
Q4_K_M, ~10.4 GB
Q2_K only
Short context only
Phi-4 14B
Q4_K_M, ~10.6 GB
does not fit
Short context only
gpt-oss-20b
IQ4_XS, ~11.5 GB (tight)
Q3_K_M, ~11.8 GB (tight)
Fast MoE, but no room
Qwen3.8 27B
IQ3_XS, ~12.0 GB (tight)
does not fit
Stretch pick
"Tight" means over 90% of the card. It loads, but anything else on the GPU can push it over. The table shows the quant we would actually run; for some models a bigger quant technically fits at 8K with no margin. The VRAM calculator shows every quant for any context length.
Why Gemma 4 12B, not Qwen3-14B
For two years the 12GB answer was "a 14B model at Q4". The problem is context. Qwen3-14B keeps a full KV cache on all 40 layers, about 160 MB per 1,000 tokens at fp16 on our numbers, so by 32K it no longer fits at Q4_K_M. Gemma 4 12B keeps a growing cache on only 8 of its 48 layers (the rest use a 1,024-token sliding window), about 16 MB per 1,000 tokens. That is why it holds 32K at Q6_K with room to spare. Qwen3-14B is still a good model; it just suits short chats on this card.
On 12GB, attention design now decides how much context you keep, not just parameter count. · Unsplash
Qwen3.8 27B on 12GB: possible, with limits
Qwen3.8 27B is a dense 27B model with vision input, a 262,144-token native context and an Apache-2.0 licence, per Qwen's model card. Its weights at IQ3_XS come to about 10.7 GB on our numbers, so on 12GB it fits only with short context and nothing else on the GPU. Full numbers: cost to run Qwen3.8 27B.
People are pushing it further. A r/LocalLLM user reported running a Q3-XXS GGUF of Qwen3.8 27B on 12GB of VRAM and 16GB of RAM with 150K of context at 11 tokens per second, using a q4_0 KV cache. By our arithmetic, 150K tokens of KV cache at roughly 4 bits is still 2 to 3 GB on top of the weights, so part of that setup has to sit in system RAM. It works, but you are trading quality (a 3-bit quant and a 4-bit cache) and speed for context.
RAM matters now: bigger MoE models on 12GB
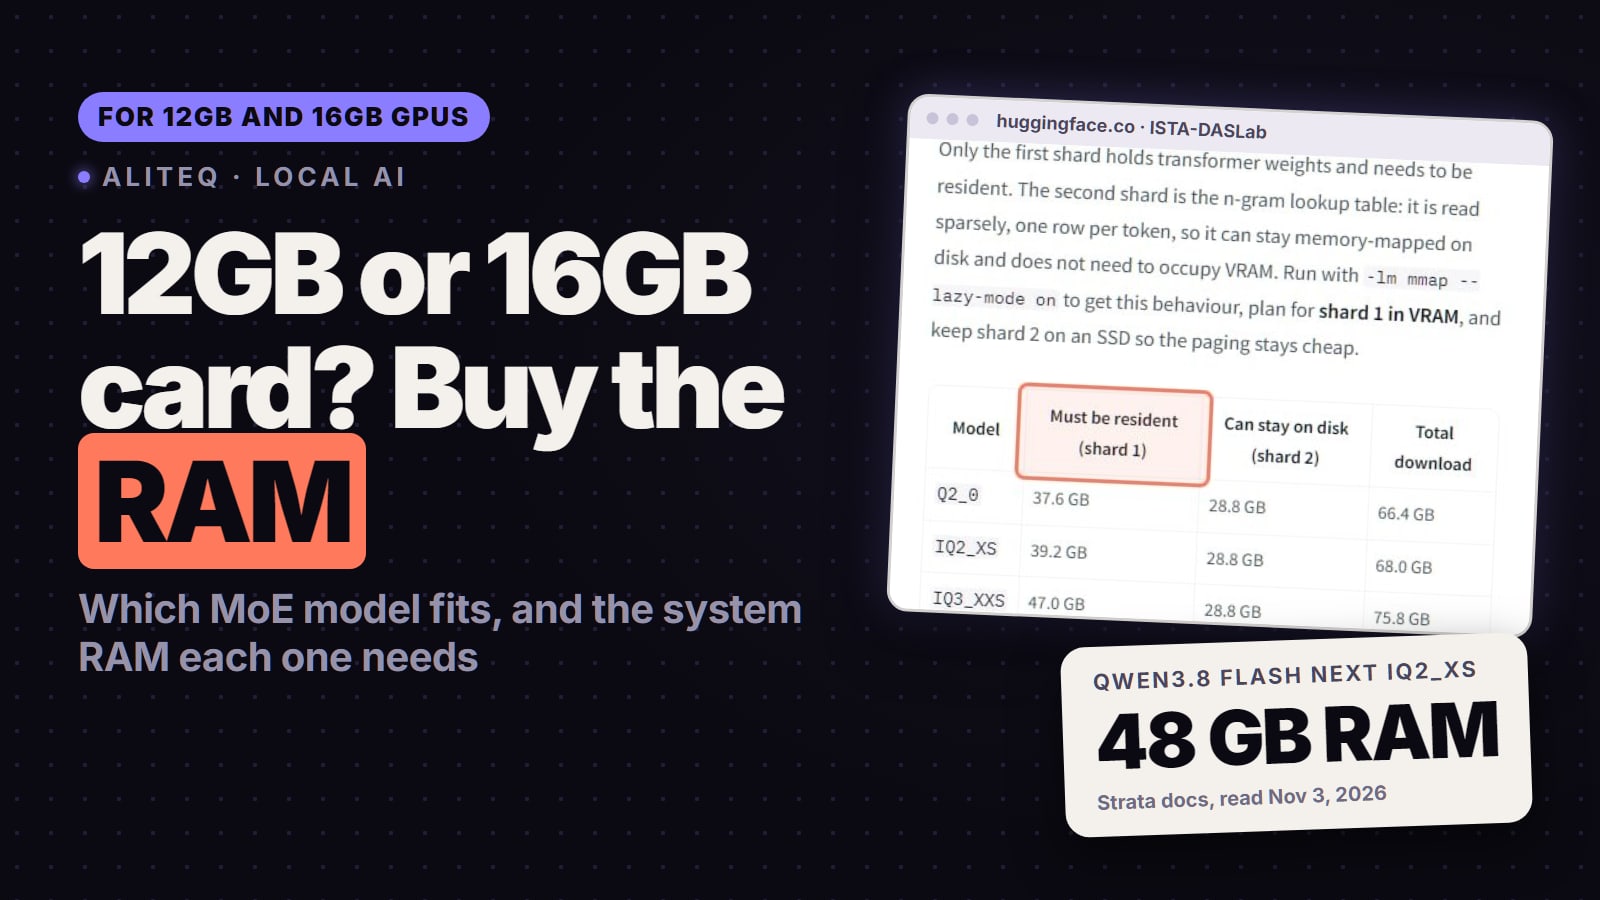
Mixture-of-experts models use only a few experts per token, so engines can keep the busy parts on the GPU and the rest in system RAM. On a 12GB card that is how you reach models such as Qwen3.6 35B-A3B or Qwen3.8 Flash Next. How far you get depends on your RAM, and our guide to MoE models on 12GB and 16GB cards works through it with llama.cpp.
The Strata engine publishes its own test table. On an RTX 3060 12GB with 46GB of RAM it lists DeepSeek V4.1 Flash 1017 at a 2.00-bit quant generating 9 to 11 tokens per second, measured on Strata 0.2.5 per its README. That is the vendor's number, at a very low quant, on a model whose download is roughly 239 to 274 GB. It shows what is possible, not what is comfortable.
The trade-offs are the same everywhere: low quants, more setup, and slower replies whenever part of the model lives in RAM or on the SSD.
Getting the most from 12GB
Pick the model by context, not just size. If you want long chats or documents, a hybrid-attention model (Gemma 4, Qwen3.5) keeps far more context in the same memory.
Stay at Q4_K_M or above for daily use. Drop to a 3-bit quant only to fit a model that is worth it, like Qwen3.8 27B.
If it crawls, it spilled. A model that loads but runs far slower than expected has part of itself or its KV cache in system RAM. Shorten the context or drop a quant.
Compare tiers. The VRAM ladder puts 8GB, 12GB, 16GB and 24GB side by side.
The image that ran with an earlier version of this guide.
Quick answers
What is the best local LLM for a 12GB GPU in November 2026?
On our numbers, Gemma 4 12B at Q6_K. It fits with 32K of context in about 10.4 GB and handles images. Qwen3.5 9B at Q8_0 is the other comfortable pick.
Can a 12GB GPU run Qwen3.8 27B?
Just about. At IQ3_XS with 8K context it needs about 12.0 GB on our estimate, so it fits with nothing else on the GPU. Longer context means offloading to system RAM, which slows it down.
Can a 12GB GPU still run 14B models?
Yes, at Q4_K_M with short context. Qwen3-14B needs about 10.4 GB at 8K, but its KV cache grows fast, so at 32K it no longer fits at Q4_K_M.
Is 12GB enough for local AI?
For most chat, writing and coding help, yes. You only hit the wall with 27B-class models at long context, or the big MoE models, which need 24GB of VRAM or lots of system RAM.
On 12GB, start with Gemma 4 12B at Q6_K, try Qwen3.8 27B when you want more depth on short prompts, and compare the 8GB and 16GB guides if you are deciding on a card. The RTX 3060 12GB is still the budget card for this tier.