The RTX 5070 Ti runs 14B models and gpt-oss-20b fast on 16GB, but on Nov 3, 2026 the cheapest eBay listings averaged about $1,328, 77% over its $749 launch price. What it runs, measured speeds, and the cheaper ways to get the same job done.
Some links on this page are referral links: we may earn a commission, at no cost to you.
Share
Is the RTX 5070 Ti worth it for local AI? Only if you can buy it near its $749 launch price. Its 16GB of GDDR7 runs every 7–14B model and gpt-oss-20b fast: hardware-corner.net measured 58.0 tokens/sec on Qwen3-14B at 16k context, about 76% faster than the 16GB RTX 5060 Ti. But it can't hold 27–32B dense models, which need 24GB. And on Nov 3, 2026 it wasn't selling near $749: GPU Poet's November reading of eBay listings put it at $1,328, close to what a 24GB RTX 3090 cost ($1,502).
The RTX 5070 Ti in four numbers (read Nov 3, 2026)
16GB
GB of GDDR7 memory
NVIDIA's spec page
$749
Launch price
NVIDIA's price at launch, Jan 2025
$1328
November 2026 street price
GPU Poet, eBay lowest average
$0.16
Rent one per hour
Vast.ai, on-demand, 21:20 UTC
Is the RTX 5070 Ti good for local AI?
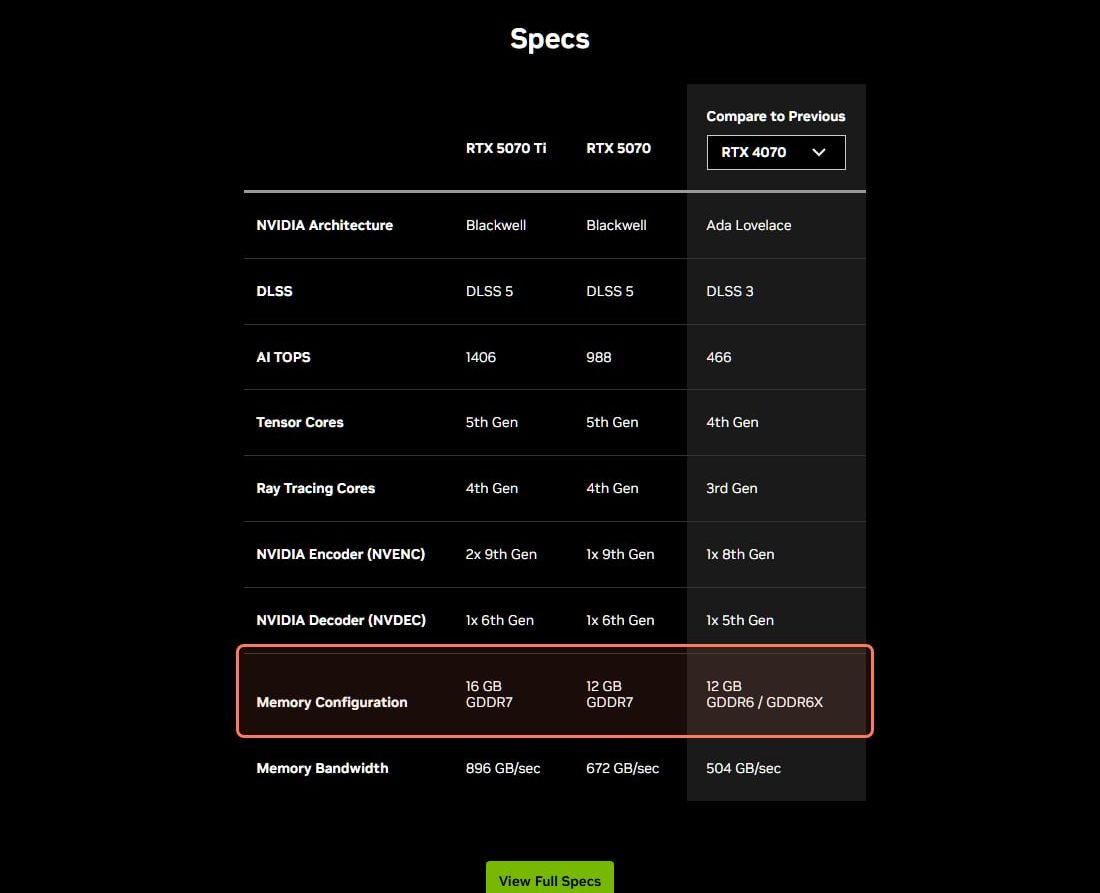
Yes. It's one of the fastest 16GB cards you can buy, and memory speed is what sets how fast a local model types. NVIDIA's spec page lists the RTX 5070 Ti with 16GB of GDDR7 at 896 GB/sec, against 672 GB/sec for the 12GB RTX 5070. It's a Blackwell card, so it has the fifth-generation Tensor Cores that accelerate NVFP4, NVIDIA's 4-bit format, and every local-AI tool (Ollama, LM Studio, llama.cpp, ComfyUI) supports it through CUDA.
NVIDIA's own RTX 5070 family spec table (nvidia.com), read Nov 3, 2026. The RTX 5070 Ti is the first column. · Screenshot of nvidia.com by aliteq
What can the RTX 5070 Ti's 16GB run?
Every 7–14B model at Q4 with room for long context, gpt-oss-20b, and image models like SDXL and FLUX at reduced precision. It can't load 27–32B dense models fully into memory. Here's the map:
7–8B models (Qwen3-8B, Llama 3.1 8B): easily, even at 64k context. Hardware-corner.net measured 87.5 tokens/sec on Qwen3-8B at 16k.
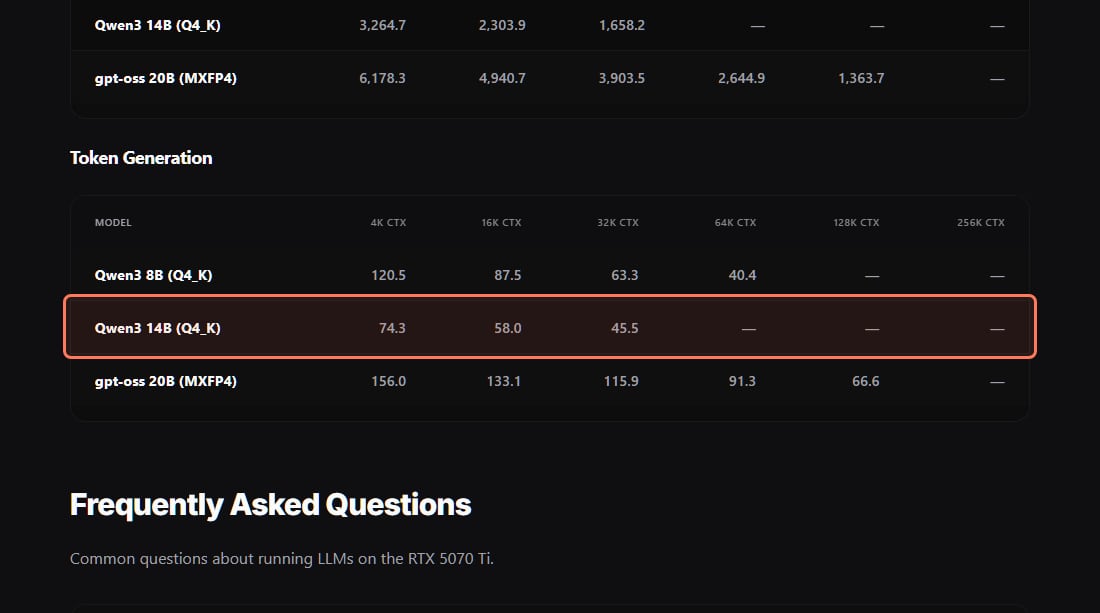
14B models (Qwen3-14B): comfortably at Q4. 58.0 tokens/sec at 16k context, 45.5 at 32k.
gpt-oss-20b: yes, and it's the fastest model on the card: 133.1 tokens/sec at 16k context and 66.6 at 128k in hardware-corner.net's tests. Our gpt-oss-20b guide covers the setup.
Bigger MoE models (Qwen3-30B-A3B and similar): not fully on the card at Q4, but llama.cpp can keep the expert layers in system RAM and still run at usable speed. See what n-cpu-moe actually does and the best MoE models for 16GB.
27–32B dense models (Qwen3-32B, Gemma-class 27B): no. At Q4 they need about 20GB, so they spill into system RAM and slow to a crawl. That's a 24GB job.
A 32B model at Q4 needs about 20GB, so it doesn't fit the 5070 Ti. 14B models (about 10GB) fit with room for context.
How fast is the RTX 5070 Ti for local LLMs?
About 58 tokens a second on a 14B model at 16k context, far faster than you can read. These are hardware-corner.net's llama.cpp measurements (page updated March 2026), not tests we ran:
Hardware-corner.net's llama.cpp token-generation table for the RTX 5070 Ti (page updated March 2026), read Nov 3, 2026. The Qwen3 14B row is outlined. · Screenshot of hardware-corner.net by aliteq
RTX 5070 Ti vs the cards buyers compare it with (read Nov 3, 2026)
eBay lowest average, Nov 2026 (GPU Poet)
RTX 5070 Ti 16GB
$1,328
RTX 5060 Ti 16GB
$706
RTX 3090 24GB (used)
$1,502
VRAM
RTX 5070 Ti 16GB
16GB GDDR7
RTX 5060 Ti 16GB
16GB GDDR7
RTX 3090 24GB (used)
24GB GDDR6X
Qwen3-14B Q4_K at 16k context*
RTX 5070 Ti 16GB
58.0 tokens/sec
RTX 5060 Ti 16GB
32.9 tokens/sec
RTX 3090 24GB (used)
Not on these pages
gpt-oss-20b at 16k context*
RTX 5070 Ti 16GB
133.1 tokens/sec
RTX 5060 Ti 16GB
82.4 tokens/sec
RTX 3090 24GB (used)
Not on these pages
Runs 27–32B dense models
RTX 5070 Ti 16GB
No
RTX 5060 Ti 16GB
No
RTX 3090 24GB (used)
Yes
Verdict
RTX 5070 Ti 16GB
Fastest 16GB, overpriced now
RTX 5060 Ti 16GB
Same models, half the price
RTX 3090 24GB (used)
Bigger models, used only
RTX 5070 Ti 16GB
RTX 5060 Ti 16GB
RTX 3090 24GB (used)
eBay lowest average, Nov 2026 (GPU Poet)
$1,328
$706
$1,502
VRAM
16GB GDDR7
16GB GDDR7
24GB GDDR6X
Qwen3-14B Q4_K at 16k context*
58.0 tokens/sec
32.9 tokens/sec
Not on these pages
gpt-oss-20b at 16k context*
133.1 tokens/sec
82.4 tokens/sec
Not on these pages
Runs 27–32B dense models
No
No
Yes
Verdict
Fastest 16GB, overpriced now
Same models, half the price
Bigger models, used only
*Speeds are hardware-corner.net's llama.cpp measurements for the RTX 5070 Ti and RTX 5060 Ti 16GB (both updated March 2026). Prices are GPU Poet's November 2026 month-to-date figures as read on Nov 3, 2026: the average of the three lowest-priced eBay listings each day. They are asking prices, not sold prices, and they move as the month goes on. GPU Poet's RTX 5060 Ti page doesn't split the 16GB and 8GB versions, so check a listing says 16GB.
Is the RTX 5070 Ti worth $1,300?
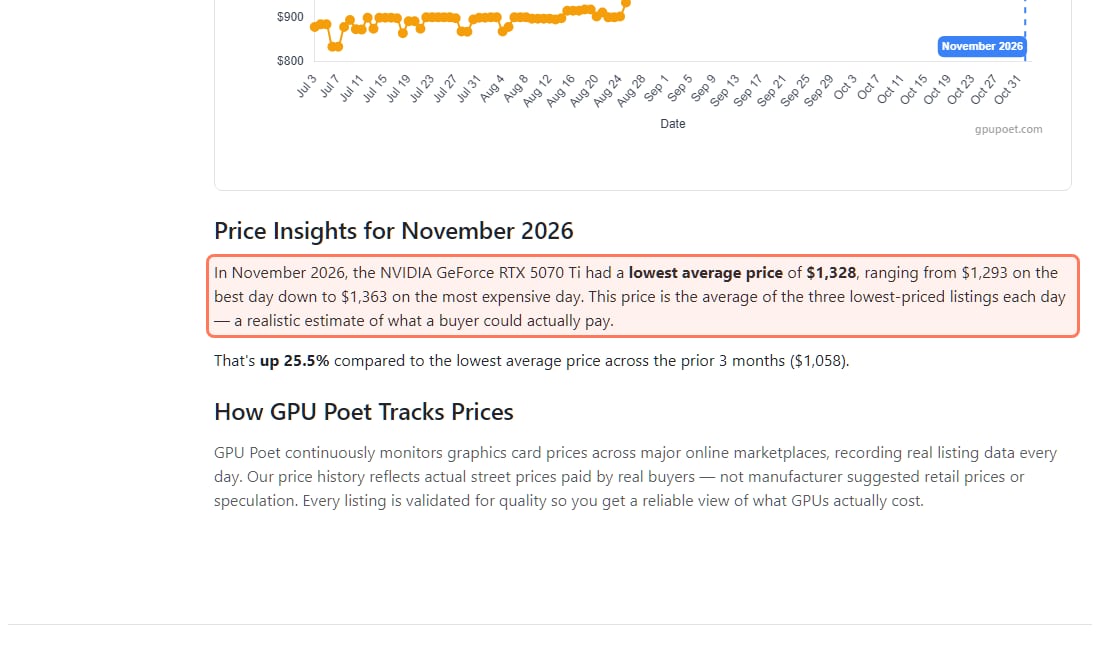
Not for local AI alone. GPU Poet's November figure for the RTX 5070 Ti was $1,328, up 25.5% on the prior three months ($1,058) and 77% over NVIDIA's $749 launch price. At that price the choice changes:
If your models are 14B or smaller, a 16GB RTX 5060 Ti runs the same models for about $706. It's slower (32.9 vs 58.0 tokens/sec on Qwen3-14B), but 33 tokens a second is still faster than reading speed.
If you want 27–32B models, a used 24GB RTX 3090 at about $1,502 runs them, and the 5070 Ti never will. Our used RTX 3090 buying guide covers what to check, and the 5060 Ti vs used 3090 comparison weighs the two.
If you also game at 1440p or 4K, the 5070 Ti's speed is worth more to you than to an AI-only buyer. The RX 9070 XT vs RTX 5070 Ti for local AI comparison covers AMD's 16GB rival.
GPU Poet's RTX 5070 Ti price page (gpupoet.com), read Nov 3, 2026. The figure is the average of the three cheapest eBay listings each day. · Screenshot of gpupoet.com by aliteq
Should you rent an RTX 5070 Ti before buying one?
Yes, if you're not sure 16GB is enough. At 21:20 UTC on Nov 3, 2026, our tracker read the RTX 5070 Ti on Vast.ai from $0.16 an hour on-demand (16 offers). The same reading had the 16GB RTX 5060 Ti from $0.11 and a 24GB RTX 3090 from $0.11 (Runpod listed the 3090 at $0.50). By our arithmetic, $1,328 buys about 8,200 hours of a rented 5070 Ti at that rate, before storage fees. Rent the card, load the model you actually want, and see if 16GB holds it at your context length. Live prices are on our cloud GPU page, and the full maths is in rent vs buy.
Is 16GB of VRAM enough for local AI?
For most people, yes. 16GB covers 7–14B models with long context, gpt-oss-20b, and image generation, which is what coding assistants, chat and ComfyUI work mostly use. It isn't enough for 27–32B dense models or for 70B models, and long contexts eat memory fast on any card. If your target is 32B, buy or rent 24GB; if it's 70B or more, see is the RTX 5090 worth it (GPU Poet's November figure for the 32GB 5090 was $6,596).
7/ 10
Verdict
Great 16GB card, wrong price right now
The RTX 5070 Ti is the fastest 16GB card for local AI and a good buy near its $749 launch price. At November 2026's street price of about $1,328 it's hard to justify for AI alone. The 5060 Ti 16GB runs the same models for about half that, and a used 3090 runs bigger ones for a little more. Buy the 5070 Ti if you find it under about $1,000 or you game on it too; otherwise rent one first.
Best for: Yes: fast 7–14B models, gpt-oss-20b, image generation, gaming, at a fair price. No: 27–32B dense models (need 24GB), or paying about $1,300 for AI alone.
The questions people actually ask
Is the RTX 5070 Ti good for running local LLMs?
Yes. Its 16GB of GDDR7 at 896 GB/sec runs 7–14B models and gpt-oss-20b fast: hardware-corner.net measured 58.0 tokens/sec on Qwen3-14B and 133.1 on gpt-oss-20b at 16k context. It can't hold 27–32B dense models, which need 24GB.
Is the RTX 5070 Ti worth it for AI in November 2026?
Only near its $749 launch price. GPU Poet's November 2026 eBay figure was $1,328, and at that price a 16GB RTX 5060 Ti (about $706) runs the same models more slowly, while a used 24GB RTX 3090 (about $1,502) runs bigger ones.
RTX 5070 Ti or RTX 5060 Ti 16GB for AI?
Both have 16GB, so they run the same models. The 5070 Ti is much faster (58.0 vs 32.9 tokens/sec on Qwen3-14B at 16k context in hardware-corner.net's tests) but cost about $1,328 vs $706 on eBay in November 2026. If 33 tokens a second is fast enough for you, the 5060 Ti is the value pick.
Can the RTX 5070 Ti run 32B models?
Not fully on the card. A 32B model at Q4 needs about 20GB, more than its 16GB, so it spills into system RAM and slows down a lot. For 32B, use a 24GB card like the RTX 3090, or rent one.
Can the RTX 5070 Ti run gpt-oss-20b?
Yes, and fast. Hardware-corner.net measured 133.1 tokens/sec at 16k context and 66.6 at 128k context on the RTX 5070 Ti with llama.cpp.
Does NVFP4 make the RTX 5070 Ti better than an older card?
It helps where tools support it. NVFP4 is the 4-bit format Blackwell's fifth-generation Tensor Cores accelerate, and older cards like the 3090 can't. But most local models still ship as GGUF files for llama.cpp and Ollama, where memory size and speed matter more than NVFP4.
Is the RTX 5070 Ti good for Stable Diffusion and FLUX?
Yes. 16GB handles SDXL comfortably and FLUX at reduced precision. See our guide to the best GPU for Stable Diffusion for what each memory size runs.
The whole question comes down to price. Near $749, the RTX 5070 Ti is the 16GB card to buy for local AI; near $1,300, it isn't. Check your model in the VRAM calculator first, and if you're unsure, rent one for an hour.