Short answer: NVIDIA if your models fit in 24 to 48GB or you need CUDA; Mac Studio if you want 70B-class and bigger models in one quiet box. Apple's prices read Nov 3, 2026, llama.cpp speeds for the M5 Max, M5 Ultra and RTX 3090, and a buyer-by-buyer table.
Some links on this page are referral links: we may earn a commission, at no cost to you.
Share
Should you buy a Mac Studio or an NVIDIA PC for local AI? Buy an NVIDIA PC if the models you want fit in 24 to 48GB, you want CUDA for fine-tuning or image and video generation, or you want to upgrade later; a used RTX 3090 PC is still the cheapest serious way in. Buy a Mac Studio if you want 70B-class or larger models in one quiet box: the M5 Max goes to 128GB and the M5 Ultra to 512GB, and with M5 chips the Mac no longer gives up small-model speed to get there. Apple's prices and specs were read on November 3, 2026.
Which machine for which buyer?
Models up to ~30B, tight budget
Best fit
Used RTX 3090 PC
Why
Cheapest entry, full CUDA stack, fast on anything in 24GB
Fine-tuning, image and video generation
Best fit
NVIDIA PC
Why
LoRA/QLoRA recipes, vLLM and most image tools target CUDA first
Quiet desk box, models up to 70B at Q4
Best fit
Mac Studio M5 Max, 128GB
Why
One pool of memory, no multi-GPU setup
70B at higher quality, or 100B+ MoE models
Best fit
Mac Studio M5 Ultra, 96 to 256GB
Why
Twice the M5 Max bandwidth
400B-class models in one box
Best fit
Mac Studio M5 Ultra, 512GB
Why
No consumer NVIDIA setup holds this in one machine
Not sure which row you are in? List the models you actually want to run and put them through the VRAM calculator. The memory number it gives you decides most of this.
Is a Mac or NVIDIA faster for local LLMs?
For models that fit on the card, they are now close; for models that don't fit, the Mac wins because the NVIDIA card can't hold them at all. Generating each token means reading the model's weights from memory, so memory bandwidth sets the speed. Reading your prompt is mostly compute. NVIDIA pairs fast compute with a small, fast pool of VRAM: NVIDIA's GA102 whitepaper lists 936 GB/s for the RTX 3090's 24GB. Apple pairs a large pool of unified memory with high bandwidth: its spec page lists 460 GB/s for the 32-core M5 Max, 614 GB/s for the 40-core M5 Max and 1.2TB/s for the M5 Ultra.
Mac Studio vs RTX 3090: the numbers that decide it (read Nov 3, 2026)
Model memory
Used RTX 3090 PC
24GB
Mac Studio M5 Max
36–128GB
Mac Studio M5 Ultra
96–512GB
M3 Ultra (previous gen)
up to 512GB
Memory bandwidth
Used RTX 3090 PC
936 GB/s
Mac Studio M5 Max
460 or 614 GB/s
Mac Studio M5 Ultra
1.2 TB/s
M3 Ultra (previous gen)
800 GB/s
7-8B Q4 generation*
Used RTX 3090 PC
115.3 t/s
Mac Studio M5 Max
119.9 t/s (40-core)
Mac Studio M5 Ultra
179.1 t/s (80-core)
M3 Ultra (previous gen)
92.1 t/s
7-8B Q4 prompt processing*
Used RTX 3090 PC
4,050 t/s
Mac Studio M5 Max
3,220 t/s (40-core)
Mac Studio M5 Ultra
4,945 t/s (80-core)
M3 Ultra (previous gen)
1,471 t/s
New price (Apple US, Nov 3, 2026)
Used RTX 3090 PC
Sold used only
Mac Studio M5 Max
from $2,499 (32-core), from $3,099 (40-core)
Mac Studio M5 Ultra
from $5,499 (64-core), from $6,799 (80-core)
M3 Ultra (previous gen)
No longer sold new
Power (vendor spec)
Used RTX 3090 PC
350W card, 750W system power
Mac Studio M5 Max
480W max, whole box
Mac Studio M5 Ultra
480W max, whole box
M3 Ultra (previous gen)
n/a
Fine-tuning ecosystem
Used RTX 3090 PC
CUDA, broadest
Mac Studio M5 Max
MLX, smaller
Mac Studio M5 Ultra
MLX, smaller
M3 Ultra (previous gen)
MLX, smaller
Used RTX 3090 PC
Mac Studio M5 Max
Mac Studio M5 Ultra
M3 Ultra (previous gen)
Model memory
24GB
36–128GB
96–512GB
up to 512GB
Memory bandwidth
936 GB/s
460 or 614 GB/s
1.2 TB/s
800 GB/s
7-8B Q4 generation*
115.3 t/s
119.9 t/s (40-core)
179.1 t/s (80-core)
92.1 t/s
7-8B Q4 prompt processing*
4,050 t/s
3,220 t/s (40-core)
4,945 t/s (80-core)
1,471 t/s
New price (Apple US, Nov 3, 2026)
Sold used only
from $2,499 (32-core), from $3,099 (40-core)
from $5,499 (64-core), from $6,799 (80-core)
No longer sold new
Power (vendor spec)
350W card, 750W system power
480W max, whole box
480W max, whole box
n/a
Fine-tuning ecosystem
CUDA, broadest
MLX, smaller
MLX, smaller
MLX, smaller
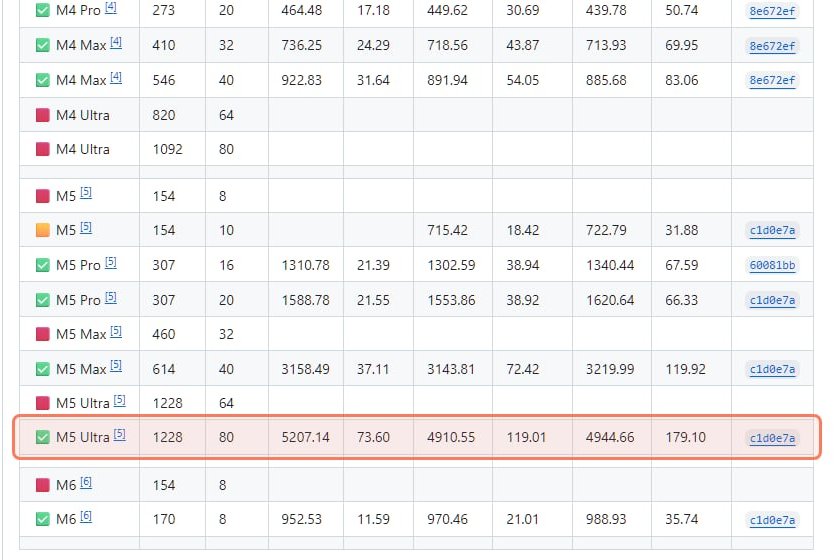
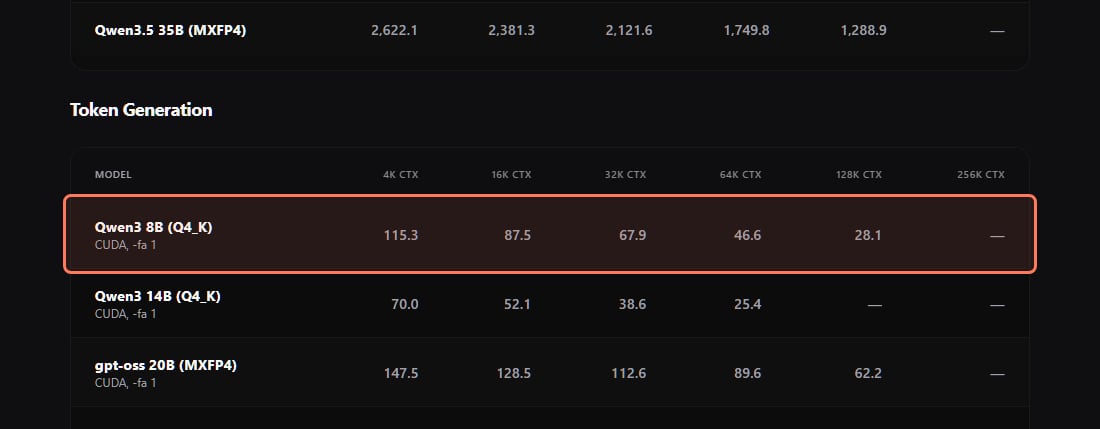
*Mac figures come from the llama.cpp Apple Silicon scoreboard: LLaMA 7B, Q4_0, short prompt (pp512, tg128). The scoreboard has rows only for the 40-core M5 Max and the 80-core M5 Ultra, which cost more than the base models; the 32-core M5 Max (460 GB/s) and 64-core M5 Ultra rows are empty, so expect them to be slower. The M3 Ultra row was measured on an older llama.cpp build than the M5 rows. RTX 3090 figures come from hardware-corner.net: Qwen3 8B, Q4_K, CUDA with flash attention, 4k context. Same llama.cpp family and quant class, different models and settings, so read small gaps as a tie. At 16k context the 3090 slows to 87.5 t/s generation. Apple's power figure is the Mac Studio's maximum continuous power, not typical draw; NVIDIA's 750W is its recommended system power for the whole PC.
The llama.cpp scoreboard (discussion #4167), read November 3, 2026. Columns are bandwidth, GPU cores, then F16, Q8_0 and Q4_0 prompt and generation speeds; the last pair is the Q4_0 figure we quote. · Screenshot of github.com/ggml-org/llama.cpp by aliteq
hardware-corner.net's RTX 3090 generation speeds, read November 3, 2026. Speed falls as the context grows. · Screenshot of hardware-corner.net by aliteq
How much does a Mac Studio cost for local AI?
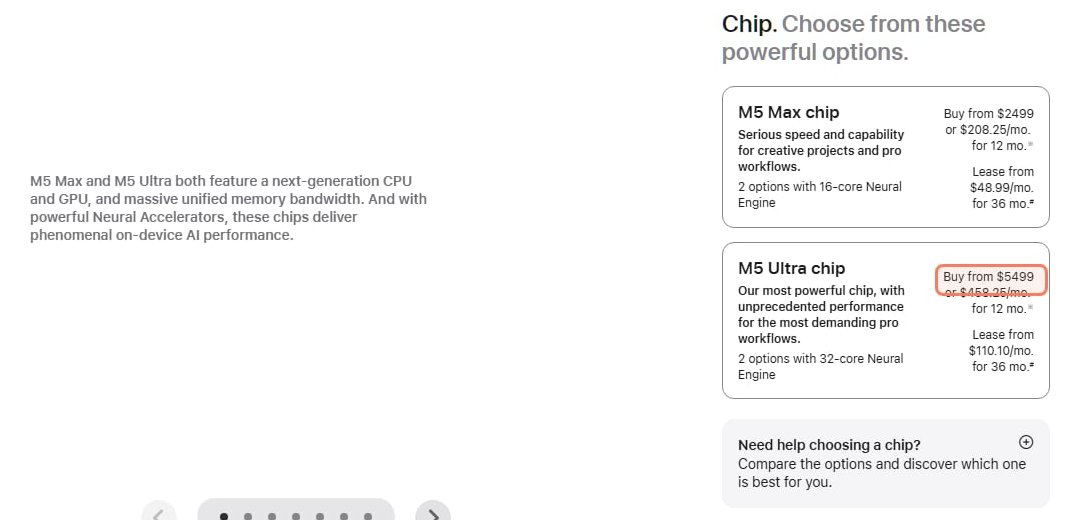
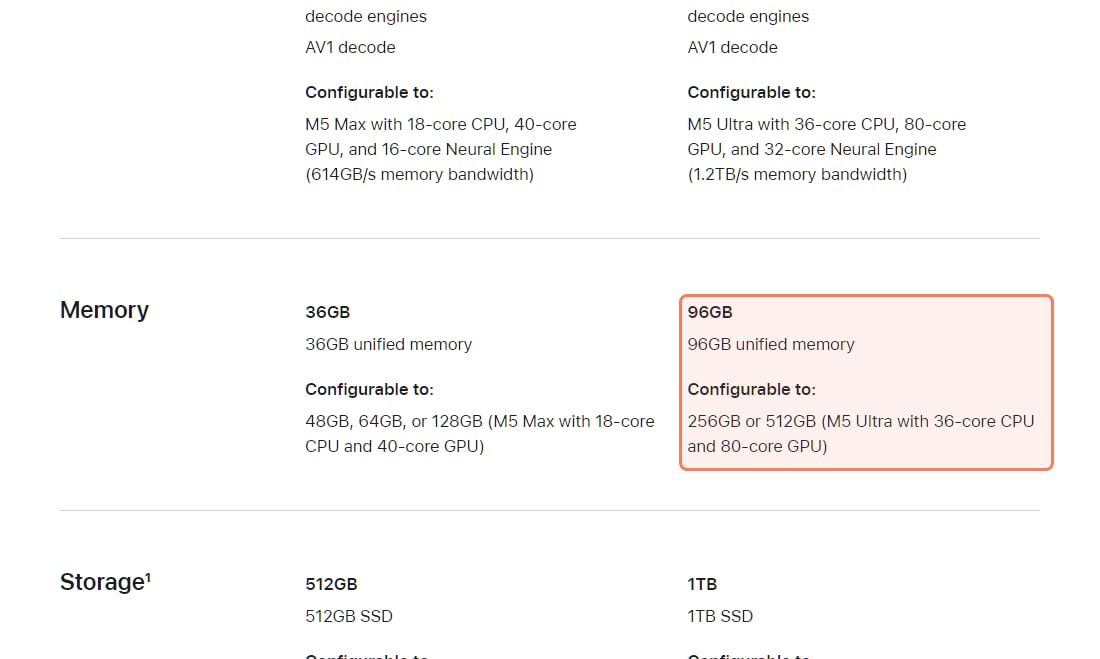
On November 3, 2026 Apple's US store listed the Mac Studio from $2,499 with the M5 Max and from $5,499 with the M5 Ultra. What you pay for local AI depends on memory, and Apple ties the big memory options to the faster chips: per its spec page, 128GB needs the 40-core M5 Max, and 256GB or 512GB needs the 80-core M5 Ultra.
Apple's US Mac Studio store, read November 3, 2026. · Screenshot of apple.com by aliteq
M5 Max, 32-core GPU, 512GB SSD
Memory
36GB
Price
$2,499
M5 Max, 40-core GPU, 512GB SSD
Memory
48GB
Price
from $3,099
M5 Max, 40-core GPU, 1TB SSD
Memory
64GB
Price
$3,799
M5 Max, 40-core GPU, 1TB SSD
Memory
128GB
Price
$5,399
M5 Ultra, 64-core GPU, 1TB SSD
Memory
96GB
Price
$5,499
M5 Ultra, 80-core GPU
Memory
96GB
Price
from $6,799
M5 Ultra, 80-core GPU
Memory
256GB or 512GB
Price
price in Apple's configurator
Memory
Price
M5 Max, 32-core GPU, 512GB SSD
36GB
$2,499
M5 Max, 40-core GPU, 512GB SSD
48GB
from $3,099
M5 Max, 40-core GPU, 1TB SSD
64GB
$3,799
M5 Max, 40-core GPU, 1TB SSD
128GB
$5,399
M5 Ultra, 64-core GPU, 1TB SSD
96GB
$5,499
M5 Ultra, 80-core GPU
96GB
from $6,799
M5 Ultra, 80-core GPU
256GB or 512GB
price in Apple's configurator
The $5,399 figure is the 64GB, 1TB M5 Max with Apple's 128GB upgrade (+$1,600) selected in its configurator. We could not get a clean 256GB or 512GB total from Apple's configurator on November 3, so we don't print one; configure it on Apple's store before you budget.
Apple's Mac Studio spec page, read November 3, 2026: 128GB needs the 40-core M5 Max, and 256GB or 512GB the 80-core M5 Ultra. · Screenshot of apple.com by aliteq
Should I get the M5 Ultra with 96GB or the M5 Max with 128GB?
Take the Ultra if your biggest model fits in about 80GB with room for context; take the Max if you need the capacity. On Apple's store they now cost almost the same: $5,399 for the 128GB M5 Max with 1TB and $5,499 for the 96GB M5 Ultra with 1TB (read Nov 3, 2026). r/LocalLLM asked exactly this in October (thread). The trade is simple. The M5 Ultra has about twice the bandwidth (1.2TB/s vs 614 GB/s), so the same model generates roughly twice as fast. The M5 Max holds 32GB more, which is the difference between a 70B model at Q8 fitting comfortably or not. Size your list in the VRAM calculator first.
What can a Mac Studio do that no single NVIDIA GPU can?
Hold a very large model in one box. Apple's spec page lists the M5 Ultra configurable to 256GB or 512GB of unified memory. No consumer NVIDIA card comes close; reaching that capacity on NVIDIA means several cards, a workstation board and a big power supply, or renting.
The catch has always been long prompts on giant models. On the previous M3 Ultra with 512GB, hardware-corner measured DeepSeek V3 671B at Q4_K_M taking 14.80 minutes to process an 8,001-token prompt (9.01 t/s), then generating at 6.21 t/s. We have not seen an equivalent 671B test on M5 yet, so treat the M3 figure as the worst case; on the 7B scoreboard the M5 Ultra processes prompts more than three times as fast as the M3 Ultra. In r/LocalLLM's Mac-vs-Spark thread (thread), owners made the same point from experience: past about 128GB, these machines are limited by compute, not memory. In another October buying thread (thread), the top reply called the Mac too slow for agentic coding, which is the same long-prompt problem: coding agents resend large contexts on every step.
Use CUDA tools. LoRA and QLoRA fine-tuning recipes, vLLM serving, and most image and video generation tools target CUDA first. Apple's MLX runs LoRA fine-tuning, but the wider tooling is smaller.
Yes: rent the GPU class you are considering for an hour and run your own models on it. A 24GB card tells you what a used-3090 PC would feel like; a 48GB or 96GB card shows whether you really need Mac-sized memory. Today's hourly prices for every tracked card are on our cloud GPU price tracker, and the rent vs buy guide shows where buying starts to pay off.
Is a 96GB Mac Studio better than four Intel Arc Pro B60s?
For most people, yes: it is the simpler setup at a lower power rating. Both give you 96GB, spent differently. The base M5 Ultra Mac Studio has 96GB in one pool at 1.2TB/s, for $5,499. Four Intel Arc Pro B60 cards also total 96GB, but as four separate 24GB pools at 456 GB/s each, per Intel's spec page (read Nov 3, 2026).
With the common way of spreading a model across cards, each card holds a slice of the layers and they take turns, so each token moves at roughly one card's bandwidth, not the sum. Tensor-parallel serving can use the cards together, but it needs software that supports it on Intel GPUs. Intel lists each B60 at 200W, so four cards come to 800W before the CPU; Apple rates the whole Mac Studio at 480W maximum. We found no published like-for-like benchmark, so we are not printing a speed comparison.
Which should you buy at each budget?
At around $2,500, the base M5 Max Studio (32-core GPU, 36GB, 460 GB/s) is the cheapest new Mac Studio. A used-3090 PC is faster per dollar on anything that fits in 24GB, and 36GB is not much more room. At around $5,500, the 128GB M5 Max ($5,399) and the 96GB M5 Ultra ($5,499) face a dual-GPU 48GB NVIDIA build; the deciding question is whether your models sit above or below 48GB. In a long r/LocalLLM thread on a $5,000 budget (thread), replies also pointed to a 128GB Framework Desktop or two 32GB AMD Radeon AI PRO R9700 cards. Above 128GB, only the 80-core M5 Ultra offers it in one box, and the realistic NVIDIA alternative is renting by the hour.
Verdict
Different questions, different winners
If your models fit in 24GB and you want CUDA tools, an NVIDIA PC is the cheaper, more flexible start. If you want 70B-class or bigger models in one quiet box, buy the Mac Studio; with M5 you no longer give up small-model speed to do it. Buying a Mac only to run 8B models, or a GPU rig hoping to run 400B-class ones, is how this decision goes wrong.
Best for: NVIDIA: low entry cost, CUDA fine-tuning, image generation, upgrades. Mac Studio: 70B+ models in one box, quiet operation, simple setup.
The questions people actually ask
Should I buy a Mac Studio or an NVIDIA PC for local AI?
Buy an NVIDIA PC if your models fit in 24 to 48GB, you need CUDA for fine-tuning or image generation, or you want to upgrade later. Buy a Mac Studio if you want 70B-class or larger models in one quiet box; the M5 Max goes to 128GB and the M5 Ultra to 512GB, per Apple's spec page (read Nov 3, 2026).
Is the M5 Mac Studio faster than an RTX 3090 for LLMs?
On the llama.cpp scoreboard, the 80-core M5 Ultra generates 179 t/s and the 40-core M5 Max 120 t/s on LLaMA 7B Q4_0. hardware-corner measured an RTX 3090 at 115 t/s on Qwen3 8B Q4_K at 4k context. The tests differ, so call the 40-core M5 Max a tie and the 80-core M5 Ultra faster. The base configs have fewer GPU cores and will be slower.
How much does the Mac Studio cost in November 2026?
Apple's US store on Nov 3, 2026 listed the M5 Max from $2,499 (32-core GPU, 36GB) and the M5 Ultra from $5,499 (64-core GPU, 96GB). The 40-core M5 Max starts at $3,099, the 128GB M5 Max with 1TB is $5,399, and the 80-core M5 Ultra starts at $6,799. The 256GB and 512GB options need the 80-core M5 Ultra; price them in Apple's configurator.
Should I get the M5 Ultra with 96GB or the M5 Max with 128GB?
They cost almost the same on Apple's store ($5,499 vs $5,399 with 1TB, Nov 3, 2026). The M5 Ultra has about twice the memory bandwidth, so it generates text roughly twice as fast on the same model. The M5 Max holds 32GB more. If your biggest model fits in about 80GB with context, take the Ultra; if you need the capacity, take the Max.
Can a Mac Studio replace a CUDA box for fine-tuning?
For small LoRA jobs, MLX can do it. For the broader tooling, such as QLoRA recipes, vLLM serving and most image and video generation, CUDA still comes first. If fine-tuning is central to your plan, choose NVIDIA.
Is a 96GB Mac Studio better than four Intel Arc Pro B60s?
Both have 96GB. The Mac has one pool at 1.2TB/s and a 480W maximum. The four B60s have four 24GB pools at 456 GB/s each and are listed at 200W per card. With common layer splitting, the cards take turns, so the Mac's single pool is the simpler setup. We found no like-for-like benchmark.
Can I try before buying either one?
Yes. Rent a 24GB card and a bigger-memory card by the hour and run your own models; our cloud GPU tracker shows today's hourly prices. A weekend of tests costs far less than the wrong machine.
What about a DGX Spark or a Strix Halo mini PC instead?
Both hold up to 128GB at about a quarter of the M5 Ultra's bandwidth, so they generate text more slowly. The DGX Spark wins on prompt processing and CUDA; Strix Halo is the cheapest way to big-model capacity and doubles as an x86 gaming PC. See our DGX Spark vs Strix Halo comparison.