On Nov 3, 2026 a rented RTX 4090 started at $0.27/hr on Vast.ai (median $0.46) against $0.89/hr on Runpod Secure Cloud. Where the low prices are, the catch behind each one, and which models, image tools and fine-tunes fit in 24GB.
Some links on this page are referral links: we may earn a commission, at no cost to you.
Share
The cheapest place to rent an RTX 4090 is Vast.ai's marketplace. At 12:20 UTC on Nov 3, 2026 the cheapest on-demand 4090 there was $0.27/hour, with the median offer at $0.46 across 39 listings, and interruptible bids started at $0.21. Runpod Secure Cloud lists the same card at $0.89/hour. Its 24GB runs 8B to 14B language models at 8-bit, 20B to 30B models at 4-bit, Flux image generation and QLoRA fine-tunes up to 14B. It does not run a 70B model. Prices move every hour, so check today's live prices before you rent.
Where is the cheapest RTX 4090 rental right now?
These are single-GPU RTX 4090 prices from our hourly price feed, read at 12:20 UTC on Nov 3, 2026. Vast.ai, Novita AI and Lium figures come from their own market APIs; the Runpod figure is its published list price, which we also confirmed on runpod.io/pricing the same day. "From" is the cheapest listing and "median" the middle one. For the price this hour, see our live cloud-GPU table.
RTX 4090 rental, $/GPU-hour, read 12:20 UTC Nov 3, 2026
Vast.ai on-demand
From
$0.27
Median
$0.46
What you get
39 marketplace offers; fixed price, not interrupted
Vast.ai interruptible
From
$0.21
Median
$0.40
What you get
Lowest priority; can be paused
Novita AI on-demand
From
$0.33
Median
-
What you get
One 4090 product in stock at read time
Novita AI spot
From
$0.17
Median
-
What you get
Spot price; one product listed at read time
Lium on-demand
From
$0.35
Median
$0.50
What you get
9 nodes on a decentralized marketplace
Runpod Secure Cloud
From
$0.89
Median
-
What you get
List price; 41 GB RAM, 6 vCPUs included
Runpod Community Cloud
From
$0.34
Median
-
What you get
Listed, but no longer taking new hosts
From
Median
What you get
Vast.ai on-demand
$0.27
$0.46
39 marketplace offers; fixed price, not interrupted
Vast.ai interruptible
$0.21
$0.40
Lowest priority; can be paused
Novita AI on-demand
$0.33
-
One 4090 product in stock at read time
Novita AI spot
$0.17
-
Spot price; one product listed at read time
Lium on-demand
$0.35
$0.50
9 nodes on a decentralized marketplace
Runpod Secure Cloud
$0.89
-
List price; 41 GB RAM, 6 vCPUs included
Runpod Community Cloud
$0.34
-
Listed, but no longer taking new hosts
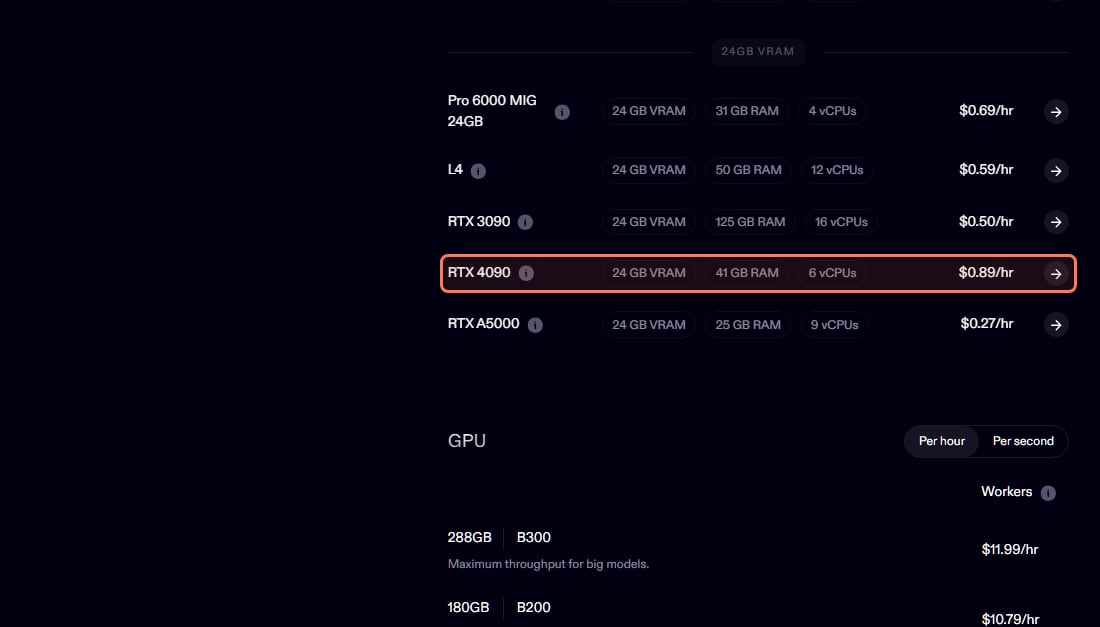
Runpod's own price list, read Nov 3, 2026: the RTX 4090 at $0.89/hr with 41 GB RAM and 6 vCPUs.
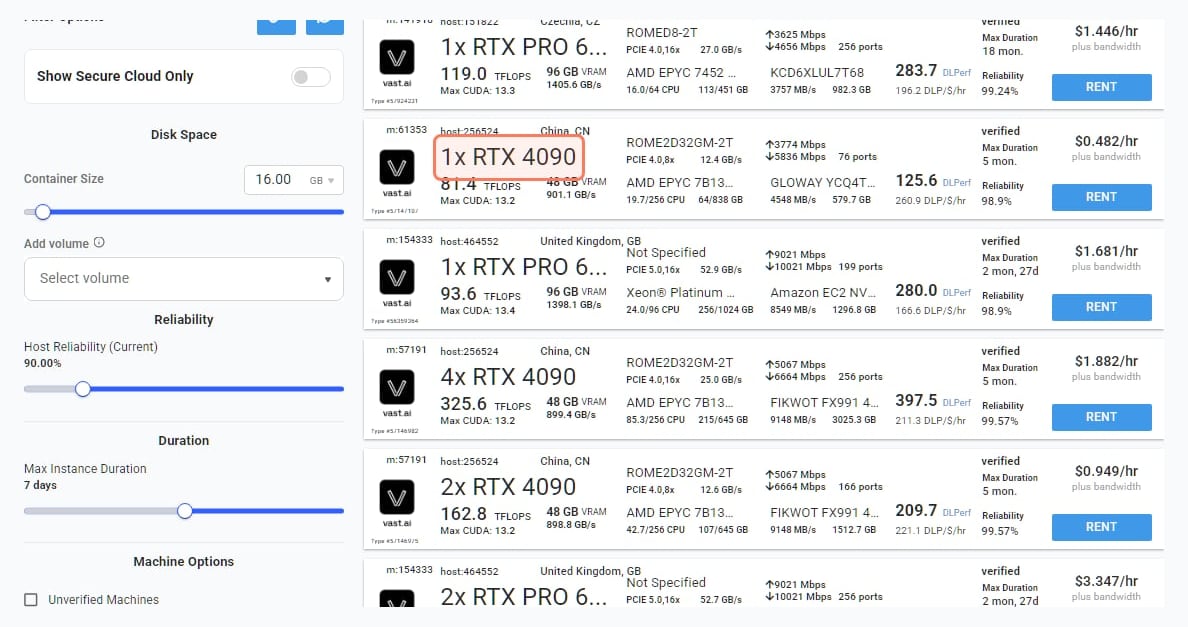
The gap is big: the median Vast 4090 is about half Runpod's list price. What you trade for it is choice and checking. Vast is a marketplace of independent hosts, so each offer has its own reliability score, location, disk and bandwidth price, and the cheapest listing may have a low reliability score or already be taken. Runpod's $0.89 is one fixed price in data centers it lists as "T3/T4". Our Vast.ai review and Runpod vs Vast vs Lambda cover that trade in detail.
Is on-demand or interruptible the better deal?
Vast's docs define on-demand as "Fixed pricing, guaranteed resources (high priority)" and interruptible as "Lowest cost, may be paused (low priority)". On Nov 3 the interruptible floor was $0.21 against $0.27 on-demand, and the medians were $0.40 against $0.46. That is only about 13% saved at the median, so for most jobs on-demand is the better buy. Interruptible makes sense for work you can restart without losing much: a batch of images, or a training run that saves checkpoints.
What does a rented 4090 cost for a real job?
Vast and Runpod both bill GPU time by the second, so you pay for the hours the machine is on. At the Nov 3 prices:
A 4-hour session costs about $1.84 at the Vast median ($0.46) or $3.56 on Runpod Secure Cloud ($0.89).
A 40-hour month of evenings costs about $18 at the Vast median or $36 on Runpod.
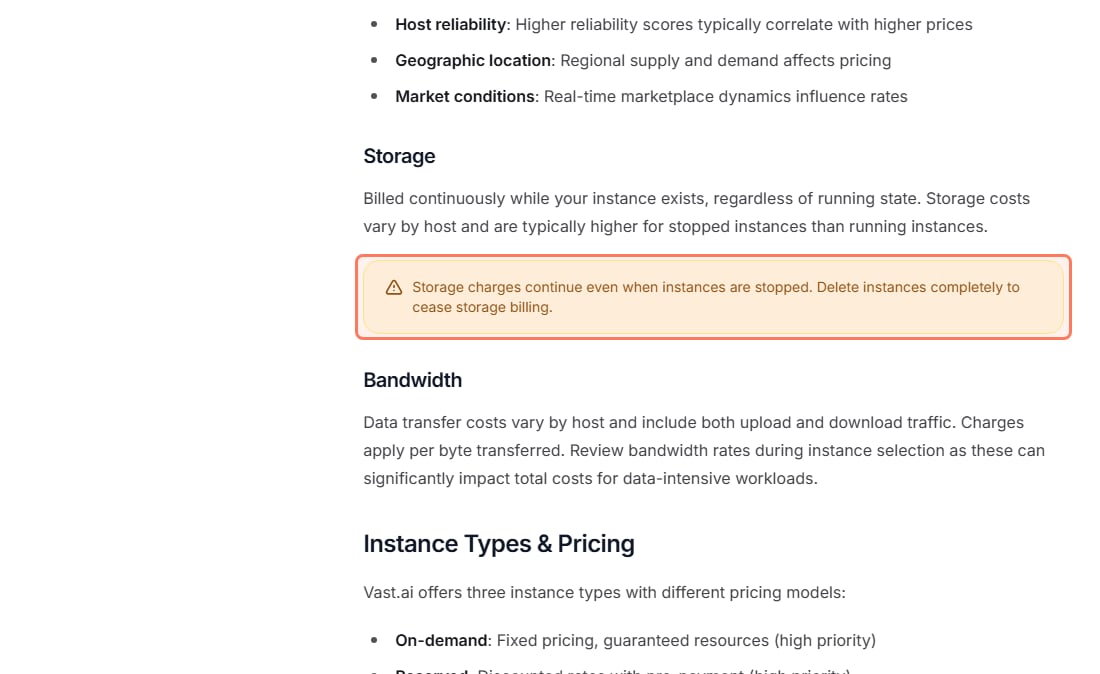
Storage and bandwidth come on top. Runpod lists container disk and running volume disk at $0.10/GB a month, and an idle volume at $0.20/GB a month. Vast's docs warn that storage is "billed continuously while your instance exists, regardless of running state", and data transfer is charged per byte at each host's rate.
Vast.ai's own docs, read Nov 3, 2026: a stopped instance still bills storage. Delete it when you are done.
Vast's offer list, Nov 1, 2026. Each price is per host, "plus bandwidth", with its own reliability score and verified label.
What can an RTX 4090's 24GB actually run?
NVIDIA lists the RTX 4090 with 24 GB of GDDR6X memory. The table below uses our VRAM engine, the same one behind the VRAM calculator: weights at the stated quantization, plus the KV cache at 16-bit and about 0.8 GB of overhead. A total under about 21.6 GB (90% of the card) leaves comfortable headroom.
Estimated VRAM on a 24GB RTX 4090 (Aliteq VRAM engine, Nov 3, 2026)
Qwen3 8B, Q8_0
8K context
10.0 GB
32K context
13.4 GB
Verdict
Fits easily
Qwen3 14B, Q8_0
8K context
16.6 GB
32K context
20.4 GB
Verdict
Fits
Mistral Small 24B, Q4_K_M
8K context
15.3 GB
32K context
19.1 GB
Verdict
Fits
Qwen3 30B-A3B (MoE), Q4_K_M
8K context
18.8 GB
32K context
21.0 GB
Verdict
Fits, little room at 32K
Qwen3 32B, Q4_K_M
8K context
21.3 GB
32K context
27.3 GB
Verdict
Tight at 8K, no at 32K
Llama 3.3 70B, Q4_K_M
8K context
39.8 GB (weights alone)
32K context
-
Verdict
Does not fit
8K context
32K context
Verdict
Qwen3 8B, Q8_0
10.0 GB
13.4 GB
Fits easily
Qwen3 14B, Q8_0
16.6 GB
20.4 GB
Fits
Mistral Small 24B, Q4_K_M
15.3 GB
19.1 GB
Fits
Qwen3 30B-A3B (MoE), Q4_K_M
18.8 GB
21.0 GB
Fits, little room at 32K
Qwen3 32B, Q4_K_M
21.3 GB
27.3 GB
Tight at 8K, no at 32K
Llama 3.3 70B, Q4_K_M
39.8 GB (weights alone)
-
Does not fit
A few more fits, from the model makers' own pages:
gpt-oss-20b: OpenAI's model card says it runs "within 16GB of memory", so it fits a 4090 with room for context. See can you run gpt-oss-20b locally.
Flux image generation: Black Forest Labs calls FLUX.1 [dev] "a 12 billion parameter rectified flow transformer". At 16-bit, the weights alone are about 24 GB (12 billion × 2 bytes), which fills the card, so on a 4090 people run an 8-bit (FP8) version. Note FLUX.1 [dev] ships under a non-commercial license. More in cloud GPUs for ComfyUI.
Fine-tuning: Unsloth's requirements table puts the minimum for QLoRA (4-bit) at 6 GB for an 8B model, 8.5 GB for 14B and 26 GB for 32B, and LoRA (16-bit) at 22 GB for 8B. So a 4090 handles QLoRA up to about 14B and 16-bit LoRA of an 8B model, but not a 32B fine-tune. Our LoRA fine-tuning guide walks through it.
When 24GB is enough but speed isn't critical: an RTX 3090 also has 24GB and was far cheaper on Nov 3: from $0.09/hr on Vast (median $0.16) and $0.50/hr on Runpod. The 4090 is faster, but for a model that fits, the 3090 often costs less per job. See RTX 4090 vs RTX 3090 for local AI.
When you need a bit more memory: the 32GB RTX 5090 rented from $0.46/hr on Vast (median $0.65) and $1.19/hr on Runpod on Nov 3, enough for a 32B model at 4-bit with real context.
When you need 70B or full fine-tuning: step up to an 80GB card; see the cheapest A100 and cheapest H100 rentals.
Frequently asked
What's the cheapest way to rent an RTX 4090?
Vast.ai's marketplace. On November 3, 2026 its cheapest on-demand 4090 was $0.27 an hour (median $0.46 across 39 offers) and interruptible started at $0.21. Runpod Secure Cloud lists the 4090 at $0.89 an hour. Prices change hourly, so check the live table before you rent.
Why does Runpod show $0.34 for a 4090 in some places?
That is the Community Cloud price. Runpod's docs say it is no longer accepting new Community Cloud hosts and existing resources remain available, so supply in that tier is shrinking. The Secure Cloud price was $0.89 an hour on November 3, 2026.
Can an RTX 4090 run a 70B model?
Not on one card. A 70B model needs about 40 GB for the weights alone at 4-bit (Q4_K_M), and the 4090 has 24 GB. Rent an 80GB A100 or H100, or two 24GB cards.
What is the biggest model a rented 4090 runs well?
About 30B at 4-bit. Mistral Small 24B and Qwen3 30B-A3B fit at Q4_K_M with 32K context by our estimate; Qwen3 32B at Q4_K_M fits only with short context (about 21.3 GB at 8K).
Do I pay for a Vast.ai 4090 when it's stopped?
Not for the GPU, but yes for storage. Vast's docs say storage is billed while the instance exists, regardless of running state, and to delete the instance to stop storage billing.
Should I rent or buy a 4090?
For occasional use, rent: a 4-hour session cost about $1.84 at the Vast median on November 3, 2026. Buying pays off only with heavy daily use. See our rent-vs-buy math.
The short version: rent the 4090 on Vast.ai when price matters and you'll pick a reliable host, on Runpod when you want one fixed price, and check your model fits with the VRAM calculator first. Live prices for every card are on our cloud-GPU compare page, and the cloud-GPU pricing pillar covers the big providers.