Local AI
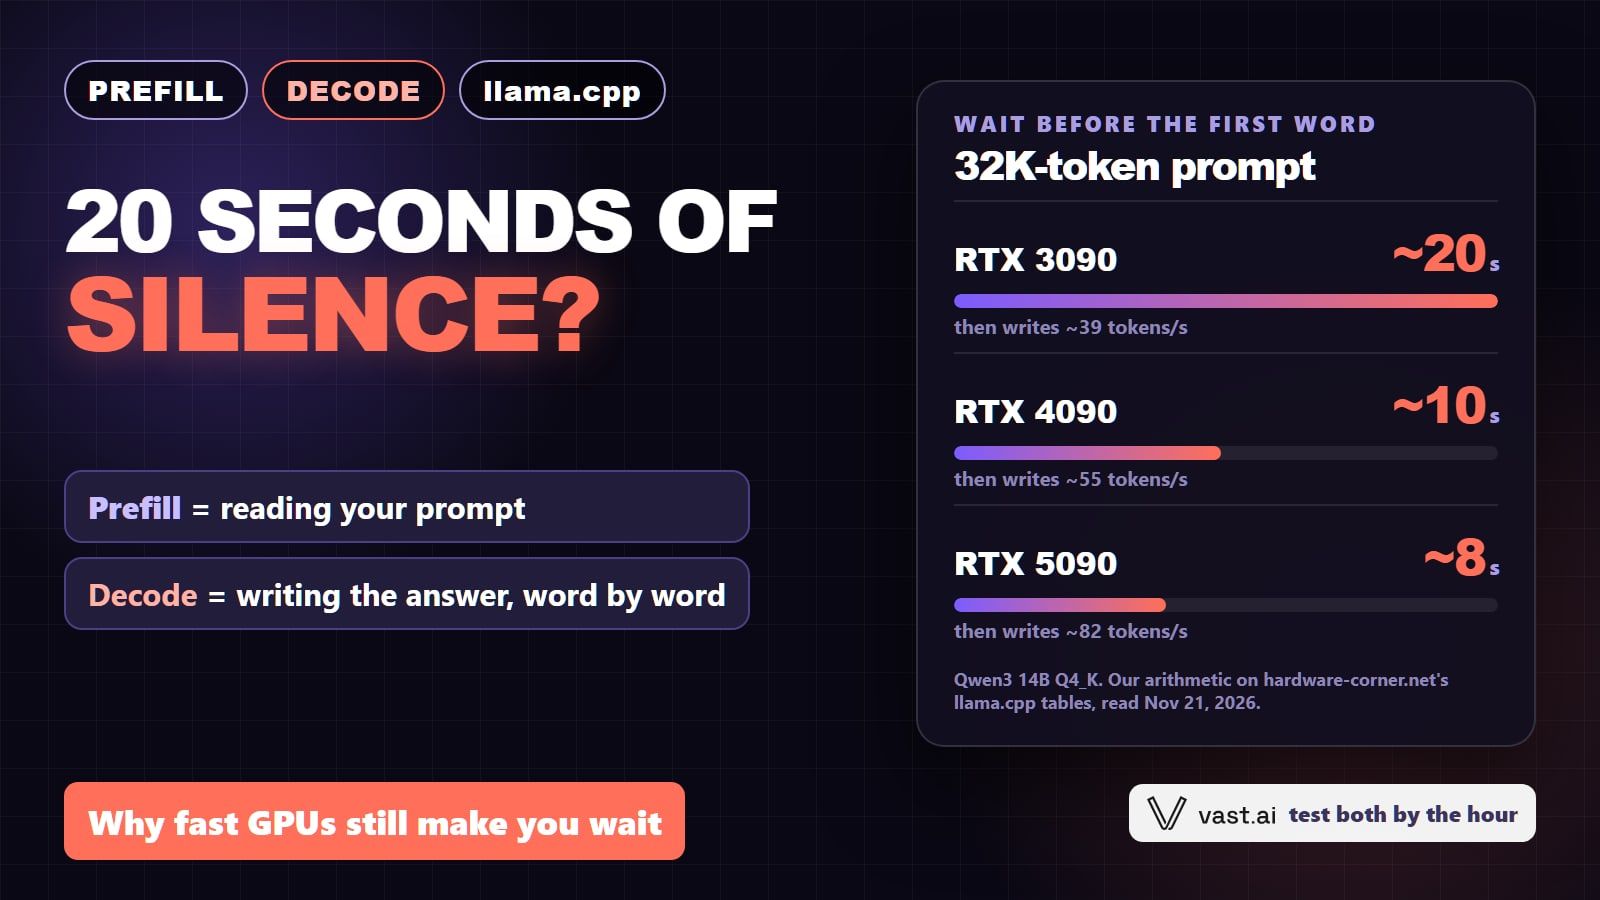
Prefill vs decode, why a fast GPU still waits 20 seconds before it answers
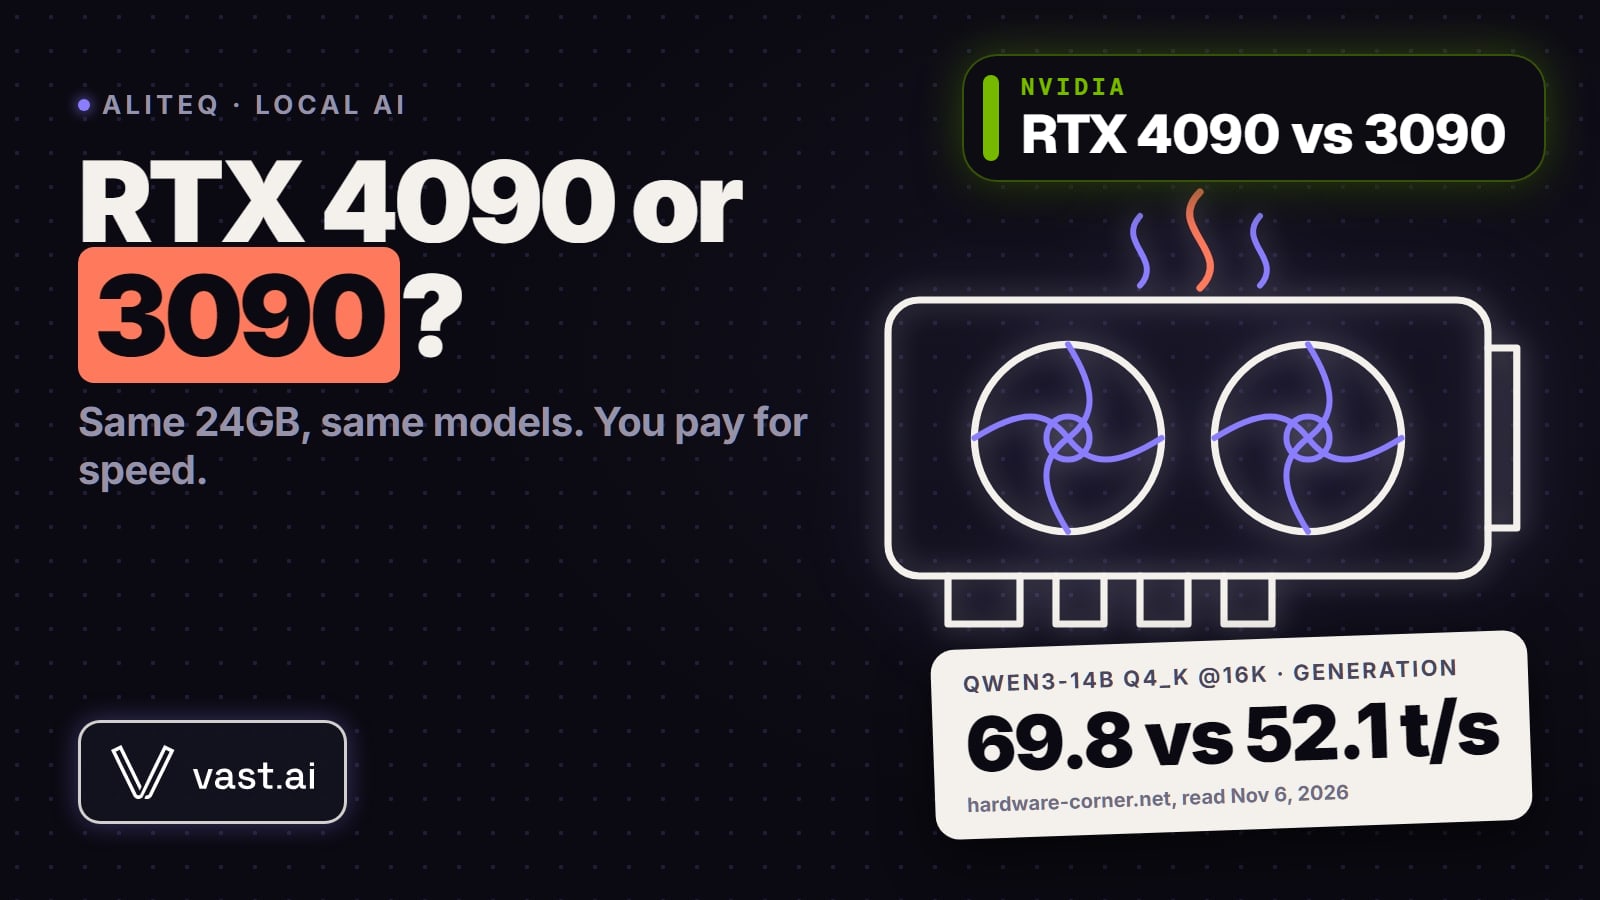
Your local model types fast, so why does a long prompt sit there in silence first? That wait is prefill, the model reading your prompt, and it is a different speed from decode, the writing you watch. Here is how long each GPU makes you wait, why a 4090 reads prompts about twice as fast as a 3090, and what it costs to rent each one. Checked Nov 21, 2026.
Ari Vale · · 8 min