On Nov 3, 2026 a single H200 rented from $3.76 an hour on Vast.ai to $6.31 a GPU on CoreWeave. What each provider charges, the cheaper H200 NVL, and the models that really need 141GB instead of an 80GB H100.
Some links on this page are referral links: we may earn a commission, at no cost to you.
Share
Renting one H200 cost from $3.76 an hour on Nov 3, 2026, the cheapest on-demand H200 SXM on Vast.ai's marketplace (median $4.70 across just 4 offers, our 20:20 UTC read). Managed H200s were $3.99 on Hyperstack and $5.29 on Runpod Secure Cloud, and the enterprise clouds listed $5.40 (Nebius) and $6.31 per GPU (CoreWeave). The H200 NVL, the PCIe version with the same 141GB, went lower: from $1.87 on Vast and $3.79 on Runpod. The 141GB is worth paying for only when your model plus its context won't fit an 80GB H100, for example a 70B model at 8-bit with a 32K context. If it fits in 80GB, an H100 does the same job for less. For the price right now, see our live cloud-GPU compare page.
One H200, on-demand, $ per GPU-hour (read Nov 3, 2026)
Vast.ai H200 NVL (cheapest offer)$1.87
Marketplace; median $4.00 across 13 offers
Vast.ai H200 SXM (cheapest offer)$3.76
Marketplace; median $4.70 across 4 offers
Runpod Secure H200 NVL$3.79
Hyperstack H200 SXM$3.99
Runpod Secure H200 SXM$5.29
Nebius HGX H200$5.40
CoreWeave HGX H200 (per GPU)$6.31
8-GPU node at $50.44/hr
How much does it cost to rent an H200?
Between $3.76 and $6.31 an hour for one H200 SXM on-demand, on Nov 3, 2026. Here is every price we could source that day, cheapest first. GMI Cloud advertises its H200 "from $3.20/GPU-hour", but its pricing page doesn't say whether that is on-demand or reserved, so we don't count it as the on-demand floor.
H200 rental · $/GPU-hour · read Nov 3, 2026
Vast.ai H200 NVL (on-demand)
Rate (from)
$1.87 (median $4.00)
Source
our API read, 13 offers
GMI Cloud H200
Rate (from)
from $3.20
Source
published starting price; page doesn't say on-demand or reserved
Vast.ai H200 SXM (on-demand)
Rate (from)
$3.76 (median $4.70)
Source
our API read, 4 offers
Runpod Secure H200 NVL
Rate (from)
$3.79
Source
our API read of Runpod
Hyperstack H200 SXM
Rate (from)
$3.99
Source
published on-demand; reservation from $2.79
Runpod Secure H200 SXM
Rate (from)
$5.29
Source
published on-demand
Nebius HGX H200
Rate (from)
$5.40
Source
published on-demand; preemptible from $0.79
CoreWeave HGX H200
Rate (from)
$6.31
Source
8-GPU node at $50.44/hr
Lambda
Rate (from)
not listed
Source
no H200 on its public price list
Rate (from)
Source
Vast.ai H200 NVL (on-demand)
$1.87 (median $4.00)
our API read, 13 offers
GMI Cloud H200
from $3.20
published starting price; page doesn't say on-demand or reserved
Vast.ai H200 SXM (on-demand)
$3.76 (median $4.70)
our API read, 4 offers
Runpod Secure H200 NVL
$3.79
our API read of Runpod
Hyperstack H200 SXM
$3.99
published on-demand; reservation from $2.79
Runpod Secure H200 SXM
$5.29
published on-demand
Nebius HGX H200
$5.40
published on-demand; preemptible from $0.79
CoreWeave HGX H200
$6.31
8-GPU node at $50.44/hr
Lambda
not listed
no H200 on its public price list
Three things move these numbers. Supply is thin: Vast had only 4 rentable single H200 SXM offers at our read, and two days earlier, on Nov 1, its cheapest was $2.76 across 7 offers. The floor can be one host and gone within the hour. Interruptible capacity is cheaper but can be taken back: Nebius lists H200 preemptible from $0.79 a GPU-hour, and Vast's interruptible H200 SXM bids started at $3.42; Vast's docs say an interruptible instance "may be paused". Runpod's $3.59 Community Cloud H200 still appears in its page data, but Runpod's docs say Community Cloud is no longer accepting new hosts, and a new account sees Secure Cloud at $5.29.
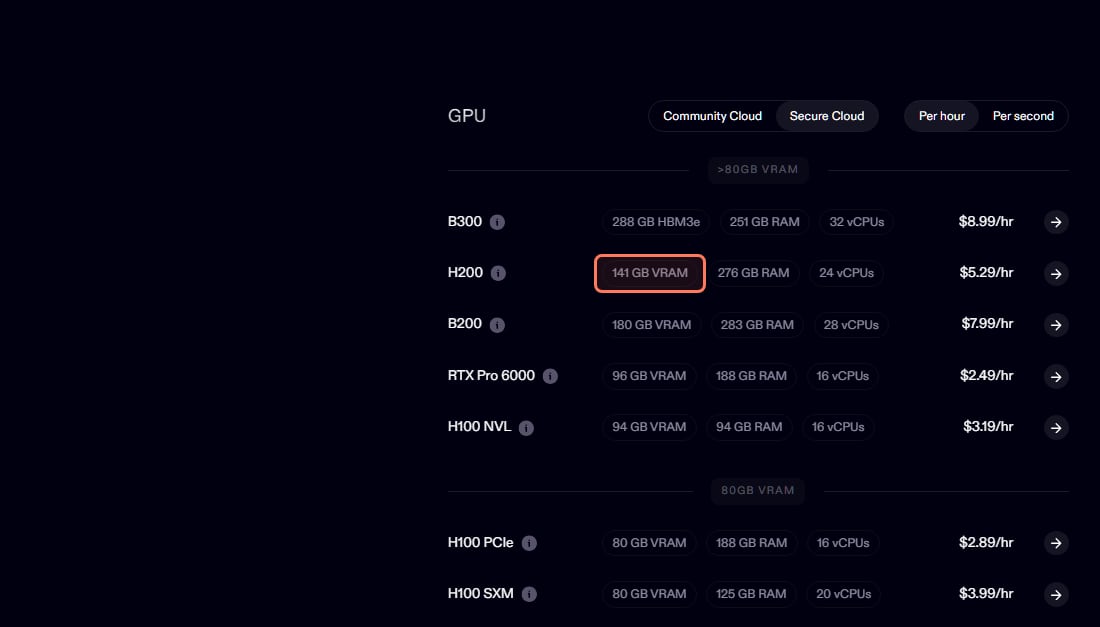
Runpod's own pricing page, Secure Cloud, read Nov 3, 2026. The step from an H100 SXM to an H200 was $1.30 an hour. · Screenshot of runpod.io by aliteq
Hyperstack's own pricing page, Nov 1, 2026. The same rates were listed on Nov 3. · Screenshot of hyperstack.cloud by aliteq
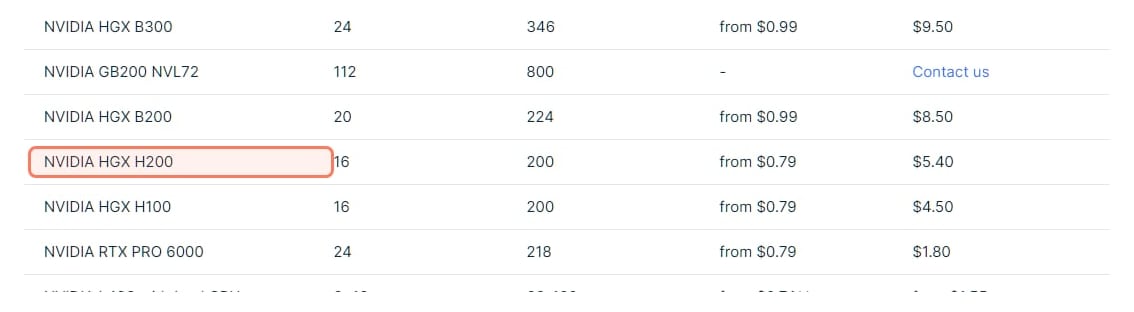
Nebius's own pricing page, Nov 1, 2026. Unchanged on Nov 3. · Screenshot of nebius.com by aliteq
H200 SXM or H200 NVL: which one are you renting?
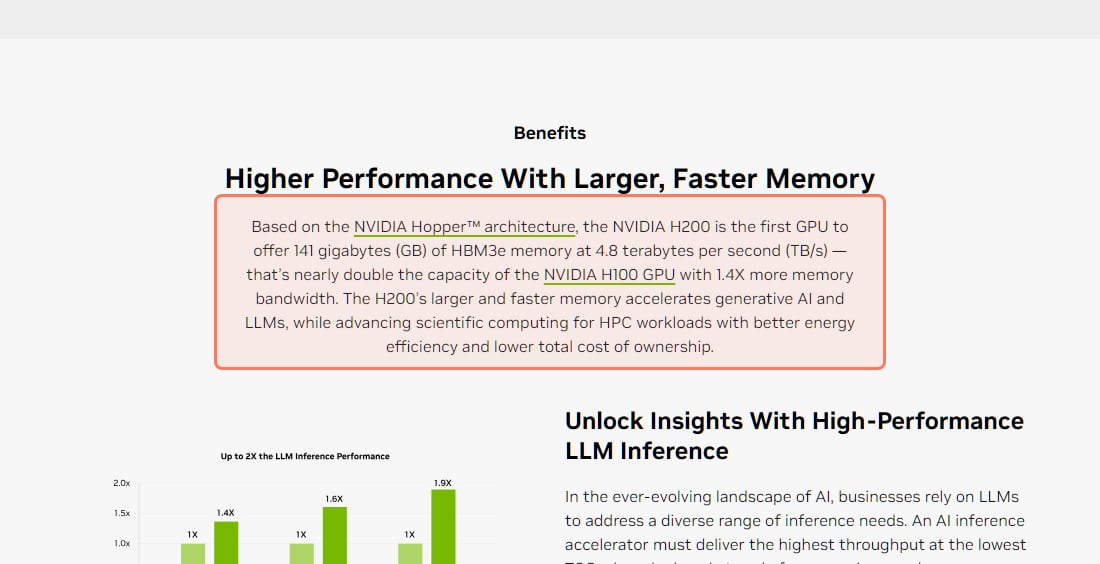
Both have 141GB of HBM3e at 4.8TB/s, per NVIDIA's spec table. The difference is the package and power:
H200 SXM: the server-board version, up to 700W, 3,958 FP8 TFLOPS (with sparsity), NVLink at 900GB/s. This is what Runpod's "H200", Hyperstack, Nebius and CoreWeave rent.
H200 NVL: a dual-slot PCIe card, up to 600W, 3,341 FP8 TFLOPS (with sparsity), linked by a 2- or 4-way NVLink bridge.
So for fitting a model, the NVL gives you exactly the same 141GB, usually for less. You give up some compute and, in multi-GPU setups, the full SXM interconnect. If your job is "load a big model on one card and serve it", the NVL is the cheaper way to get the memory. Check the listing name before you rent: on Vast and Runpod both versions appear, and they are priced differently.
NVIDIA's own H200 page, read Nov 3, 2026. · Screenshot of nvidia.com by aliteq
When is 141GB worth paying for?
When the model, its context (the KV cache) and a little overhead need more than 80GB. That is the whole test. Here is what our VRAM calculator estimates for some common cases, and which card they fit:
Does it fit? Estimated VRAM from our calculator
32B model (Qwen3 32B), 16-bit, 32K context
Estimated VRAM
about 70 GB
Verdict
fits an H100 (tight); H200 not needed
70B model (Llama 3.3 shape), 4-bit Q4_K_M, 32K context
Estimated VRAM
about 51 GB
Verdict
fits an H100 easily
70B model, 8-bit Q8_0, 8K context
Estimated VRAM
about 73 GB
Verdict
fits an H100, barely
70B model, 8-bit Q8_0, 32K context
Estimated VRAM
about 81 GB
Verdict
does not fit 80GB; fits an H200
70B model, 8-bit Q8_0, 128K context
Estimated VRAM
about 111 GB
Verdict
H200 only
70B model, 16-bit, 8K context
Estimated VRAM
about 135 GB
Verdict
tight even on an H200
Qwen3 235B-A22B (MoE), 3-bit Q3_K_M, 32K context
Estimated VRAM
about 114 GB
Verdict
H200 only
Qwen3 235B-A22B (MoE), 4-bit Q4_K_M, 32K context
Estimated VRAM
about 139 GB
Verdict
tight on an H200; plan for two cards
Estimated VRAM
Verdict
32B model (Qwen3 32B), 16-bit, 32K context
about 70 GB
fits an H100 (tight); H200 not needed
70B model (Llama 3.3 shape), 4-bit Q4_K_M, 32K context
about 51 GB
fits an H100 easily
70B model, 8-bit Q8_0, 8K context
about 73 GB
fits an H100, barely
70B model, 8-bit Q8_0, 32K context
about 81 GB
does not fit 80GB; fits an H200
70B model, 8-bit Q8_0, 128K context
about 111 GB
H200 only
70B model, 16-bit, 8K context
about 135 GB
tight even on an H200
Qwen3 235B-A22B (MoE), 3-bit Q3_K_M, 32K context
about 114 GB
H200 only
Qwen3 235B-A22B (MoE), 4-bit Q4_K_M, 32K context
about 139 GB
tight on an H200; plan for two cards
The pattern: long context and 8-bit 70B models are where the H200 earns its premium, along with big mixture-of-experts models squeezed to 3-bit. A 4-bit 70B or anything 32B and under fits an 80GB H100. Full 16-bit 70B weights alone come close to filling 141GB, so that is a two-GPU job on any card. Check your exact model and context in the VRAM calculator before you rent.
One H200 or two H100s?
If your model needs more than 80GB, the alternative is splitting it across two H100s. On Nov 3, 2026 one H200 was cheaper than two H100 SXMs everywhere we checked:
Runpod Secure: one H200 $5.29 vs two H100 SXMs $7.98 ($3.99 each)
Hyperstack: one H200 SXM $3.99 vs two H100 SXMs $6.40 ($3.20 each)
Vast.ai (cheapest offers): one H200 SXM $3.76 vs two H100 SXMs $4.80 ($2.40 each)
One card also skips the work of splitting a model across GPUs, which not every tool handles well. That is the strongest case for the H200: not speed, but one card instead of two.
When should you rent an H100 instead?
Whenever your job fits in 80GB. The H200 is a Hopper chip like the H100, and NVIDIA's spec table gives the H200 SXM the same headline FP8 compute figure the H100 SXM carries. For a model that already fits, you would pay roughly $1.30 to $1.40 more an hour (Runpod, Vast's cheapest offers) for memory you don't use. Our cheapest H100 guide has every H100 price from the same day, and if you need even more memory per card, see H100 vs B200.
Is the H200 faster than the H100?
For serving many users, often yes; for one person chatting, not by much. NVIDIA's H200 page says it "boosts inference speed by up to 2X compared to H100 GPUs" and shows Llama 2 70B as "1.9X Faster". The footnote is the honest part: that test ran the H100 at batch size 8 and the H200 at batch size 32. The extra memory lets the H200 serve four times as many requests at once, which is where most of the gain comes from. If you are one user running one prompt at a time, expect the speedup to come mainly from the 1.4x memory bandwidth, not 1.9x.
What else adds to the bill?
Storage. On both Vast and Runpod it keeps billing after you stop the GPU. Vast's docs say: "Storage charges continue even when instances are stopped. Delete instances completely to cease storage billing." Runpod's docs list volume disk at $0.10/GB/month while running and $0.20/GB/month while stopped. A 70B model at 8-bit is about 75GB of files before your datasets, so delete what you don't need when you're done, or keep it on a network volume ($0.07/GB/month for the first 1TB on Runpod).
Should you rent or buy an H200?
For a project measured in hours or weeks, rent. Buying only starts to make sense when the cards run all day, every day. In September a r/LocalLLaMA user posted their team's rent-or-buy working for an 8-GPU HGX H200 server, which they put at $320,000 to $420,000, against a median on-demand rate of about $4.40 per GPU-hour across the providers they compared. Replies pointed at the costs a quick spreadsheet leaves out: power and the interest on the money. Our rent vs buy guide walks through the same maths for smaller cards.
Frequently asked
How much does it cost to rent an H200?
On Nov 3, 2026, one H200 SXM rented from $3.76 an hour on-demand on Vast.ai (median $4.70 across 4 offers), $3.99 on Hyperstack, $5.29 on Runpod Secure Cloud, $5.40 on Nebius and $6.31 per GPU on CoreWeave. The H200 NVL went from $1.87 on Vast and $3.79 on Runpod. Prices on marketplaces move hourly; see aliteq.com/cloud-gpu for today's.
Is the H200 worth it over an H100?
Only if you need the memory. The H200 has 141GB against the H100's 80GB, with 1.4x the memory bandwidth per NVIDIA. It's worth it when a model plus its context won't fit 80GB, such as a 70B model at 8-bit with 32K context, or when one H200 replaces two H100s. If your workload fits in 80GB, an H100 is cheaper.
What's the difference between the H200 SXM and the H200 NVL?
Both have 141GB of HBM3e at 4.8TB/s. The SXM is the server-board version (up to 700W, 3,958 FP8 TFLOPS with sparsity); the NVL is a PCIe card (up to 600W, 3,341 FP8 TFLOPS with sparsity). For fitting a big model on one card, the NVL gives the same memory and usually rents for less.
Is one H200 cheaper than two H100s?
On Nov 3, 2026, yes, everywhere we checked: $5.29 vs $7.98 on Runpod Secure Cloud, $3.99 vs $6.40 on Hyperstack, and $3.76 vs $4.80 at Vast's cheapest offers. One card also avoids splitting the model across GPUs.
Why does Runpod show an H200 for $3.59 in some places?
That is the Community Cloud price. Runpod's docs say Community Cloud is no longer accepting new hosts, while existing resources remain available, so a new account sees Secure Cloud, where the H200 was $5.29 an hour on Nov 3, 2026.
Can I rent an H200 cheaper than $3.76 an hour?
Yes, with trade-offs. The H200 NVL went from $1.87 on Vast, Hyperstack reservations start at $2.79, and interruptible capacity goes lower (Nebius preemptible from $0.79 a GPU-hour), but interruptible instances can be paused or reclaimed mid-job.