Laptop memory can't be upgraded, so the memory you can give the GPU sets the biggest model you'll ever run. Which laptop fits which models, with Apple, NVIDIA, AMD and HP specs and Apple US prices read Nov 3, 2026.
Some links on this page are referral links: we may earn a commission, at no cost to you.
Share
Which laptop should you buy to run local AI? The one with enough memory for the models you want, because you can't add memory to a laptop later. For 70B models or gpt-oss-120b, that means a MacBook Pro with the 40-core M5 Max and 64 to 128GB of unified memory, or a Windows laptop with AMD's Ryzen AI Max+ 395 and 128GB. For models up to about 32B, an RTX 5090 laptop (24GB) is the fastest and gives you CUDA. For 8B to 14B models, a 12 to 16GB RTX laptop or a 32GB MacBook Pro does the job. Specs below come from Apple, NVIDIA, AMD and HP's own pages, and Apple's US prices from its store, all read on Nov 3, 2026.
The memory ceilings that decide it (vendor spec pages, Nov 3, 2026)
128GB
Most unified memory in a MacBook Pro
MacBook Pro, 40-core M5 Max
96GB
Ryzen AI Max+ 395, assignable to the GPU
Of 128GB, per AMD and HP
24GB
RTX 5090 laptop GPU memory
GDDR7, 896GB/s
~40GB
Memory a 70B model needs
Q4_K_M weights, our VRAM engine
Which laptop should I buy for the models I want to run?
Start from the model, not the laptop. Our VRAM rule is about 0.57GB per billion parameters at Q4_K_M, the quant most people run, plus memory for the context and about 0.8GB of overhead. You can check any model in the VRAM calculator. Mapped onto the laptops on sale on Nov 3, 2026:
8B to 9B models (Qwen3 8B, Gemma-class)
Memory it needs
about 5.5 to 7GB
Laptop to buy
RTX 5070 laptop (8 or 12GB), or MacBook Pro M6 with 24GB
Why
Any current GPU laptop fits it
12B to 14B models
Memory it needs
about 10 to 14GB
Laptop to buy
RTX 5070 Ti (12GB) or RTX 5080 (16GB) laptop, or MacBook Pro with 24 to 32GB
Why
16GB leaves room for longer context
gpt-oss-20b, 27B to 32B models
Memory it needs
about 12 to 22GB at moderate context
Laptop to buy
RTX 5090 laptop (24GB), or MacBook Pro M5 Pro with 48GB
Why
24GB is the fastest way to run this tier on a laptop
70B dense models
Memory it needs
about 40GB plus context
Laptop to buy
MacBook Pro 40-core M5 Max with 64GB or more, or a 128GB Ryzen AI Max+ 395 laptop
Why
No GPU laptop has more than 24GB
gpt-oss-120b and 100B+ MoE models
Memory it needs
about 63GB and up
Laptop to buy
MacBook Pro M5 Max with 128GB, or a 128GB Ryzen AI Max+ 395 laptop
Why
Needs the biggest pool you can buy
Memory it needs
Laptop to buy
Why
8B to 9B models (Qwen3 8B, Gemma-class)
about 5.5 to 7GB
RTX 5070 laptop (8 or 12GB), or MacBook Pro M6 with 24GB
Any current GPU laptop fits it
12B to 14B models
about 10 to 14GB
RTX 5070 Ti (12GB) or RTX 5080 (16GB) laptop, or MacBook Pro with 24 to 32GB
16GB leaves room for longer context
gpt-oss-20b, 27B to 32B models
about 12 to 22GB at moderate context
RTX 5090 laptop (24GB), or MacBook Pro M5 Pro with 48GB
24GB is the fastest way to run this tier on a laptop
70B dense models
about 40GB plus context
MacBook Pro 40-core M5 Max with 64GB or more, or a 128GB Ryzen AI Max+ 395 laptop
No GPU laptop has more than 24GB
gpt-oss-120b and 100B+ MoE models
about 63GB and up
MacBook Pro M5 Max with 128GB, or a 128GB Ryzen AI Max+ 395 laptop
Needs the biggest pool you can buy
The model sizes come from our VRAM engine (Qwen3-32B is about 18.5GB of weights at Q4_K_M, a 70B about 40GB) and from our gpt-oss-120b page, where every GGUF is about 63GB. The laptop memory figures are the vendors' own.
Why does memory matter more than GPU speed on a laptop?
Because a laptop is the one computer you can't upgrade. On a desktop you can add a second card or swap in a bigger one. A laptop's GPU memory and its RAM are soldered, so the biggest model you can load on the day you buy it is the biggest you'll ever load. If a model doesn't fit, it either won't load or it spills into slow system memory and crawls.
Speed comes second, and it's set mostly by memory bandwidth: to write each word (token), the machine reads the model's weights from memory. That's why an RTX 5090 laptop, at 896GB/s, is the fastest laptop for anything that fits in its 24GB, and why the M5 Max (614GB/s) is quicker than the M5 Pro (307GB/s) on the same model.
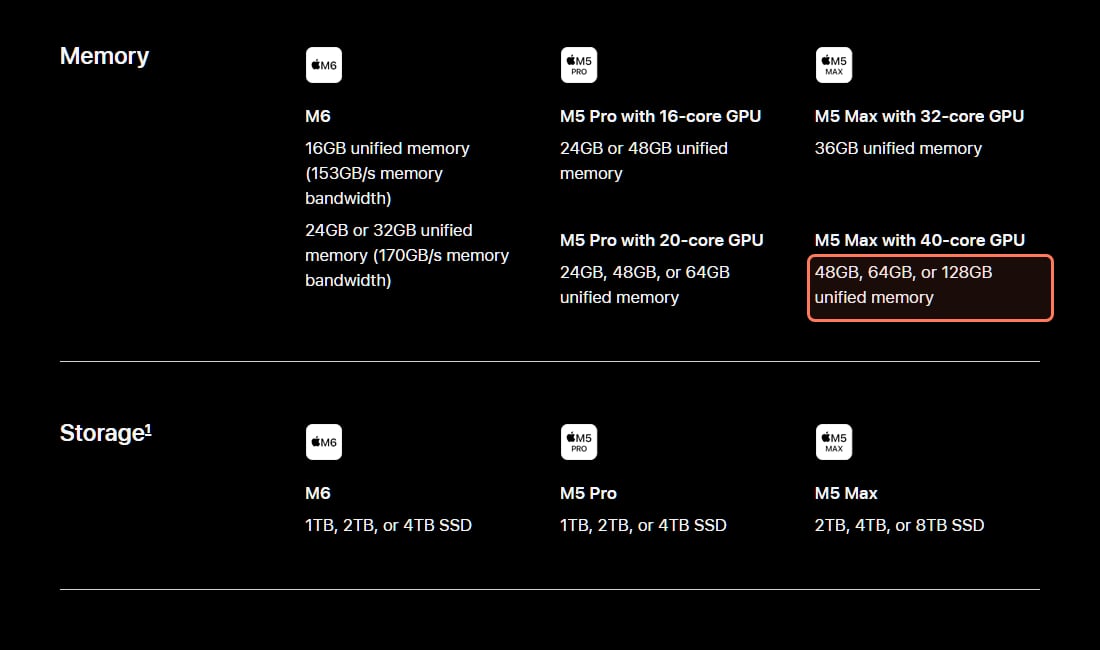
Apple's MacBook Pro spec page, read Nov 3, 2026. Only the 40-core M5 Max goes past 64GB; the 32-core M5 Max is 36GB only. · Screenshot of apple.com by aliteq
Is a MacBook Pro the best laptop for local AI?
For big models, yes, if you're happy on macOS. Apple's spec page lists these MacBook Pro chips on Nov 3, 2026, and the US store lists these starting prices:
M6 (14-inch only)
Unified memory options
16GB, 24GB or 32GB
Memory bandwidth
153GB/s (16GB), 170GB/s (24 or 32GB)
US price from (Nov 3, 2026)
$1,999
M5 Pro, 16-core GPU
Unified memory options
24GB or 48GB
Memory bandwidth
307GB/s
US price from (Nov 3, 2026)
$2,499 (14-inch)
M5 Pro, 20-core GPU
Unified memory options
24GB, 48GB or 64GB
Memory bandwidth
307GB/s
US price from (Nov 3, 2026)
$2,699 (14-inch), $2,999 (16-inch)
M5 Max, 32-core GPU
Unified memory options
36GB
Memory bandwidth
460GB/s
US price from (Nov 3, 2026)
$4,099 (14-inch), $4,399 (16-inch)
M5 Max, 40-core GPU
Unified memory options
48GB, 64GB or 128GB
Memory bandwidth
614GB/s
US price from (Nov 3, 2026)
$4,699 (14-inch), $4,999 (16-inch)
Unified memory options
Memory bandwidth
US price from (Nov 3, 2026)
M6 (14-inch only)
16GB, 24GB or 32GB
153GB/s (16GB), 170GB/s (24 or 32GB)
$1,999
M5 Pro, 16-core GPU
24GB or 48GB
307GB/s
$2,499 (14-inch)
M5 Pro, 20-core GPU
24GB, 48GB or 64GB
307GB/s
$2,699 (14-inch), $2,999 (16-inch)
M5 Max, 32-core GPU
36GB
460GB/s
$4,099 (14-inch), $4,399 (16-inch)
M5 Max, 40-core GPU
48GB, 64GB or 128GB
614GB/s
$4,699 (14-inch), $4,999 (16-inch)
Prices are Apple's starting prices for each chip's standard configuration; extra memory costs more, and Apple's configurator shows the upgrade price for each step. The M6 model was on pre-order on Nov 3, with Apple's store saying it's "Available starting 11.6."
On llama.cpp's Apple Silicon scoreboard (LLaMA 7B, Q4_0), the 40-core M5 Max generates 119.9 tokens a second and the 20-core M5 Pro 66.3, read Nov 3, 2026. That's a small model; a 70B is roughly ten times bigger, and dividing 614GB/s by its 40GB gives a ceiling of about 15 tokens a second on the M5 Max before any real-world losses. Usable for chat, not fast. Our cheapest way to run 70B page works through that trade.
Two honest limits. macOS keeps part of the memory for itself, so the GPU can't use all 128GB. And Apple Silicon doesn't run CUDA, so some image, video and training tools that expect an NVIDIA card run slower or not at all. Our Mac vs NVIDIA comparison covers the same choice on the desktop.
Is an RTX 5090 gaming laptop good for local AI?
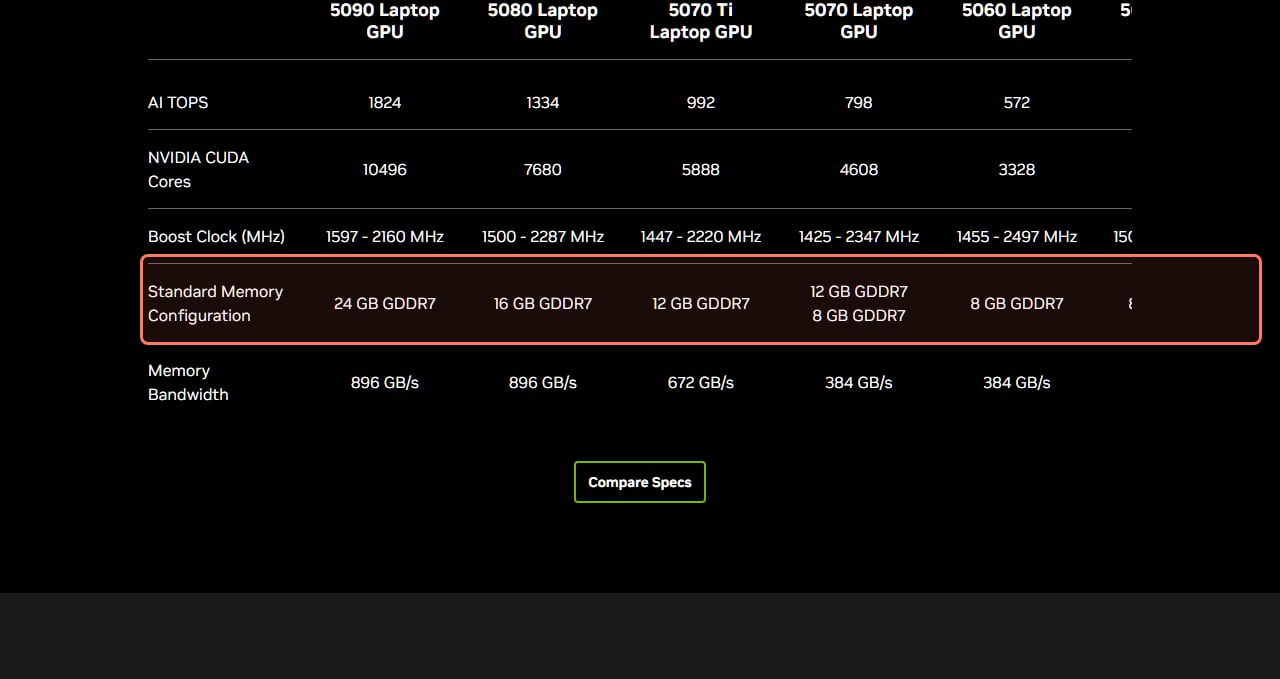
Yes, for models up to about 32B, and it's the fastest laptop you can buy for them. NVIDIA's laptop spec table, read Nov 3, 2026, lists the RTX 5090 Laptop GPU with 24GB of GDDR7 at 896GB/s. The RTX 5080 laptop has 16GB at the same 896GB/s, the RTX 5070 Ti 12GB at 672GB/s, and the RTX 5070 12GB or 8GB at 384GB/s.
NVIDIA's RTX 50 Series laptop spec table, read Nov 3, 2026. 24GB on the RTX 5090 is the most GPU memory in any NVIDIA laptop. · Screenshot of nvidia.com by aliteq
A 24GB laptop runs the same tier as a 24GB desktop card: a 27B model at Q5_K_M with 32K of context, Qwen3-32B at Q4, or gpt-oss-20b with room to spare (our 24GB model guide lists what fits). It also runs CUDA, so ComfyUI, Stable Diffusion, FLUX and fine-tuning scripts work as their guides assume.
What it can't do is a 70B model in GPU memory. 40GB of weights won't fit in 24GB. You can offload part of a model to system RAM, which works well for some mixture-of-experts models, but a dense 70B slows to a crawl that way. Laptop speed also depends on the power limit each maker sets: NVIDIA lists the RTX 5090 Laptop GPU's boost clock as a range, 1597 to 2160 MHz, so check the spec sheet of the exact laptop.
What about Windows laptops with AMD Ryzen AI Max+ 395 (Strix Halo)?
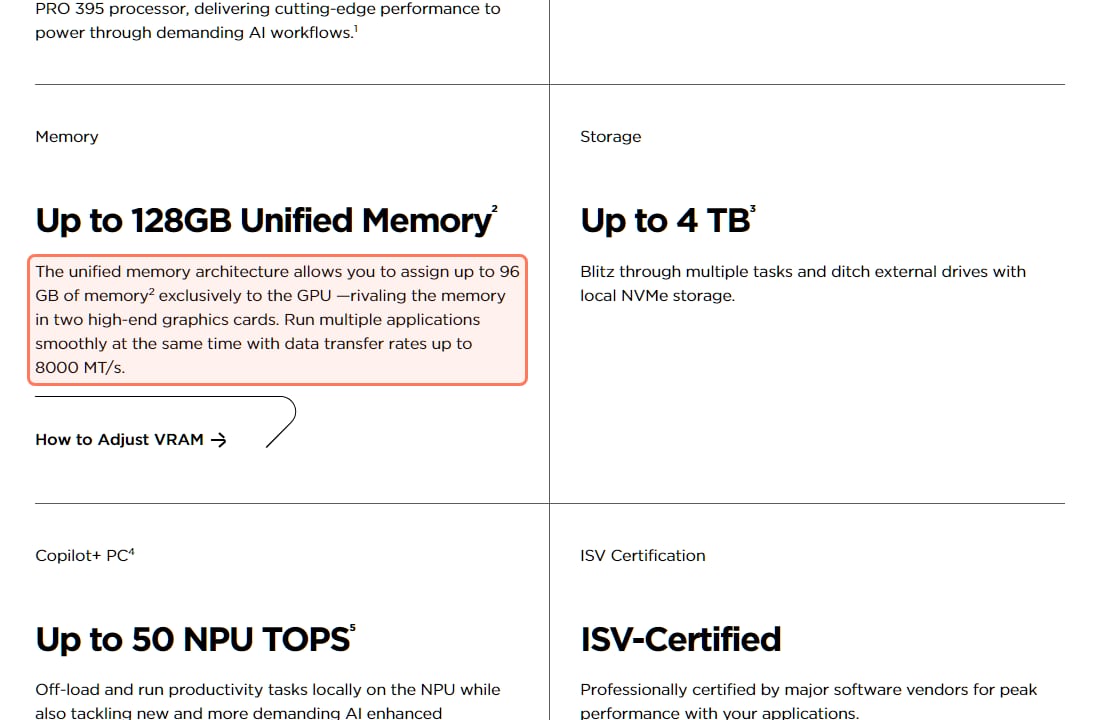
They're the Windows answer to a big-memory MacBook. AMD's spec page for the Ryzen AI Max+ 395 lists 128GB maximum memory, 256-bit LPDDR5x at up to 8000 MT/s, and Radeon 8060S graphics. AMD's own blog says that "up to 96GB can be converted to VRAM through AMD Variable Graphics Memory." HP's ZBook Ultra G1a page says the same in plain words: up to 128GB of unified memory, with up to 96GB you can "assign" "exclusively to the GPU". ASUS lists its ROG Flow Z13 (2025) with "128GB LPDDR5X 8000 on board".
HP's ZBook Ultra G1a page, read Nov 3, 2026: up to 96GB of a 128GB laptop can be assigned to the GPU. · Screenshot of hp.com by aliteq
96GB holds a 70B model at Q4 or gpt-oss-120b, and AMD's FAQ says the GPU can technically reach 112GB on a 128GB machine, though "The highest performance can be unlocked by limiting workloads to 96GB". The trade is speed. A 256-bit bus at 8000 MT/s works out to 256GB/s, well under half the 40-core M5 Max's 614GB/s, so the same big model generates more slowly. There's also no CUDA; you run models through llama.cpp's Vulkan or ROCm builds, LM Studio or Ollama. Our Strix Halo VRAM guide explains how to set the split, and local AI on AMD Radeon covers the software.
MacBook Pro, Strix Halo or RTX 5090 laptop: which one for me?
MacBook Pro M5 Max vs RTX 5090 laptop for local AI
MacBook Pro M5 Max (40-core)
Up to 128GB unified, 614GB/s
vs
RTX 5090 laptop
24GB GDDR7, 896GB/s
Up to 128GB
Memory for models
24GB
70B and gpt-oss-120b
Biggest model in memory
Up to about 32B
614GB/s
Speed on models that fit both
896GB/s
Metal, MLX, llama.cpp
Software support
CUDA, everything
From $4,699 (14-inch)
Price (Nov 3, 2026)
Varies by maker
(40-core) wins 2wins 2 laptop
Buy a MacBook Pro M5 Max (40-core) with 64 to 128GB if you want 70B-class or 100B+ MoE models on battery, in one quiet machine, and you're fine without CUDA. 64GB holds a 70B at Q4 with modest context; 128GB is the only laptop pool that fits gpt-oss-120b with room for long conversations.
Buy a 128GB Ryzen AI Max+ 395 laptop if you need Windows or Linux and big models, and can accept lower speed than the M5 Max.
Buy an RTX 5090 laptop if your models are 32B or smaller, you also make images or video in ComfyUI, or you want CUDA for fine-tuning. It's the fastest for everything that fits in 24GB.
Buy an RTX 5070 Ti or 5080 laptop, or a 24 to 32GB MacBook Pro, if you mostly run 8B to 14B models for coding help and chat.
Should I rent a GPU instead of buying a big-memory laptop?
If you need a 70B model only now and then, probably. The jump from a base 40-core M5 Max to 128GB is a large spend for a model you might run a few evenings a month. A rented 48GB card runs a 70B at Q4 by the hour, and you can keep a cheaper laptop for everything else. Our rent vs buy page does the break-even maths, and /cloud-gpu shows today's prices from our live price feed.
Do NPU and "AI PC" labels matter for local LLMs?
Not much for running chat models today. The NPU TOPS on a spec sheet (HP lists up to 50 NPU TOPS for the ZBook Ultra) is a different engine from the GPU, and llama.cpp, LM Studio and Ollama run local LLMs on the GPU or CPU. For local LLMs, compare GPU-usable memory first and memory bandwidth second.
Quick answers
What is the best laptop for running local AI models?
The one with enough GPU-usable memory for your biggest model. For 70B models and gpt-oss-120b, that's a MacBook Pro with the 40-core M5 Max and 64 to 128GB (Apple lists up to 128GB at 614GB/s, from $4,699 for the 14-inch on Nov 3, 2026) or a 128GB Ryzen AI Max+ 395 laptop that can give up to 96GB to the GPU. For models up to about 32B, an RTX 5090 laptop with 24GB is the fastest and runs CUDA.
Is a MacBook good for running local LLMs?
Yes, and it's the easiest way to run large models on a laptop. Unified memory means the GPU can use most of the machine's RAM, so a 64GB or 128GB M5 Max MacBook Pro holds models no NVIDIA laptop can. The limits are that it doesn't run CUDA and that macOS keeps part of the memory for itself.
Can a gaming laptop run local AI?
Yes, within its GPU memory. Per NVIDIA's spec table, an RTX 5090 laptop has 24GB, an RTX 5080 laptop 16GB, an RTX 5070 Ti laptop 12GB and an RTX 5070 laptop 8 or 12GB. That covers 8B to 32B models, fast, plus CUDA tools like ComfyUI. A dense 70B model doesn't fit in any of them.
How much RAM does a laptop need for local AI?
At Q4_K_M, plan on about 0.57GB per billion parameters plus a few GB for context. 16GB of GPU memory runs up to about 20B, 24GB runs 27B to 32B, 64GB runs a 70B with modest context, and 128GB fits gpt-oss-120b. Laptop memory can't be upgraded, so buy for the models you'll want later, not only today.
Is 16GB or 32GB enough on a MacBook for local AI?
16GB runs 7B to 9B models after macOS takes its share. 32GB runs 14B models comfortably and some 27B to 32B models at Q4 with short context. For 70B models you need 64GB or more, which on a MacBook Pro means the 40-core M5 Max (or 64GB on the 20-core M5 Pro, which is slower).
Is a Ryzen AI Max+ 395 laptop better than a MacBook Pro M5 Max for AI?
It's the Windows and Linux option with a similar memory ceiling: AMD lists up to 128GB, with up to 96GB assignable to the GPU. Its memory bus works out to about 256GB/s against 614GB/s on the 40-core M5 Max, so big models generate more slowly, and neither runs CUDA. Pick it if you need Windows or Linux.