All four run local AI on unified memory, so the memory size decides which models load and the chip decides how fast they reply. Which box fits which models and budget, with prices read in November 2026, and when a graphics card or a rented GPU beats all of them.
Some links on this page are referral links: we may earn a commission, at no cost to you.
Share
Buy the cheapest box with enough unified memory for the biggest model you will run, then pay more only for what you need on top: speed (Mac Studio), CUDA (DGX Spark) or the lowest price per gigabyte (a Strix Halo mini PC). On our VRAM engine at 4-bit, 32GB runs 27B models, 64GB runs 30B to 35B models at 8-bit, 128GB runs gpt-oss-120b, and only a 256GB Mac Studio holds a 235B model in one box.
Part of our best GPU for local AI guide, which covers the graphics-card side of the same decision.
Why unified memory is the whole decision
On a PC with a graphics card, a model has to fit the card's own VRAM: a 24GB card holds 24GB, full stop. On a Mac, a Strix Halo mini PC or a DGX Spark, the CPU and GPU draw from one shared pool, so a 128GB box can hold a model that would need four 24GB cards in a tower. That is the reason these small, quiet machines matter for local AI.
There are two catches. First, the GPU never gets all of it. macOS sets a recommended GPU memory ceiling (Apple's Metal documentation calls it recommendedMaxWorkingSetSize) and doesn't publish the percentage, so we plan on two-thirds of memory at 32GB and below and three-quarters above, from values llama.cpp users have logged. On a 128GB Strix Halo, AMD's own setting tops out at 96GB for the GPU. So a 128GB box means about 96GB for the model and its context.
Second, none of these machines can be upgraded. Macs, Strix Halo boxes and the DGX Spark have no memory slots, so the memory you pick at checkout is the biggest model that machine will ever hold. Check your exact model, quantization and context length in the VRAM calculator before you choose.
Which box fits which models
These are our VRAM engine's figures at 4-bit (Q4_K_M) with a 16K context, computed Nov 6, 2026, against the GPU share we plan on.
What each memory size runs, and the cheapest box with it
32GB
GPU share we plan on
About 21GB
Fits at 4-bit unless noted
Qwen3.6 27B (17.5GB), gpt-oss-20b (13.3GB)
Cheapest box with it
Mac mini M6, $1,299 (Apple, Nov 6, 2026)
64GB
GPU share we plan on
About 48GB
Fits at 4-bit unless noted
Qwen3 32B and Qwen3.6 35B-A3B at 8-bit; a 70B at 4-bit only tight (45.6GB)
Cheapest box with it
Strix Halo, $2,199.99 sale (GMKtec, Nov 6, 2026)
128GB
GPU share we plan on
About 96GB
Fits at 4-bit unless noted
gpt-oss-120b (67.9GB), Qwen3.5 122B-A10B (71.8GB), a 70B at 8-bit (75.6GB)
Cheapest box with it
Strix Halo, $3,449 to $3,499.99 (Framework, GMKtec)
256GB
GPU share we plan on
About 192GB
Fits at 4-bit unless noted
Qwen3 235B-A22B (136.5GB)
Cheapest box with it
Mac Studio M5 Ultra, $9,499 (Apple, Nov 6, 2026)
GPU share we plan on
Fits at 4-bit unless noted
Cheapest box with it
32GB
About 21GB
Qwen3.6 27B (17.5GB), gpt-oss-20b (13.3GB)
Mac mini M6, $1,299 (Apple, Nov 6, 2026)
64GB
About 48GB
Qwen3 32B and Qwen3.6 35B-A3B at 8-bit; a 70B at 4-bit only tight (45.6GB)
Strix Halo, $2,199.99 sale (GMKtec, Nov 6, 2026)
128GB
About 96GB
gpt-oss-120b (67.9GB), Qwen3.5 122B-A10B (71.8GB), a 70B at 8-bit (75.6GB)
Strix Halo, $3,449 to $3,499.99 (Framework, GMKtec)
256GB
About 192GB
Qwen3 235B-A22B (136.5GB)
Mac Studio M5 Ultra, $9,499 (Apple, Nov 6, 2026)
64GB is the awkward tier for 70B models: a 70B at 4-bit uses about 95% of a 64GB machine's GPU share on our math, so it may load but leaves little room for a long context. If 70B is the goal, buy 128GB.
Mac mini, Mac Studio, Strix Halo or DGX Spark side by side
Reply speed follows memory bandwidth, because every new token means reading the model's active weights from memory. Prompt speed and image generation follow GPU compute, where NVIDIA leads. Prices are the vendors' own US stores on the date shown.
[Mac mini M6](/mac-mini-local-ai-buying-guide)
Memory
up to 32GB
Bandwidth
153 to 170 GB/s
Price (date read)
$1,299 with 32GB (Apple, Nov 6, 2026)
Buy it for
27B models, the cheapest start
Mac mini M5 Pro
Memory
up to 64GB
Bandwidth
307 GB/s
Price (date read)
$2,699 with 64GB (Apple, Nov 6, 2026)
Buy it for
30B to 35B models, small and quiet
[Strix Halo mini PC](/gpus/ryzen-ai-max-plus-395-128gb)
Memory
up to 128GB
Bandwidth
about 256 GB/s
Price (date read)
$3,449 Framework DIY (Nov 3); $3,499.99 GMKtec sale (Nov 6)
Buy it for
The cheapest 128GB, x86, Windows or Linux
[Mac Studio M5 Max](/gpus/m5-max-40-core)
Memory
up to 128GB
Bandwidth
614 GB/s
Price (date read)
$5,099 with 128GB, 512GB SSD (Apple, Nov 6, 2026)
Buy it for
The fastest replies at 128GB
[DGX Spark](/gpus/dgx-spark)
Memory
64GB or 128GB
Bandwidth
273 GB/s
Price (date read)
$6,950 for 128GB (NVIDIA store, Nov 17, 2026); 64GB from $4,999 at partners
Buy it for
CUDA, long prompts, image and video
[Mac Studio M5 Ultra](/gpus/m5-ultra)
Memory
96GB to 512GB
Bandwidth
1.2 TB/s
Price (date read)
$9,499 with 256GB, 1TB (Apple, Nov 6, 2026)
Buy it for
235B-class models in one box
Memory
Bandwidth
Price (date read)
Buy it for
[Mac mini M6](/mac-mini-local-ai-buying-guide)
up to 32GB
153 to 170 GB/s
$1,299 with 32GB (Apple, Nov 6, 2026)
27B models, the cheapest start
Mac mini M5 Pro
up to 64GB
307 GB/s
$2,699 with 64GB (Apple, Nov 6, 2026)
30B to 35B models, small and quiet
[Strix Halo mini PC](/gpus/ryzen-ai-max-plus-395-128gb)
up to 128GB
about 256 GB/s
$3,449 Framework DIY (Nov 3); $3,499.99 GMKtec sale (Nov 6)
The cheapest 128GB, x86, Windows or Linux
[Mac Studio M5 Max](/gpus/m5-max-40-core)
up to 128GB
614 GB/s
$5,099 with 128GB, 512GB SSD (Apple, Nov 6, 2026)
The fastest replies at 128GB
[DGX Spark](/gpus/dgx-spark)
64GB or 128GB
273 GB/s
$6,950 for 128GB (NVIDIA store, Nov 17, 2026); 64GB from $4,999 at partners
CUDA, long prompts, image and video
[Mac Studio M5 Ultra](/gpus/m5-ultra)
96GB to 512GB
1.2 TB/s
$9,499 with 256GB, 1TB (Apple, Nov 6, 2026)
235B-class models in one box
In Tom's Hardware's three-way test (Jul 30, 2026), even the older M4 Max Mac Studio generated 27% to 82% more tokens per second than a GB10 system, while GB10 led on prompt processing and on its Flux image test. Our Mac Studio vs DGX Spark vs Strix Halo comparison has the full numbers.
Which one should you buy?
You want to run 27B to 35B models quietly
Buy a Mac mini. A 32GB Mac mini M6 at $1,299 loads Qwen3.6 27B at 4-bit; a 64GB Mac mini M5 Pro runs the 30B to 35B models at 8-bit with about 1.8 times the bandwidth of the base chip. The Mac mini stops at 64GB, so if you think you will want 70B models next year, skip it. Our Mac mini buying guide maps every config against 13 models, and the best Mac for local AI covers the whole Apple lineup.
You want 128GB for the least money
Buy a Strix Halo mini PC (AMD Ryzen AI Max+ 395). GMKtec's 128GB EVO-X2 was $3,499.99 on sale on Nov 6, 2026, and Framework's 128GB Desktop DIY Edition was $3,449 on Nov 3. If you saw "about $1,999" for one earlier this year, that price is gone; memory prices pushed these boxes up across 2026. Replies come at roughly DGX Spark pace. Our Strix Halo VRAM guide explains the BIOS memory split, and Ryzen AI Max+ 395 vs Mac mini and Mac Studio shows what the extra $1,650 for a Mac buys.
You want the fastest replies from big models
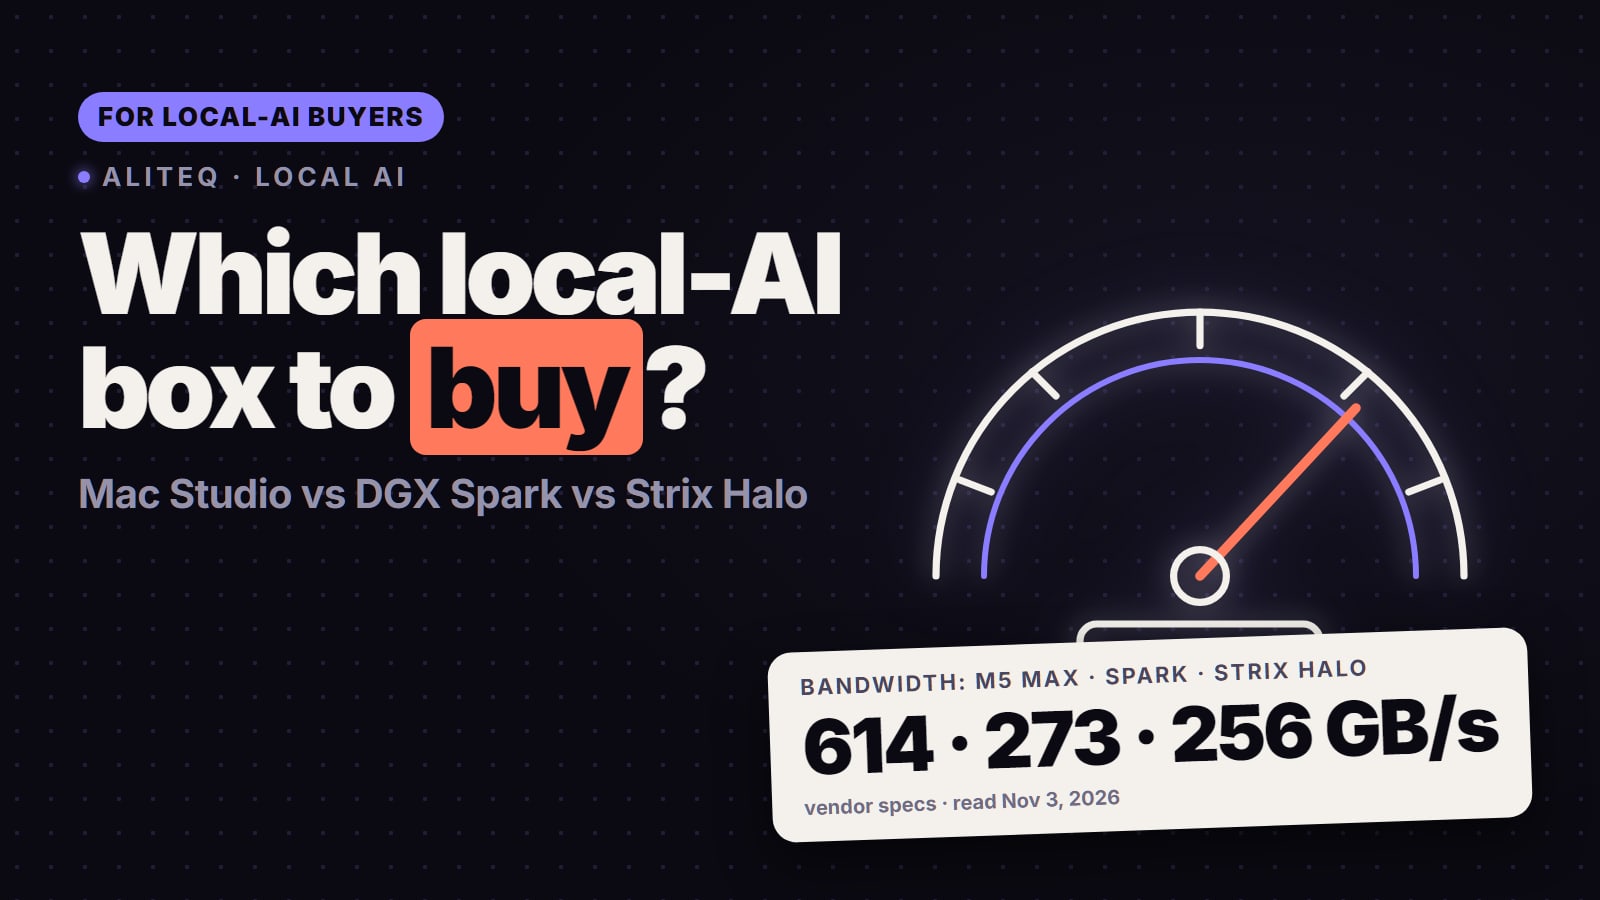
Buy a Mac Studio. The 40-core M5 Max reads memory at 614 GB/s, more than twice the DGX Spark's 273 GB/s, and the M5 Ultra reaches 1.2 TB/s. It is the best pick for chat and coding with 70B to 120B models. If your models fit in 24 to 48GB, an NVIDIA PC is faster still; our Mac Studio vs NVIDIA PC guide splits that by buyer, and the M5 Ultra vs RTX PRO 6000 comparison covers the top end.
You need CUDA, long prompts or image generation
Buy a DGX Spark, or a partner GB10 box with the same chip. It runs NVIDIA's software stack, processes long prompts fastest of the three 128GB boxes, and handles ComfyUI and Flux better than a Mac. The price is the problem: NVIDIA's own 128GB, 4TB DGX Spark was $6,950 on NVIDIA's US store on Nov 17, 2026, up from $3,999 at launch and $4,699 after February, and the ASUS Ascent GX10 with 128GB and 1TB was $5,999 on the same store. Our DGX Spark price page tracks every step and every partner box.
Your models fit in 24 to 32GB
Skip these boxes and buy a graphics card. A desktop GPU has several times the bandwidth of a 256 to 273 GB/s mini PC, so it replies faster for less money. The best GPU for local AI guide covers which card, and our AI GPU price list shows what each costs to buy or rent today.
Should you rent before you buy?
For the DGX Spark, yes, because you can rent its chip. On Nov 17, 2026 our tracker read a single GB10 on Vast.ai from $0.24 an hour (median $0.55), so a few hours of testing your own prompts costs a few dollars. At the $0.55 median, $6,950 buys about 12,600 rented hours, which is over four years at eight hours a day (our arithmetic, before electricity). Runpod does not rent the GB10. Macs and Strix Halo boxes aren't rented the same way, so for those, published benchmarks are what you have. Our rent vs buy guide works through the full math.
If your models fit in 32GB, a rented RTX 5090 is the honest alternative: it generates tokens faster than any box on this page on models that fit, though it can't load what needs 128GB.
Which is better for local AI, a Mac Studio or a DGX Spark?
The Mac Studio writes replies faster (614 GB/s on the M5 Max against 273 GB/s on the Spark) and costs less at 128GB ($5,099 at Apple on Nov 6, 2026, against $6,950 for the Spark on NVIDIA's store on Nov 17, 2026). The DGX Spark wins on CUDA software, long-prompt processing and image generation.
What is the cheapest computer with 128GB of memory for local AI?
A Strix Halo mini PC with AMD's Ryzen AI Max+ 395. Framework's 128GB Desktop DIY Edition was $3,449 on Nov 3, 2026 and GMKtec's 128GB EVO-X2 was $3,499.99 on sale on Nov 6, 2026. The GPU can use up to 96GB of it.
Is a Mac mini enough for local AI?
Up to its memory. A 32GB Mac mini runs 27B models at 4-bit and a 64GB Mac mini M5 Pro runs 30B to 35B models at 8-bit. For 70B and bigger models you need 128GB, which means a Mac Studio, a Strix Halo box or a DGX Spark.
Why doesn't a 128GB machine run a 128GB model?
The operating system needs part of the memory and each platform caps the GPU's share. Plan on about 96GB for the model and its context on a 128GB Mac or Strix Halo box.
Is a unified-memory box faster than a graphics card?
Not on models that fit both. A desktop graphics card has several times the memory bandwidth of a 256 to 273 GB/s mini PC, so it replies faster. The box wins on capacity, holding 70B to 120B models no single consumer card can.
Prices on this page were read on the vendors' US stores on the dates shown, and memory prices moved all through 2026, so check the price at checkout. For the graphics-card side of the same decision, go back to the best GPU for local AI, and for live rental prices see the cloud GPU tracker.