The rule by model size, the card sizes it maps to, and the real Ollama download sizes we checked it against on Nov 3, 2026. Why context costs some models far more than others, why MoE models still need room for every parameter, and what to do when your card is too small.
Some links on this page are referral links: we may earn a commission, at no cost to you.
Share
How much VRAM do you need to run an AI model? At Q4_K_M, the quant most people run, about 0.57 GB per billion parameters for the weights, plus memory for the context (the KV cache) and about 0.8 GB of runtime overhead. So a 9B model needs about 6.5 GB at 8K context, a 27B about 17 GB, and a 70B about 40 GB for the weights alone. In card sizes: 8GB runs 9B-class models, 12GB runs 12B to 14B, 16GB runs 20B models or a 27B at 3-bit, and 24GB runs a 27B at Q4_K_M with 32K of context. We checked the rule against Ollama's real download sizes on November 3, 2026; for the newest hybrid Qwen models the real files are up to about 1 GB bigger, so keep that headroom. Check your exact model and card in the VRAM calculator.
How much VRAM per billion parameters?
It depends on the quant. A model's size is its parameter count (the "B" in Qwen3.8 27B), and each quant stores those parameters at a different number of bits. A GGUF quant is a bit bigger than its name suggests, because the format stores scales alongside the weights and keeps some tensors at higher precision: in our engine Q4_K_M works out to 4.85 bits per weight and Q8_0 to 8.5, calibrated against published GGUF file sizes. That gives these working figures for the weights alone:
Q8_0
VRAM per billion parameters
~1.0 GB
A 27B model
~27.5 GB
Quality
Effectively lossless
Q6_K
VRAM per billion parameters
~0.76 GB
A 27B model
~21.2 GB
Quality
Very close to Q8
Q5_K_M
VRAM per billion parameters
~0.66 GB
A 27B model
~18.4 GB
Quality
Small, hard-to-notice loss
Q4_K_M
VRAM per billion parameters
~0.57 GB
A 27B model
~15.7 GB
Quality
The community default
Q3_K_M
VRAM per billion parameters
~0.46 GB
A 27B model
~12.6 GB
Quality
Noticeable loss; fits a bigger model
IQ3_XS
VRAM per billion parameters
~0.38 GB
A 27B model
~10.7 GB
Quality
Aggressive; test before trusting it
VRAM per billion parameters
A 27B model
Quality
Q8_0
~1.0 GB
~27.5 GB
Effectively lossless
Q6_K
~0.76 GB
~21.2 GB
Very close to Q8
Q5_K_M
~0.66 GB
~18.4 GB
Small, hard-to-notice loss
Q4_K_M
~0.57 GB
~15.7 GB
The community default
Q3_K_M
~0.46 GB
~12.6 GB
Noticeable loss; fits a bigger model
IQ3_XS
~0.38 GB
~10.7 GB
Aggressive; test before trusting it
Our figures are in the binary gigabytes VRAM is measured in (a "24GB" card has 24,576 MiB). The quantization guide covers how to choose between quants.
What size model can each GPU run?
Here is the rule turned into card sizes, at Q4_K_M with 8K of context unless the row says otherwise. We leave about 10% of the card free, because a model that needs 98% of VRAM loads and then fails the moment a browser or the desktop wants some.
8GB
Runs comfortably
7B to 9B models
Example on our numbers
Qwen3.5 9B: ~6.5 GB at 8K
12GB
Runs comfortably
12B to 14B models
Example on our numbers
Qwen3-14B: ~10.4 GB at 8K
16GB
Runs comfortably
20B models, or a 27B at 3-bit
Example on our numbers
gpt-oss-20b: ~13.0 GB at 8K; Qwen3.8 27B at IQ3_XS: ~12.0 GB
24GB
Runs comfortably
27B to 32B models
Example on our numbers
Qwen3.8 27B: ~18.5 GB at 32K; Qwen3-32B: ~21.3 GB at 8K
48GB
Runs comfortably
70B models
Example on our numbers
70B weights alone: ~40 GB
Runs comfortably
Example on our numbers
8GB
7B to 9B models
Qwen3.5 9B: ~6.5 GB at 8K
12GB
12B to 14B models
Qwen3-14B: ~10.4 GB at 8K
16GB
20B models, or a 27B at 3-bit
gpt-oss-20b: ~13.0 GB at 8K; Qwen3.8 27B at IQ3_XS: ~12.0 GB
24GB
27B to 32B models
Qwen3.8 27B: ~18.5 GB at 32K; Qwen3-32B: ~21.3 GB at 8K
These are current models at Q4_K_M from our VRAM engine (weights, KV cache at fp16, and about 0.8 GB of overhead), next to the size of the Q4_K_M download Ollama lists for the same model, read on November 3, 2026.
Qwen3 8B
Our weights estimate
~4.6 GB
Ollama Q4_K_M download (Nov 3, 2026)
5.2GB
Total at 8K context
~6.5 GB
Total at 32K context
~9.9 GB
Qwen3.5 9B
Our weights estimate
~5.5 GB
Ollama Q4_K_M download (Nov 3, 2026)
6.6GB
Total at 8K context
~6.5 GB
Total at 32K context
~7.2 GB
Qwen3-14B
Our weights estimate
~8.3 GB
Ollama Q4_K_M download (Nov 3, 2026)
9.3GB
Total at 8K context
~10.4 GB
Total at 32K context
~14.1 GB
gpt-oss-20b (MoE)
Our weights estimate
~11.8 GB
Ollama Q4_K_M download (Nov 3, 2026)
14GB (MXFP4)
Total at 8K context
~13.0 GB
Total at 32K context
~14.1 GB
Qwen3.8 27B
Our weights estimate
~15.7 GB
Ollama Q4_K_M download (Nov 3, 2026)
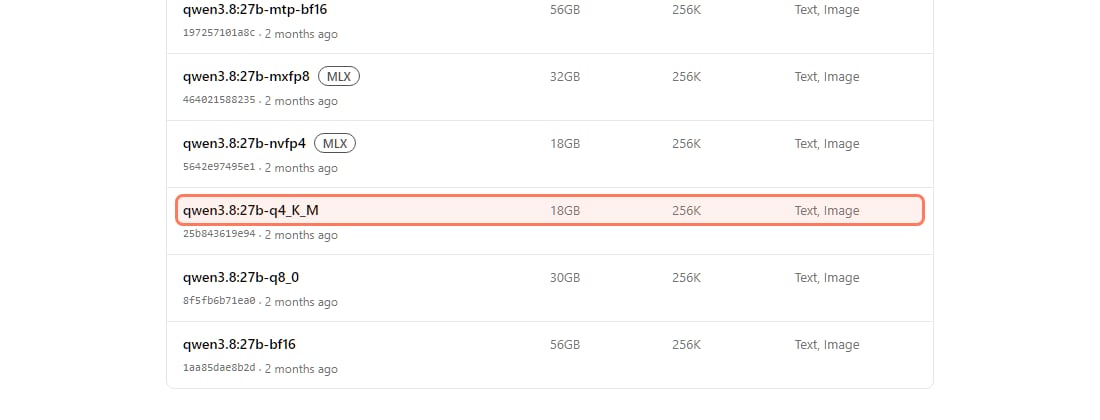
18GB
Total at 8K context
~17.0 GB
Total at 32K context
~18.5 GB
Qwen3-32B
Our weights estimate
~18.5 GB
Ollama Q4_K_M download (Nov 3, 2026)
20GB
Total at 8K context
~21.3 GB
Total at 32K context
~27.3 GB
Qwen3.5 35B-A3B (MoE)
Our weights estimate
~20.3 GB
Ollama Q4_K_M download (Nov 3, 2026)
22GB
Total at 8K context
~21.2 GB
Total at 32K context
~21.7 GB
Llama 3.3 70B
Our weights estimate
~39.8 GB
Ollama Q4_K_M download (Nov 3, 2026)
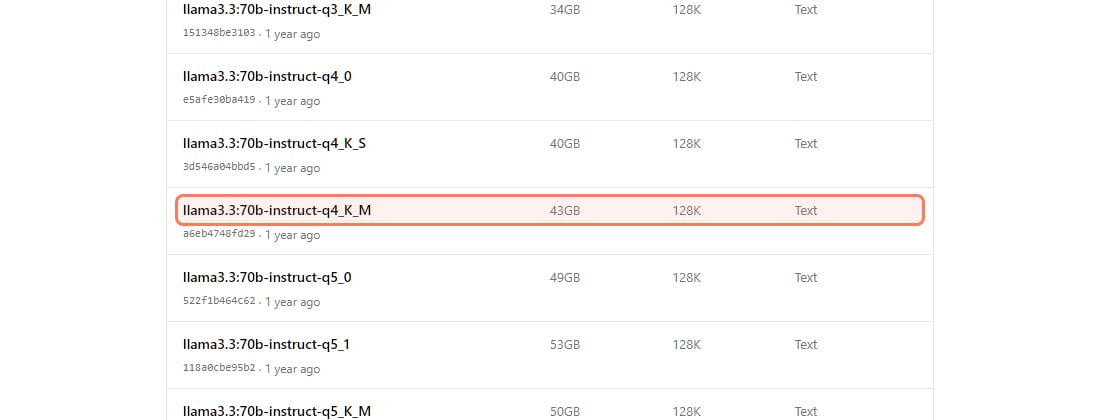
43GB
Total at 8K context
~43 GB
Total at 32K context
~51 GB
Our weights estimate
Ollama Q4_K_M download (Nov 3, 2026)
Total at 8K context
Total at 32K context
Qwen3 8B
~4.6 GB
5.2GB
~6.5 GB
~9.9 GB
Qwen3.5 9B
~5.5 GB
6.6GB
~6.5 GB
~7.2 GB
Qwen3-14B
~8.3 GB
9.3GB
~10.4 GB
~14.1 GB
gpt-oss-20b (MoE)
~11.8 GB
14GB (MXFP4)
~13.0 GB
~14.1 GB
Qwen3.8 27B
~15.7 GB
18GB
~17.0 GB
~18.5 GB
Qwen3-32B
~18.5 GB
20GB
~21.3 GB
~27.3 GB
Qwen3.5 35B-A3B (MoE)
~20.3 GB
22GB
~21.2 GB
~21.7 GB
Llama 3.3 70B
~39.8 GB
43GB
~43 GB
~51 GB
Ollama's tags page for Qwen3.8: the 27B at Q4_K_M is an 18GB download. Read November 3, 2026. · Screenshot of ollama.com by aliteq
Why is the real download bigger than the estimate?
Mostly units, and for some models a few extra tensors. Ollama lists sizes in decimal gigabytes, which read about 7% higher than the binary gigabytes VRAM is counted in: Llama 3.3 70B's 43GB is about 40 GB of VRAM, which matches our estimate. For Qwen3 32B and Qwen3.5 35B-A3B the two also match. For the newer hybrid Qwen models (Qwen3.5 9B, Qwen3.8 27B) the real files are still about 0.6 to 1.1 GB bigger than our weights figure, and gpt-oss-20b ships in OpenAI's own MXFP4 format rather than Q4_K_M. So on those, add about 1 GB of headroom to our totals.
Ollama's tags page for Llama 3.3: the 70B at Q4_K_M is a 43GB download, about 40 GB in VRAM units. That's why a 70B needs a 48GB card or two 24GB cards. Read November 3, 2026. · Screenshot of ollama.com by aliteq
Anywhere from about half a gigabyte to 8 GB at 32K tokens, depending on the model's design. The KV cache is the model's running memory of the conversation, and it grows with every token. Older models keep a cache on every layer; newer hybrid models keep a growing cache on only some layers. Qwen's model card for Qwen3.8 27B, for example, lists 64 layers in a "16 × (3 × (Gated DeltaNet → FFN) → 1 × (Gated Attention → FFN))" layout, so only 16 of them hold a growing cache.
Qwen3-32B
KV cache per 1,000 tokens (fp16)
~250 MB
At 32K tokens
~8 GB
Qwen3-14B
KV cache per 1,000 tokens (fp16)
~156 MB
At 32K tokens
~5 GB
Qwen3 8B
KV cache per 1,000 tokens (fp16)
~141 MB
At 32K tokens
~4.5 GB
Qwen3.8 27B
KV cache per 1,000 tokens (fp16)
~62 MB
At 32K tokens
~2 GB, plus ~0.3 to 0.5 GB fixed state
gpt-oss-20b
KV cache per 1,000 tokens (fp16)
~47 MB
At 32K tokens
~1.5 GB
Qwen3.5 9B
KV cache per 1,000 tokens (fp16)
~31 MB
At 32K tokens
~1 GB, plus ~0.1 to 0.2 GB fixed state
Gemma 4 12B
KV cache per 1,000 tokens (fp16)
~16 MB
At 32K tokens
~0.5 GB, plus ~0.3 GB fixed window cache
KV cache per 1,000 tokens (fp16)
At 32K tokens
Qwen3-32B
~250 MB
~8 GB
Qwen3-14B
~156 MB
~5 GB
Qwen3 8B
~141 MB
~4.5 GB
Qwen3.8 27B
~62 MB
~2 GB, plus ~0.3 to 0.5 GB fixed state
gpt-oss-20b
~47 MB
~1.5 GB
Qwen3.5 9B
~31 MB
~1 GB, plus ~0.1 to 0.2 GB fixed state
Gemma 4 12B
~16 MB
~0.5 GB, plus ~0.3 GB fixed window cache
That is why Qwen3.8 27B uses less memory at 32K than the older Qwen3-32B, and why Qwen3.5 9B stays near 7 GB at 32K (tight on an 8GB card once you add the ~1 GB download headroom, but possible) while Qwen3 8B needs about 10 GB. An 8-bit KV cache halves these figures, at a small quality cost.
Do mixture-of-experts models need less VRAM?
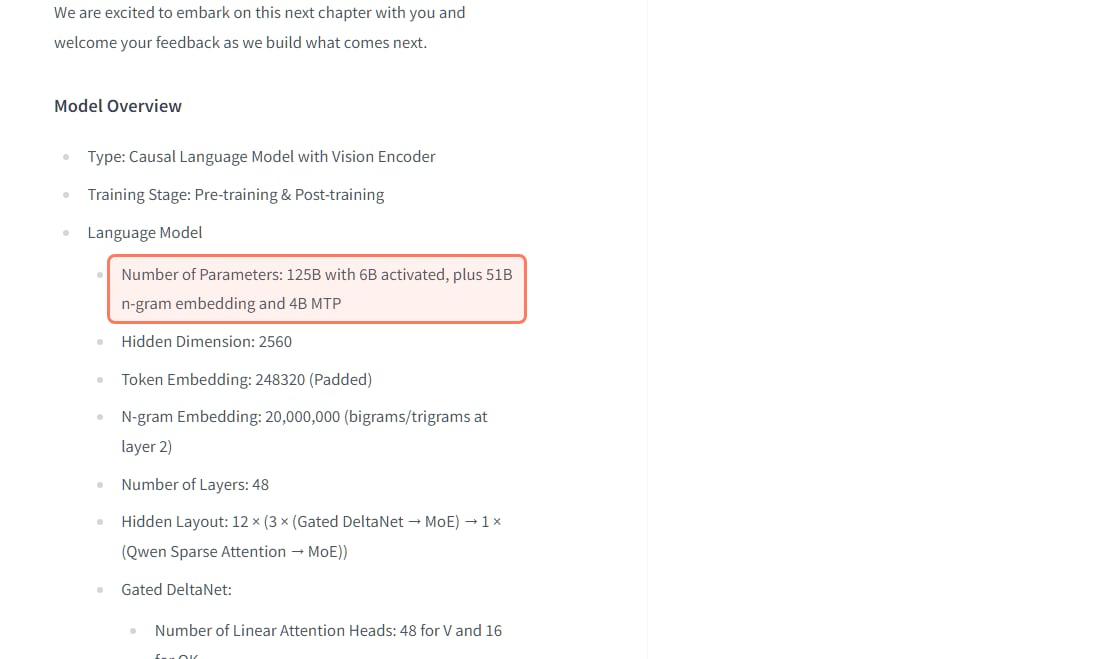
No. Total parameters set VRAM; active parameters set speed. OpenAI's model card describes gpt-oss-20b as "21B parameters with 3.6B active parameters", and it still needs room for all 21B: that is the 14GB download above. Qwen3.8 Flash Next is a bigger case. Its model card lists "125B with 6B activated, plus 51B n-gram embedding and 4B MTP", about 180B of weights in all, so at Q4_K_M it needs roughly 100 GB if everything stays in memory.
Qwen's own model card for Qwen3.8 Flash Next: 6B active, but 125B plus 51B of n-gram embedding to store. Read November 3, 2026. · Screenshot of huggingface.co by aliteq
What the small active count buys is speed, and the option to keep inactive experts in system RAM. Engines like llama.cpp (with its MoE offload, explained in what --n-cpu-moe actually does) keep the busy parts on the GPU and the rest in RAM, so an 8GB or 12GB card can run a model several times its size. The costs are real: those setups usually run 2-bit to 4-bit quants, and anything read from RAM slows each token down. The most common complaint we see is a model that loads fine and then runs far slower than expected, because part of it spilled out of VRAM. If you go this route, size your RAM too: see how much RAM you need for local AI.
What if the model doesn't fit my card?
Five options, cheapest first:
Drop one quant. Going from Q4_K_M to IQ4_XS saves about 12% on the weights; Q3_K_M saves about 19%.
Shorten the context, or use an 8-bit KV cache. On older models this can free several GB.
Pick a hybrid-attention model. Qwen3.5, Qwen3.8 and Gemma 4 need far less memory per token of context.
Offload to RAM. Works best for MoE models; costs speed.
Rent a bigger card for the job. On November 3, 2026 (15:20 UTC) our price feed showed a 24GB RTX 3090 on Vast.ai from $0.11 an hour on-demand and a 48GB RTX A6000 there from $0.35 an hour on-demand. Prices move hourly; cloud GPU prices shows today's.
Renting is also the honest way to check this article's numbers on your own model before you spend on hardware. If you're choosing a card to buy, start with the best GPU for local AI.
Quick answers
How much VRAM do I need to run an AI model?
At Q4_K_M, about 0.57 GB per billion parameters for the weights, plus the KV cache for your context and about 0.8 GB of overhead. On our numbers a 9B model needs about 6.5 GB at 8K context, a 27B about 17 GB, and a 70B about 40 GB for the weights alone. Ollama's Q4_K_M downloads matched within about 1 GB when we checked on Nov 3, 2026.
How much VRAM do I need for a 7B or 8B model?
About 5 to 6.5 GB at Q4_K_M with 8K context, so a 6GB card is too tight for most of them and an 8GB card is comfortable. At 32K context an older 8B such as Qwen3 8B needs about 10 GB, while the hybrid Qwen3.5 9B stays near 7 GB.
How much VRAM do I need for a 70B model?
About 40 GB for the weights at Q4_K_M (Ollama lists Llama 3.3 70B's Q4_K_M download at 43GB, read Nov 3, 2026), plus context. That means a 48GB card, two 24GB cards, a Mac with plenty of unified memory, or offloading part of it to RAM at a big speed cost.
Is 8GB of VRAM enough for AI?
For 7B to 9B models at Q4_K_M, yes. Qwen3.5 9B needs about 6.5 GB at 8K context on our numbers. Bigger models need a 3-bit quant or offloading to system RAM.
Does context length affect VRAM usage?
Yes, and by very different amounts per model. At 32K tokens, Qwen3-32B's KV cache is about 8 GB on our numbers, while Gemma 4 12B's is about 0.5 GB. Check your exact model and context in the VRAM calculator.
Do mixture-of-experts models need less VRAM?
No. VRAM is set by total parameters; active parameters set speed. gpt-oss-20b has 3.6B active parameters but still needs room for all 21B. MoE models do offload to system RAM better than dense ones, which is how they run on small cards.
Can I run AI models without enough VRAM?
Yes, within limits: use a smaller quant, a shorter context, a hybrid-attention model, offload to RAM, or rent a bigger card by the hour. For fast, predictable performance the model has to fit in VRAM.
That's the rule: a bit over half the parameter count in GB at Q4_K_M, plus context, plus headroom. Check any model against your card in the VRAM calculator, then pick a model from the VRAM ladder and set it up with our beginner's guide.